Projects using Python in Madrid
Projects using Python in Madrid
Sign Up
Post a job
Sign Up
Log In
Filters
2
Projects
People
Message
0
Víctor Aguado
Abonoteatro al día
0
4
Message
1
Berckan Guerrero
pro
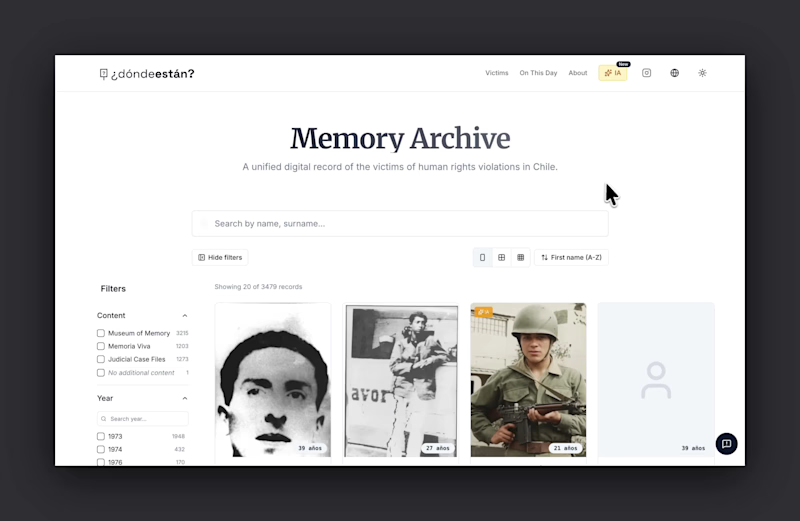
¿Dónde Están?: Full-stack memorial platform aggregating nearly 9,000 source records from Chile's military dictatorship across 3 sources. Python async ETL pipeline with fuzzy matching achieves 99% deduplication accuracy, resolving them into 3,216 unique victim profiles. AI-powered image restoration using Real-ESRGAN and GFPGAN recovers detail from low-resolution archival photographs. Supabase PostgreSQL backend with 63 migrations and Row Level Security on every table. Full-text search with Spanish stemming and unaccent handling. SHA-256 change detection for incremental sync. Nuxt 3, Vue 3, TypeScript. The first platform in Latin America to unify dictatorship victim records with AI-restored historical photographs.
1
901
Message
1
fernando aporta franco
pro
webhook-replay — capture a webhook once, replay it locally
1
3
Message
0
Eric Rodriguez
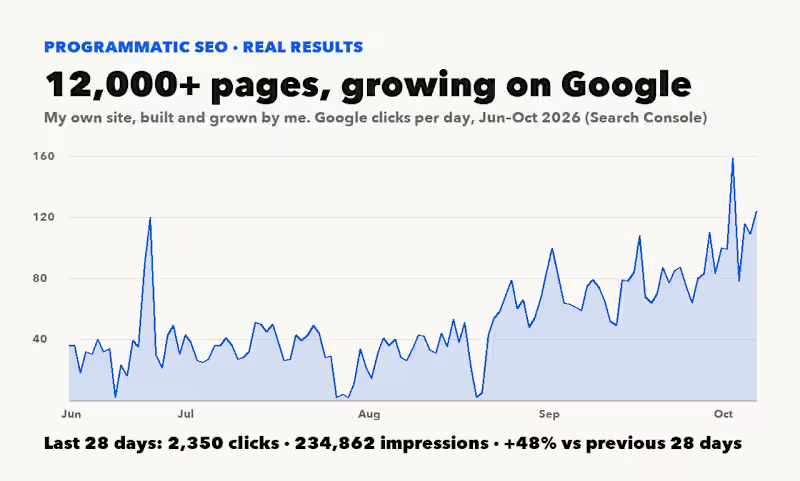
LaborIA: a programmatic SEO site with 12,000+ pages
0
0
Message
0
Kai Relaunch Dept
Proofline Keeper — Transaction Firewall for AI Agents
0
9
Message
0
Felix Gomez-Guillamon
Freelancer | SEO & AI Services | Ranked Top 2
0
31
Message
0
Beatriz Perez Fernandez
Commercial Operations Process Optimization
0
0
Message
0
Máximo Fernández Núñez
Naviground: autonomous vehicle perception
0
0
Message
0
Carlos Salgado
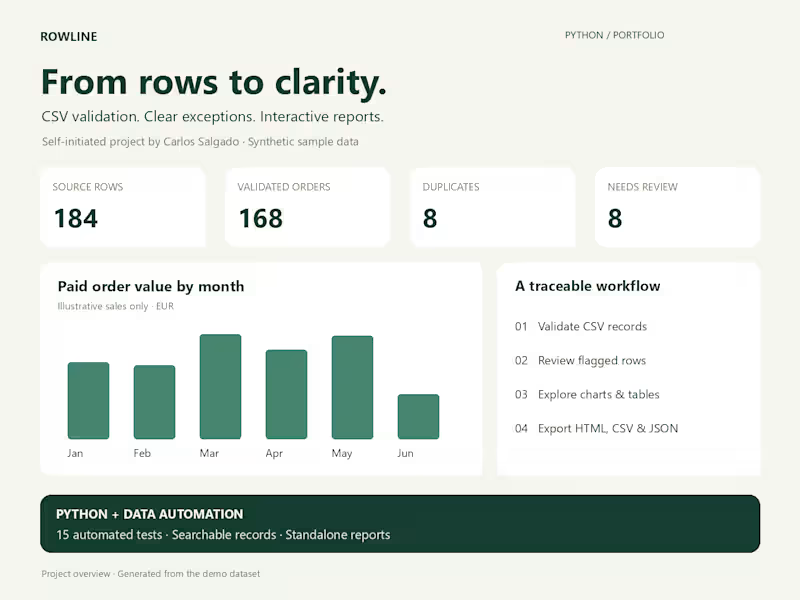
Rowline — Python CSV cleaning & sales reports A self-initiated data automation demo that turns a messy sales CSV into clean exports and an interactive HTML report. The Python workflow validates rows, detects duplicates and flags conflicting IDs while preserving monetary precision. Sample run: 184 input rows, 168 valid rows, 8 duplicates and 8 rows for review. Includes CSV/JSON exports, charts and searchable tables. Verified with 15 automated tests. The public link shows a generated report with sample data; CSV processing runs in the local Python application. Demo: https://carlos-salgado-website-concepts.salgado-carlos-d.chatgpt.site/rowline/
0
26
Message
0
Iria Iglesias
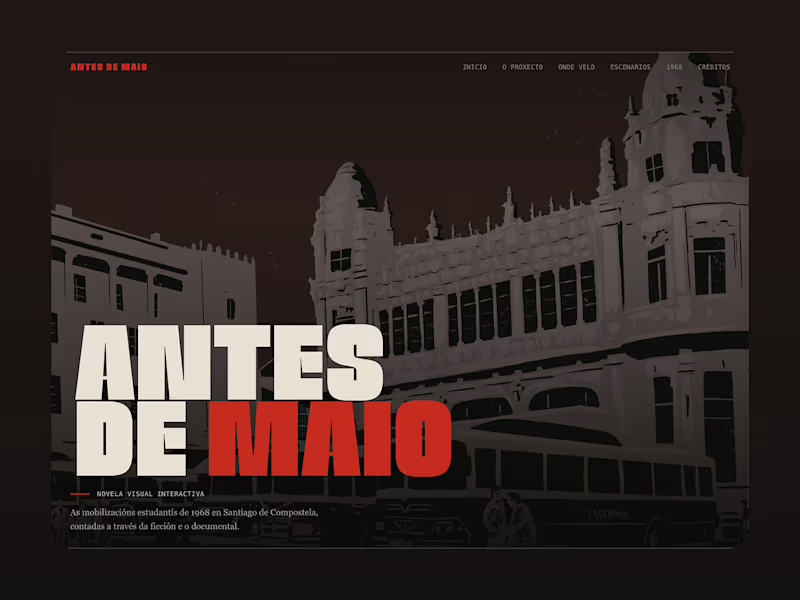
Antes de maio (Before May)
0
15
Message
0
Leonardo Garma
Desktop application for electrophysiology data analysis
0
26
Message
0
Javier Aquique
Machine Learning Algorithm - Autoencoder-Based Anomaly Detection
0
15
Message
0
Jorge Cañete
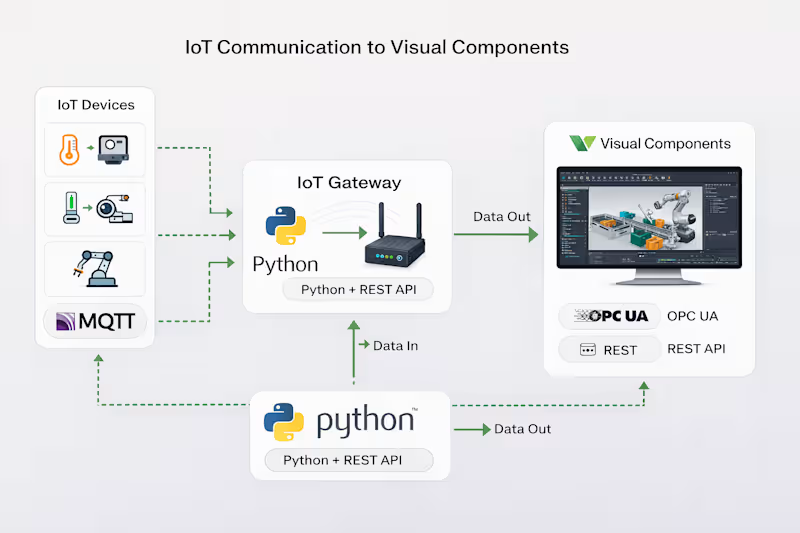
IoT data flow with Visual Components
0
45
Message
0
HAMZA EL QADIRI
Spotify Loader Benchmark The Spotify Loader Benchmark is a comprehensive framework for evaluating different data loading strategies on the Spotify dataset, providing insights into the performance of various loading mechanisms. By comparing sequential, vectorized, multithreaded, raw SQL, Celery-based, and Flink-based loaders, this project helps developers optimize their data loading processes. With its robust architecture and flexible design, the Spotify Loader Benchmark is an essential tool for anyone working with large datasets.
0
102
Message
0
José Ángel Olivares
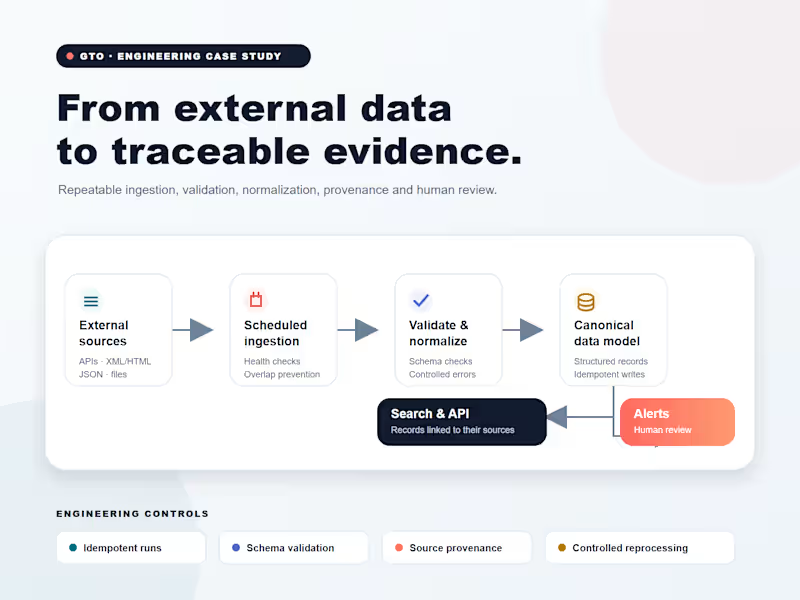
Traceable Data Pipeline | Evidence & Alerts
0
1
Message
0
Pablo Verdugo
From Freelancer to Startup: Journey in Web Scraping & Automation
0
19
Explore projects