Projects using FastAPI in BengaluruProjects using FastAPI in BengaluruProject Title:- Custom Enterprise RAG Assistant | Chat with Documents & PDFs
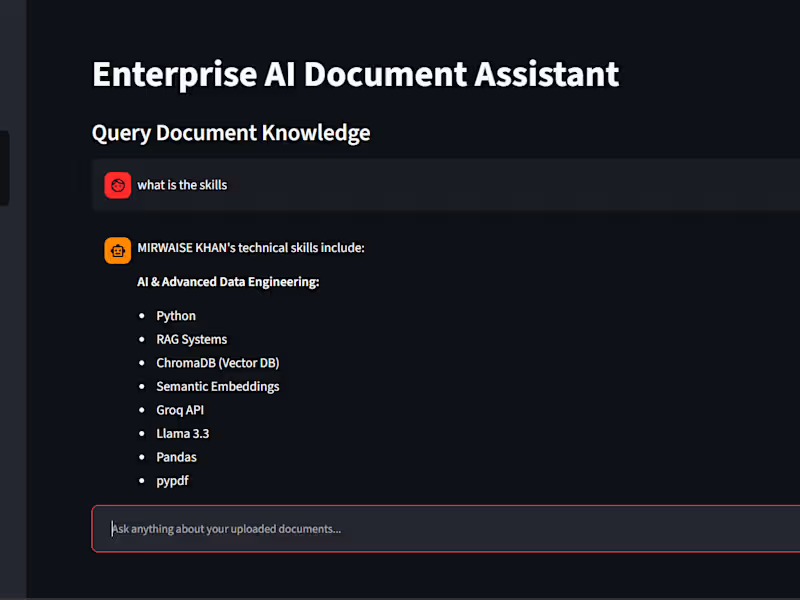
Project Overview: DocuMind is an enterprise-grade Retrieval-Augmented Generation (RAG) assistant designed to eliminate manual data extraction and prevent AI hallucinations. It converts static corporate files (PDFs, reports, resumes, contracts) into an interactive, grounded knowledge engine that provides answers backed by direct page-level citations.
The Problem Solved: * Manual Data Hunting: Eliminates hours spent reading through dense, complex documentation.
AI Hallucinations: Constrains LLM outputs strictly to uploaded context, ensuring reliable, factual data.
Lack of Auditability: Provides exact file names and page references for compliance and verification.
Key Technical Features: * Dynamic Indexing: Fast chunking and local vector embedding using Hugging Face models (all-MiniLM-L6-v2).
High-Accuracy Vector Search: ChromaDB integration for persistent vector storage and low-latency similarity retrieval.
Decoupled Architecture: Asynchronous FastAPI backend paired with a clean, responsive Streamlit chat frontend.
Contextual Synthesis: Powered by Google Gemini (gemini-2.5-flash) for cost-effective inference.
Tech Stack: Python, FastAPI, LangChain, ChromaDB, Hugging Face, Google Gemini, Streamlit. Built a full ecommerce fashion storefront for AL Creations (abaya, hijab & custom wear) — homepage, shop filters, product pages, cart/checkout, WhatsApp ordering, and a client admin to manage products & stock.
Designed for real small businesses who want an Amazon-style shopping experience without Shopify complexity.
Stack: HTML, CSS, JavaScript, React-ready UI patterns, Supabase, Netlify.
Live demo: https://al-creations-store-preview.netlify.app
I help brands launch clean, mobile-friendly websites that convert visitors into orders. LookInsight AI : AI Customer Support Automation System
Full-stack AI system that automates customer support workflows.
What it does:
→ Classifies customer intent (complaint, inquiry, refund, support) → Detects urgency and routes to the right team
→ Looks up customer history via knowledge graph
→ Generates personalized response drafts in seconds
Key features: • Real-time processing pipeline with live visualization
• Multi-channel support (Email, Twitter, Slack, WhatsApp)
• Business rules engine for tier-based treatment (VIP, Premium, Regular)
• Neo4j knowledge graph for customer context
Tech stack: Python, FastAPI, OpenAI GPT-4, Neo4j, Next.js, TypeScript
Live demo: https://lookinsight.ai
Skills: Python AI OpenAI FastAPI Next.js Customer Support Automation
Link: https://lookinsight.ai 𝗛𝗲𝗮𝗱𝗹𝗶𝗻𝗲: Most Voice AI agents still feel like glorified walkie-talkies. So I built one that actually listens like a human.
Most voice bots today follow a rigid, linear loop: You speak ➔ Wait ➔ Bot speaks. If you dare interrupt them mid-sentence? They either completely ignore you or their context buffer gets totally mangled.
𝗧𝗼 𝘀𝗼𝗹𝘃𝗲 𝘁𝗵𝗶𝘀, I engineered Astra Duplex Agent — a sub-50ms, ultra-low latency, full-duplex conversational Voice AI built to handle natural human interruptions seamlessly.
Here is what went into building the architecture under the hood:
True Full-Duplex WebSockets: Built on FastAPI, allowing real-time bi-directional audio streaming instead of turn-based HTTP requests.
Edge Voice Activity Detection (VAD): Deployed Silero VAD using ONNX Runtime to catch user barge-ins at the edge with near-zero overhead.
LangGraph State Machine: Instead of a simple monolithic script, the conversation logic is modeled as a state graph, giving precise control over execution flow.
Partial State Tracking & Memory Persistence: This was the trickiest part. When an interruption happens, Astra doesn't just stop audio playback — an async kill-switch halts Groq's LLaMA-3.1 mid-token, calculates the exact partial sentence actually spoken by the TTS, and saves only that partial context to an Upstash Redis buffer.
Sub-50ms Inference & Streaming: Leveraged Groq LPU (LLaMA-3.1 + Whisper Large v3) paired with ElevenLabs Turbo v2.5 streaming.
The result? An agent that you can interrupt mid-thought, change topics with on the fly, and ask follow-up questions without it losing historical context.
Containerized with Docker and live on Render & Vercel.
Check out the full architecture & live demo below!
https://lnkd.in/eC6yak3i
(https://lnkd.in/eC6yak3i)https://lnkd.in/eN38HGZD
(https://lnkd.in/eN38HGZD)#VoiceAI (https://www.linkedin.com/search/results/all/?keywords=%23voiceai&origin=HASH_TAG_FROM_FEED) #GenerativeAI (https://www.linkedin.com/search/results/all/?keywords=%23generativeai&origin=HASH_TAG_FROM_FEED) #LangGraph (https://www.linkedin.com/search/results/all/?keywords=%23langgraph&origin=HASH_TAG_FROM_FEED) #SystemDesign (https://www.linkedin.com/search/results/all/?keywords=%23systemdesign&origin=HASH_TAG_FROM_FEED) #FastAPI (https://www.linkedin.com/search/results/all/?keywords=%23fastapi&origin=HASH_TAG_FROM_FEED) #MachineLearning (https://www.linkedin.com/search/results/all/?keywords=%23machinelearning&origin=HASH_TAG_FROM_FEED) #WebSockets (https://www.linkedin.com/search/results/all/?keywords=%23websockets&origin=HASH_TAG_FROM_FEED) #Python (https://www.linkedin.com/search/results/all/?keywords=%23python&origin=HASH_TAG_FROM_FEED) #AIENGINEERING (https://www.linkedin.com/search/results/all/?keywords=%23aiengineering&origin=HASH_TAG_FROM_FEED)