Digital Fusion
Account Manager at Digital Fusion
- 1x
- Hired
- 1
- Followers

Project 1: Database Migration & Audit
Project Title: 5,000+ Record Database Audit and Migration
Role: Administrative Specialist
Tools Used: Property Tree, PropertyMe, Microsoft Excel
Project Description:
Successfully audited, cleaned, and migrated a massive database of over 5,000 property and client records for a busy real estate firm. The primary goal was transitioning historical data seamlessly between platforms while maintaining strict data integrity.
The Process:
Exported raw legacy data into Microsoft Excel to isolate missing information and system errors.
Formatted, mapped, and cleaned 5,000+ rows of data to match the exact field requirements of the new system.
Successfully imported the verified dataset into PropertyMe with zero downtime or lost records.
0
23
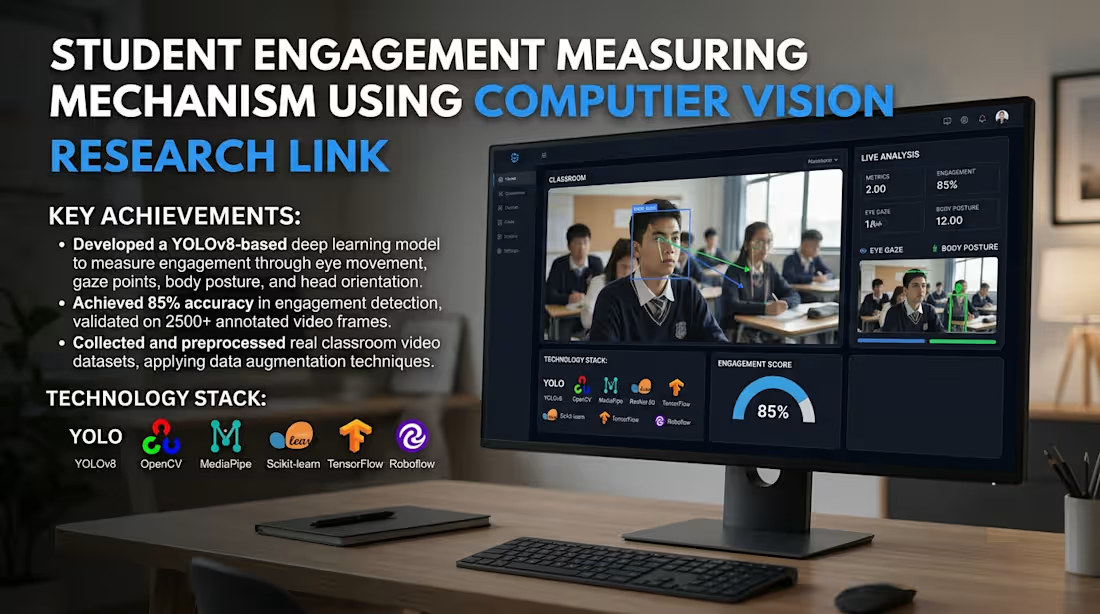
Student engagement measuring mechanism using computer vision — Research Link
– Collected and preprocessed real classroom video datasets, applying data augmentation techniques to
improve model robustness.
– Developed a YOLOv8-based deep learning model to measure engagement through eye movement, gaze
points, body posture, and head orientation of students.
– Achieved 85% accuracy in engagement detection, validated on 2500+ annotated video frames, providing
actionable insights for educators.
– Tech Stack: YOLOv8, OpenCV, MediaPipe, ResNet-50, Scikit-learn, TensorFlow, Roboflow.
0
39
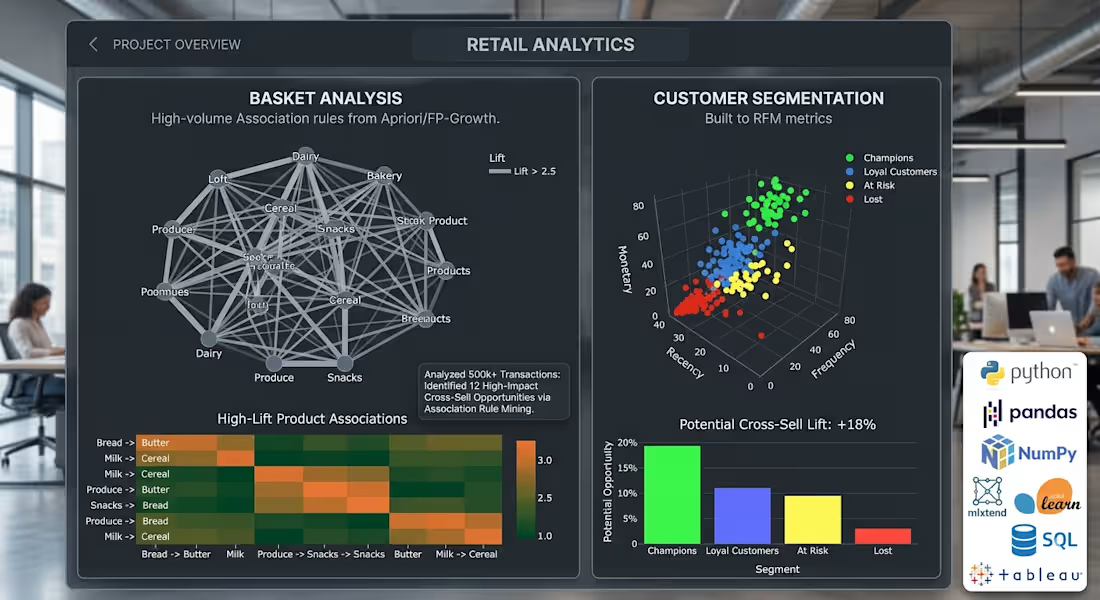
Retail basket analysis and customer segmentation
– Conducted deep-dive analysis on 500k+ retail transactions using Apriori and FP-Growth to discover
cross-sell opportunities, identifying high-lift product associations and seasonal purchase patterns.
– Performed RFM customer segmentation, improving potential cross-sell rate by 18%, and built interactive
dashboards.
– Tech Stack: Python (pandas, NumPy, mlxtend, scikit-learn), SQL, Tableau, plotly.
0
46
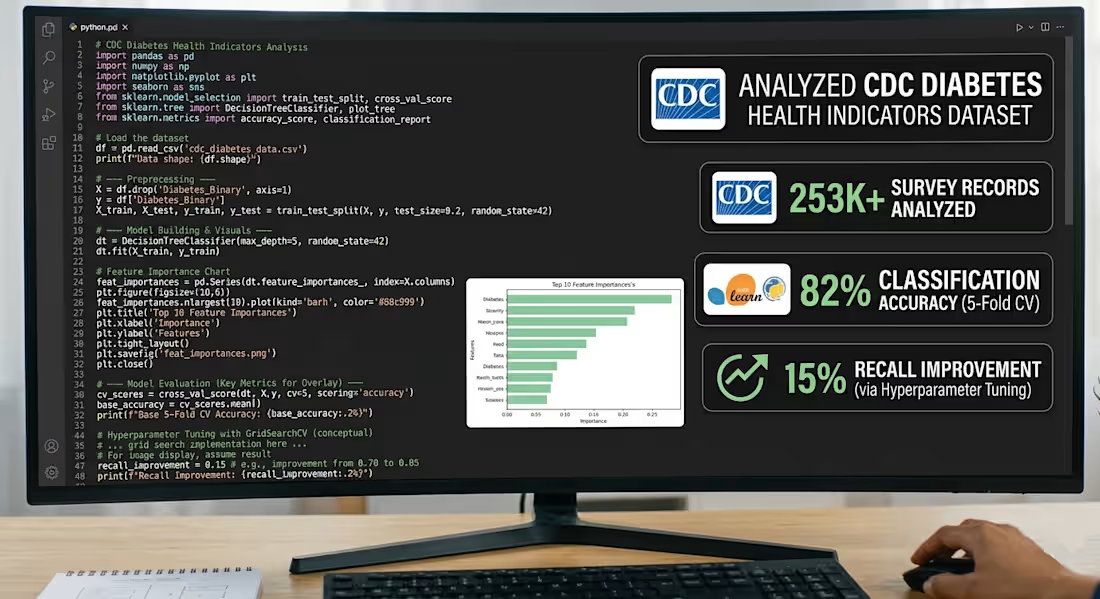
Analyzed CDC diabetes health indicators dataset
– Analyzed 253k+ survey records to uncover risk factor patterns; built Decision Tree models with 5-fold cross-validation, achieving 82% classification accuracy.
– Optimized model performance through hyperparameter tuning, improving recall of positive diabetes cases by 15%, supporting more accurate early-risk detection insights.
– Tech Stack: Python, Pandas, NumPy, Scikit-learn, Seaborn, Matplotlib, Imbalanced-learn
0
75