The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

An autonomous agent set loose overnight on a refactor can finish the morning having redone its own completed work, not crashed, not errored, just quietly rewriting files it already fixed, hours after it fixed them.
The instinct is to blame the model. But the same model, used interactively across an equally long session, usually doesn't fail this way nearly as often. The difference isn't capability, it's that someone was in the loop, implicitly signaling "that part's done, move on." An unattended agent has no equivalent. Nothing marks a finished subtask as closed, so it stays active in context at the same rate the task grows, until a meaningful share of what the agent's weighing at any moment is work that's already done.
That's a design gap, not a model limit. It needs an explicit mechanism, a task list the agent checks against, a summarization step that collapses finished work into a short note, a hard boundary between subtasks where only the outcome carries forward.
Wrote the full breakdown, with the overnight-refactor example: https://medium.com/@nagatomopedro05/unattended-ai-agents-have-a-context-problem-humans-never-had-60961eb2d4e7

medium.com
Unattended AI Agents Have a Context Problem Humans Never Had
A team sets an autonomous coding agent loose overnight on a multi-file refactor: rename a core interface, update every call site, adjust…

Great work
The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started








Related posts

AI Automation SaaS Website Design
AUTONIX is a modern AI automation SaaS website concept designed to help businesses streamline workflows, automate repetitive tasks, and manage AI agents more efficiently.
The design combines a clean, minimal interface with bold typography, futuristic visuals, interactive UI elements, and a seamless user experience. From AI-powered task automation to real-time productivity insights, every section is designed to communicate the value of intelligent automation in a clear and engaging way.
This project explores how thoughtful UI/UX design can make complex AI technology feel intuitive, accessible, and easy to use for modern businesses.
Services: SaaS Website Design, UI/UX Design, Landing Page Design, AI Product Design.


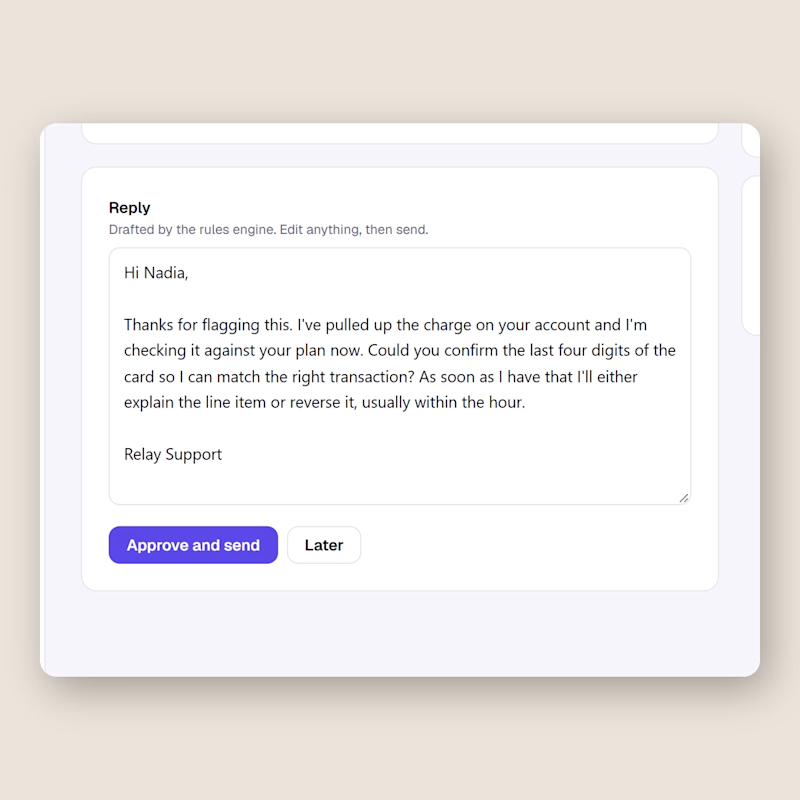
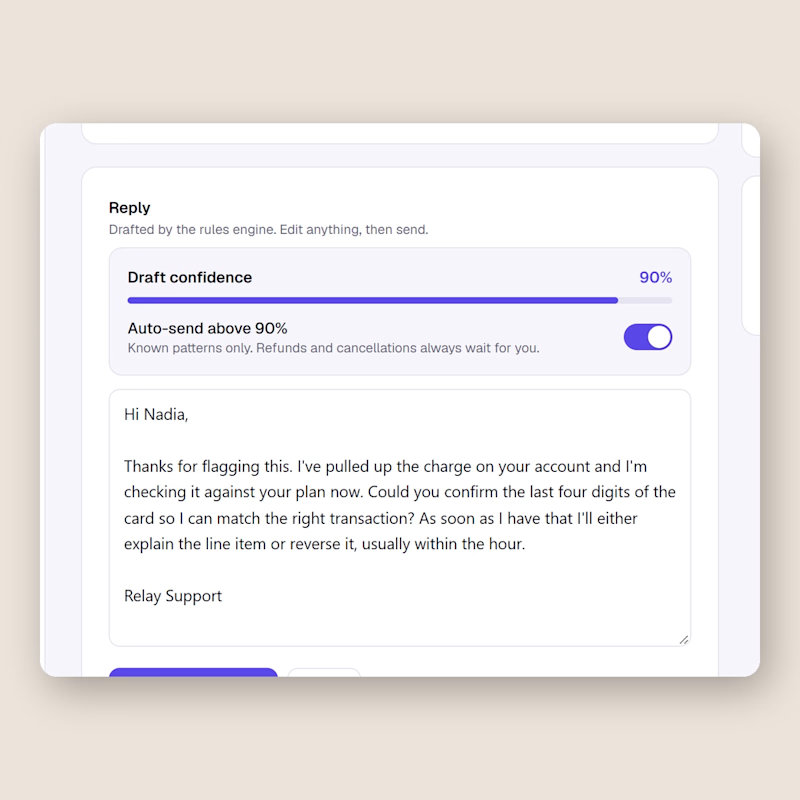
Same support inbox, one difference. Left keeps a human on every send. Right lets the AI send on its own once the draft confidence passes 90, refunds and cancellations excluded.
I built both in Relay this week and I still cannot decide.
Would you flip that switch for your own customers, and at what number?
0 voted
0%
2 voted
100%
2 votes
Closed

I'd flip it per topic, not per score. A 90 on a question the AI has answered hundreds of times is safe. A 90 on a question it has never seen is still a guess. Can Relay set a different threshold per topic?

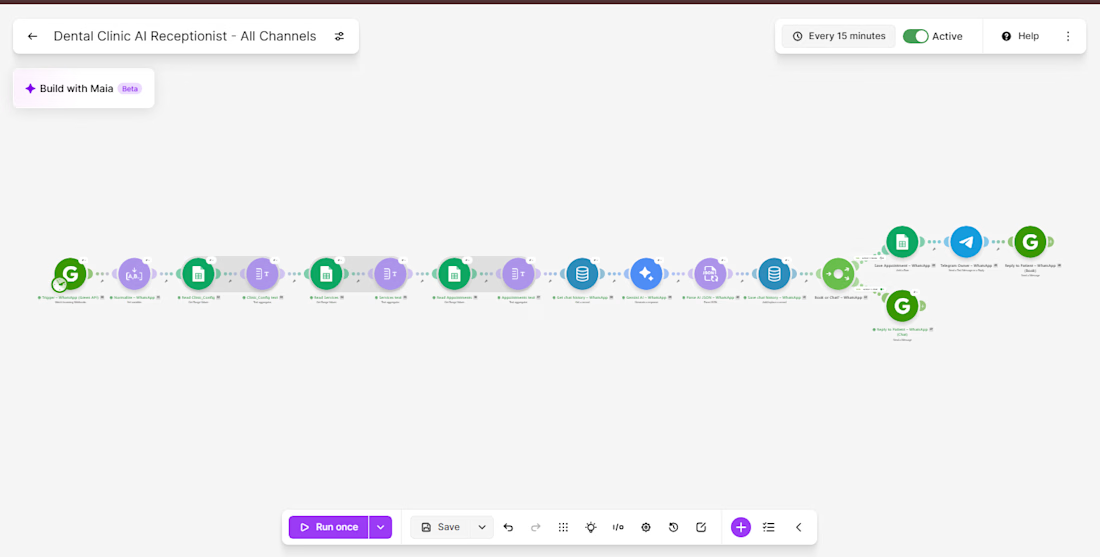
🚨 A dental clinic was losing patients every single day.
Not because of bad service. Not because of high prices.
Because nobody was replying to messages.
Patients messaged on WhatsApp, Messenger, SMS… And waited. And waited. And left.
The clinic owner contacted me with one simple ask:
“I can’t hire someone to reply 24/7. Can you help?”
So, I built them an AI receptionist that never sleeps. 👇
Here’s exactly what it does:
✅ Omnichannel Support: Instantly replies to patients on WhatsApp, Facebook Messenger & SMS — all from one system.
✅ Human-like AI: Google Gemini AI understands the message, detects intent, and replies naturally.
✅ Smart FAQ Handler: Answers questions about services, pricing & clinic hours by pulling live data from Google Sheets.
✅ Automated Booking: Checks availability, blocks double-bookings, and confirms only after saving to the sheet.
✅ Instant Alerts: Notifies the clinic owner instantly via Gmail + Telegram on every new booking.
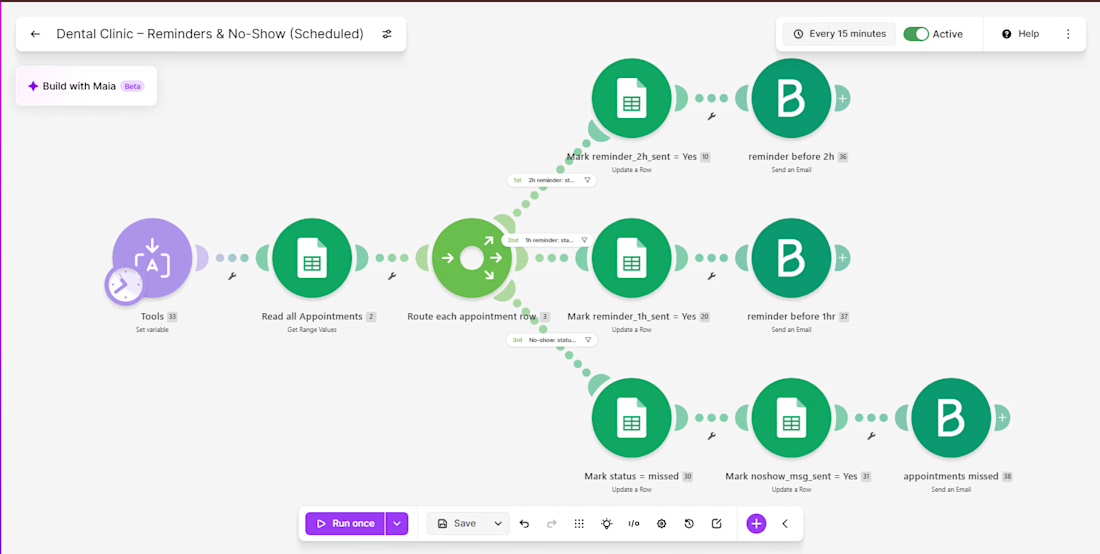
✅ Smart Reminders: Sends automated email reminders — 2 hours and 1 hour before the appointment.
✅ No-Show Recovery: Detects missed appointments and automatically sends a polite rescheduling email after 12 hours.
The Tech Stack 🛠️:
⚙️ Make.com — Automation backbone
🧠 Google Gemini 2.0 Flash — AI brain
📊 Google Sheets — Live clinic database
💬 Green API — WhatsApp integration
📱 Facebook Messenger API & Twilio — Chat & SMS
✉️ Brevo — Email reminders
📢 Telegram Bot — Owner notifications
💾 Make.com DataStore — Conversation memory per patient
The Result? 📈
Every patient gets an instant, intelligent reply — 24/7. No missed bookings. No forgotten appointments. No manual follow-ups.
The clinic owner now wakes up to confirmed appointments already in the sheet with zero manual effort.
This is what I build for businesses. If you’re still replying manually and losing leads while you sleep — DM me. Let’s fix that. 👇
#MakeAutomation #AIAutomation #NoCode #Makecom #GeminiAI #WhatsAppAutomation #BusinessAutomation #AIReceptionist #FreelanceAutomation #Upwork #Fiverr



Nice build, and very close to a WhatsApp assistant I just built for a dental-clinic use case on the WhatsApp Cloud API. Two things mattered a lot in testing: when a patient asks for a person, the bot has to go completely quiet for that chat until the owner hands it back, and the...