The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost
Taste Test
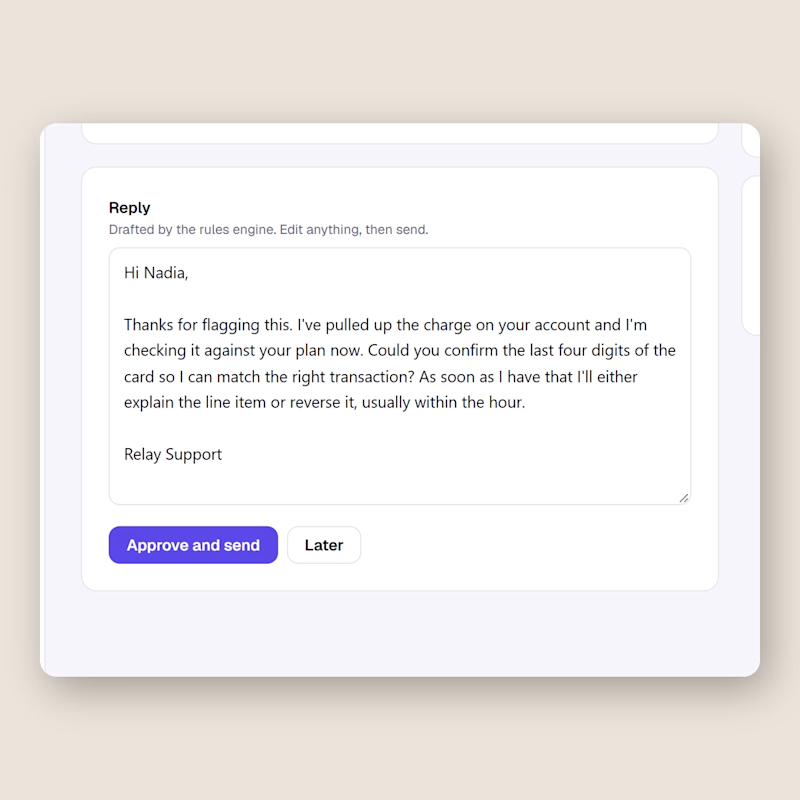
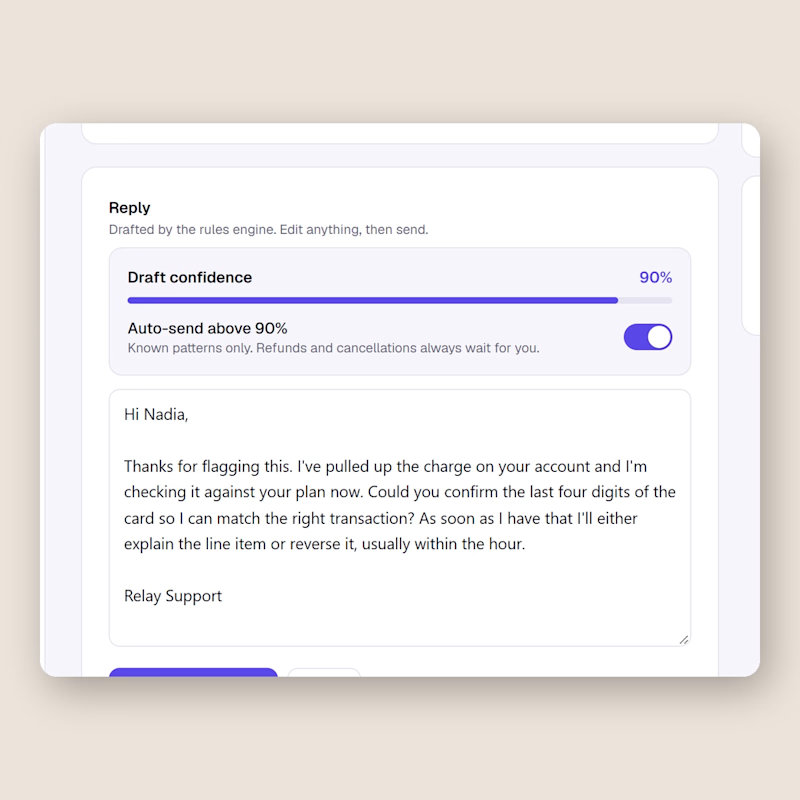
Same support inbox, one difference. Left keeps a human on every send. Right lets the AI send on its own once the draft confidence passes 90, refunds and cancellations excluded.
I built both in Relay this week and I still cannot decide.
Would you flip that switch for your own customers, and at what number?
0 voted
0%
2 voted
100%
2 votes
Closed

I'd first keep replies above 90 in draft mode and compare them with the final human-reviewed replies. Among those drafts, how often is the answer correct, and does that vary between FAQs and account-specific requests?

that's the right experiment and it's nearly free to run. shadow mode, every draft above 90 gets logged next to what the human actually sent, then diff the two. my bet is FAQs clear 95 percent and account-specific requests fall apart, because the model can't see the ledger. which...

I'd split it by what the reply does, not by the score. In the support assistant I built, plain answers from the help docs go out with their sources, but anything that changes an order or refunds money waits for a person, at any confidence. A model can be confidently wrong on an...
no cluster data yet, honestly. the shadow log is this weekend's build, so right now it's a bet, not a result. your split is the one i trust more than the score too, and Relay already half-does it, refunds and cancellations never auto-send whatever the number says. where i expect...
Retrieval with citations. The help docs are split into chunks, searched per question, and every answer cites the passages it used. Your point about facts the email doesn't contain is where I'd expect the misses too. In that project, order status and refund eligibility never come...

Auto-send above 90% is absolutely better because Draft confidence tool is more practical ❤️❤️❤️
great job Ali🔥🔥🔥
Pardon Ali ❤️
Great idea 🎉🎉

I'd flip it per topic, not per score. A 90 on a question the AI has answered hundreds of times is safe. A 90 on a question it has never seen is still a guess. Can Relay set a different threshold per topic?
Draft only, no floor. Let a new topic earn auto-send: once its last 20 drafts went out unedited, open it at 90. One heavy edit by a human sends it back to draft.
That is a cleaner rule than any threshold I would have picked. The topic earns it, the human's edits take it away. I will put that counter into the shadow log this week: last 20 unedited opens the topic at 90, one heavy edit resets it. What counts as heavy for you, any change to a number or date, or a diff over some size?
The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started








Related posts


Your Hero Section Has One Job: Be Clear.
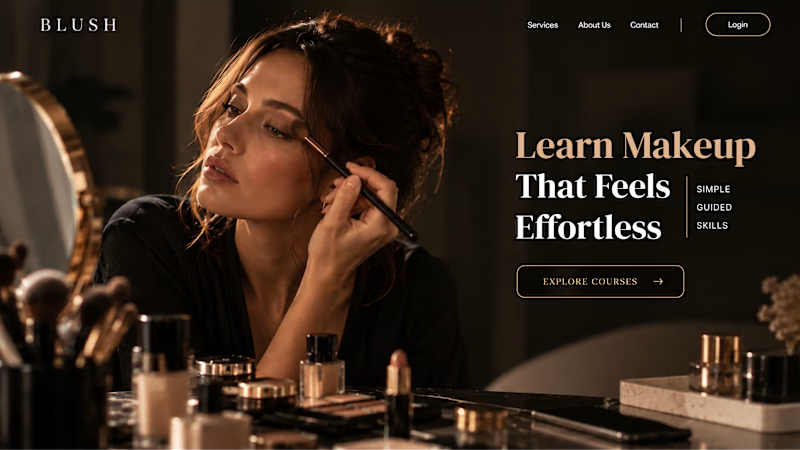
You don’t need huge headlines or long explanations. You need the right image + short headline + clear offer.
For the first version, we worked on the branding, the image and the copy together, so at first glance it’s clear: this is a makeup course, and here’s what you’ll get.
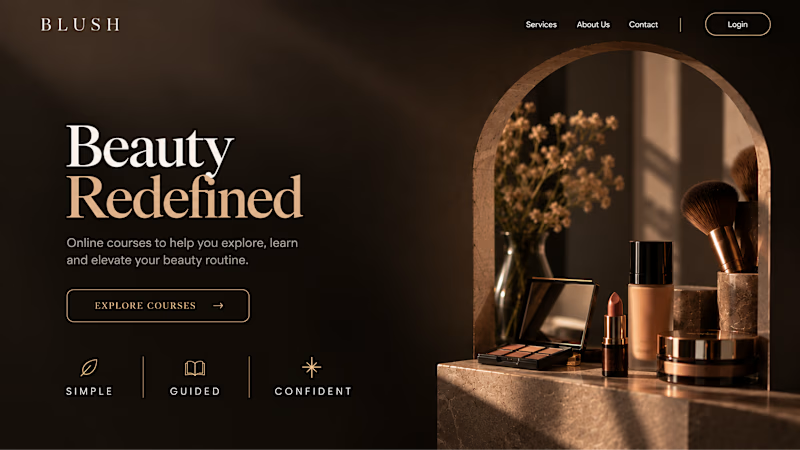
The second version is still beautiful and still feels like beauty. But what are you actually getting? A makeup course? Products? A store? That’s the problem with a Hero that looks good but isn’t thought through.
Your first screen doesn’t need to say everything. It just needs to say the right thing.

22 voted
61%
14 voted
39%
36 votes
Closed


I’ve been working on a bold, modern-retro logotype and can’t decide between these two options.
🆘 Which one feels more aesthetically pleasing to you?

11 voted
26%
31 voted
74%
42 votes
Closed
CAPITAL is great but SMALL is unique great job Nawras 🔥🔥

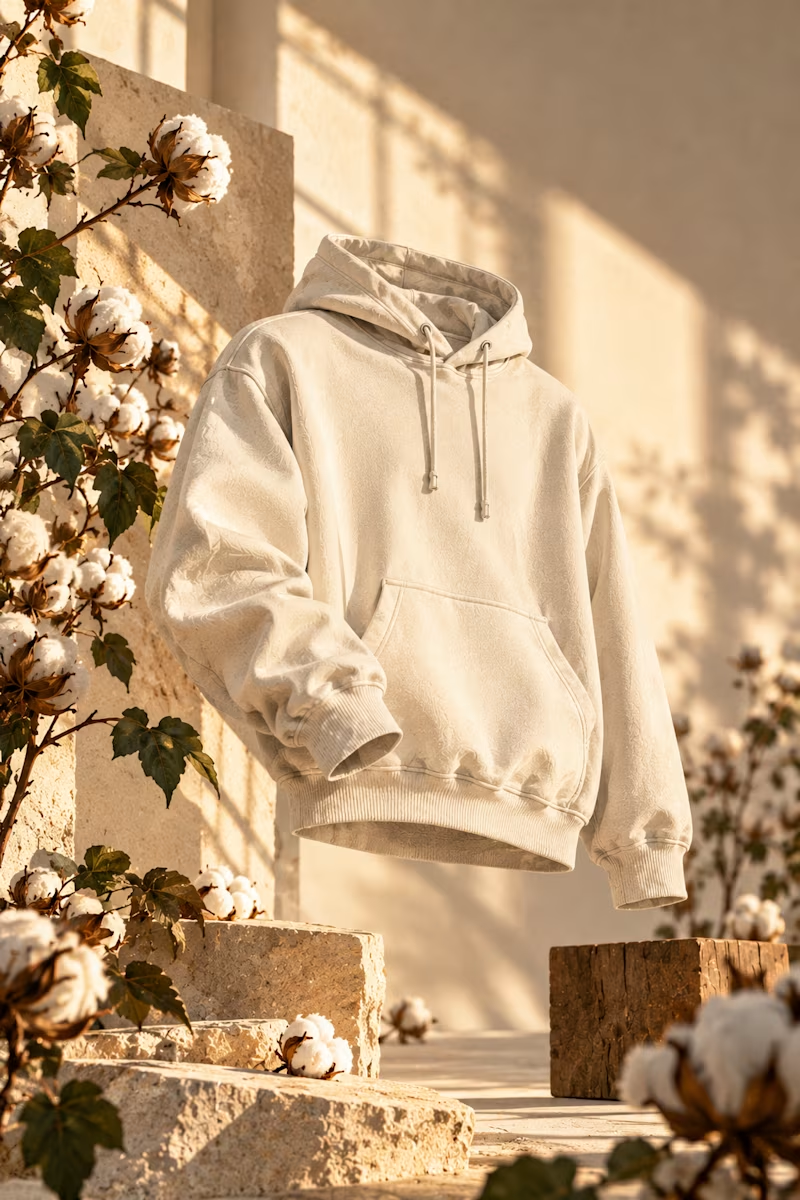
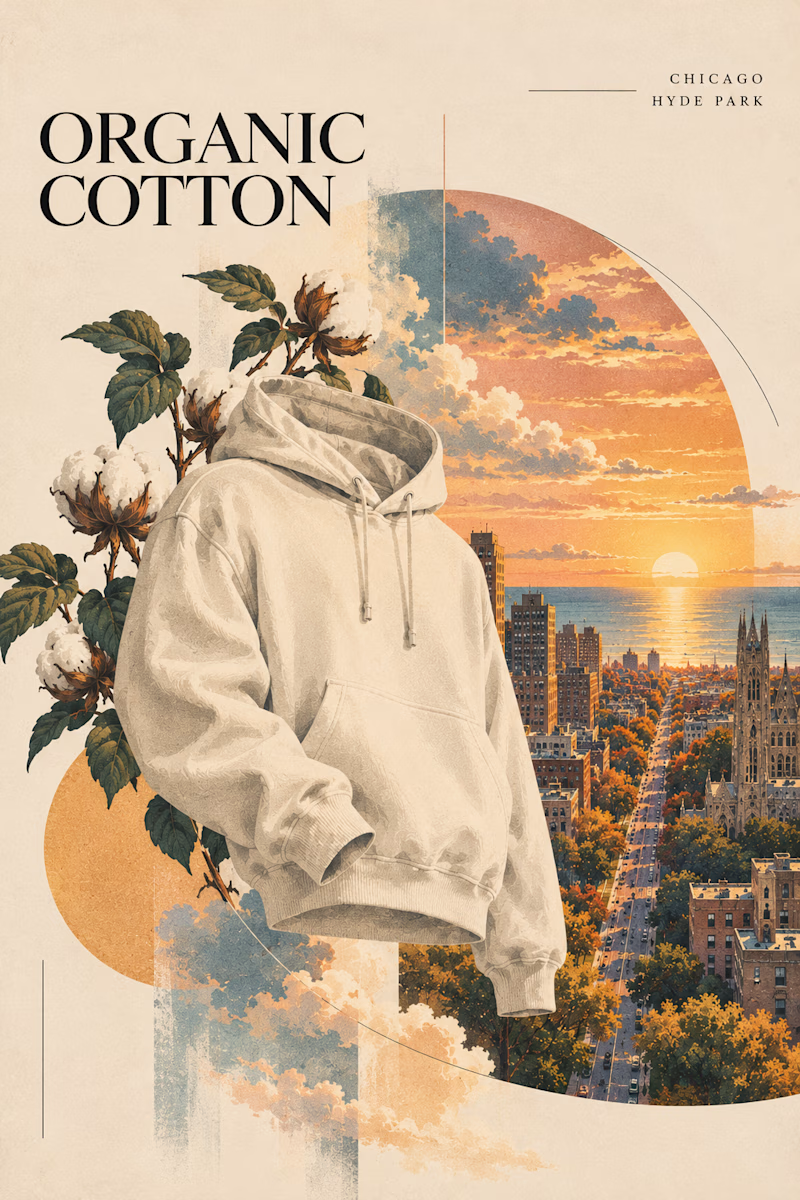
Two directions for an organic cotton apparel campaign. Which style works better?

6 voted
60%
4 voted
40%
10 votes
Closed
Sunlight studio is more stunning 🔥🔥
great job Mitchell❤️