The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

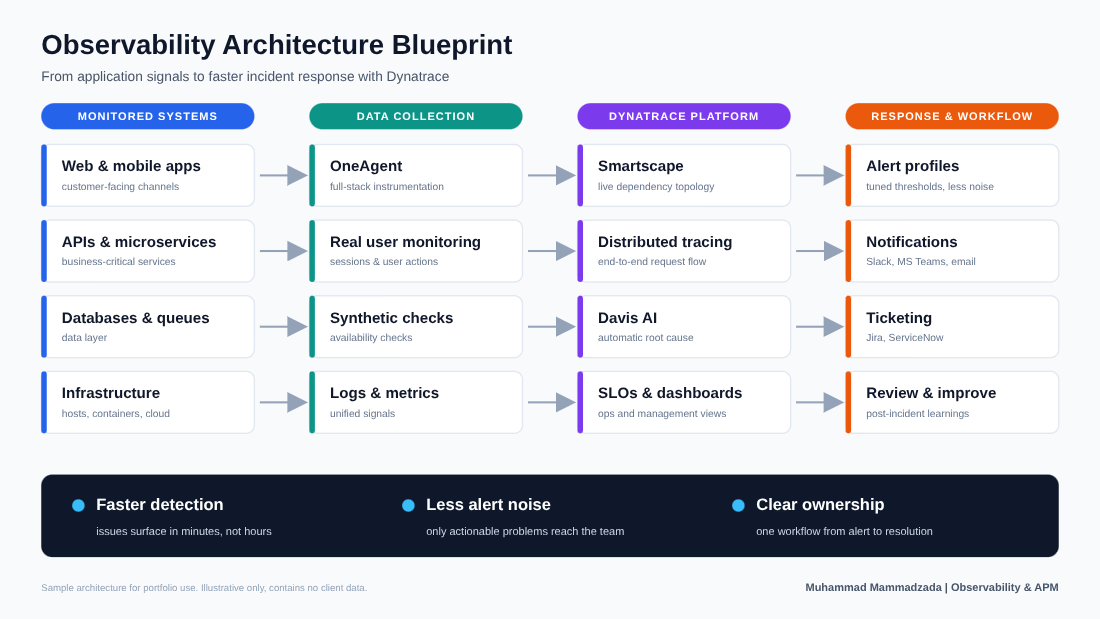
A sample observability architecture I designed to show how a team can go from raw application signals to faster incident response using Dynatrace.
The challenge: Growing teams often have logs, metrics and traces scattered across tools, so finding the root cause of a production issue takes too long and alerts become noise.
What I did:
Mapped the full flow: monitored systems → data collection → Dynatrace platform → alerting and workflow
Covered APM, real user monitoring, synthetic checks, distributed tracing and logs in one view
Defined how alerts reach the right people through Slack/Teams and Jira/ServiceNow
Planned SLO dashboards for both operations and management
Tools: Dynatrace, Smartscape, Davis AI, Jira, ServiceNow
This is a generic blueprint with no client data. I can adapt it to your stack and run a short audit of your current monitoring setup.


The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started



Related posts

AI Analytics Dashboard
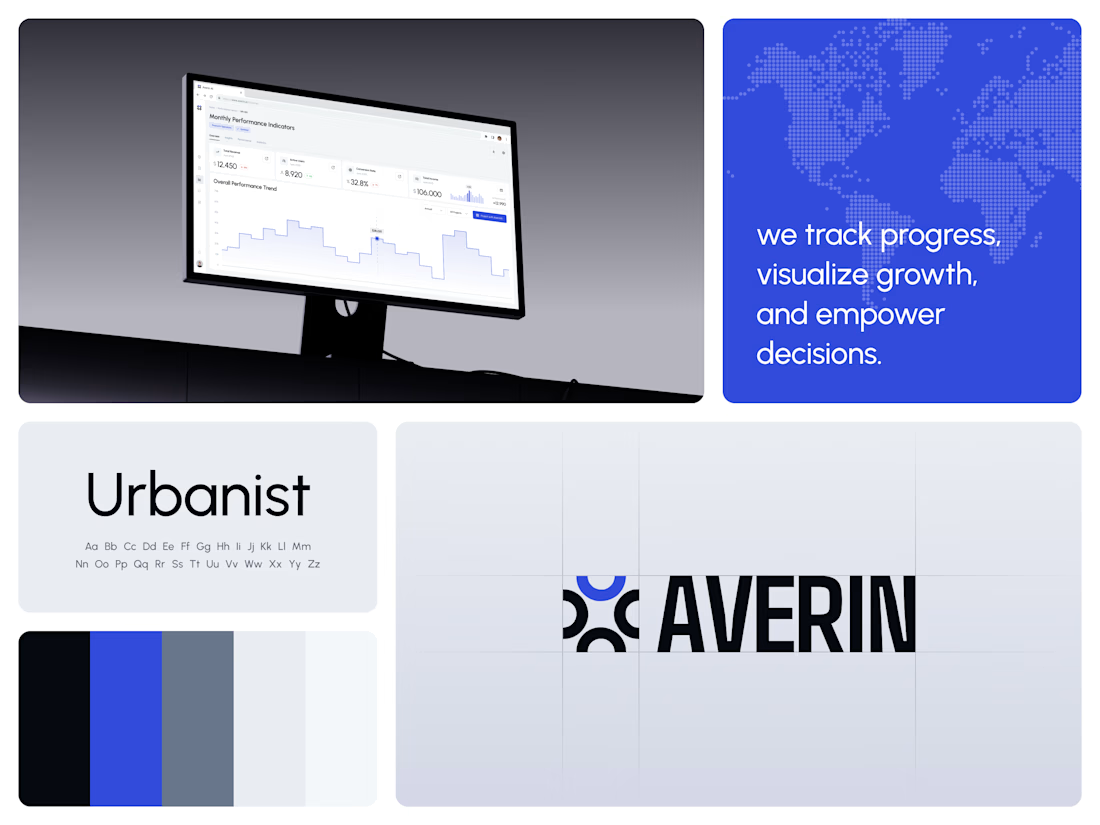
One blue runs from the logo to the chart line.
Revenue, active users, conversion rate and income sit in a row of cards above the trend chart. The cards answer where the numbers stand. The stepped line answers how they got there, holding each period's value until the next, with a tooltip on a dashed guide line for the exact figure.
The identity pairs a four-arc mark with a condensed wordmark, drawn to the same top and bottom lines on the construction grid. The top arc's blue comes back in the slogan tile, the chart line and the main button, so the brand and the product share one accent.
Designed by the Hue & Machine team.
#DashboardDesign #DataVisualization #SaaS #Analytics #AI #WebApp #BrandIdentity #UIDesign #ProductDesign #FigmaDesign



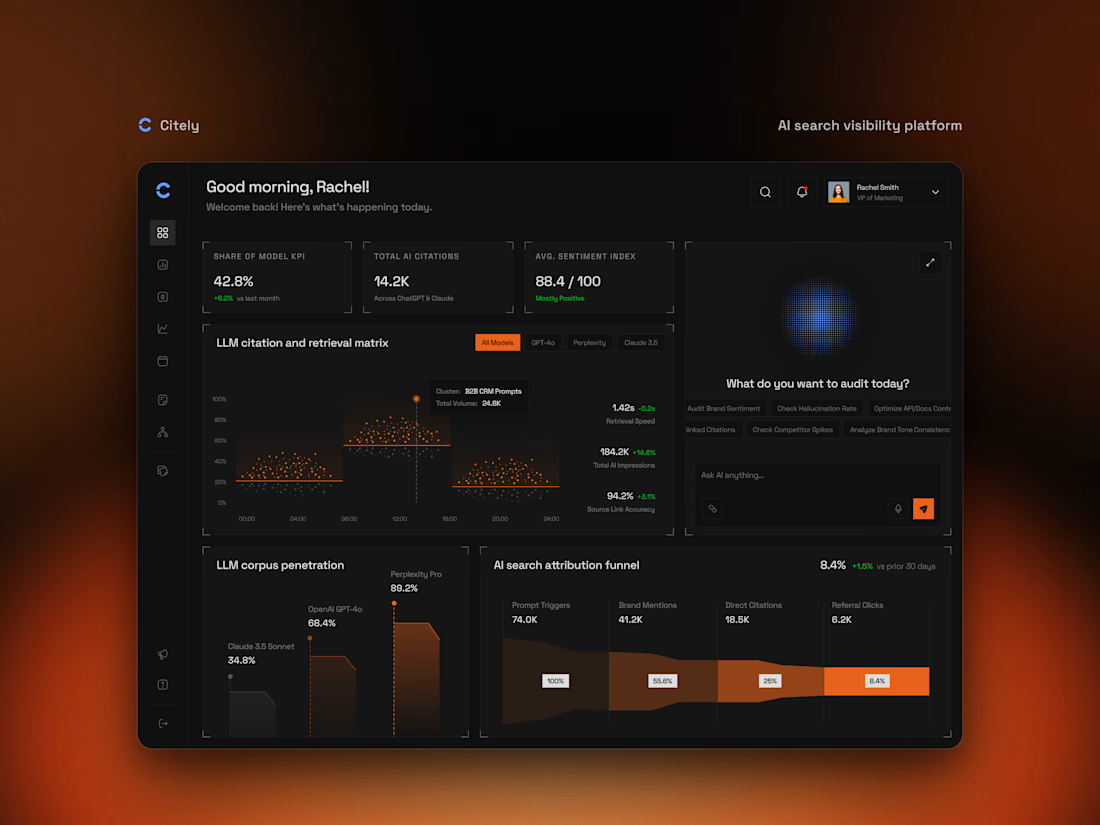
Been working on a dashboard for an AI search visibility platform. It shows how ChatGPT, Perplexity and Claude talk about your brand, all on one screen.
Went dark with a single orange accent to keep the data calm.
What would you change?