The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost


An AI agent becomes much more useful when it has somewhere real to work.
Not another disposable chat. A private Linux workspace where it can keep project context, use browser and terminal tools, run automations, and leave behind inspectable files, logs, and deployed systems.
This is the operating model behind two recent builds:
InterviewCoach: Android/Compose + FastAPI/LangGraph, a public APK, and 111,723 deterministic load-test requests with 0 failures.
An omnichannel agent: one LangGraph-controlled brain, PostgreSQL/pgvector state, and active Instagram, Telegram, and WhatsApp adapters.
I have now made the same managed environment available as a Contra product. Starter is $30/month: 2 vCPU, 4 GB RAM, 40 GB storage, automation runtime, controlled Google sign-in, and 30 minutes of expert support.
The boundary is explicit: the subscription covers the workspace and its support allocation. Custom integrations, migration, and production hardening are scoped separately.
If you are a founder or operator with one real workflow to prove before committing to a larger build, this is the entry point.


The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Related posts

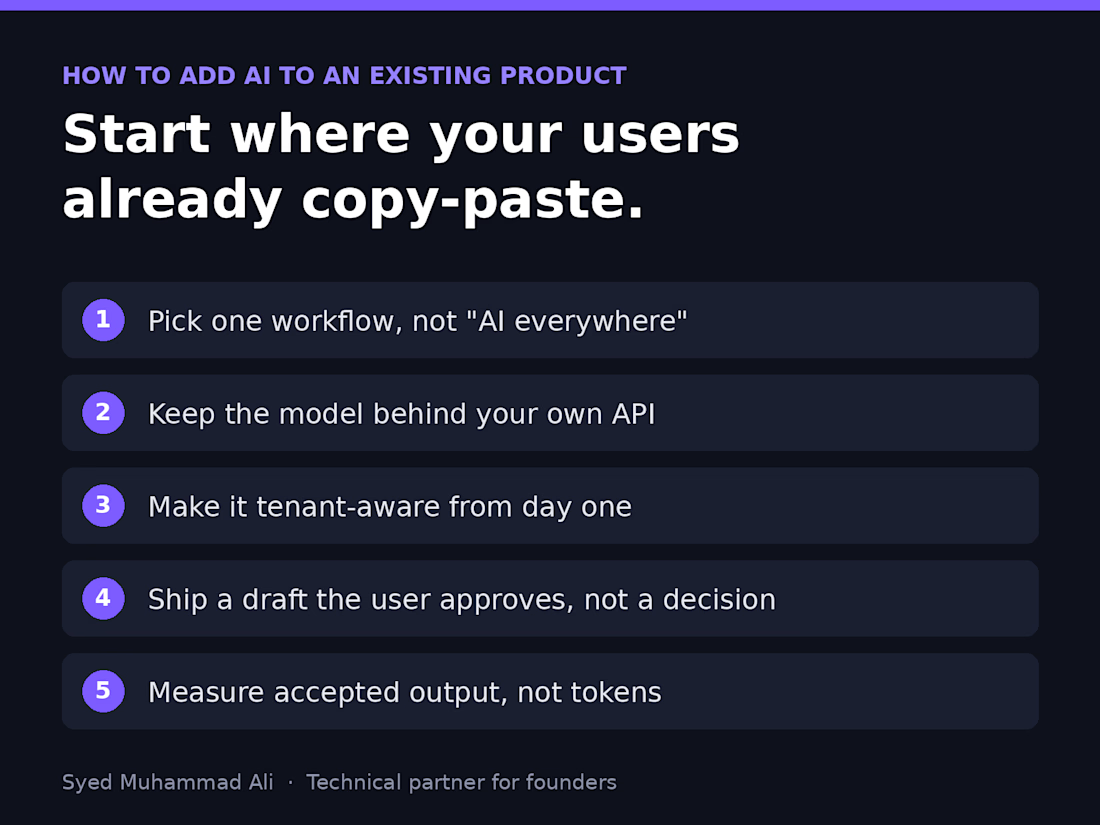
Before you add AI to your product, find the screen where your users already copy and paste.
That's usually where the real AI feature lives. Not a chatbot in the corner, but a step people already do by hand: summarising a ticket, drafting a reply, tagging an upload, pulling fields out of a PDF.
Here's the order I follow when a founder asks me to add AI to an existing SaaS:
1. Pick one workflow, not "AI everywhere." Watch where users leave your app to paste something into ChatGPT and come back. That round trip is your feature.
2. Keep the model behind your own API. One service owns prompts, retries, logging and cost limits, so you can switch providers without touching the frontend.
3. Make it tenant-aware from day one. Each customer's data, prompts and usage stay scoped to their account, or the first enterprise security review will stop you.
4. Ship a draft, not a decision. Let the AI suggest and the user approve. You earn trust and get real feedback before you automate anything.
5. Measure accepted output, not tokens. If users rewrite most of what it produces, the prompt or the context is wrong, and that's your real roadmap.
Most AI features that flop didn't fail because of the model. They were bolted onto the wrong step.
What's the one task your users still copy into ChatGPT?

Watching where users paste into ChatGPT and come back is such a practical way to find the real feature. Most teams start with the chatbot instead.

Everyone is shipping AI agents right now. Almost no one is testing them — and that is the whole problem.
A demo agent and a production agent are different animals. The demo works because you walked it down the happy path. Production breaks on the paths you never imagined.
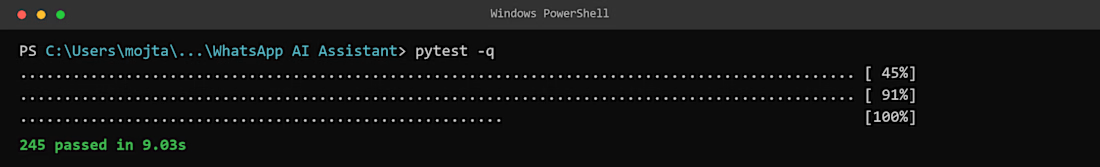
A real example from my own work: a support assistant correctly handed a conversation to a human when someone wrote "I want to talk to a person" in Spanish — but not in English, because one phrase was missing from a rule. Every automated test passed. It only surfaced when I ran real conversations through it.
That is the gap the "agents will replace everything" wave keeps skipping. The hard part was never making an agent act. It is making it:
• say "I don't know" instead of guessing,
• hand control back to a human at the right moment,
• and prove, with tests, that it still behaves when the input gets strange.
Autonomy is cheap. Trustworthy autonomy is the real engineering.
Before you let an AI agent near real users or real data — what is the first thing you check?


The Spanish vs English handoff bug is such a good example. Every test passes until a real user shows up.

Most inbound bottlenecks aren't caused by low lead volume—they happen during triage.
When inquiries roll into a Google Sheet or CRM, operations teams often waste 10–15 minutes per submission reading through messy paragraphs, deciphering budget mismatch, and manually deciding who gets an immediate call vs. a standard rate sheet.
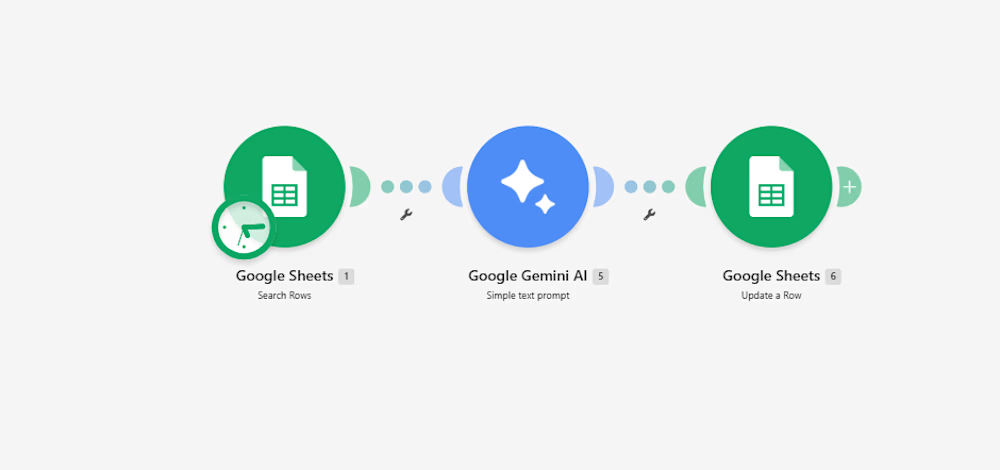
Instead of adding a bulky CRM add-on, I documented a lightweight 3-step automation pipeline built inside Make:
Intake & Extraction: An active listener triggers immediately upon a new submission, extracting core variables: client scope, target deliverables, timeline, and stated budget.
Context-Aware Evaluation (Gemini 2.5 Flash): The payload passes through an AI evaluation node with strict guardrails:
Evaluates budget against minimum agency criteria.
Assigns a triage score: Hot (immediate priority), Warm (nurture), or Cold (disqualified/template reply).
Generates a strict 15-word operational summary—no long paragraphs.
Determines an automated next step (e.g., routing to an account lead or flagging for asynchronous follow-up).
Data Return & Clean Pipeline: Appends the structured classification directly back to the master operational tracker, keeping the sheet filterable and clean.
The outcome: The sales and operations team can filter the entire board by priority status in two clicks, cutting first-touch response time to minutes without manually reading every single submission.
I’ve documented the full scenario map, execution logic, and data schemas below.
Curious how other agency operators and automation leads here handle their lead enrichment layer—are you doing AI scoring at the form level, or later in the CRM pipeline?:


For the budget gate, I'd keep an unstated budget separate from one explicitly below your minimum. Does the Make route ask for clarification when the amount or currency is missing, so a potentially suitable lead doesn't fall into Cold by default?