The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost


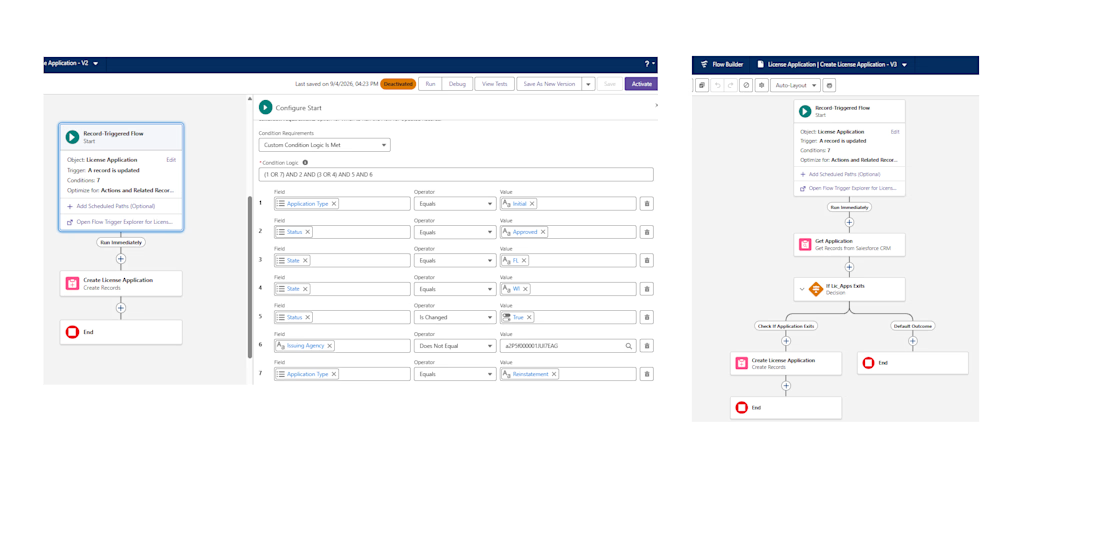
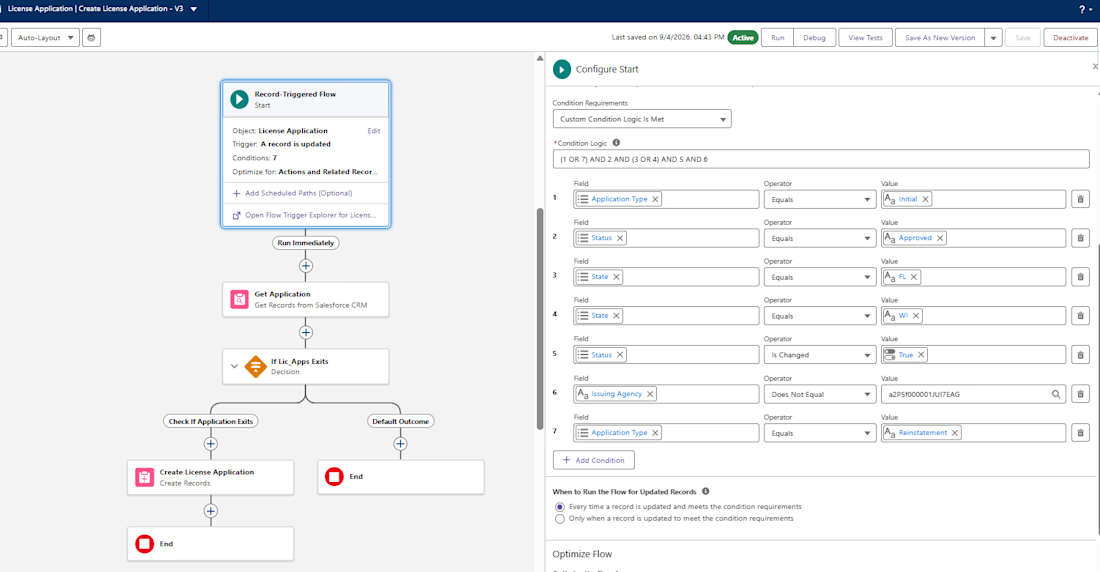
Optimized a Salesforce Flow Automation to prevent the creation of duplicate records when the flow runs. Previously, the automation did not perform duplicate checks, which could result in unnecessary and inaccurate records.
As a Salesforce Developer, I implemented Salesforce best practices to improve data quality, streamline Salesforce automation, and reduce manual effort. I also focused on clean Salesforce CRM data and scalable automation.
This solution helps the client maintain a clean database, improve team efficiency, and ensure users work only on the records that require their attention, helping the business scale faster.
Salesforce Developer | Salesforce Flow Automations | Salesforce Apex | Salesforce LWC Expert | HubSpot Expert | HubSpot CRM | HubSpot Setup | HubSpot Automation | HubSpot RevOps


The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started




Related posts

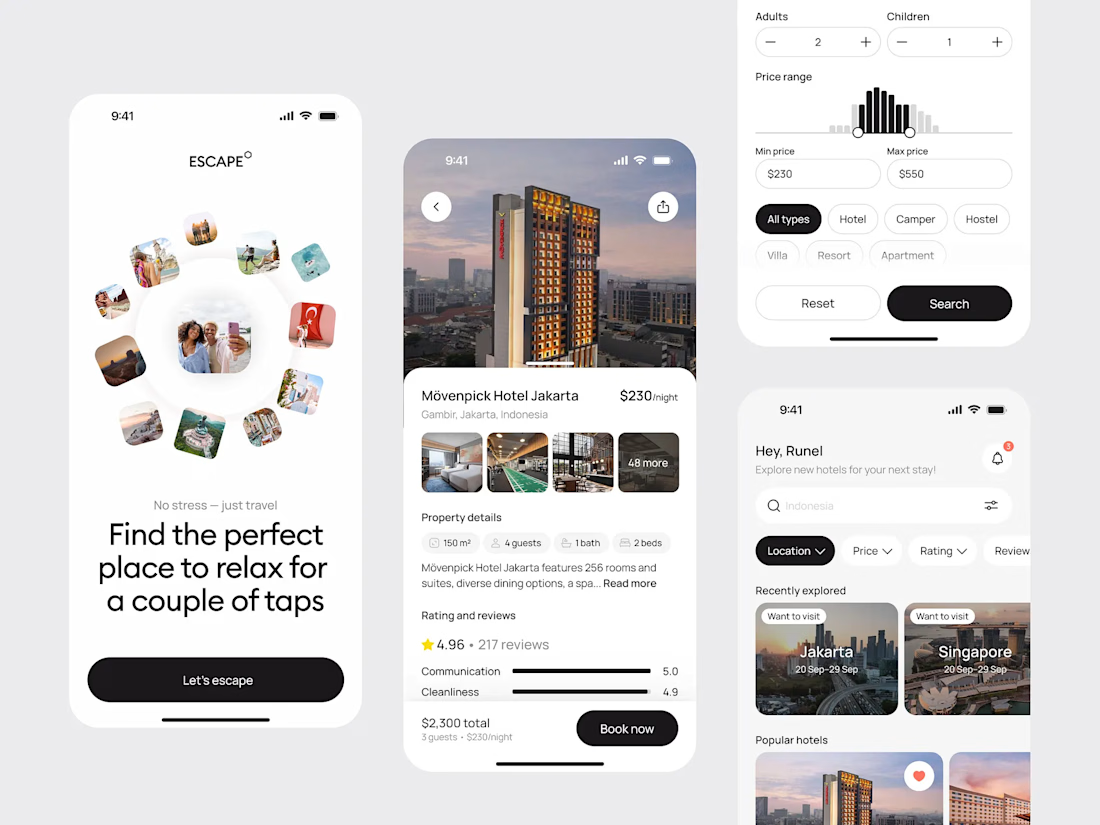
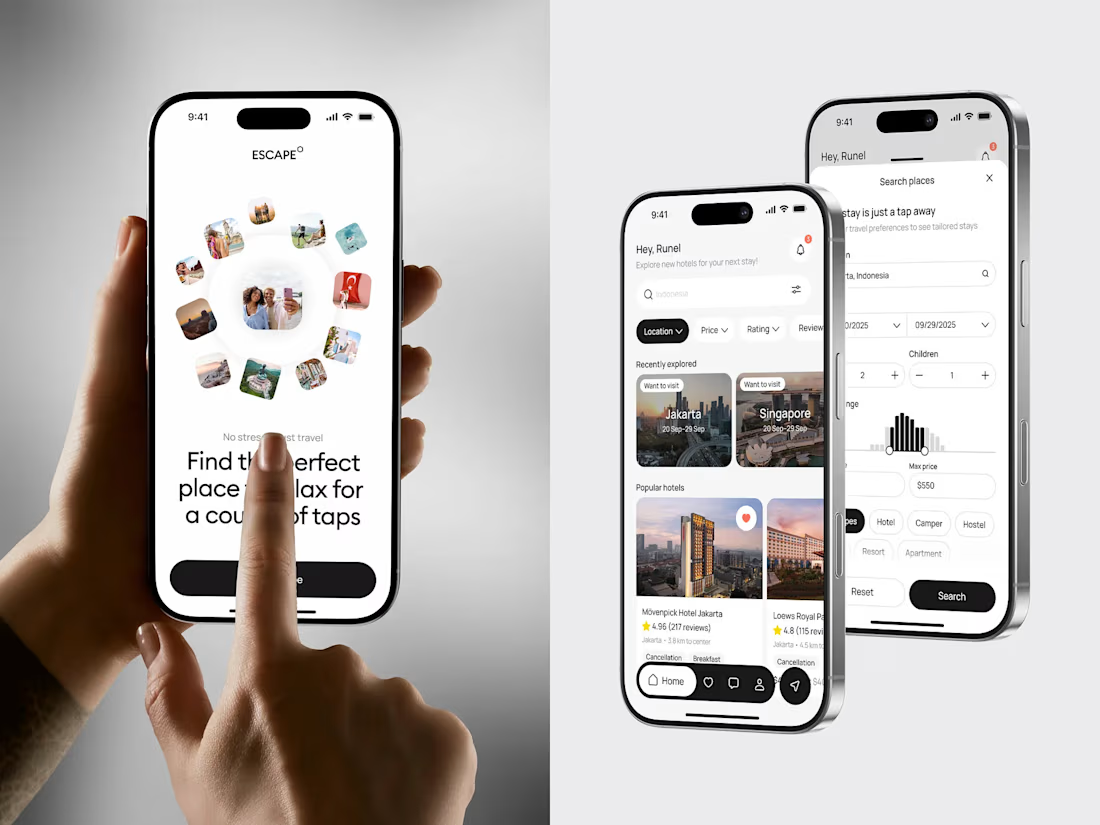
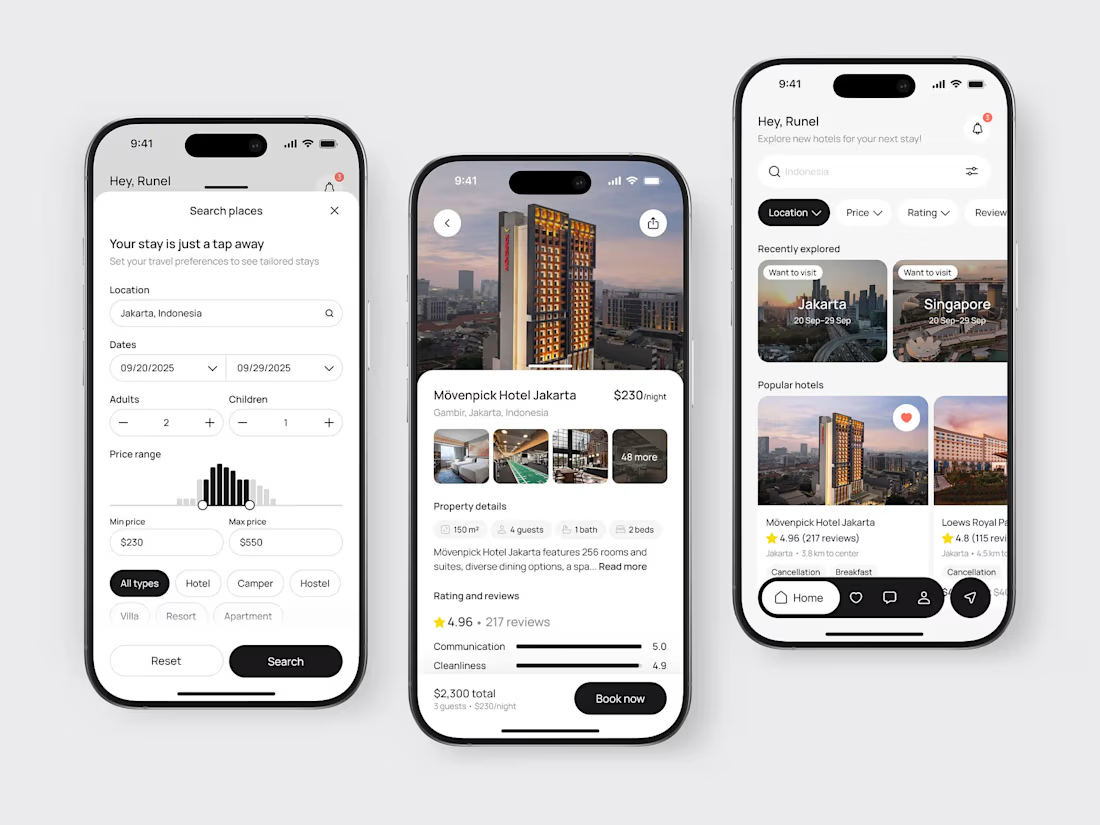
Really clean and polished app design! The booking flow looks intuitive and the overall UI feels modern and easy to use. 👏



good work


The isometric integration map as the hero does a lot of heavy lifting, it makes an abstract on-call product feel tangible at a glance instead of a wall of logos.

AI Assistant Using Your Business Knowledge Base — RAG on Your Documents
THE PROBLEM
Q&A bots break down when knowledge lives in documents: a 100-page manual has no "questions" to match, it can't fit into a prompt, and generic chatbots hallucinate instead of admitting what they don't know.
THE SOLUTION
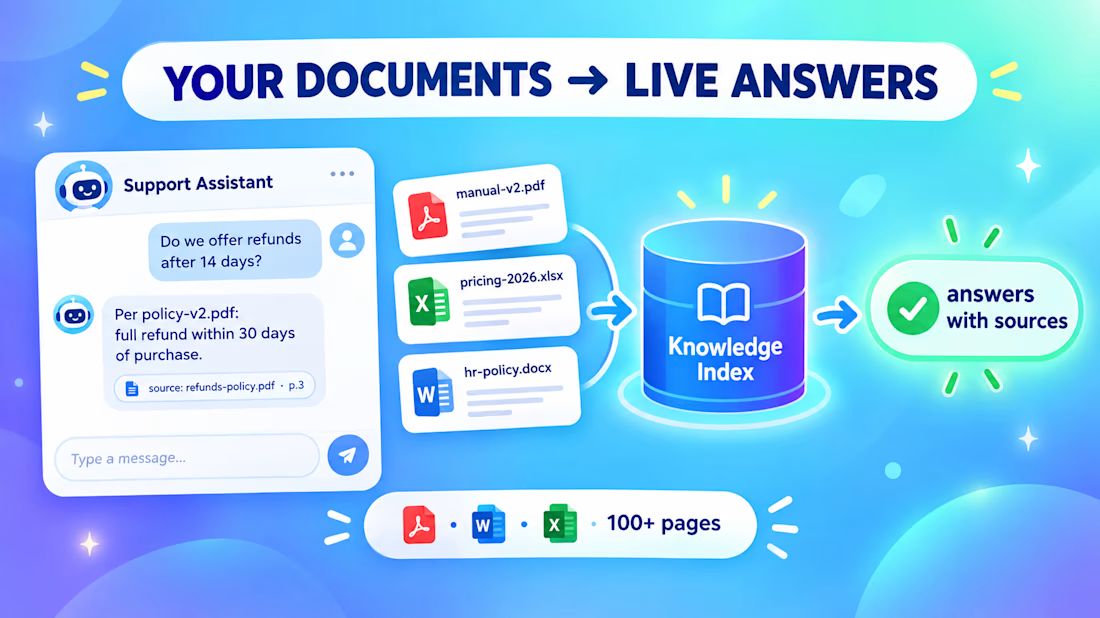
A RAG (Retrieval-Augmented Generation) knowledge base: documents are split into meaningful chunks, embedded into a vector index, and the assistant answers from the right sections — by meaning, not keywords.
Any format as-is: PDF, DOCX, TXT, Markdown — 100+ pages is fine
Answers grounded in YOUR documents — it says "I don't have that information" rather than inventing
Source references — every answer shows which document and section it came from
Runs on your infrastructure — documents never leave your control
One command to re-index after updating documents — documented, no programmer needed
LIVE DEMO
Ask it about my products, pricing, deployment and support — it answers from 6 real documents with sources:
https://kb-assistant-demo.dvc-ai.workers.dev



The 'I don't have that information' line is the part most RAG builds skip, and it's the one that matters. How do you set the cutoff? On mine, a fixed similarity threshold broke once I filtered results by user role. Scores shifted and it refused questions it could answer.