The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

IMDB Movie Review Sentiment Analysis
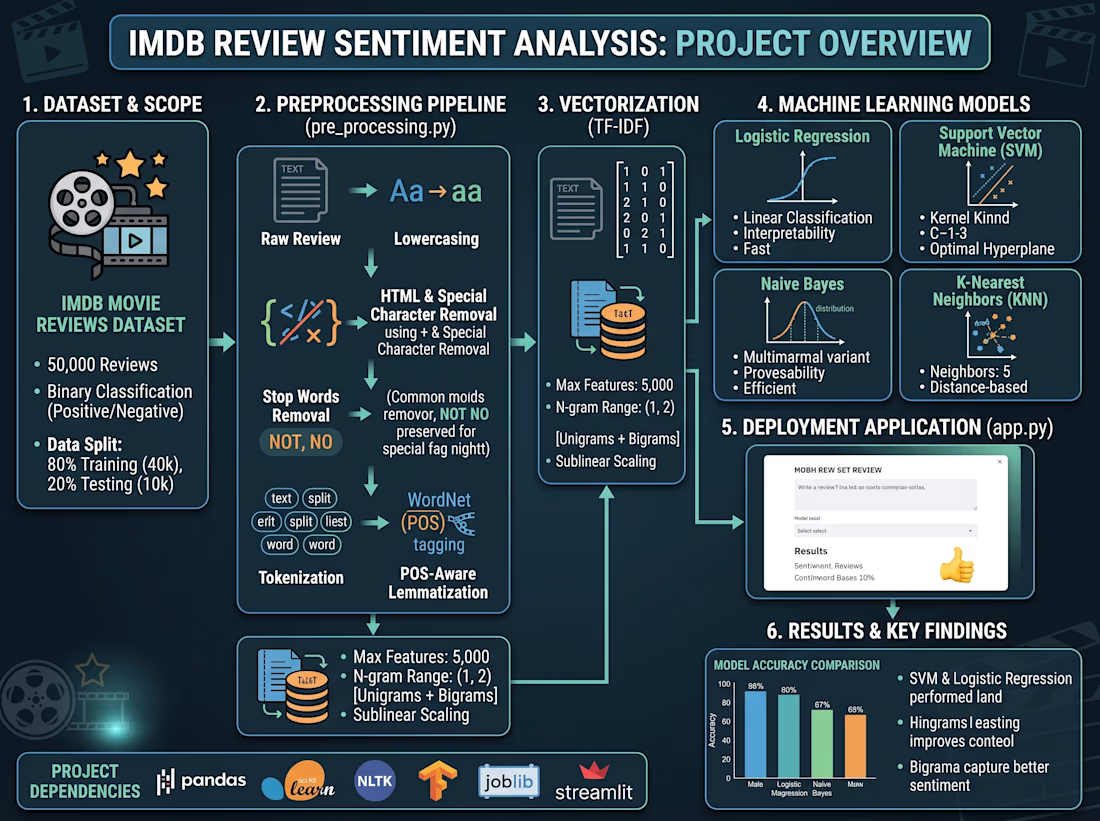
Built an end-to-end Natural Language Processing system to classify 50,000 IMDB movie reviews as positive or negative.
The project includes a complete text preprocessing pipeline with tokenization, stop-word handling, POS-aware lemmatization, and negation preservation. I used TF-IDF vectorization with unigram and bigram features and trained and compared four machine learning models: Logistic Regression, SVM, Naive Bayes, and KNN.
The best-performing models achieved approximately 90% accuracy, with SVM and Logistic Regression producing the strongest results. I also built a Streamlit web application that allows users to enter reviews, select a trained model, and receive real-time sentiment predictions with confidence scores.
Key work:
Developed an end-to-end NLP preprocessing pipeline
Implemented TF-IDF feature extraction with n-grams
Trained and compared four classification algorithms
Evaluated models using accuracy, precision, recall, confusion matrices, and classification reports
Serialized trained models for deployment
Built a real-time Streamlit inference application


The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started

Challenges
View all


Related posts

Been building a medical assistant for a client, where you can ask a question and get answers from sources like MedlinePlus, StatPearls, and FDA drug labels, with citations you can check yourself.
This is the empty state. Added a few suggested questions so you have somewhere to start instead of staring at a blank box.
How does the UI feel for a medical product, too sparse, or does the simplicity work?


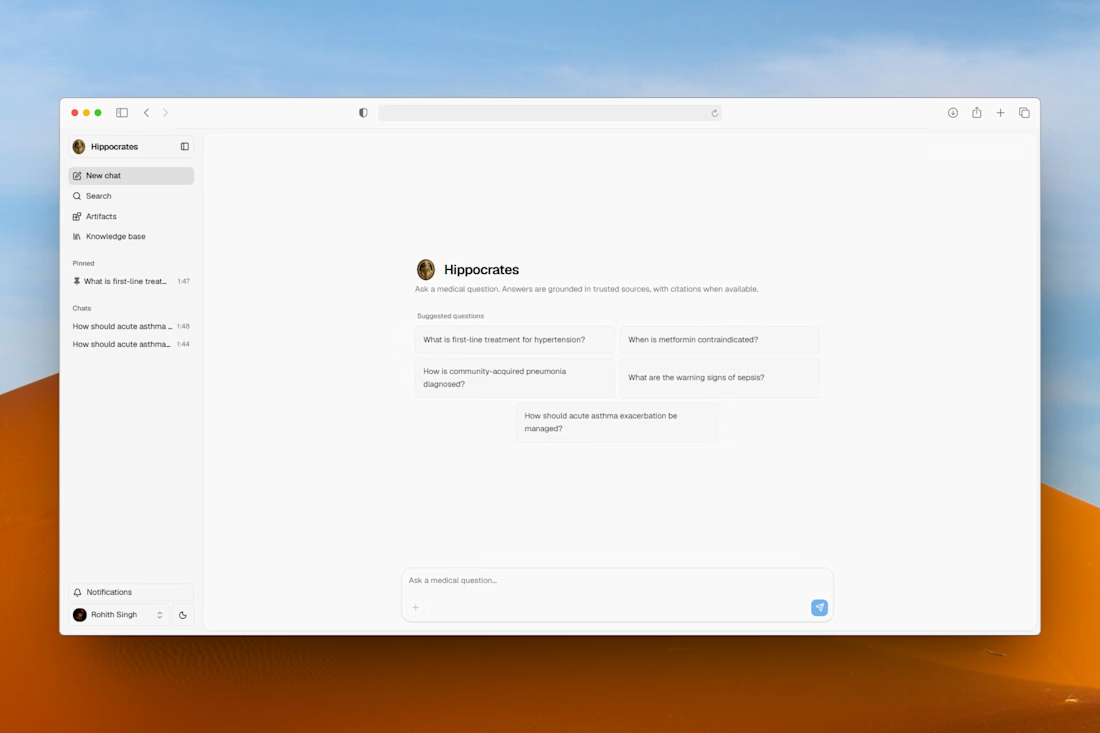

The empty state doesn't wait for a blank query box - it seeds real suggested questions so the first interaction is answering, not figuring out what to ask.

Clean and ready to set your business instantly! Complete workflow, he also make apps in every niche 💯 recommend @Yuvraj Singh


As an AI Engineer, I spend most of my day working in the terminal—so I thought, why not make my portfolio look like one? 🖥️🟩
I wanted a personal site that reflects how I actually work. No flashy animations or endless scrolling, just a clean, interactive command-line interface built with React and TypeScript.
In the video below, you can see how to navigate it. You can type ls projects to see the RAG systems and ML architectures I've built, or cat experience to see my background.
Take it for a test drive and let me know if you discover any of the commands!

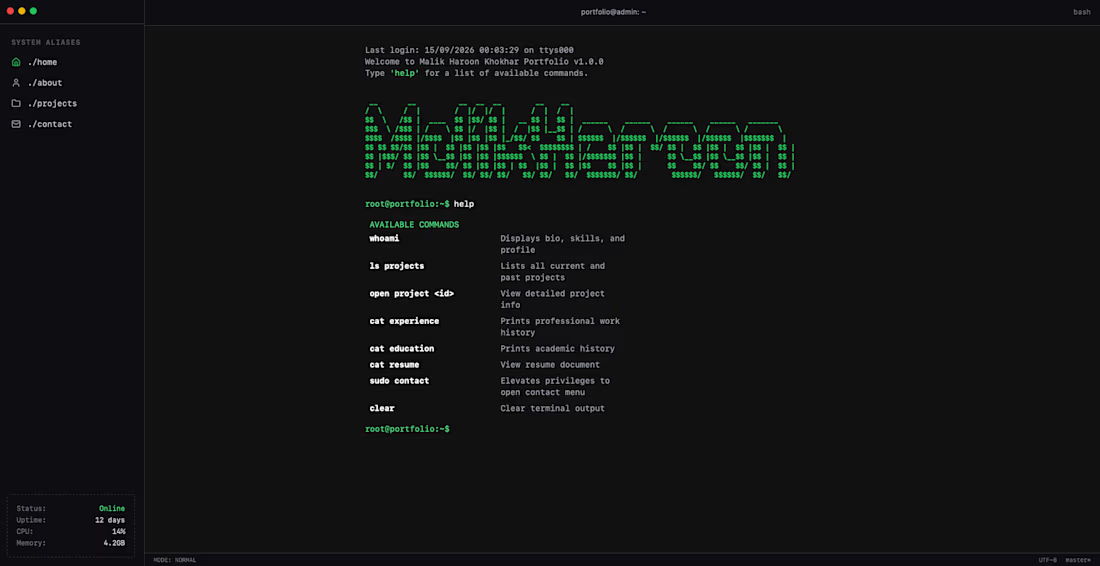

The terminal metaphor is carried through with real discipline—the monospace hierarchy and command-based navigation make the portfolio feel like a tool, not just a skin. Exposing projects, experience, and contact as discoverable commands is a smart interaction detail.