The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

Hi Contra people,
As you know RAG/LLM systems look easy in demo mode. The real learning starts when they hit production. 😅
I recently wrote a Medium article sharing some of my lessons learned while building and deploying RAG/LLM systems — the unexpected challenges, trade-offs, and things that only become obvious once real users and real data enter the picture.
Now I’m curious to hear from the community:
What was your latest “Aha!” moment with RAG/LLM systems?
• What surprised you the most?
• Which approaches worked (or didn’t)?
• What would you do differently next time?
Would love to exchange practical lessons from real-world deployments 👇
#LLM #RAG #GenAI #AIEngineering #MachineLearning #MLOps
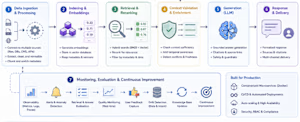
medium.com
Building an Intelligent FAQ Assistant: The Complete Production RAG Pipeline
Moving an enterprise Retrieval-Augmented Generation (RAG) system from a functional codebase to a resilient production service is…
The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started


Related posts

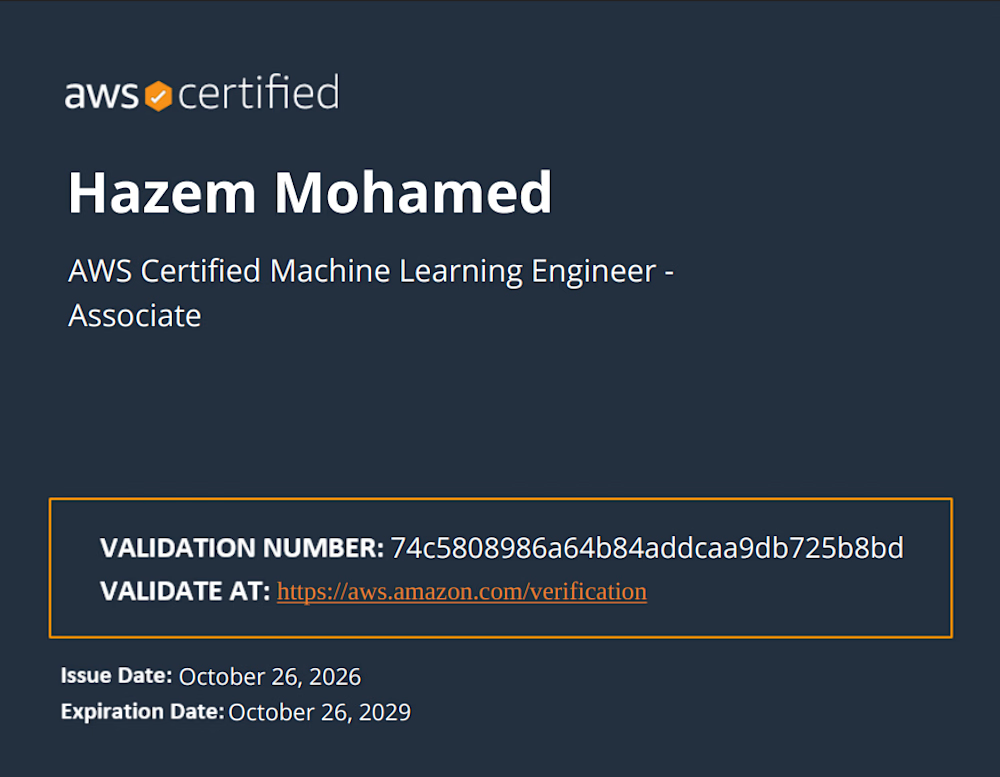
Proud to officially add the AWS Certified Machine Learning Engineer - Associate certification to my toolkit!
Building robust machine learning pipelines and scaling AI workloads securely on the cloud has always been a key focus of mine. Earning this certification has been a great deep-dive into mastering AWS ML infrastructure, MLOps best practices, and production-grade architectures.
Ready to bring these advanced capabilities to upcoming data science and engineering projects! Let's build something impactful. 💡💪
🔗 Verify Certificate:
Validation Number: 74c5808986a64b84addcaa9db725b8bd
Verification Link: https://aws.amazon.com/verification
#AWS #MachineLearning #AI #CloudComputing #DataAnalysis #MLOps



Congratulations on earning the AWS Machine Learning Engineer certification, Hazem khaled! Robust pipelines and cloud automation make all the difference for production-grade AI systems.

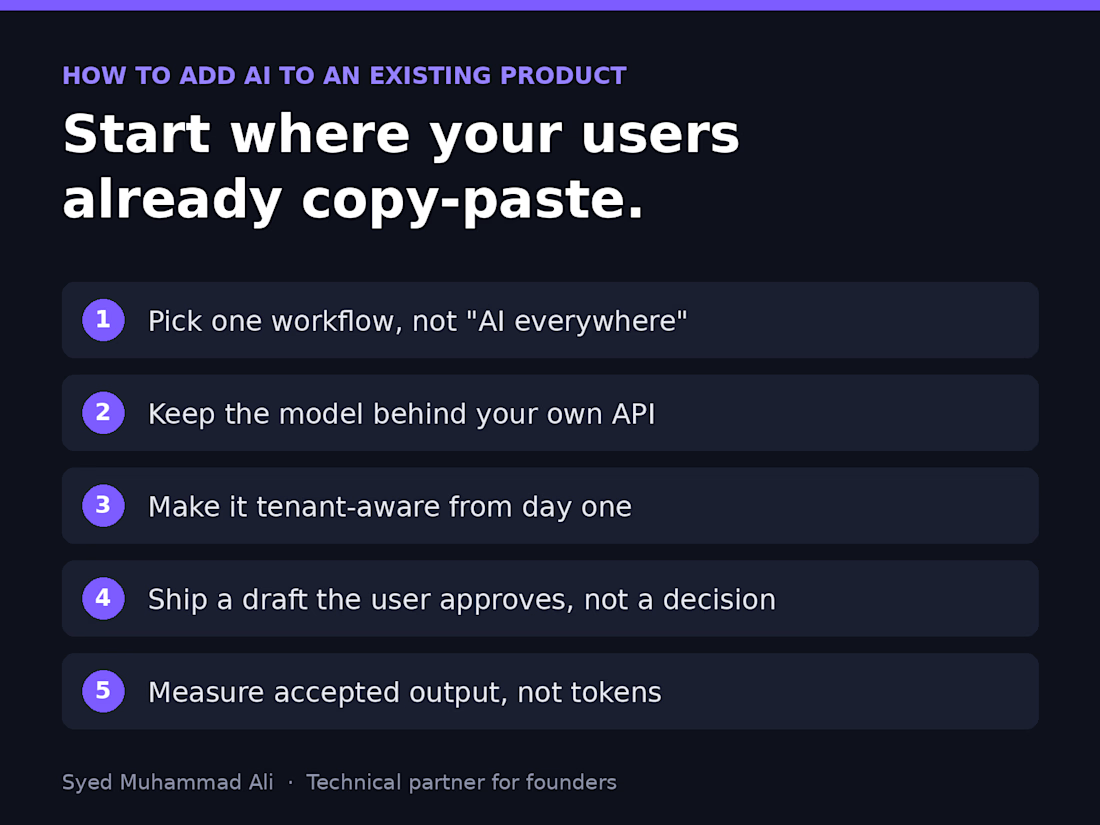
Before you add AI to your product, find the screen where your users already copy and paste.
That's usually where the real AI feature lives. Not a chatbot in the corner, but a step people already do by hand: summarising a ticket, drafting a reply, tagging an upload, pulling fields out of a PDF.
Here's the order I follow when a founder asks me to add AI to an existing SaaS:
1. Pick one workflow, not "AI everywhere." Watch where users leave your app to paste something into ChatGPT and come back. That round trip is your feature.
2. Keep the model behind your own API. One service owns prompts, retries, logging and cost limits, so you can switch providers without touching the frontend.
3. Make it tenant-aware from day one. Each customer's data, prompts and usage stay scoped to their account, or the first enterprise security review will stop you.
4. Ship a draft, not a decision. Let the AI suggest and the user approve. You earn trust and get real feedback before you automate anything.
5. Measure accepted output, not tokens. If users rewrite most of what it produces, the prompt or the context is wrong, and that's your real roadmap.
Most AI features that flop didn't fail because of the model. They were bolted onto the wrong step.
What's the one task your users still copy into ChatGPT?

Watching where users paste into ChatGPT and come back is such a practical way to find the real feature. Most teams start with the chatbot instead.

Everyone is shipping AI agents right now. Almost no one is testing them — and that is the whole problem.
A demo agent and a production agent are different animals. The demo works because you walked it down the happy path. Production breaks on the paths you never imagined.
A real example from my own work: a support assistant correctly handed a conversation to a human when someone wrote "I want to talk to a person" in Spanish — but not in English, because one phrase was missing from a rule. Every automated test passed. It only surfaced when I ran real conversations through it.
That is the gap the "agents will replace everything" wave keeps skipping. The hard part was never making an agent act. It is making it:
• say "I don't know" instead of guessing,
• hand control back to a human at the right moment,
• and prove, with tests, that it still behaves when the input gets strange.
Autonomy is cheap. Trustworthy autonomy is the real engineering.
Before you let an AI agent near real users or real data — what is the first thing you check?

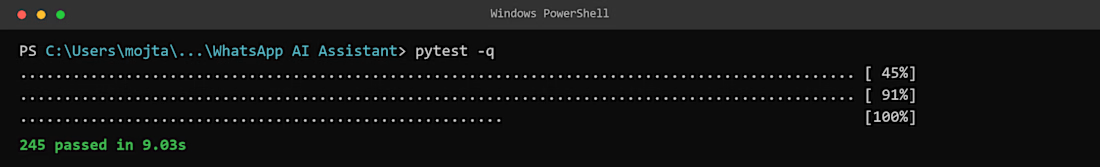

The Spanish vs English handoff bug is such a good example. Every test passes until a real user shows up.