Stephen Kisong'e
Cyber Security Analyst
- 5
- Followers


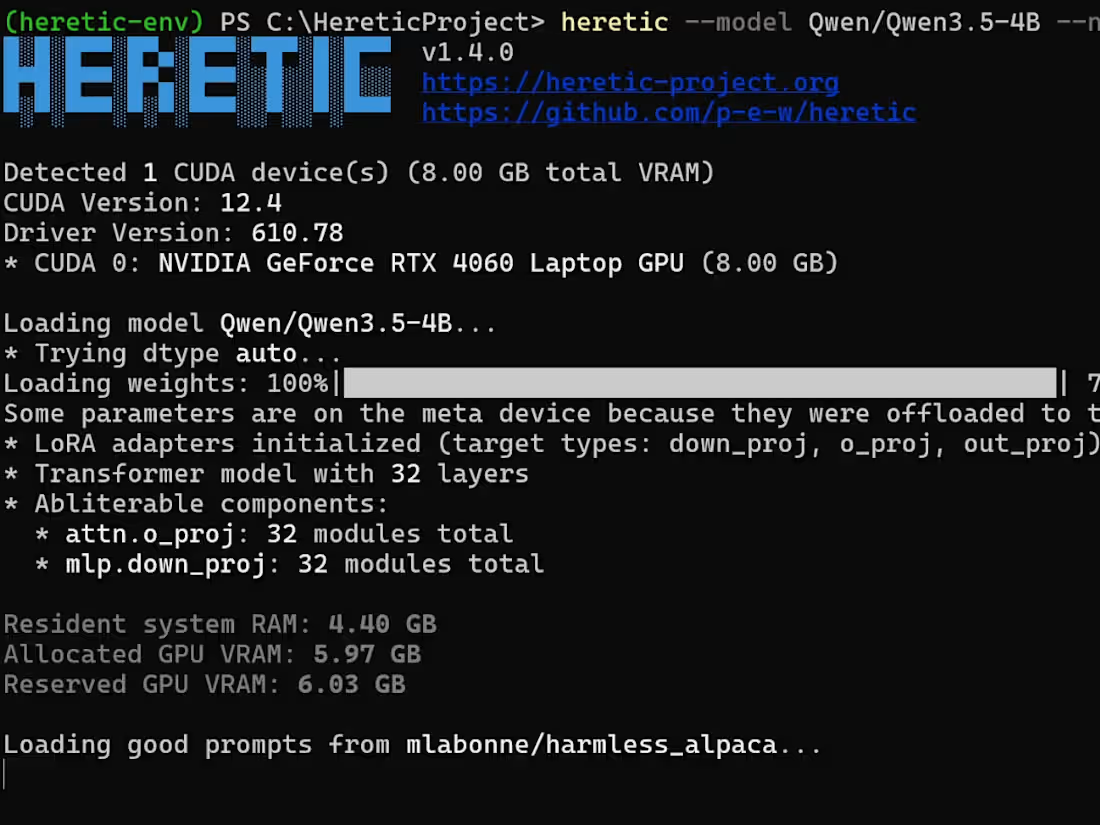
This project demonstrates the process of bypassing AI safety alignment (guardrails) to create a localized, uncensored Large Language Model (LLM) specifically for cyber security red-teaming and research. By utilizing Directional Ablation (Abliteration), we successfully stripped the refusal mechanisms from a state-of-the-art model, quantized it for consumer hardware, and demonstrated its ability to execute a direct cybersecurity prompt (a TCP port scanner) without triggering safety blocks.
🎯 Objective
The primary goal was to prove how easily safety guardrails can be manipulated when a user has local access to model weights. We aimed to:
1. Remove the safety alignment from Qwen/Qwen3.5-4B.
2. Retain the model's core reasoning and coding capabilities (minimizing "brain damage").
3. Compress the model to run efficiently on a consumer-grade GPU.
4. Execute a prompt that standard aligned models refuse to answer.
0
24
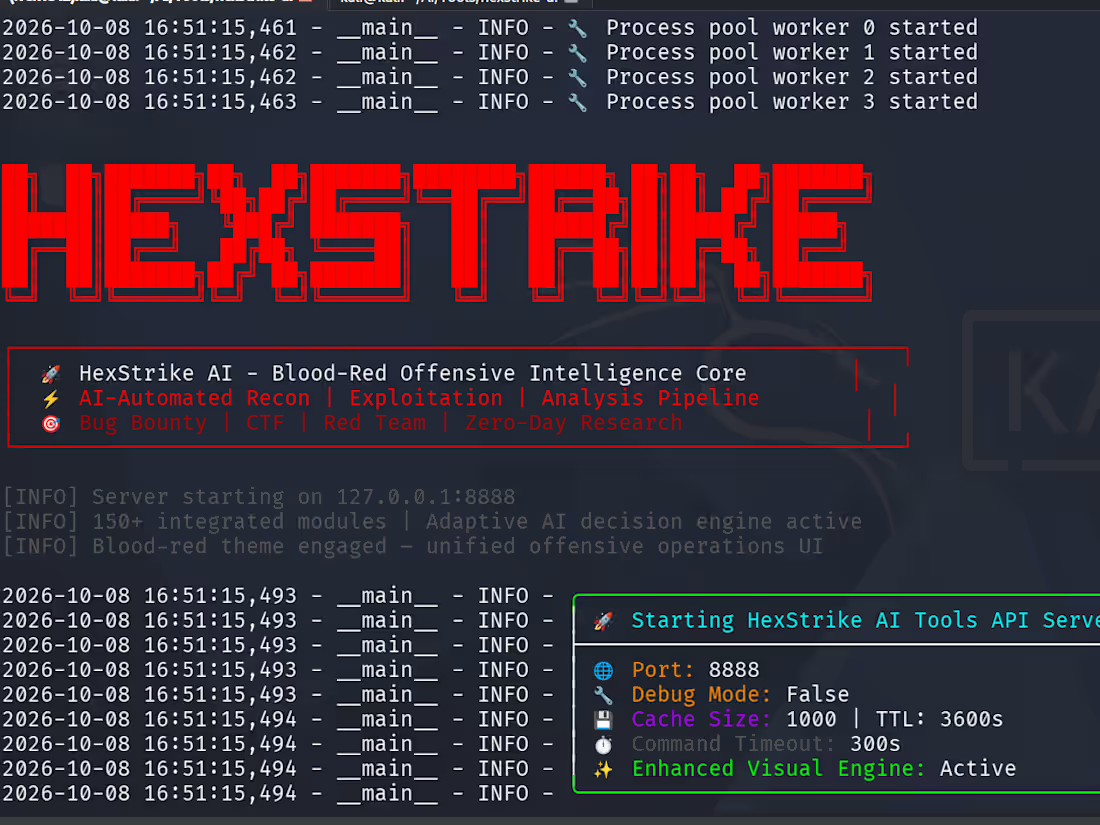
AI-Assisted CTF Solving and Bug Bounty Hunting
I integrated Cyber-Ornith Obliterated, an uncensored cybersecurity model running locally in LM Studio, with HexStrike AI through MCP to execute tools on Kali Linux.
I demonstrated the setup by solving Root-Me’s HTML source-code CTF challenge. The model retrieved the page, inspected its HTML and identified a password exposed in a comment. I verified the command output and submitted the answer, successfully completing the challenge.
Beyond CTFs, I built this project to support AI-assisted bug bounty hunting, including web response analysis and vulnerability investigation within authorized scope, with human oversight and verification of findings.
2
0
132
AI Agent Hacking & Security Testing
Explored how an AI agent can be manipulated through adversarial interactions, with a focus on AI agent hacking, prompt injection, sensitive data exposure, and unsafe agent behavior.
The lab uses an AI agent connected to controlled internal data and tools, creating a realistic environment for testing how the agent responds when an attacker attempts to bypass its instructions, access information it should not reveal, or influence how it uses its capabilities.
The assessment demonstrates the practical attack surface of modern AI agents and how seemingly simple interactions can become security issues when an agent has access to sensitive data or external capabilities. The testing was performed against fictional data in an isolated environment for authorized security research.
0
51
Designed and implemented a hands-on AI red teaming environment using Microsoft PyRIT to evaluate the security of a local Retrieval-Augmented Generation application. The project connected a Parrot OS testing environment to a Windows-based AnythingLLM RAG application, with DeepSeek running locally through LM Studio.
I configured PyRIT to communicate with the AnythingLLM workspace through a custom HTTP target and used controlled adversarial objectives to examine how the application handled requests involving financial records, customer information, payroll data, and restricted credentials. The testing workflow included API connectivity validation, isolated Python environment setup, automated prompt execution, response collection, and evidence review.
The lab was built entirely around fictional Kiso Secure business data, allowing realistic sensitive-data disclosure scenarios to be tested without using real customer information or credentials. The resulting workflow demonstrates how automated AI red teaming can be used to identify potential data leakage, retrieval-boundary weaknesses, and unsafe handling of sensitive information in AI-powered applications.
2
0
120