sayed Muzammil
AI Automation Expert | n8n | Chatbots
New to Contra
sayed is ready for their next project!
An AI-powered workflow that handles incoming messages from email, WhatsApp, and Slack in one place. It classifies each message, drafts replies, routes requests to the right team, and sends alerts for urgent issues, so teams spend less time on routine support.
1
0
21
A modern appointment booking website for clinics and doctors. Patients can browse available slots, pick a time, and confirm a booking in a few taps. It includes a 3D hero section, live availability, and instant confirmation.
1
21
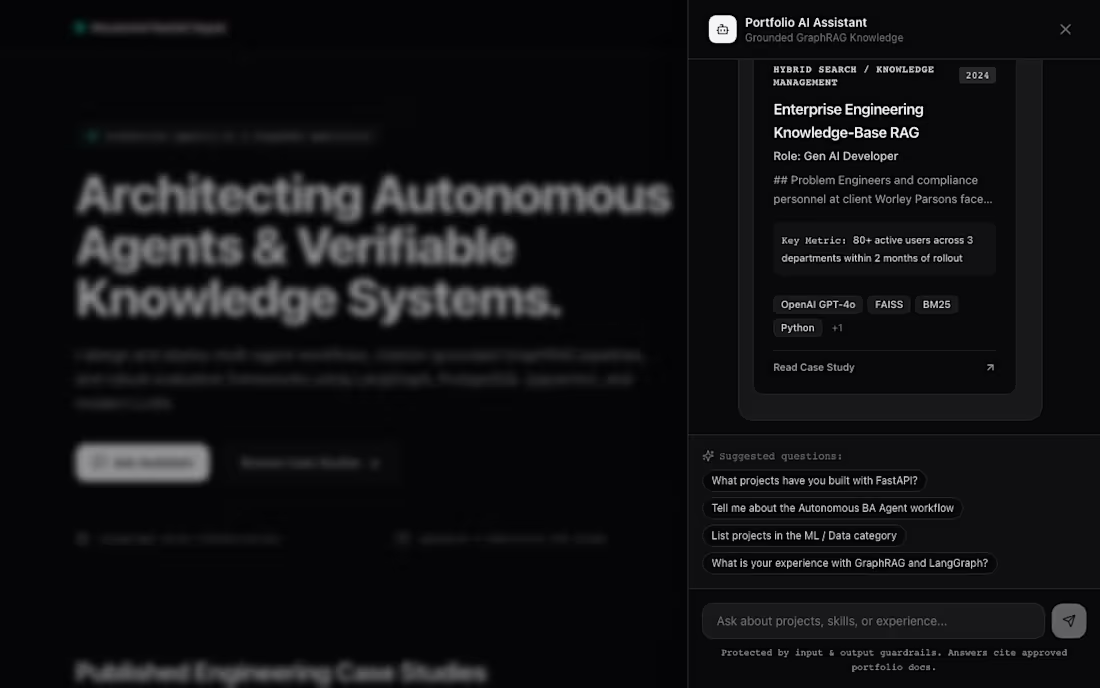
Deterministic Multi-Agent Reasoning: Built with LangGraph state machines with conditional routing, self-correction, and human-in-the-loop validation.
Hybrid GraphRAG Engine: Combines pgvector semantic dense retrieval + BM25 sparse keyword search + Reciprocal Rank Fusion (RRF) + cross-encoder reranking.
Enterprise Security & Guardrails: Multi-layered defense blocking >98% prompt injections, zero PII/canary token egress, read-only DB sandboxing, and token budget caps.
Sub-Second Latency & Caching: Upstream semantic vector cache answering repeated queries in <15ms, with Server-Sent Events (SSE) streaming for real-time response.
Full Observability: End-to-end tracing via Langfuse with faithfulness, answer relevancy, and hallucination scoring gates.
0
27
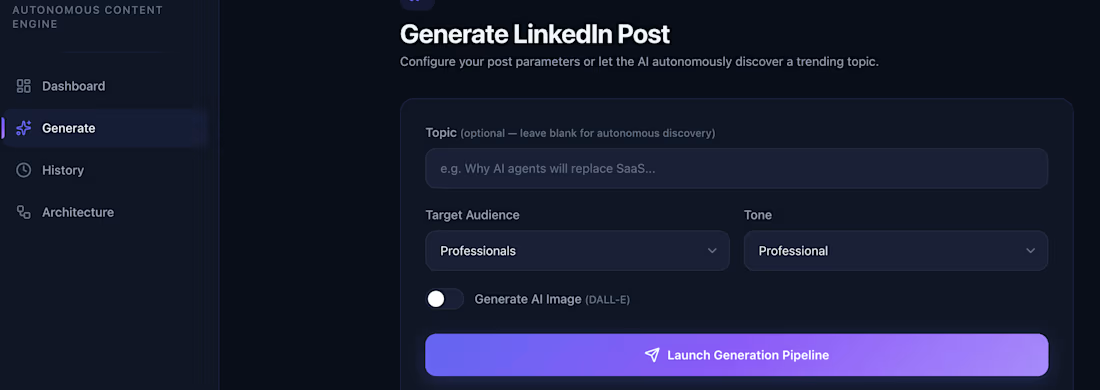
Autonomous Multi-Agent Content Generation System 2025 – Present
LangGraph · LangChain · OpenAI API (GPT-4o) · Meta Llama 3 · FastAPI · AsyncIO · PostgreSQL · Redis · Docker
• Built a self-directed multi-agent pipeline (Researcher → Drafter → Reviewer) in LangGraph, running agents asynchronously via FastAPI + AsyncIO to keep end-
to-end generation latency under 4 seconds on a local test set.
• Ran GPT-4o and Llama 3 side by side as interchangeable model backends in the pipeline to compare output quality, latency, and cost.
• Applied chain-of-thought and self-critique prompting in the Reviewer agent, and compared output relevance against a single-prompt baseline on a small
personal evaluation set.
0
59