Production Observability & SRE Telemetry PlatformRené Bon Ćirić
Escape extortionate SaaS observability bills ($5,000–$20,000+/month on Datadog or New Relic), eliminate metric noise and unhelpful alert spam, and gain crystal-clear visibility into production health.
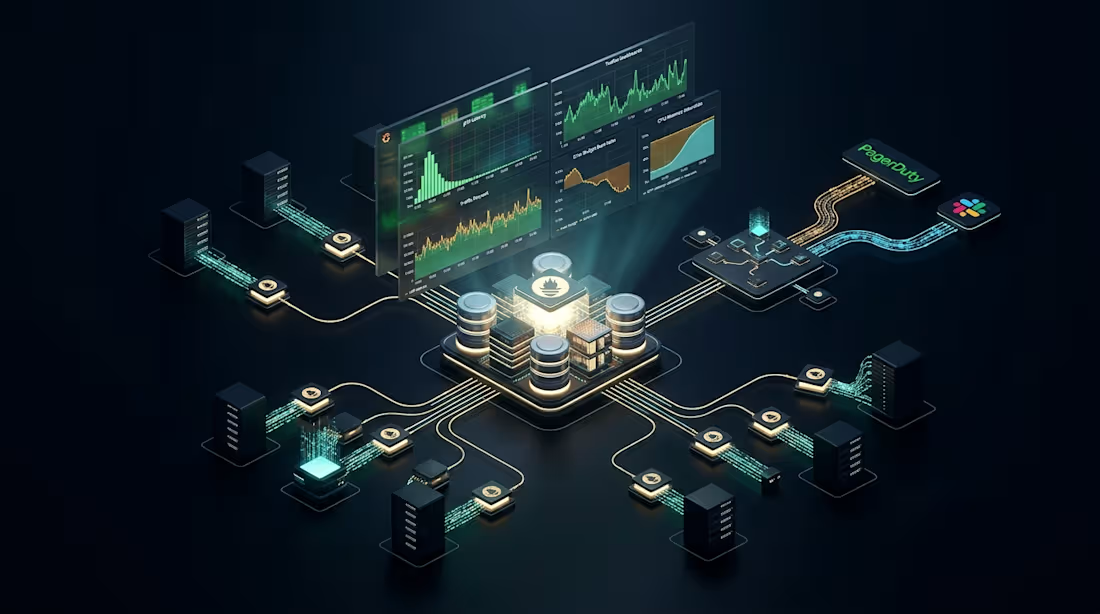
We architect and deploy a production-grade, sovereign telemetry stack powered by Prometheus, Grafana, and Alertmanager on CentOS Stream 10. We replace hundreds of noisy alerts with actionable Service Level Objectives (SLOs) focused on the Four Golden Signals (Latency, Traffic, Errors, and Saturation), with high-priority notifications routed directly to PagerDuty, Slack, or Telegram.
Architecture & Safety Invariants
Zero Per-Host SaaS Penalties: Ingest millions of metric samples per second on your own infrastructure without per-node or per-container licensing penalties.
Signal Over Noise: Mathematically grounded multi-window SLO burn-rate alerts that fire only when user experience is genuinely compromised.
High-Performance Long-Term Storage: TSDB chunk compression, retention tuning, and downsampling keeping historical telemetry accessible in milliseconds.
Unified Fleet Telemetry: Complete visibility across physical bare-metal nodes, virtual hypervisors, container workloads, and network interfaces.
Tangible Engineering Deliverables
Production Prometheus & Alertmanager Cluster: Tuned Prometheus server on CentOS Stream 10 with Node Exporter, Process Exporter, and Blackbox synthetic probes.
Executive & Engineering Grafana Dashboards: 3-tier dashboard suite (Executive Overview, Golden Signal SLOs, and Deep Debugging) visualizing p50/p95/p99 latency, throughput, and saturation.
Structured Journald Logging Architecture: Hardened systemd-journald configuration with JSON structured logging, rate limiting, and centralized log forwarding.
Multi-Window SLO Burn Rate Alert Routing: PagerDuty, Slack, or Telegram notification rules with alert deduplication, grouping, and noise suppression.
SRE Telemetry Runbook & On-Call Playbook: Documentation detailing dashboard metrics, query templates, alert escalation policies, and threshold adjustments.
Starting at$3,500
Duration2 weeks
Tags
CentOS
Grafana
Linux
Prometheus
DevOps Engineer
Observability
Site Reliability Engineering
Service provided by
René Bon Ćirić Ixtlahuacán de los Membrillos, Mexico
- 2
- Followers
Production Observability & SRE Telemetry PlatformRené Bon Ćirić
Starting at$3,500
Duration2 weeks
Tags
CentOS
Grafana
Linux
Prometheus
DevOps Engineer
Observability
Site Reliability Engineering
Escape extortionate SaaS observability bills ($5,000–$20,000+/month on Datadog or New Relic), eliminate metric noise and unhelpful alert spam, and gain crystal-clear visibility into production health.
We architect and deploy a production-grade, sovereign telemetry stack powered by Prometheus, Grafana, and Alertmanager on CentOS Stream 10. We replace hundreds of noisy alerts with actionable Service Level Objectives (SLOs) focused on the Four Golden Signals (Latency, Traffic, Errors, and Saturation), with high-priority notifications routed directly to PagerDuty, Slack, or Telegram.
Architecture & Safety Invariants
Zero Per-Host SaaS Penalties: Ingest millions of metric samples per second on your own infrastructure without per-node or per-container licensing penalties.
Signal Over Noise: Mathematically grounded multi-window SLO burn-rate alerts that fire only when user experience is genuinely compromised.
High-Performance Long-Term Storage: TSDB chunk compression, retention tuning, and downsampling keeping historical telemetry accessible in milliseconds.
Unified Fleet Telemetry: Complete visibility across physical bare-metal nodes, virtual hypervisors, container workloads, and network interfaces.
Tangible Engineering Deliverables
Production Prometheus & Alertmanager Cluster: Tuned Prometheus server on CentOS Stream 10 with Node Exporter, Process Exporter, and Blackbox synthetic probes.
Executive & Engineering Grafana Dashboards: 3-tier dashboard suite (Executive Overview, Golden Signal SLOs, and Deep Debugging) visualizing p50/p95/p99 latency, throughput, and saturation.
Structured Journald Logging Architecture: Hardened systemd-journald configuration with JSON structured logging, rate limiting, and centralized log forwarding.
Multi-Window SLO Burn Rate Alert Routing: PagerDuty, Slack, or Telegram notification rules with alert deduplication, grouping, and noise suppression.
SRE Telemetry Runbook & On-Call Playbook: Documentation detailing dashboard metrics, query templates, alert escalation policies, and threshold adjustments.
$3,500