Python ETL Pipeline & Data CleaningMojtaba Karimiabdar
Your data is spread across spreadsheets, exports, an old database and a few APIs, and every report starts with copy-paste and clean-up?
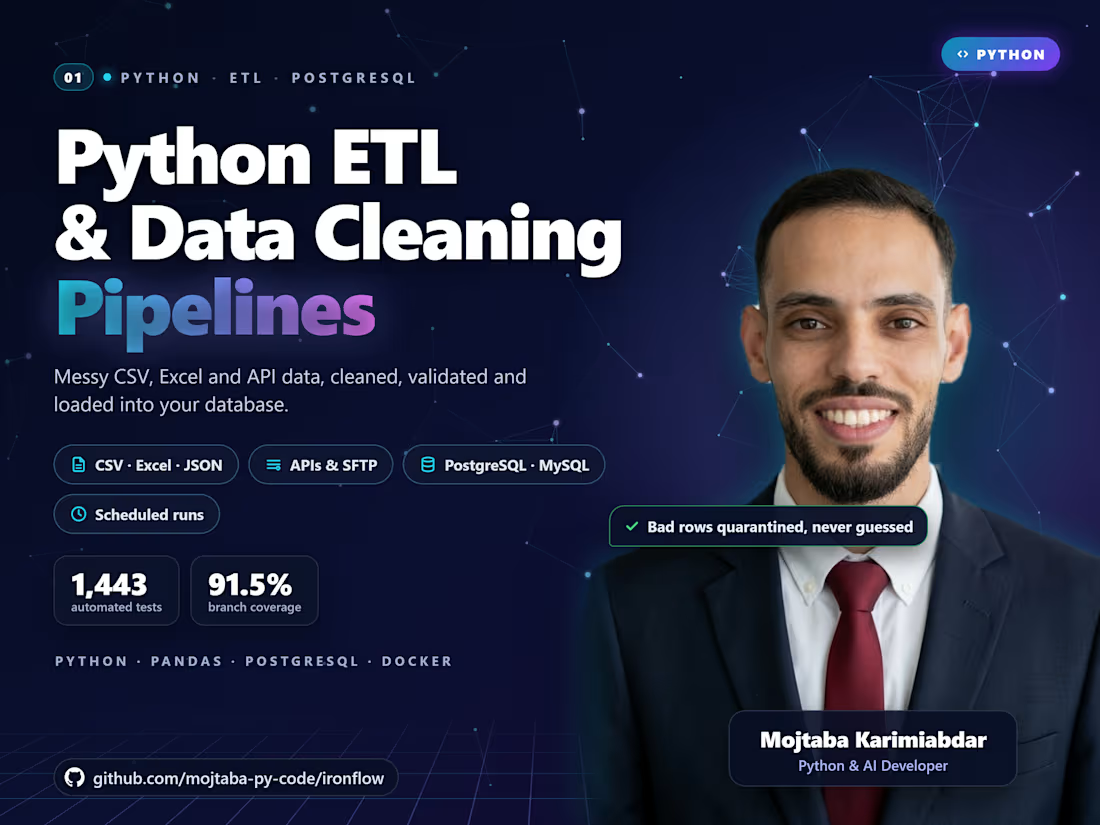
I build a Python ETL pipeline that collects it, cleans it, checks every row and loads it into your database. You can run it again anytime, with one command or on a schedule.
This is for you if
• You re-clean the same exports again and again
• Your data lives in several places and never quite matches
• You're moving to a new database and can't afford a messy migration
• You need clean, trusted tables before building reports or dashboards
What you receive
• A working pipeline, tested on your real sample data
• Clean tables: fixed dates and text, no duplicates, every row validated
• A reject report: rows that break a rule are set aside with the exact reason, never guessed
• Safe loading: a failed run rolls back, so your tables are never half-loaded
• Full source code and configuration, Docker included, yours to keep
• A short guide: how to run it, schedule it and change it
Options you can add
• Sources: CSV, Excel, JSON, XML, Parquet, PostgreSQL, MySQL, SQLite, REST and GraphQL APIs, SFTP / FTP
• Destinations: PostgreSQL, MySQL or SQLite, or clean CSV, Excel, JSON or Parquet files, an SFTP folder or your own API
• Loading: full refresh, append, upsert (insert new and update changed rows) or incremental (only what changed)
• Privacy: mask, hash or encrypt personal data before it is stored
• Automation: scheduled runs, resume after a failure, alerts by e-mail, Slack or webhook, and a small dashboard with run history
• One-time jobs: a database migration (for example MySQL to PostgreSQL) or merging years of spreadsheets into one table
How we work
You share a small sample of each source and where the data should go.
I send a written plan: tables, cleaning rules, and what's in and out. Nothing starts until you approve it.
I build and test the pipeline on your sample, with regular progress updates.
You receive the code, the guide and a first run report.
We review it together and I make your changes.
Proof you can check
Built on the same rules as my open-source ETL engine, IronFlow: 1,443 automated tests, 91.5% branch coverage, transactional loads, and a reject file for every bad row.
https://github.com/mojtaba-py-code/ironflow
Not included
Hosting, database or paid third-party API fees (billed to you directly by those providers), and websites that need a login or block automated access.
Ready to start? Send me a message with a short description of your data, and I'll reply with a plan before you order.
FAQs
Example work

Mojtaba's other services
Starting at$110
Duration4 days
Tags
Docker
Microsoft Excel
MySQL
pandas
PostgreSQL
Python
Automation Engineer
Backend Engineer
Data Engineer
Service provided by
Mojtaba Karimiabdar Ankara, Turkey
- 5.00
- Rating
- 12
- Followers
Python ETL Pipeline & Data CleaningMojtaba Karimiabdar
Starting at$110
Duration4 days
Tags
Docker
Microsoft Excel
MySQL
pandas
PostgreSQL
Python
Automation Engineer
Backend Engineer
Data Engineer
Your data is spread across spreadsheets, exports, an old database and a few APIs, and every report starts with copy-paste and clean-up?
I build a Python ETL pipeline that collects it, cleans it, checks every row and loads it into your database. You can run it again anytime, with one command or on a schedule.
This is for you if
• You re-clean the same exports again and again
• Your data lives in several places and never quite matches
• You're moving to a new database and can't afford a messy migration
• You need clean, trusted tables before building reports or dashboards
What you receive
• A working pipeline, tested on your real sample data
• Clean tables: fixed dates and text, no duplicates, every row validated
• A reject report: rows that break a rule are set aside with the exact reason, never guessed
• Safe loading: a failed run rolls back, so your tables are never half-loaded
• Full source code and configuration, Docker included, yours to keep
• A short guide: how to run it, schedule it and change it
Options you can add
• Sources: CSV, Excel, JSON, XML, Parquet, PostgreSQL, MySQL, SQLite, REST and GraphQL APIs, SFTP / FTP
• Destinations: PostgreSQL, MySQL or SQLite, or clean CSV, Excel, JSON or Parquet files, an SFTP folder or your own API
• Loading: full refresh, append, upsert (insert new and update changed rows) or incremental (only what changed)
• Privacy: mask, hash or encrypt personal data before it is stored
• Automation: scheduled runs, resume after a failure, alerts by e-mail, Slack or webhook, and a small dashboard with run history
• One-time jobs: a database migration (for example MySQL to PostgreSQL) or merging years of spreadsheets into one table
How we work
You share a small sample of each source and where the data should go.
I send a written plan: tables, cleaning rules, and what's in and out. Nothing starts until you approve it.
I build and test the pipeline on your sample, with regular progress updates.
You receive the code, the guide and a first run report.
We review it together and I make your changes.
Proof you can check
Built on the same rules as my open-source ETL engine, IronFlow: 1,443 automated tests, 91.5% branch coverage, transactional loads, and a reject file for every bad row.
https://github.com/mojtaba-py-code/ironflow
Not included
Hosting, database or paid third-party API fees (billed to you directly by those providers), and websites that need a login or block automated access.
Ready to start? Send me a message with a short description of your data, and I'll reply with a plan before you order.
FAQs
Example work
Mojtaba's other services
$110