AI incident triage agent for a SaaS platform team (n8n + OpenAI)

Ali Sabir


Problem
A B2B SaaS platform team on Kubernetes was drowning in alerts. Every page needed an engineer to open Grafana, pull logs, check recent deploys and decide whether it was real. Night pages took 20 to 40 minutes just to triage, and the same five failure modes kept coming back.
What I built
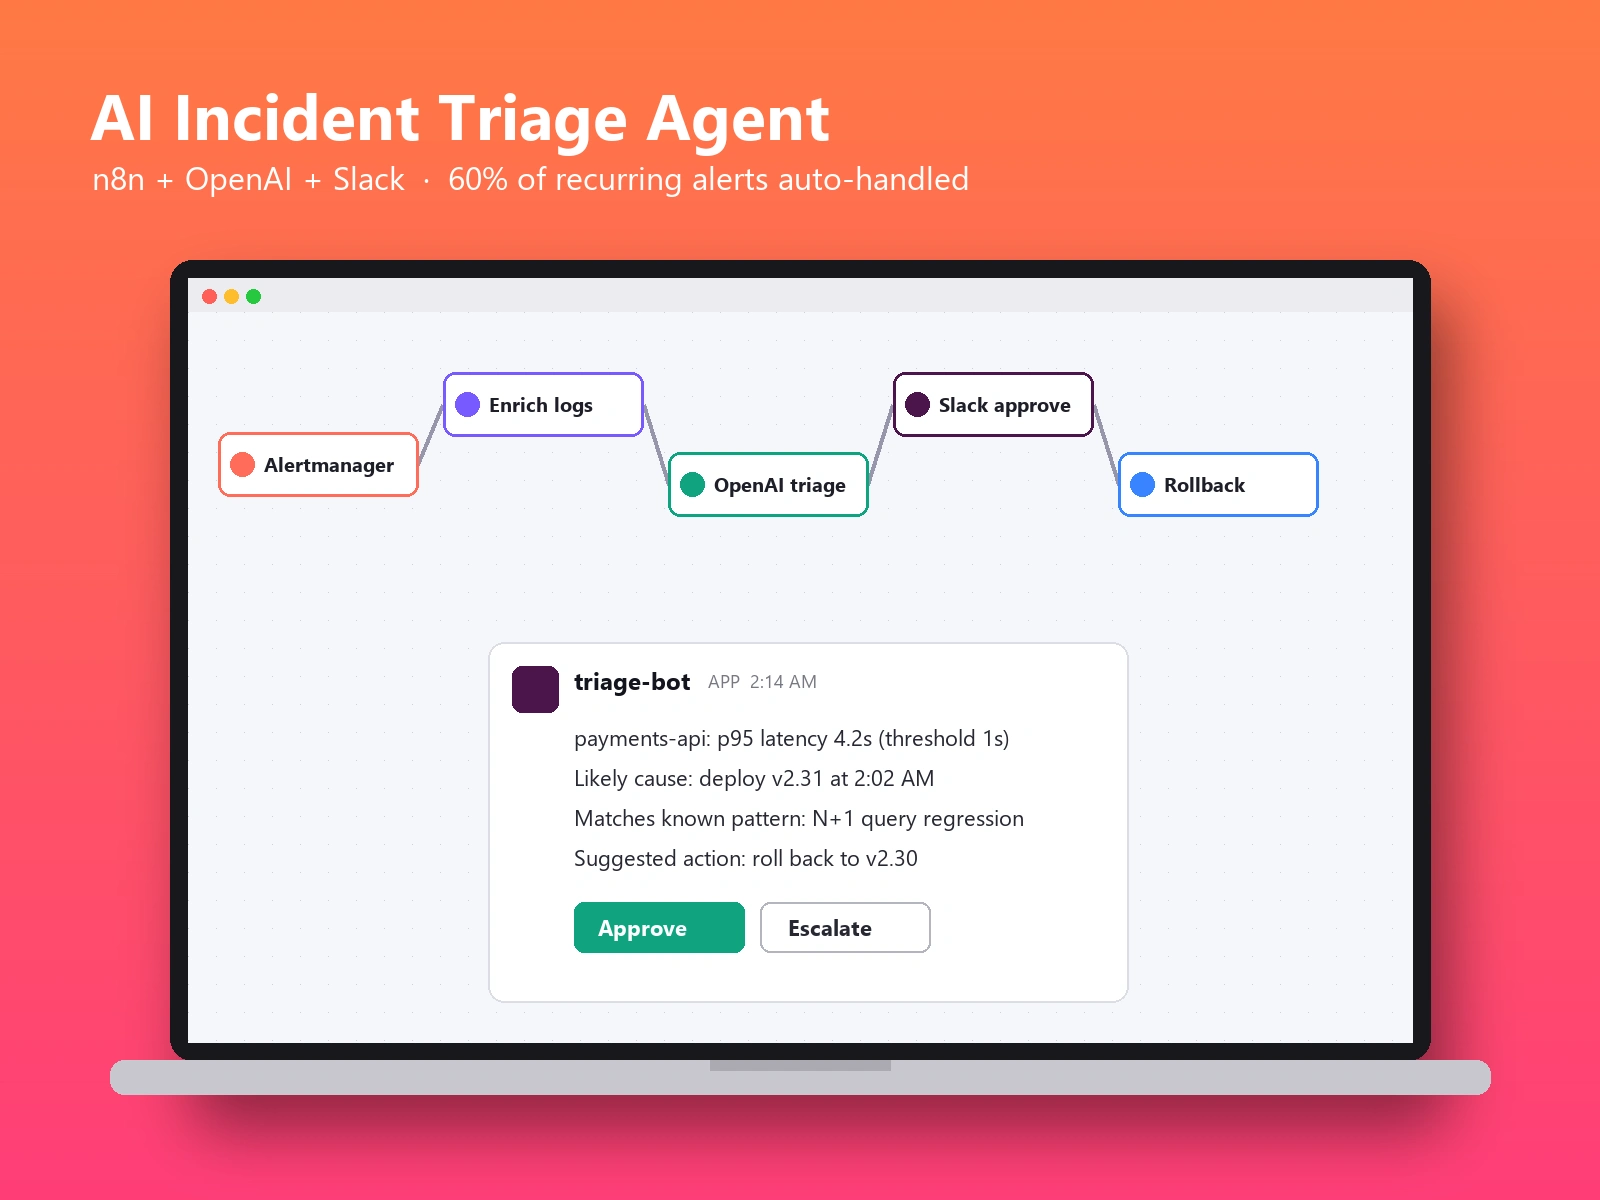
An n8n workflow that receives every Alertmanager alert, enriches it with Prometheus metrics, recent pod logs and the last Argo CD deploys for the affected service
An OpenAI-powered triage agent that classifies the alert (known pattern, deploy regression, capacity, or unknown), explains the likely cause in plain English and proposes the matching runbook step
Slack integration that posts a one-screen incident summary with buttons to approve a safe automated action, such as rollback, restart or scale-up, or to escalate to a human
Guardrails: every automated action is allow-listed, dry-run first, logged, and reversible, with a human approval for anything touching production data
A weekly digest that groups incidents by root cause so the team can fix the underlying issue instead of re-triaging it
Outcome
Median time from page to a confident diagnosis dropped from about 30 minutes to under 5
Roughly 60% of recurring alerts are now handled end to end without waking anyone
Fewer, higher-quality pages, and the digest drove four permanent fixes in the first month
Delivered in three weeks, with documentation and a handover session so the team owns the workflows
Stack
n8n, OpenAI API, Slack API, Prometheus, Alertmanager, Grafana, Argo CD, Kubernetes, Python, Postgres
Like this project
Posted Oct 9, 2026
n8n + OpenAI agent that triages Kubernetes alerts, proposes runbook actions in Slack and auto-resolves ~60% of recurring pages. Diagnosis: 30 min to under 5.
Likes
0
Views
1