
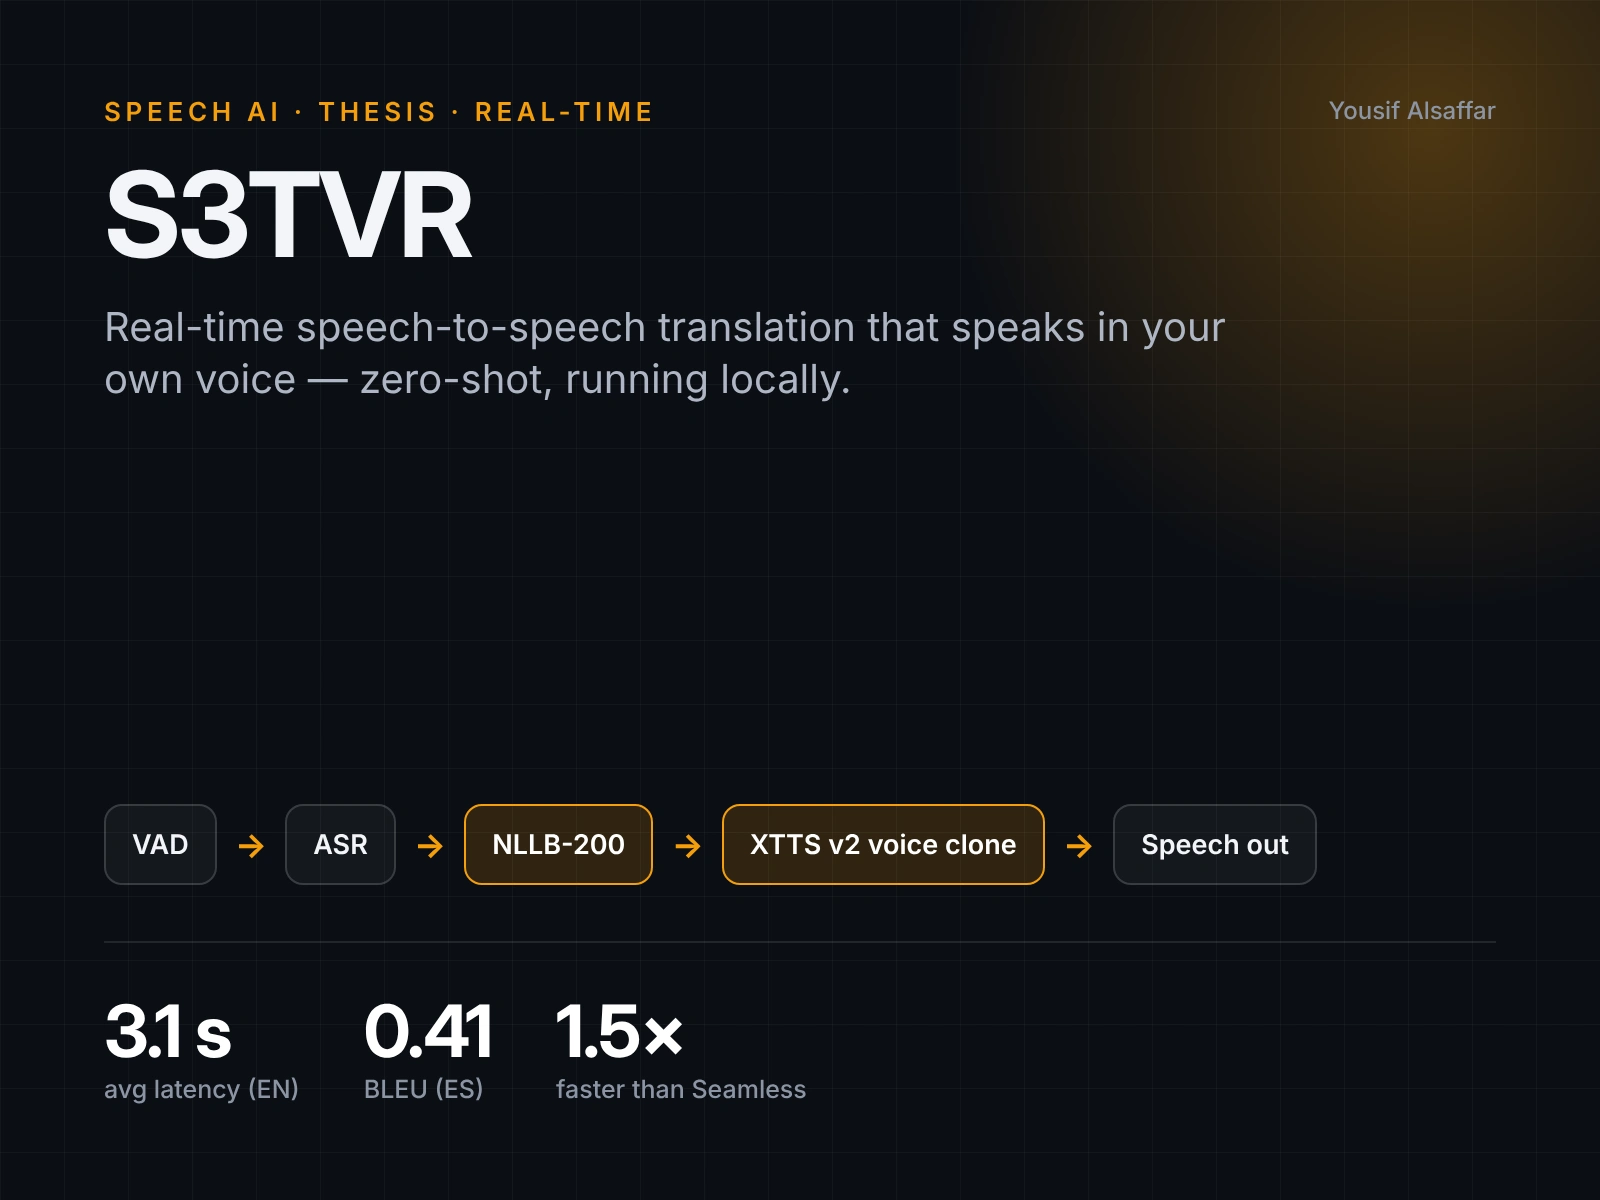
S3TVR (Seamless Speech-to-Speech Translation with Voice Replication) was my bachelor's thesis at IE University. It translates live speech between English and Spanish and speaks the translation in the speaker's own voice, cloned zero-shot, running locally.
How it works: a cascaded real-time pipeline of voice activity detection, noise reduction, speech recognition (NVIDIA Parakeet / FastConformer via NeMo), translation (Meta NLLB-200) and voice-cloning text-to-speech (Coqui XTTS v2), optimised with CUDA and DeepSpeed. Every stage is modular, so models can be swapped as better ones appear.
Results against Meta's Seamless Streaming model: about 3.1 s average latency per sentence versus 4.6-4.7 s, and BLEU of 0.36 (English) and 0.41 (Spanish) versus about 0.20.
0 likes · 0 views · Oct 31, 2026
S3TVR (Seamless Speech-to-Speech Translation with Voice Replication) was my bachelor's thesis at IE University. It translates live speech between English and...


