RAG PDF Chat — Ask Questions About Any Document

Sujay Singh


Overview
A document question-answering app: upload a PDF, ask questions in plain language, and get answers grounded in the document's actual content instead of the model's guesses.
The challenge
Large language models don't know what's inside your private documents, and they can make things up. The goal was to give the model the right parts of the document at question time, so its answers stay accurate and relevant.
How it works
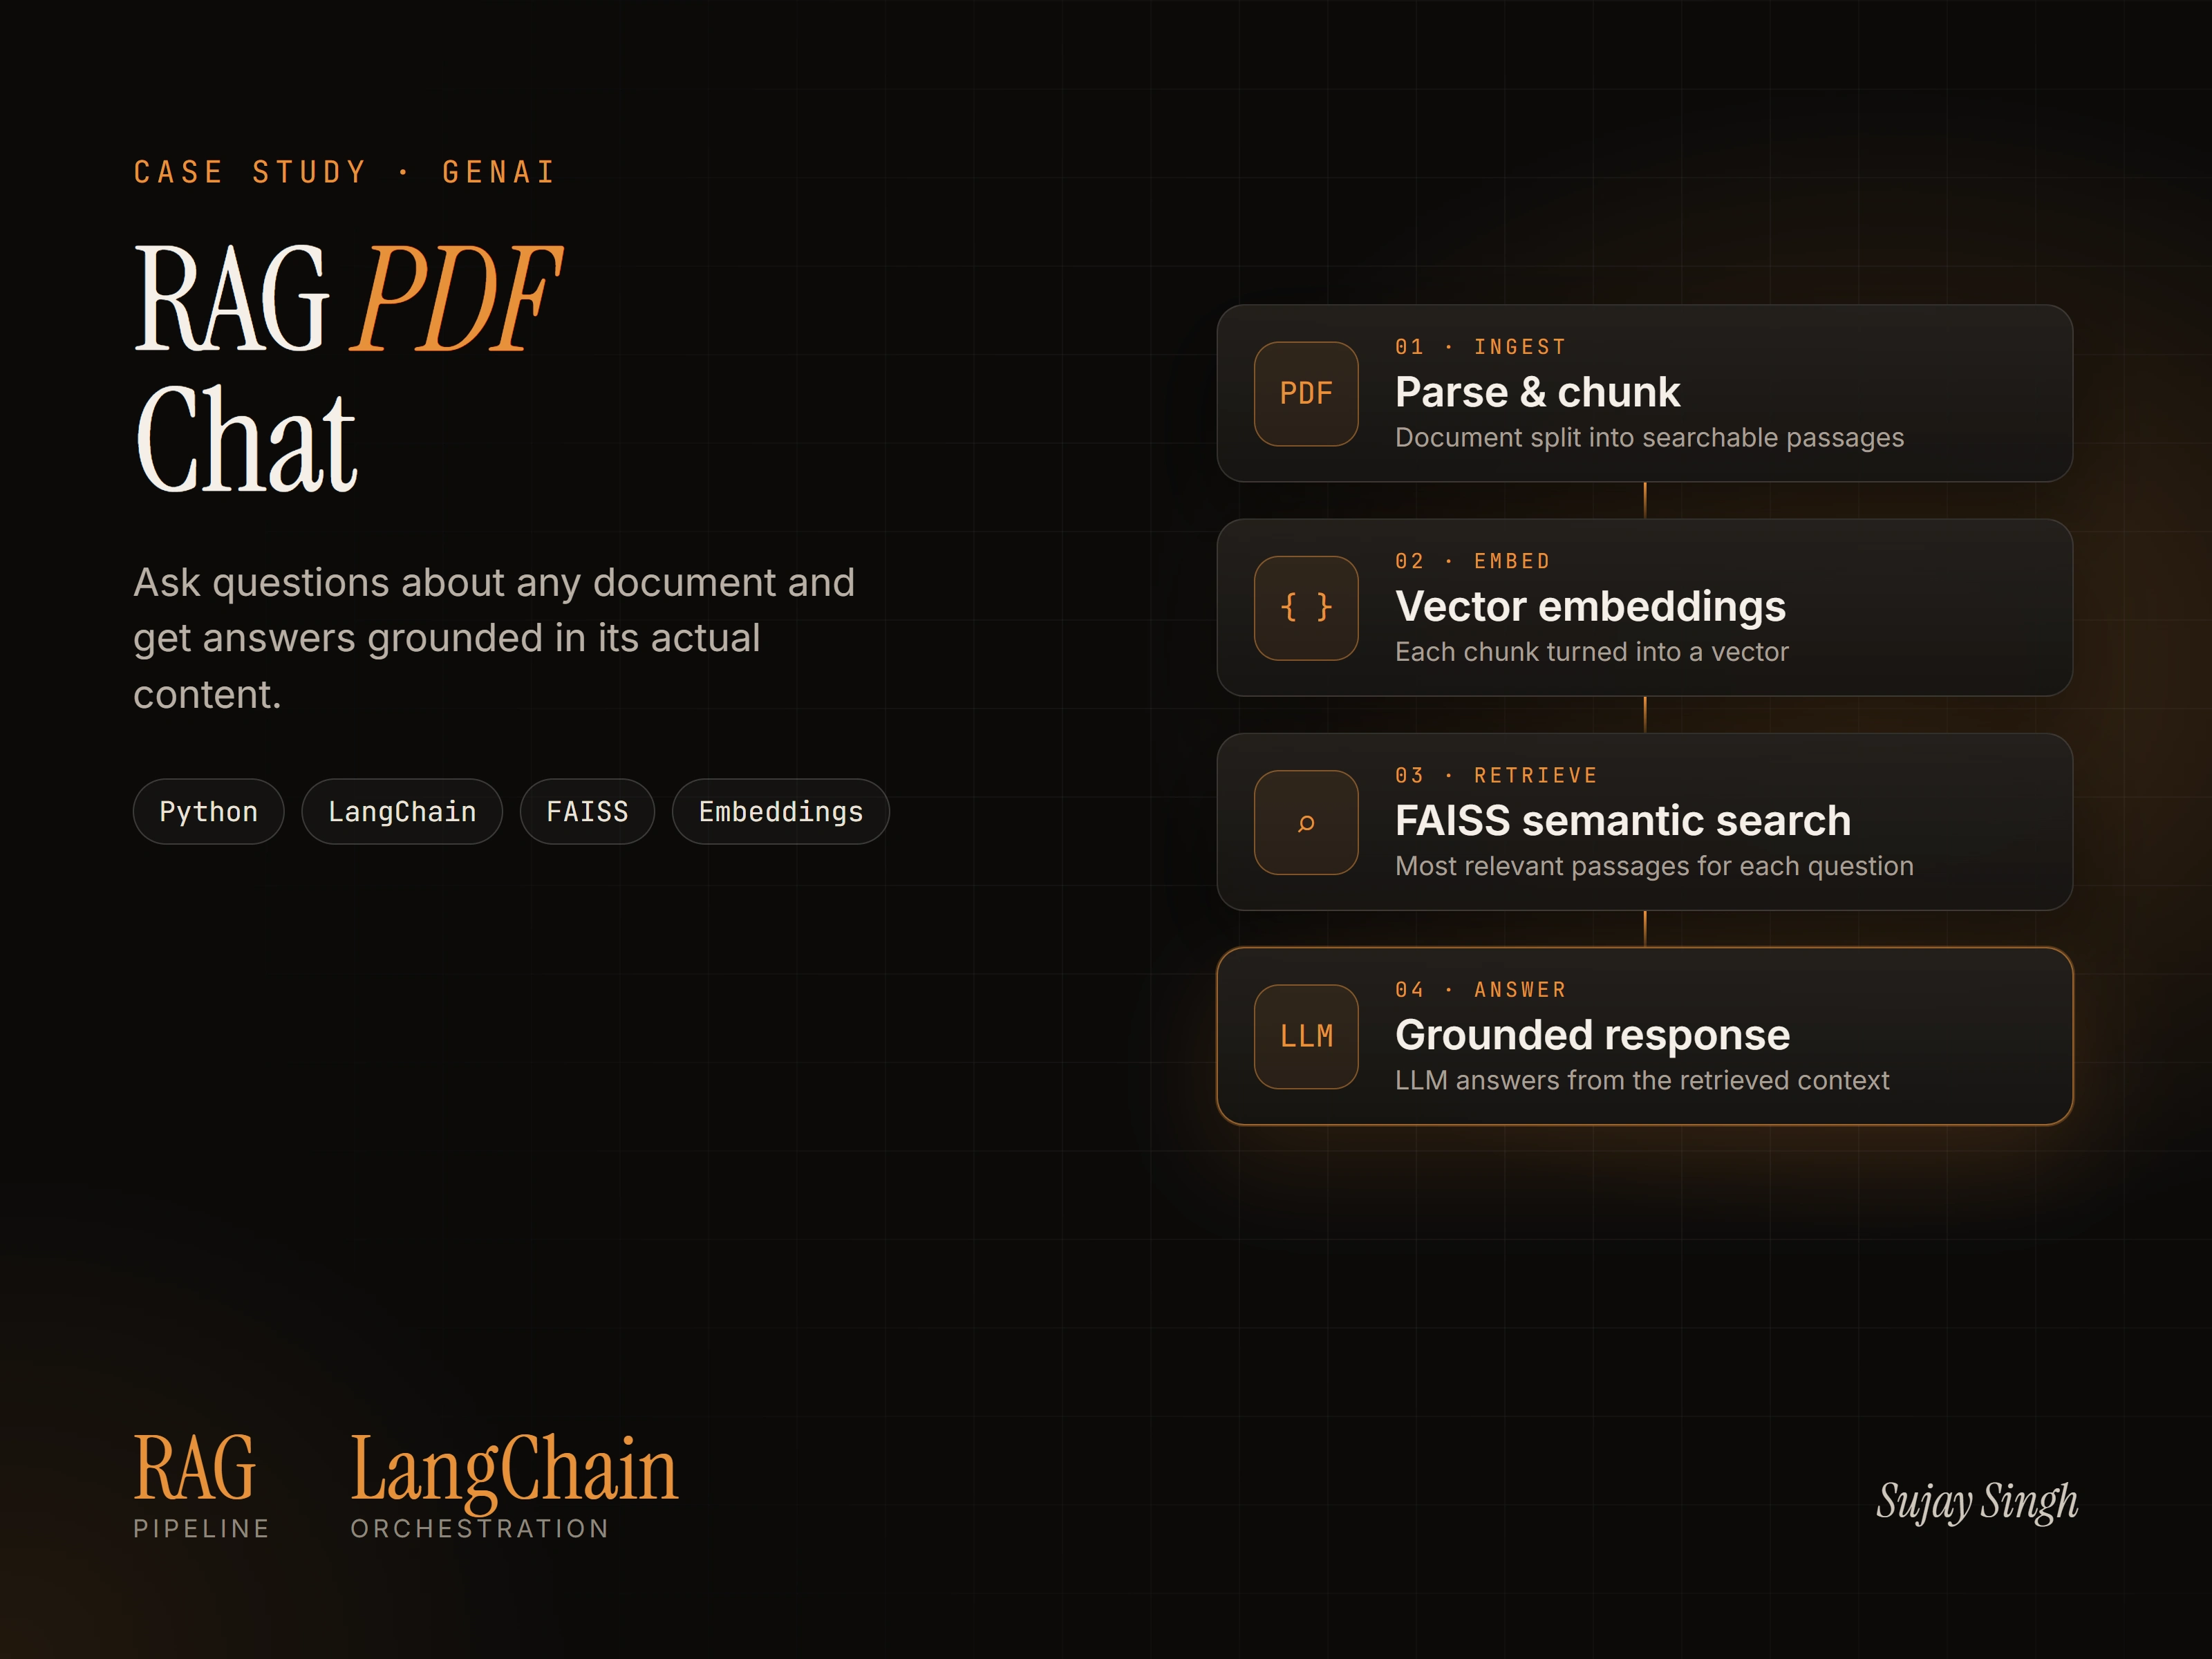
Ingestion — the PDF is parsed and split into chunks
Embeddings — each chunk is converted into a vector embedding
Vector store — embeddings are indexed in FAISS for fast similarity search
Retrieval — each question is embedded and matched against the most relevant chunks (semantic search)
Generation — the retrieved context is passed to the LLM, which answers based on the document
What I built
The complete RAG pipeline with LangChain
Document chunking and embedding generation
FAISS vector store and semantic search
Question-answering flow connecting retrieval to the LLM
Tech stack
Python · LangChain · FAISS · Embeddings · LLM APIs
Where this applies
The same architecture powers customer-support bots over help docs, internal knowledge-base assistants, and contract or policy Q&A — the kind of AI feature I build for clients.
Like this project
Posted Oct 7, 2026
A retrieval-augmented generation (RAG) app that answers questions about uploaded PDFs, built with Python, LangChain, embeddings and FAISS vector search.
Likes
0
Views
1