Private AI Processing, From Request to Delivery

Christopher Gamache

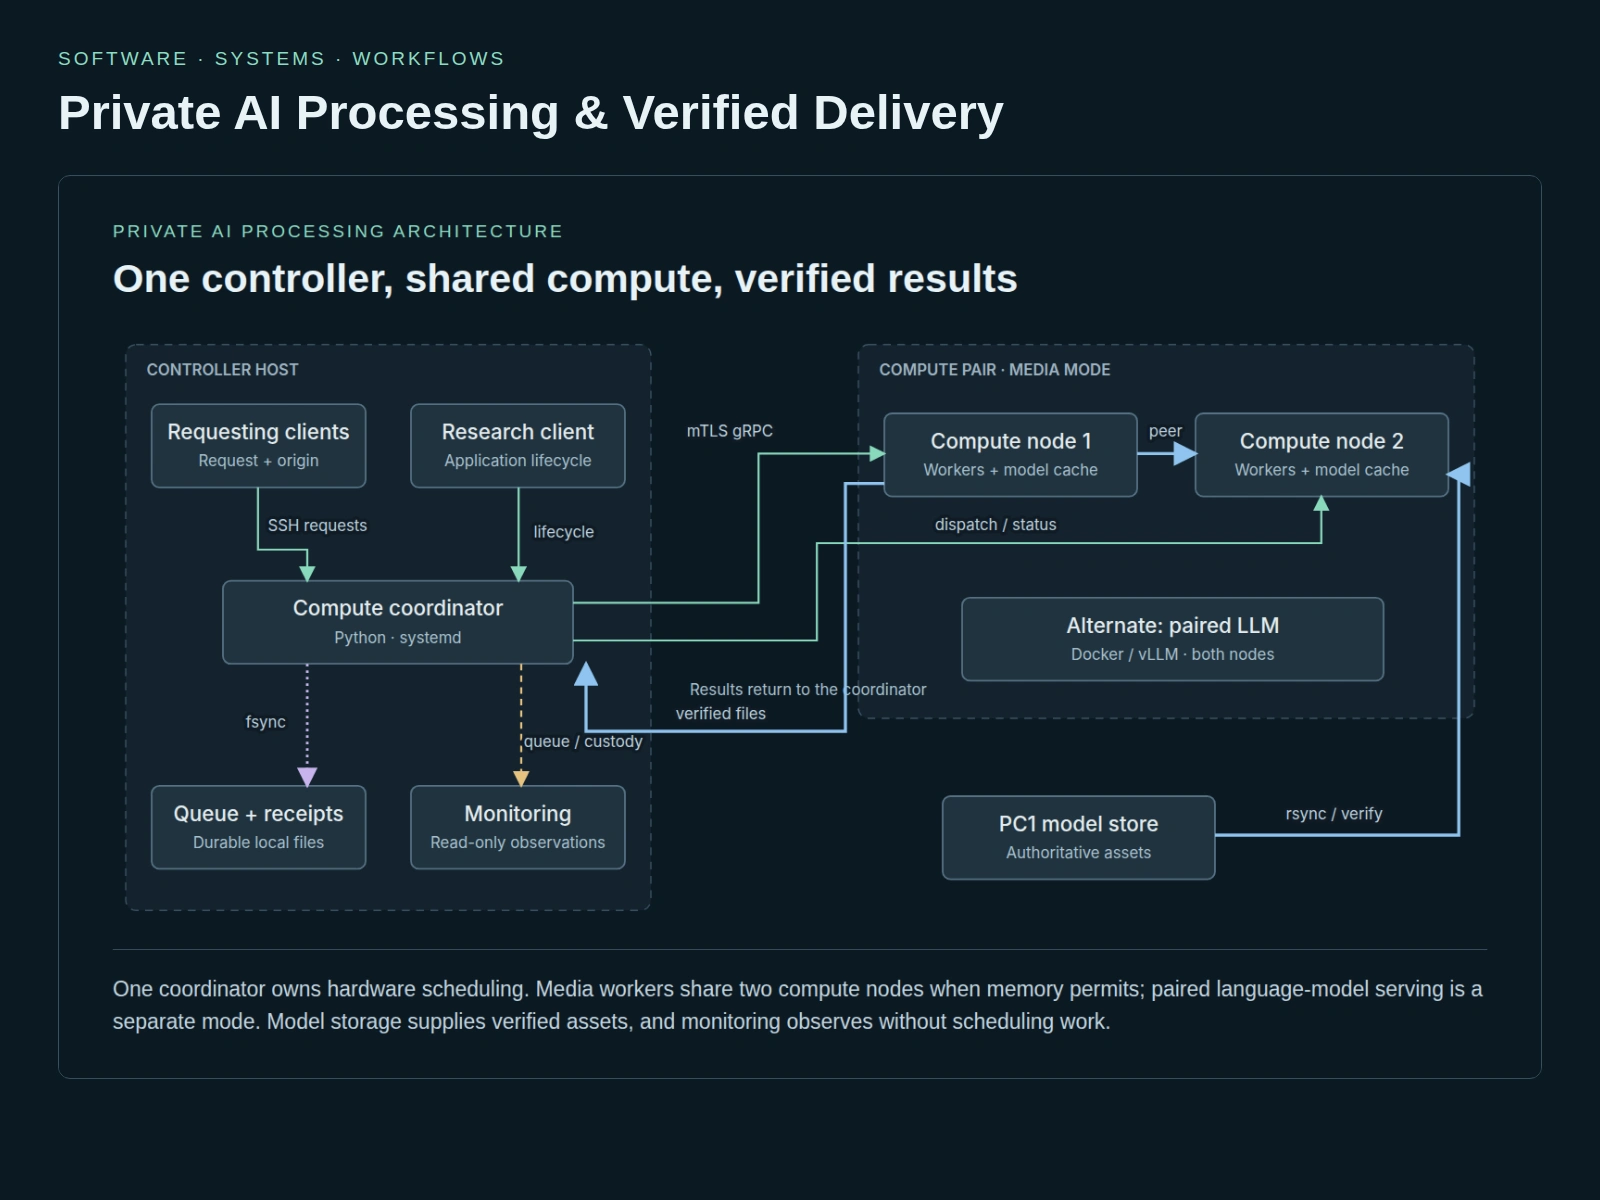
Putting AI to work takes more than selecting a model. Wild Pines built a shared processing system that connects incoming requests to available compute, the models required and the checks needed before delivery.
Requests enter a shared queue, execution is coordinated around the required models and available compute, and checked outputs return to the calling application. Recovery and delivery are part of that path. Developed around the needs of several applications, Engine gives new AI features a common processing foundation instead of requiring each application to build its own.
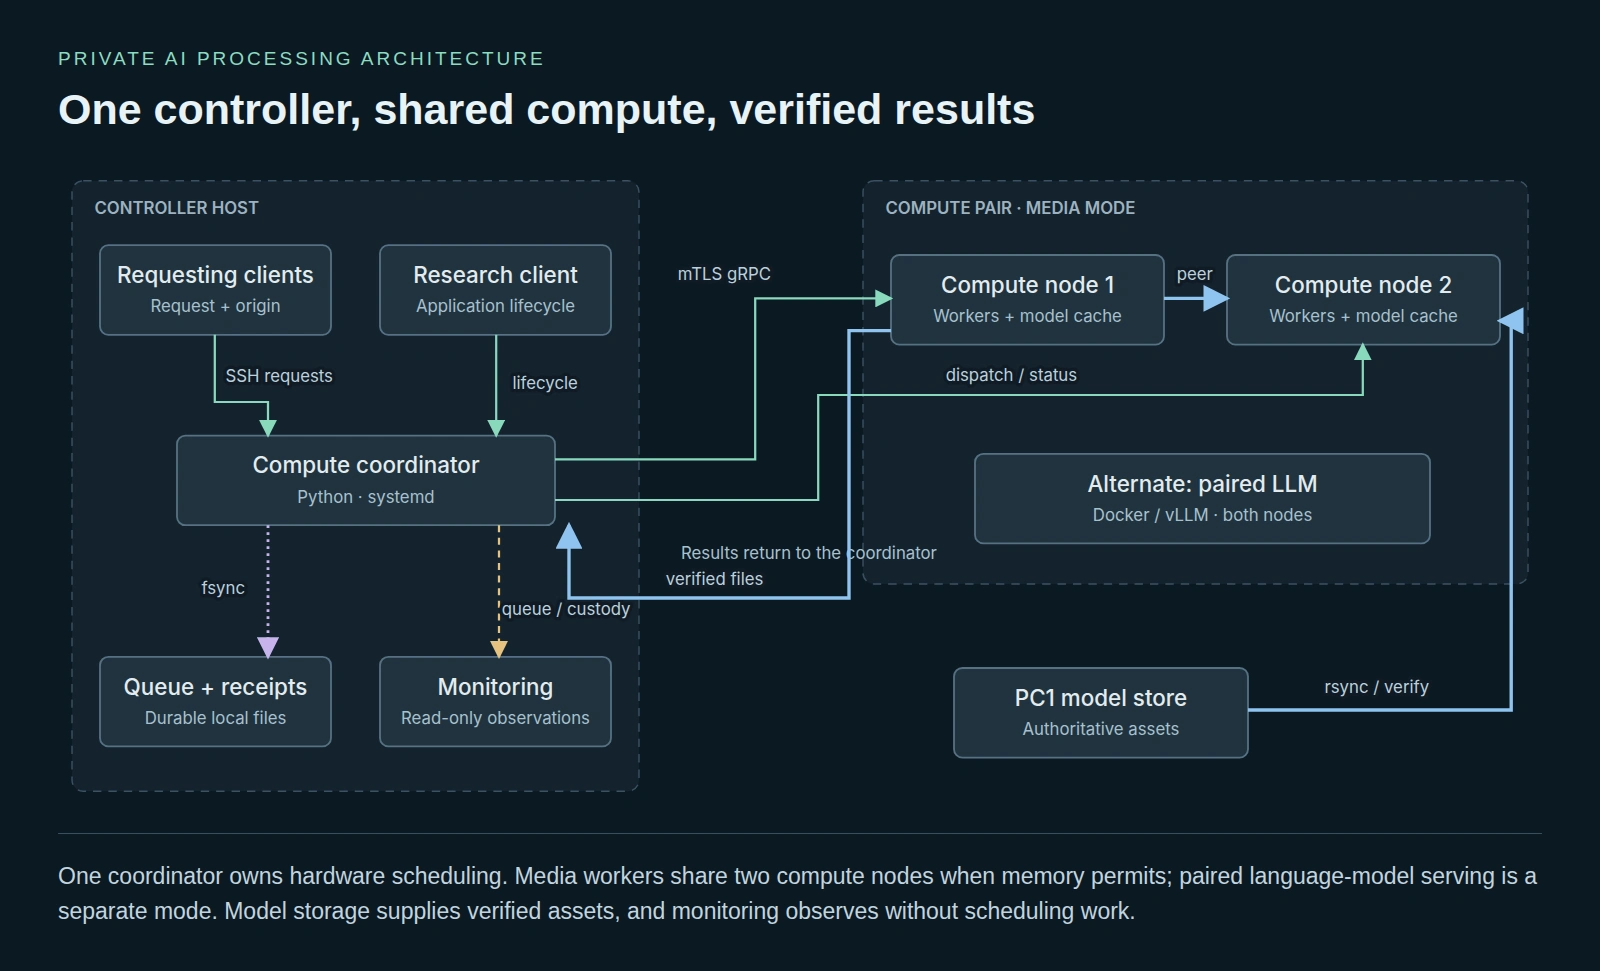
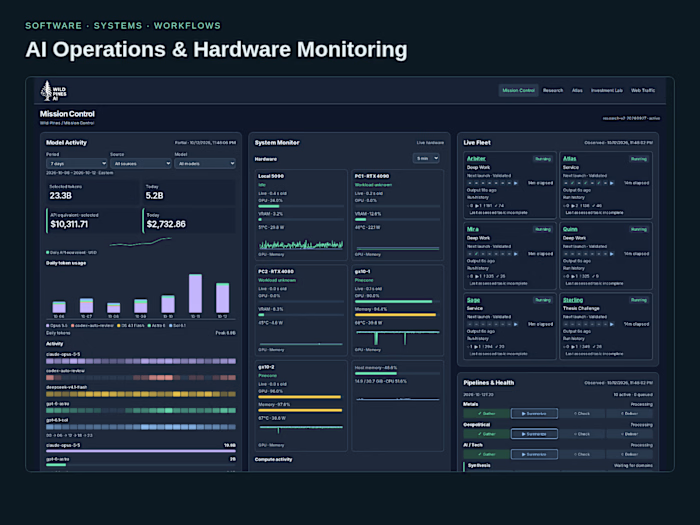
One coordinator owns hardware scheduling. Media workers share two compute nodes when memory permits; paired language-model serving is a separate mode. Model storage supplies verified assets, and monitoring observes without scheduling work.
Internal Wild Pines infrastructure. PC1 is a workstation display alias.
Like this project
Posted Oct 13, 2026
Shared AI processing that coordinates requests, models and compute, with output checks and recoverable delivery.
Likes
0
Views
0