Deep Research RAG

Abhishek Vinod


Deep Research RAG
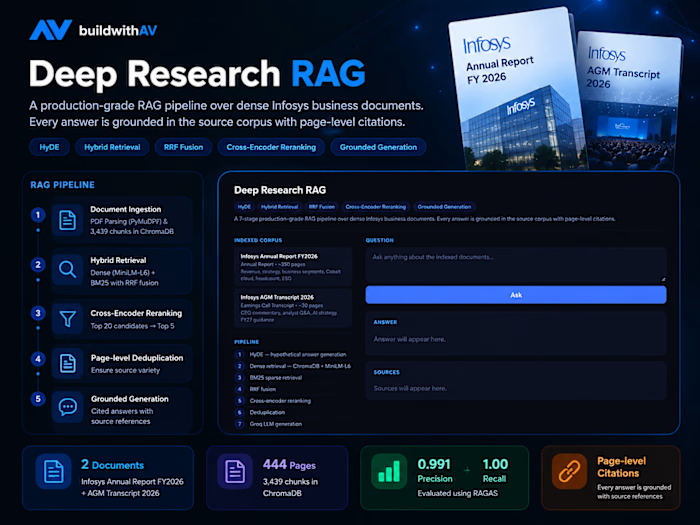
A production-grade Retrieval-Augmented Generation system for dense business and research document corpora. Designed for research analysts and strategy consultants who need evidence-grounded, cited answers across multi-document collections — annual reports, DRHPs, industry reports, expert transcripts.
Live demo: deep-research-rag-production.up.railway.app
Problem
Analysts spend hours manually reading documents to locate specific data points, cross-reference claims across sources, and build evidence-grounded views. Keyword search (Ctrl+F) is shallow. A basic chatbot is unreliable — it hallucinates and cannot cite sources.
This system solves that with a 7-stage pipeline that retrieves the most relevant context before generating an answer, and cites every claim to a specific source document and page number.
Architecture
Tech Stack
Component Library / Service API framework FastAPI + Uvicorn Vector store ChromaDB Dense embeddings sentence-transformers (all-MiniLM-L6-v2) Sparse retrieval rank-bm25 Reranking cross-encoder/ms-marco-MiniLM-L-6-v2 LLM generation Groq API (compound-beta-mini) Containerisation Docker + Docker Compose Deployment Railway (Dockerised, Southeast Asia region) Evaluation Local RAGAS-equivalent metrics (no API calls)
Evaluation Results
Evaluated on 13 ground-truth question-answer pairs across the ingested corpus.
Metric Score What it means Context Precision 0.991 Retrieved chunks are almost entirely relevant Context Recall 1.000 Every reference sentence is covered by the retrieved context Faithfulness 0.385 See note below Answer Relevancy 0.462 Correlates with faithfulness — same root cause
Note on Faithfulness: The 0.385 is a measurement artefact, not hallucination. The cross-encoder faithfulness metric penalises terse one-liner answers (produced for numerical fact queries) because short answer sentences score in a different logit range than full sentences when paired with long context paragraphs. Conceptual questions — where the model produces multi-sentence answers — all scored 1.000. Fix: modify the generation prompt to require full-sentence answers for all query types.
Project Structure
Quickstart — Portfolio Demo UI
Then open http://localhost:7860 for the dark-mode browser interface with example questions, inline answers, and page-level source citations.
Quickstart — Production API
Interactive docs: http://localhost:8000/docs
Quickstart — Docker
The ChromaDB vector store is baked into the Docker image. HuggingFace model weights are cached in a named Docker volume (
huggingface_cache) so they download once and persist across container restarts.API Reference
GET /health
GET /healthReturns pipeline readiness status.
POST /query
POST /queryRuns the full 7-stage pipeline.
Errors:
422 — empty or missing question field500 — pipeline error (check detail field)Like this project
Posted Oct 2, 2026
Production-grade RAG system for multi-document research and consulting intelligence