AI-Powered OCR Pipeline for Document Processing

Most OCR systems stop at text extraction.
The real value starts after the document is read.
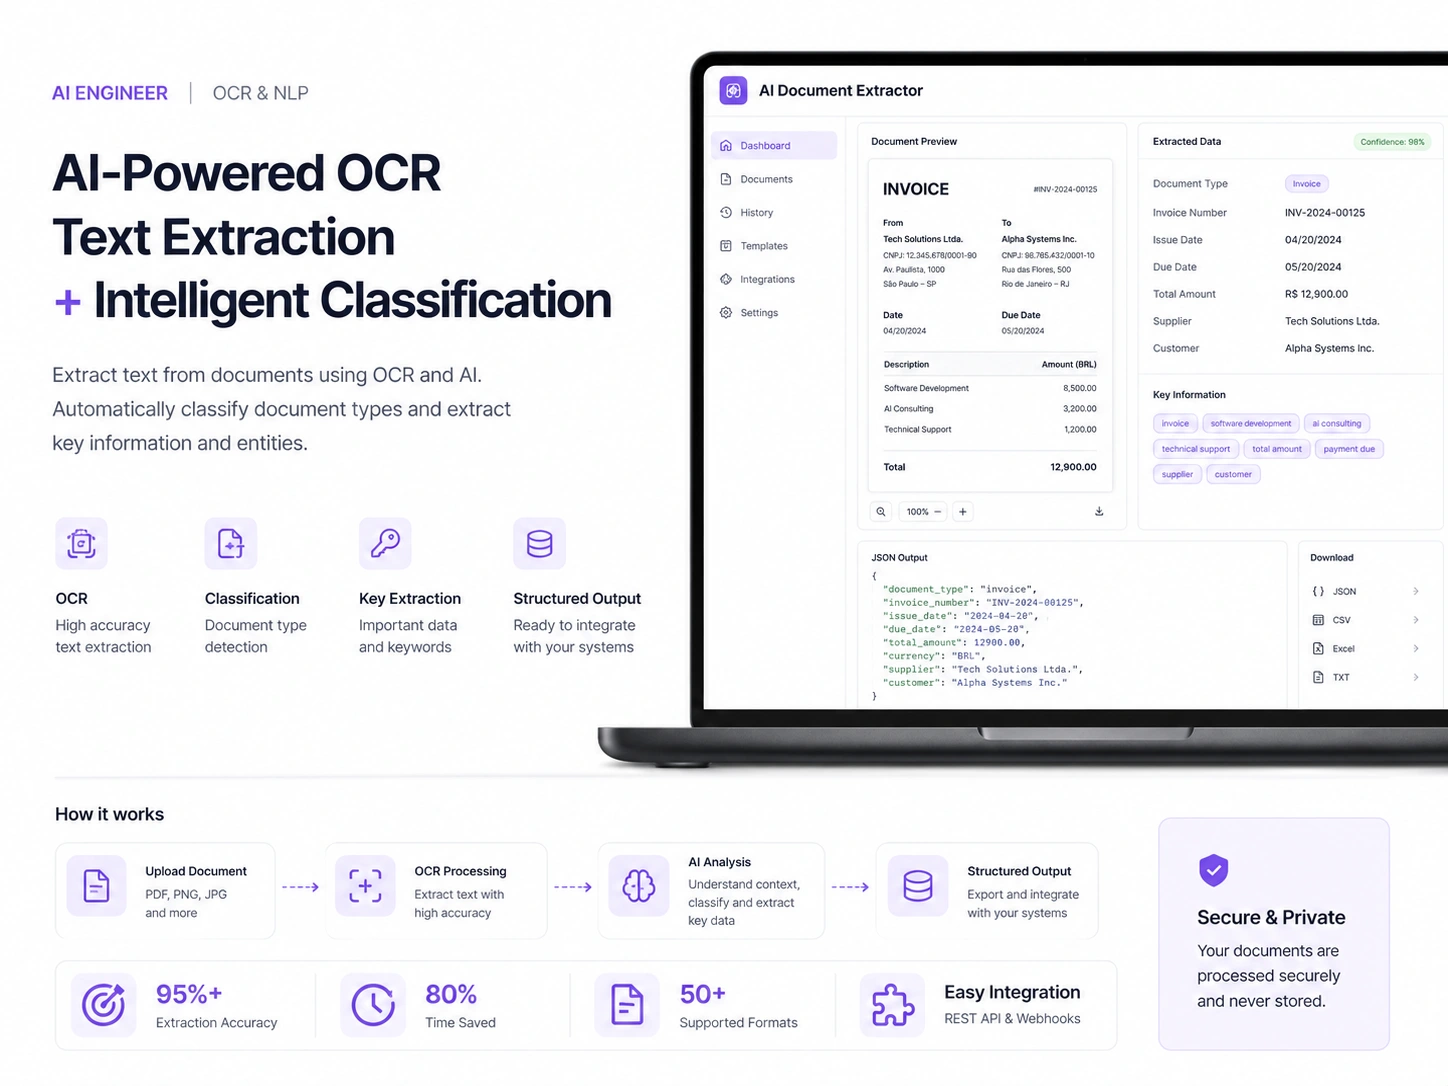
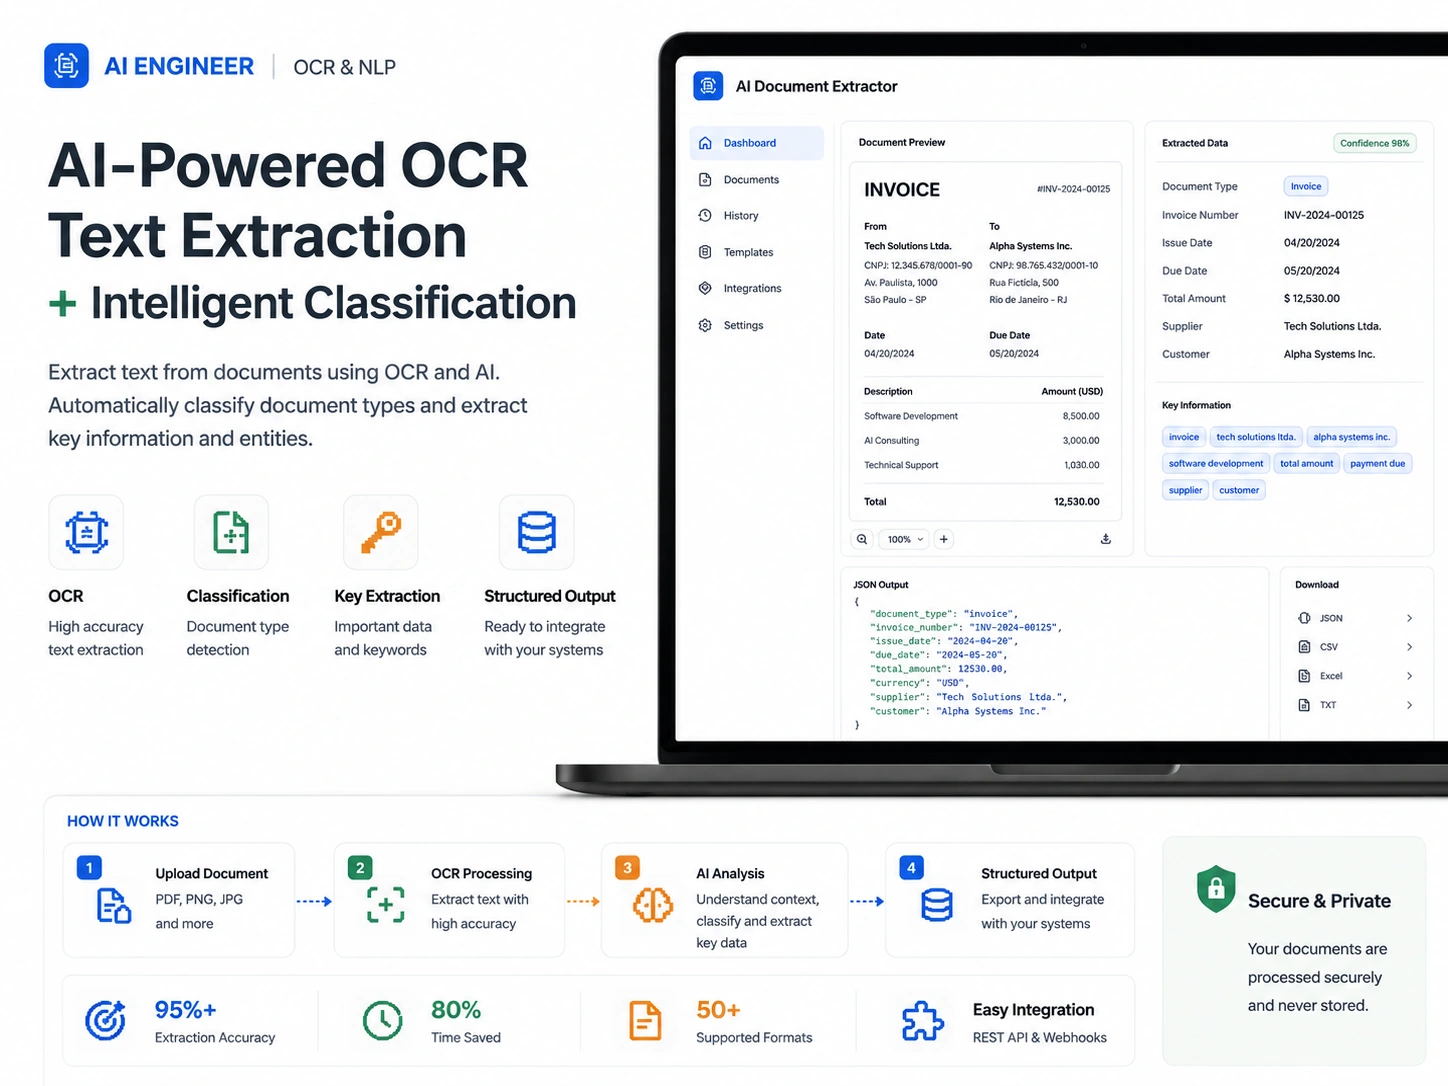
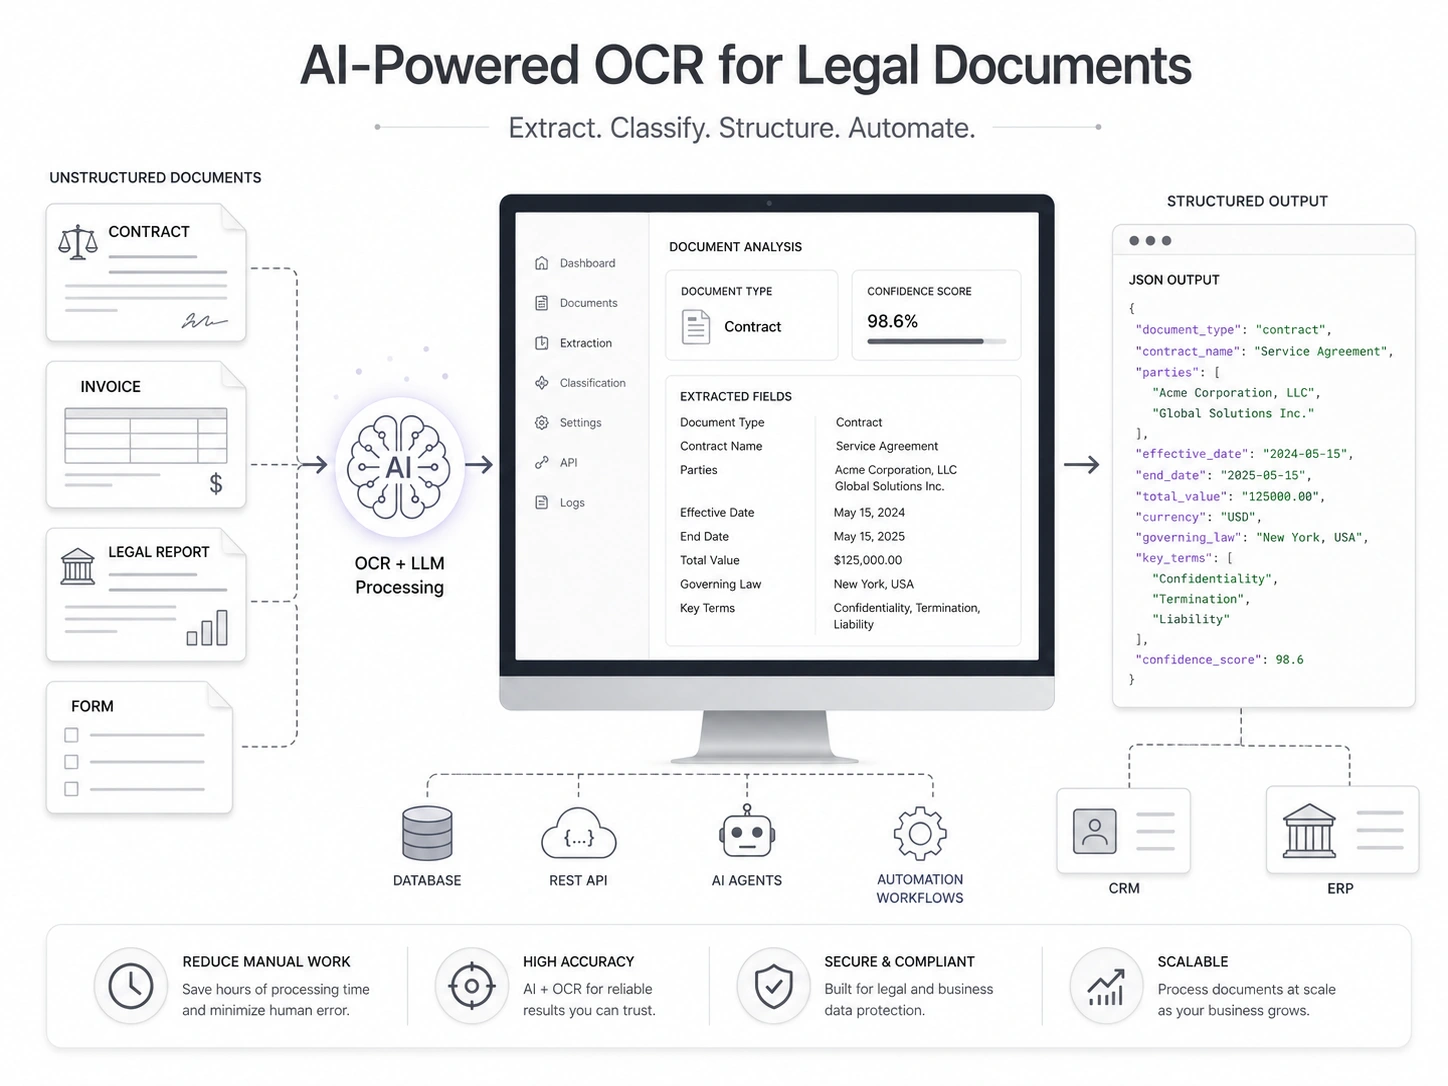
In this project, I built an AI-powered OCR pipeline capable of extracting text from invoices, contracts, reports, and forms while also classifying the document type and identifying key information automatically.
Instead of returning raw text only, the system structures the data into usable outputs for automation workflows, CRMs, ERPs, and AI agents. This reduces manual processing time and makes documents immediately actionable inside business operations.
The stack combines OCR engines with LLM-based processing for contextual understanding, keyword extraction, and intelligent classification. The result is a more reliable document processing flow that can integrate directly with APIs, databases, and automation systems.
This is where AI engineering becomes practical: transforming unstructured files into structured business data at scale
0 likes · 0 views · May 7, 2026
Most OCR systems stop at text extraction. The real value starts after the document is read. In this project, I built an AI-powered OCR pipeline capable of ex...
Timeline
Feb 2, 2026 - Feb 16, 2026