Agent Evaluation & Benchmarking Dashboard

Sineth Madduma


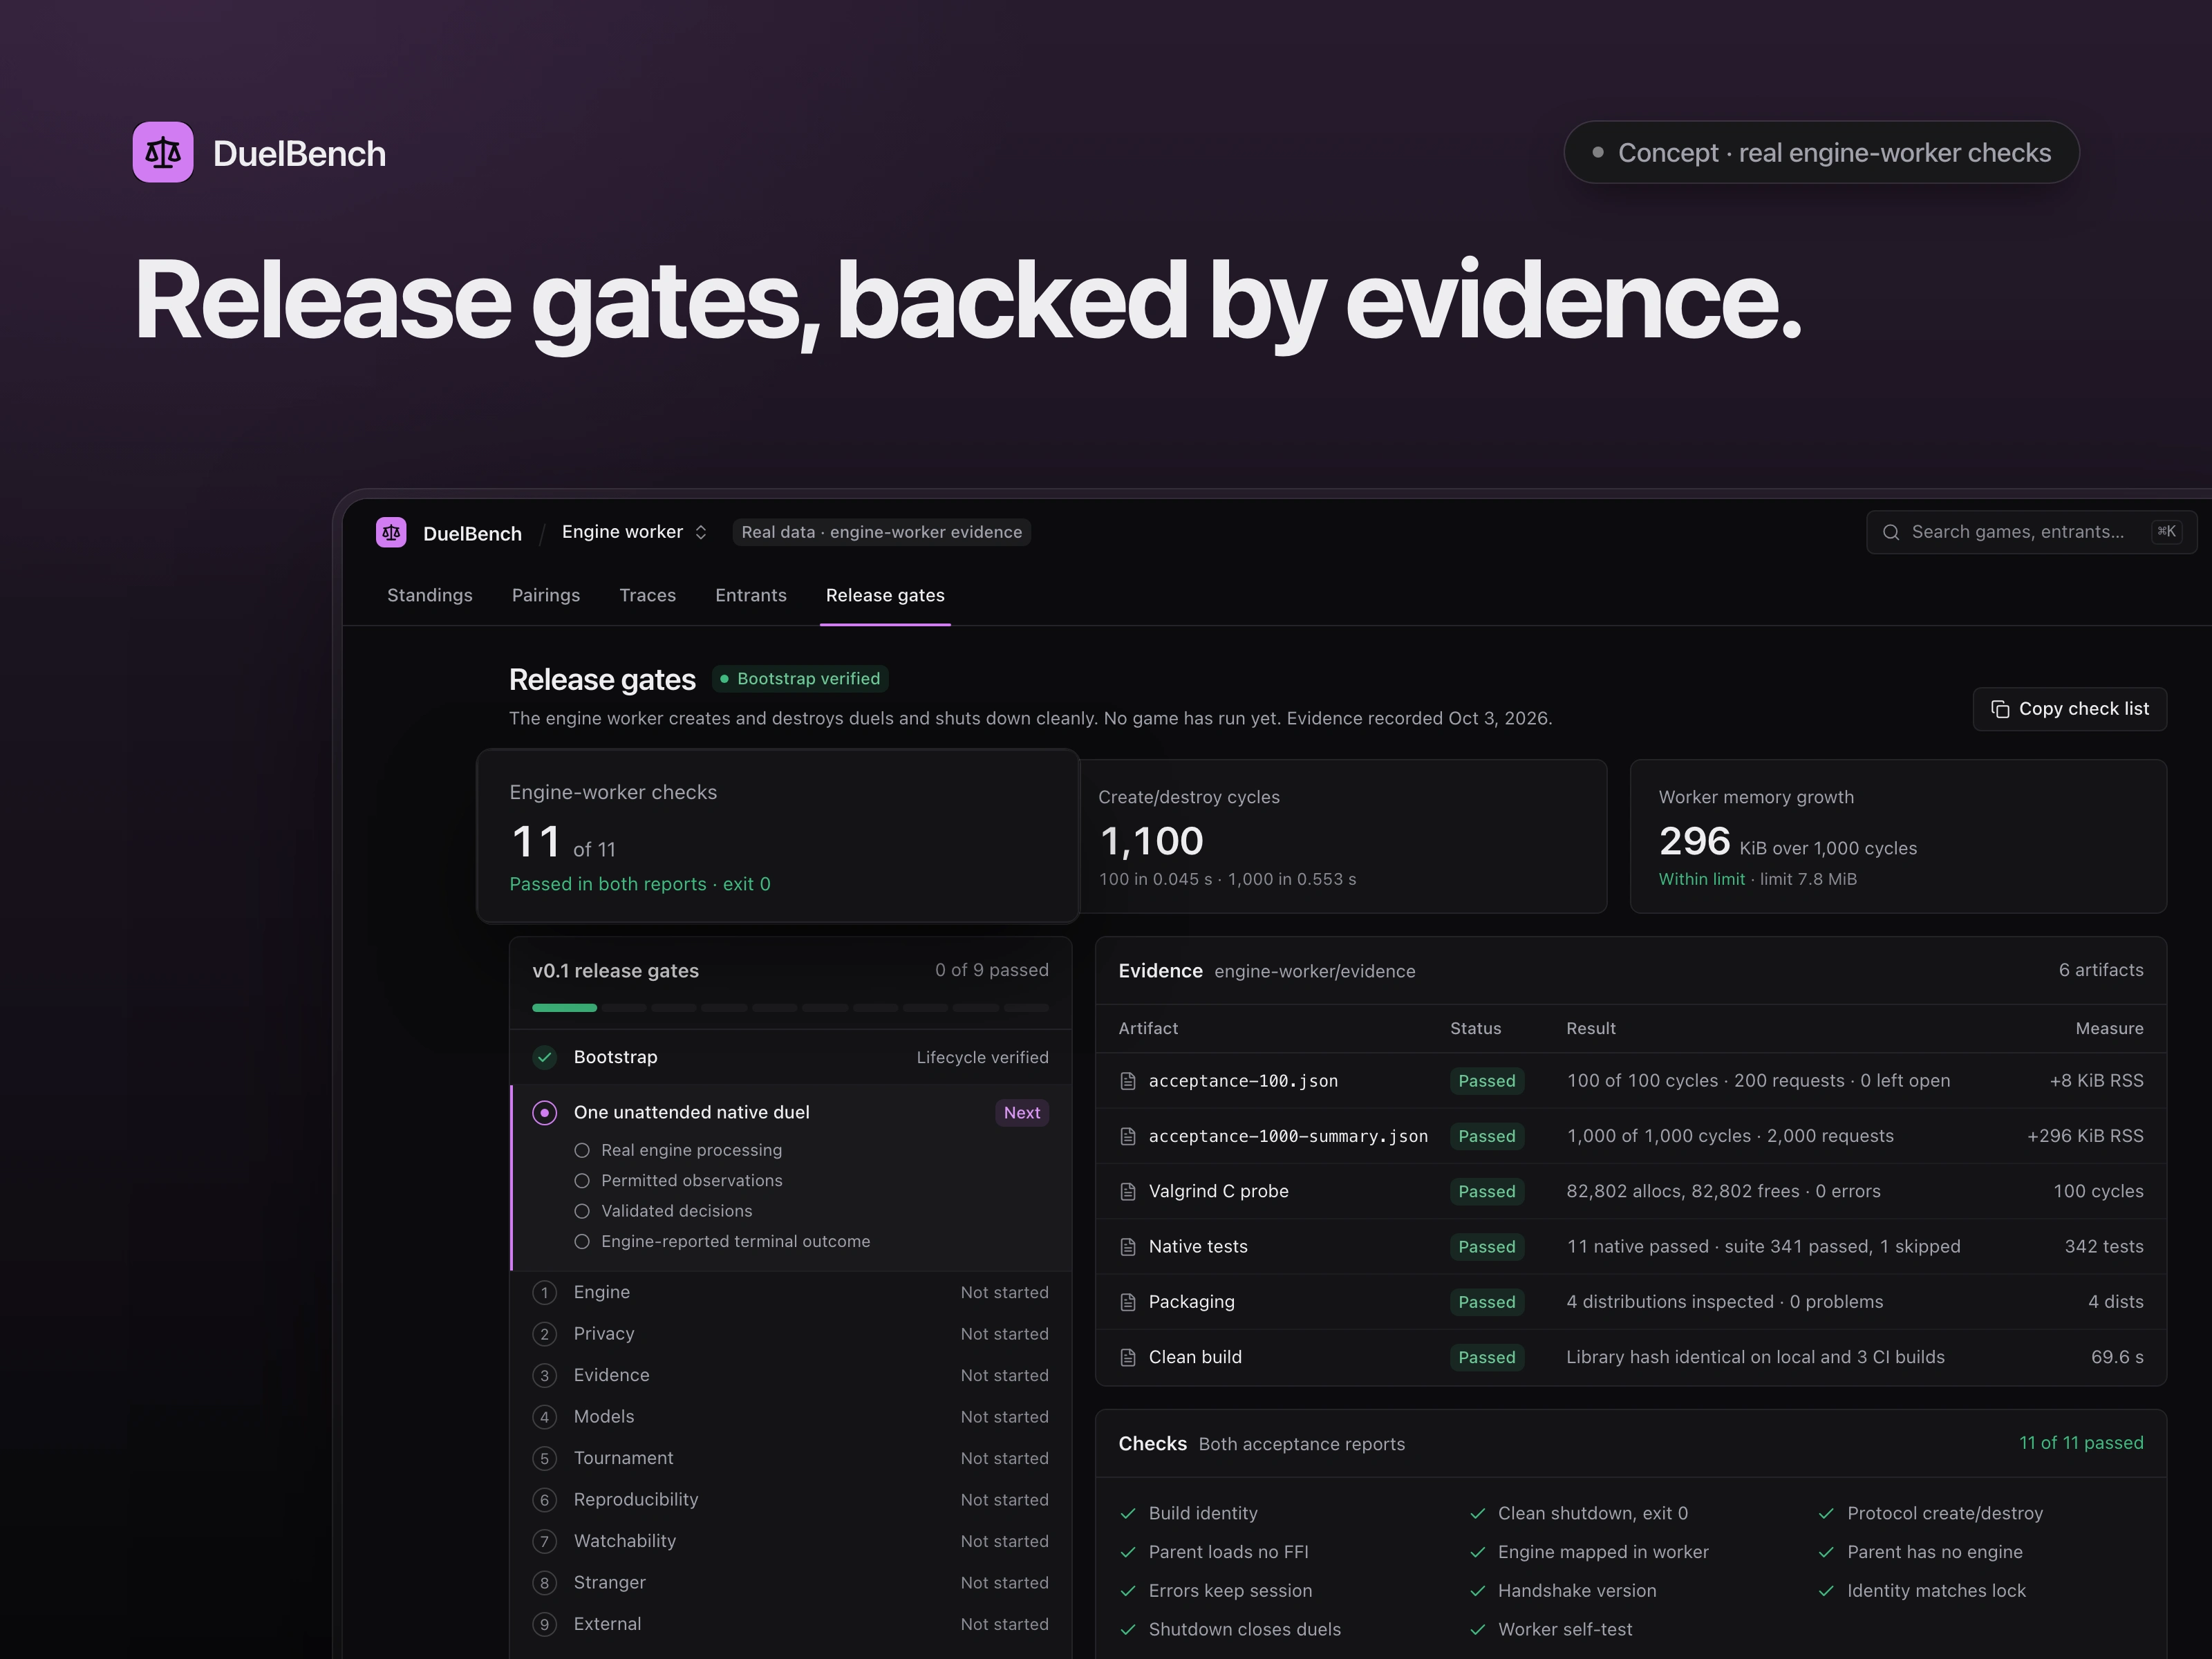
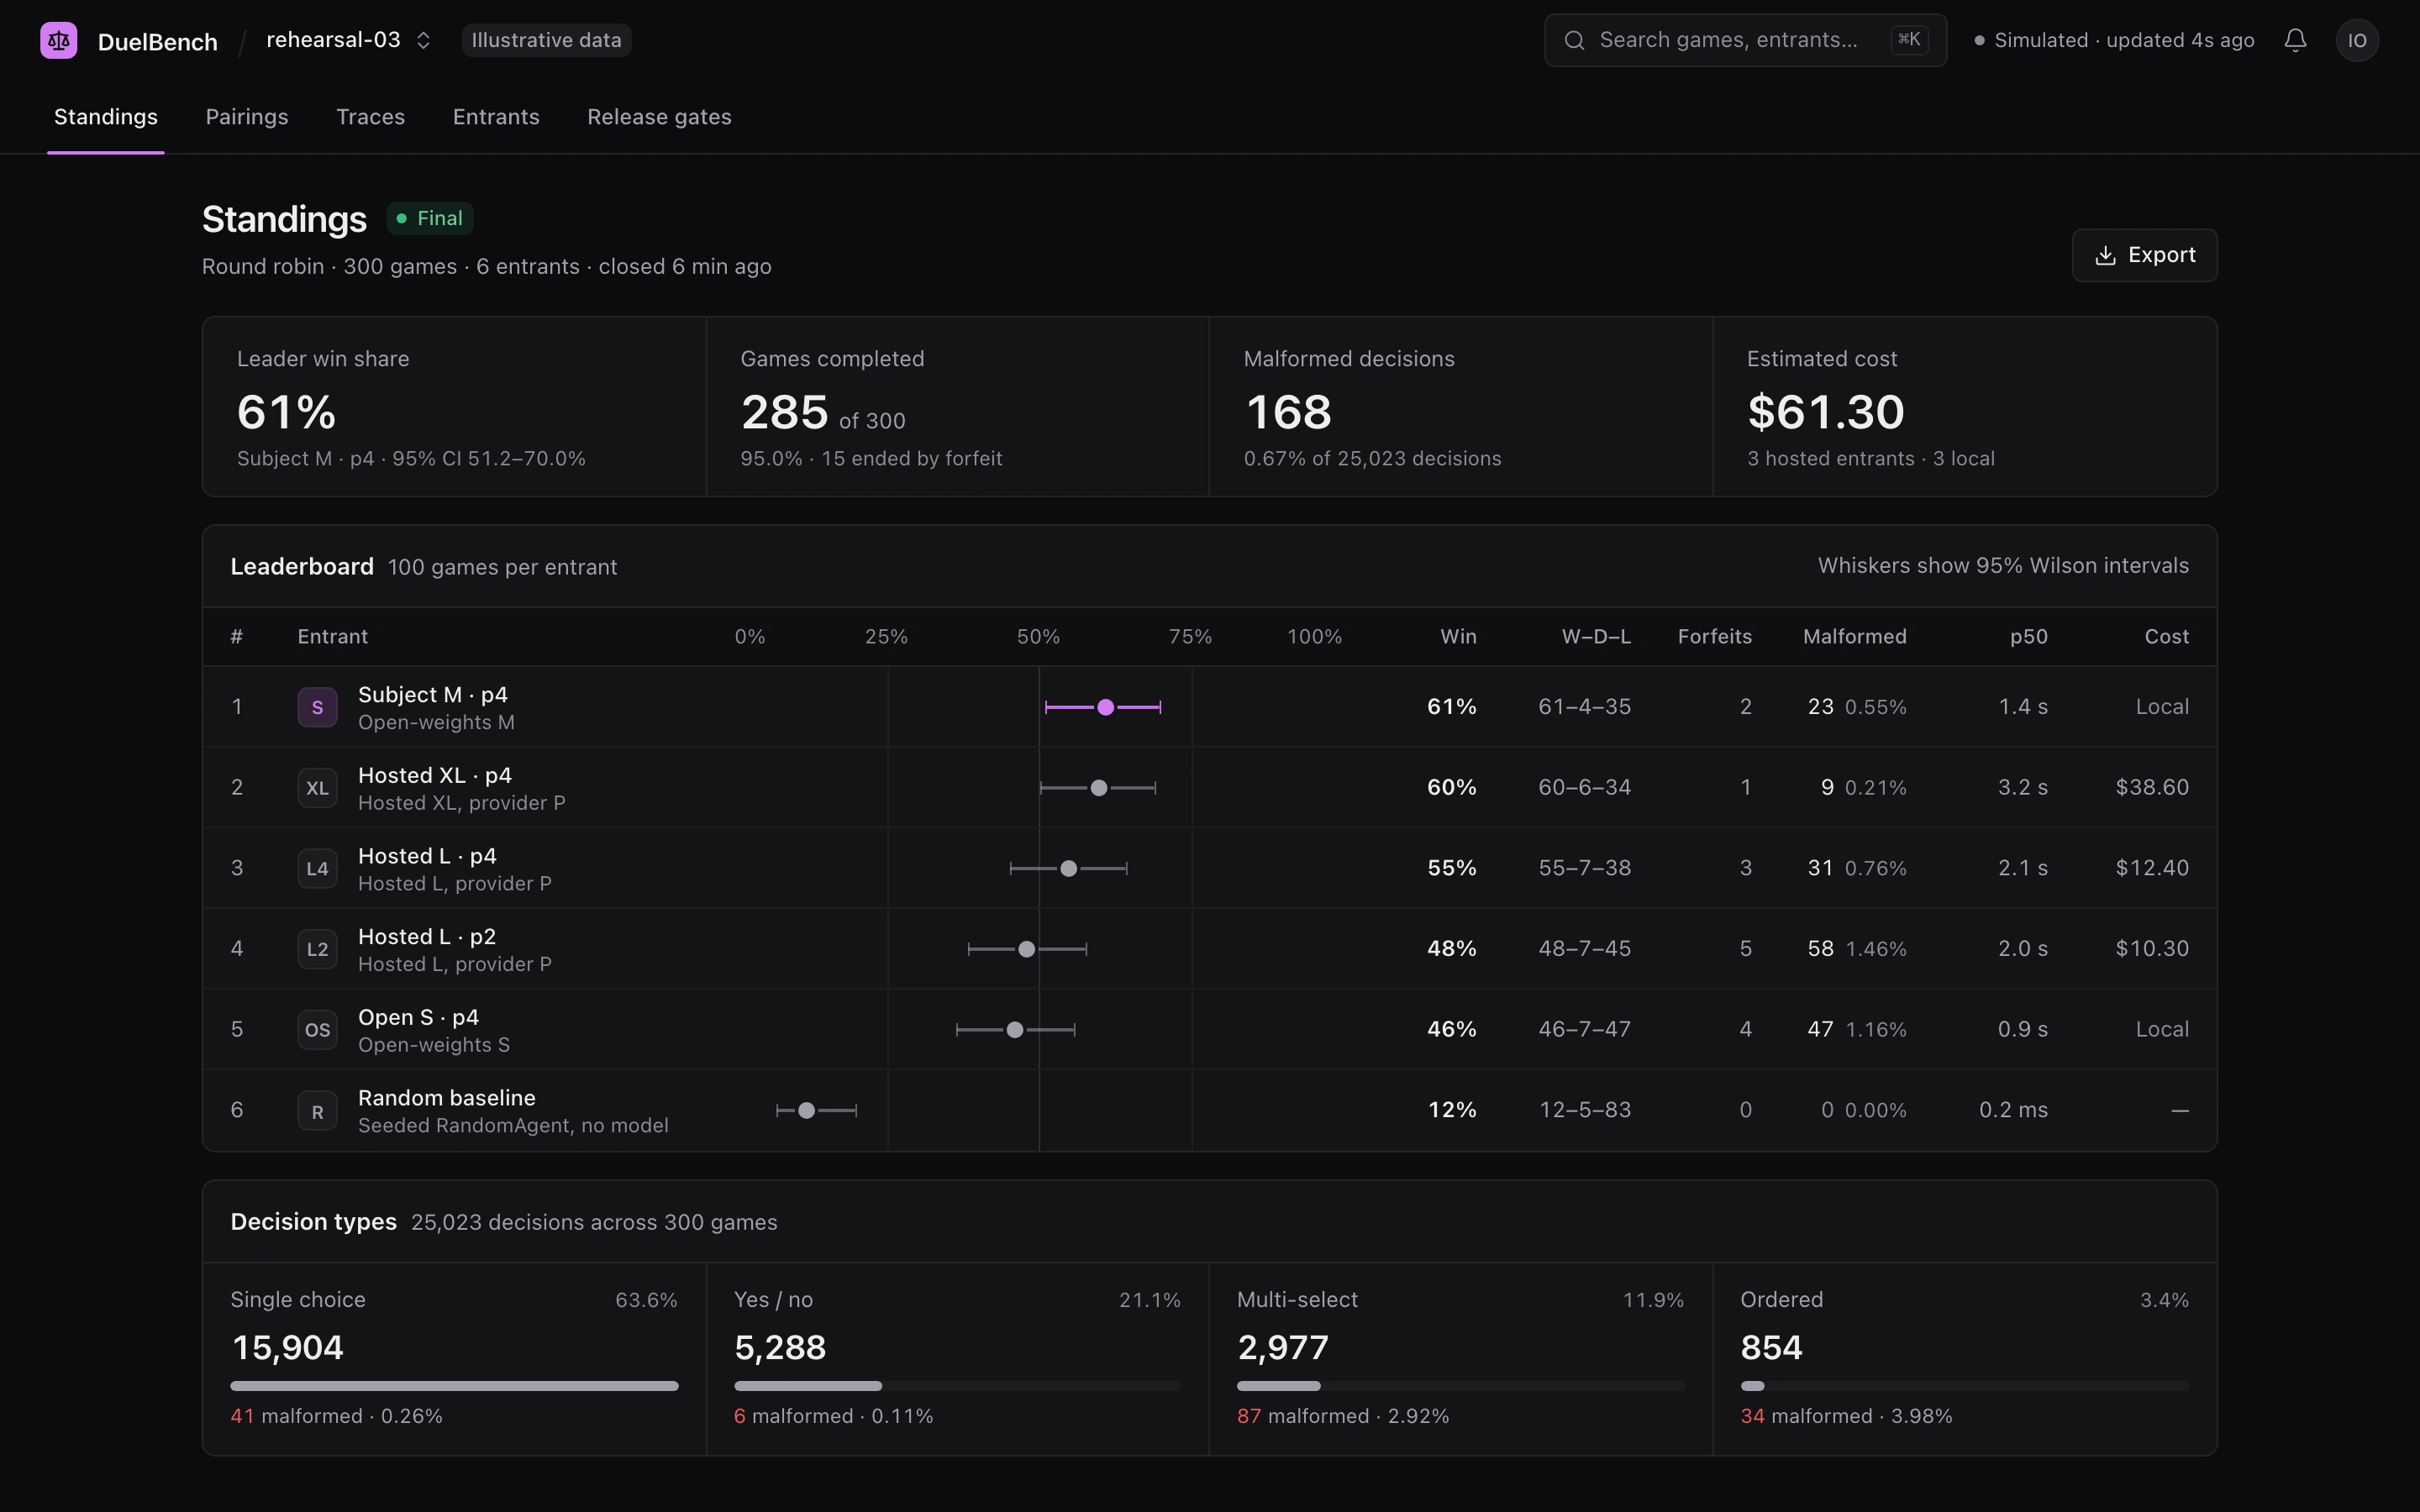
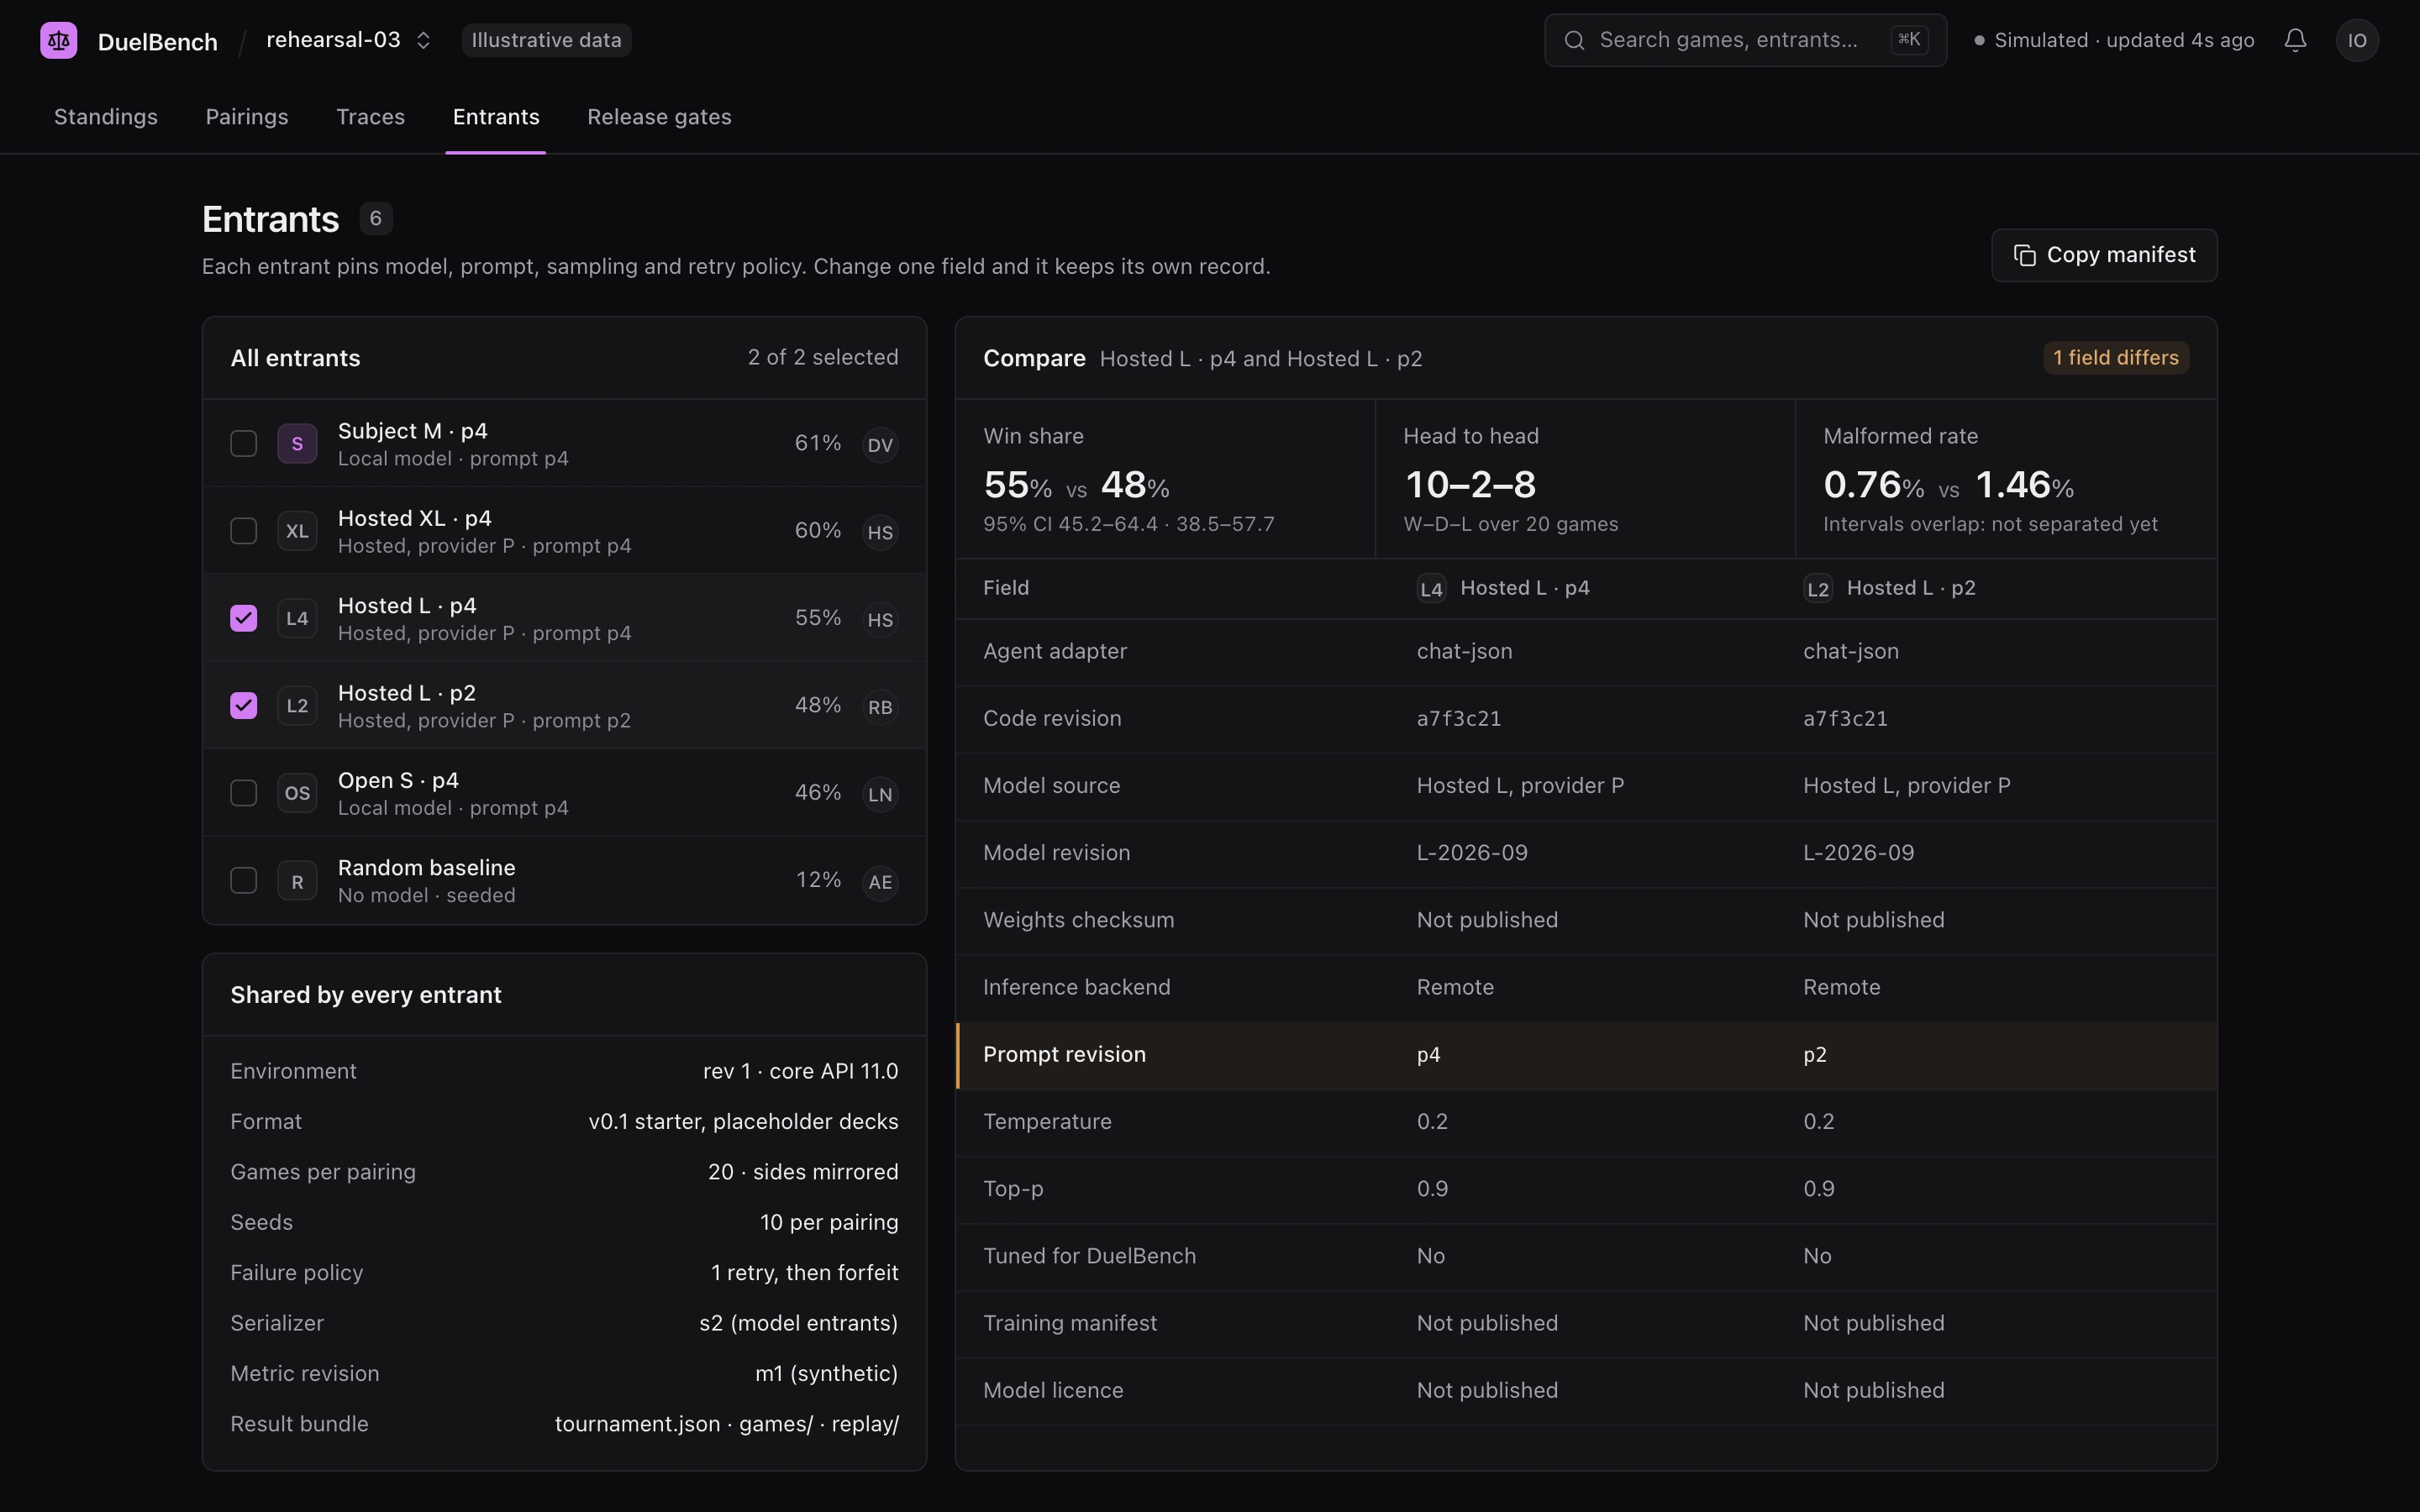
Status: Concept. An evaluation interface for an agent harness I'm building; no games have been played yet. Data is illustrative except the engine-worker evidence on the gates screen.
The problem
Teams comparing agent setups often let one model grade another, then can't say why one setup won. I wanted an external engine to own legality, randomness and outcomes, and a results view showing only what it observed.
What I built
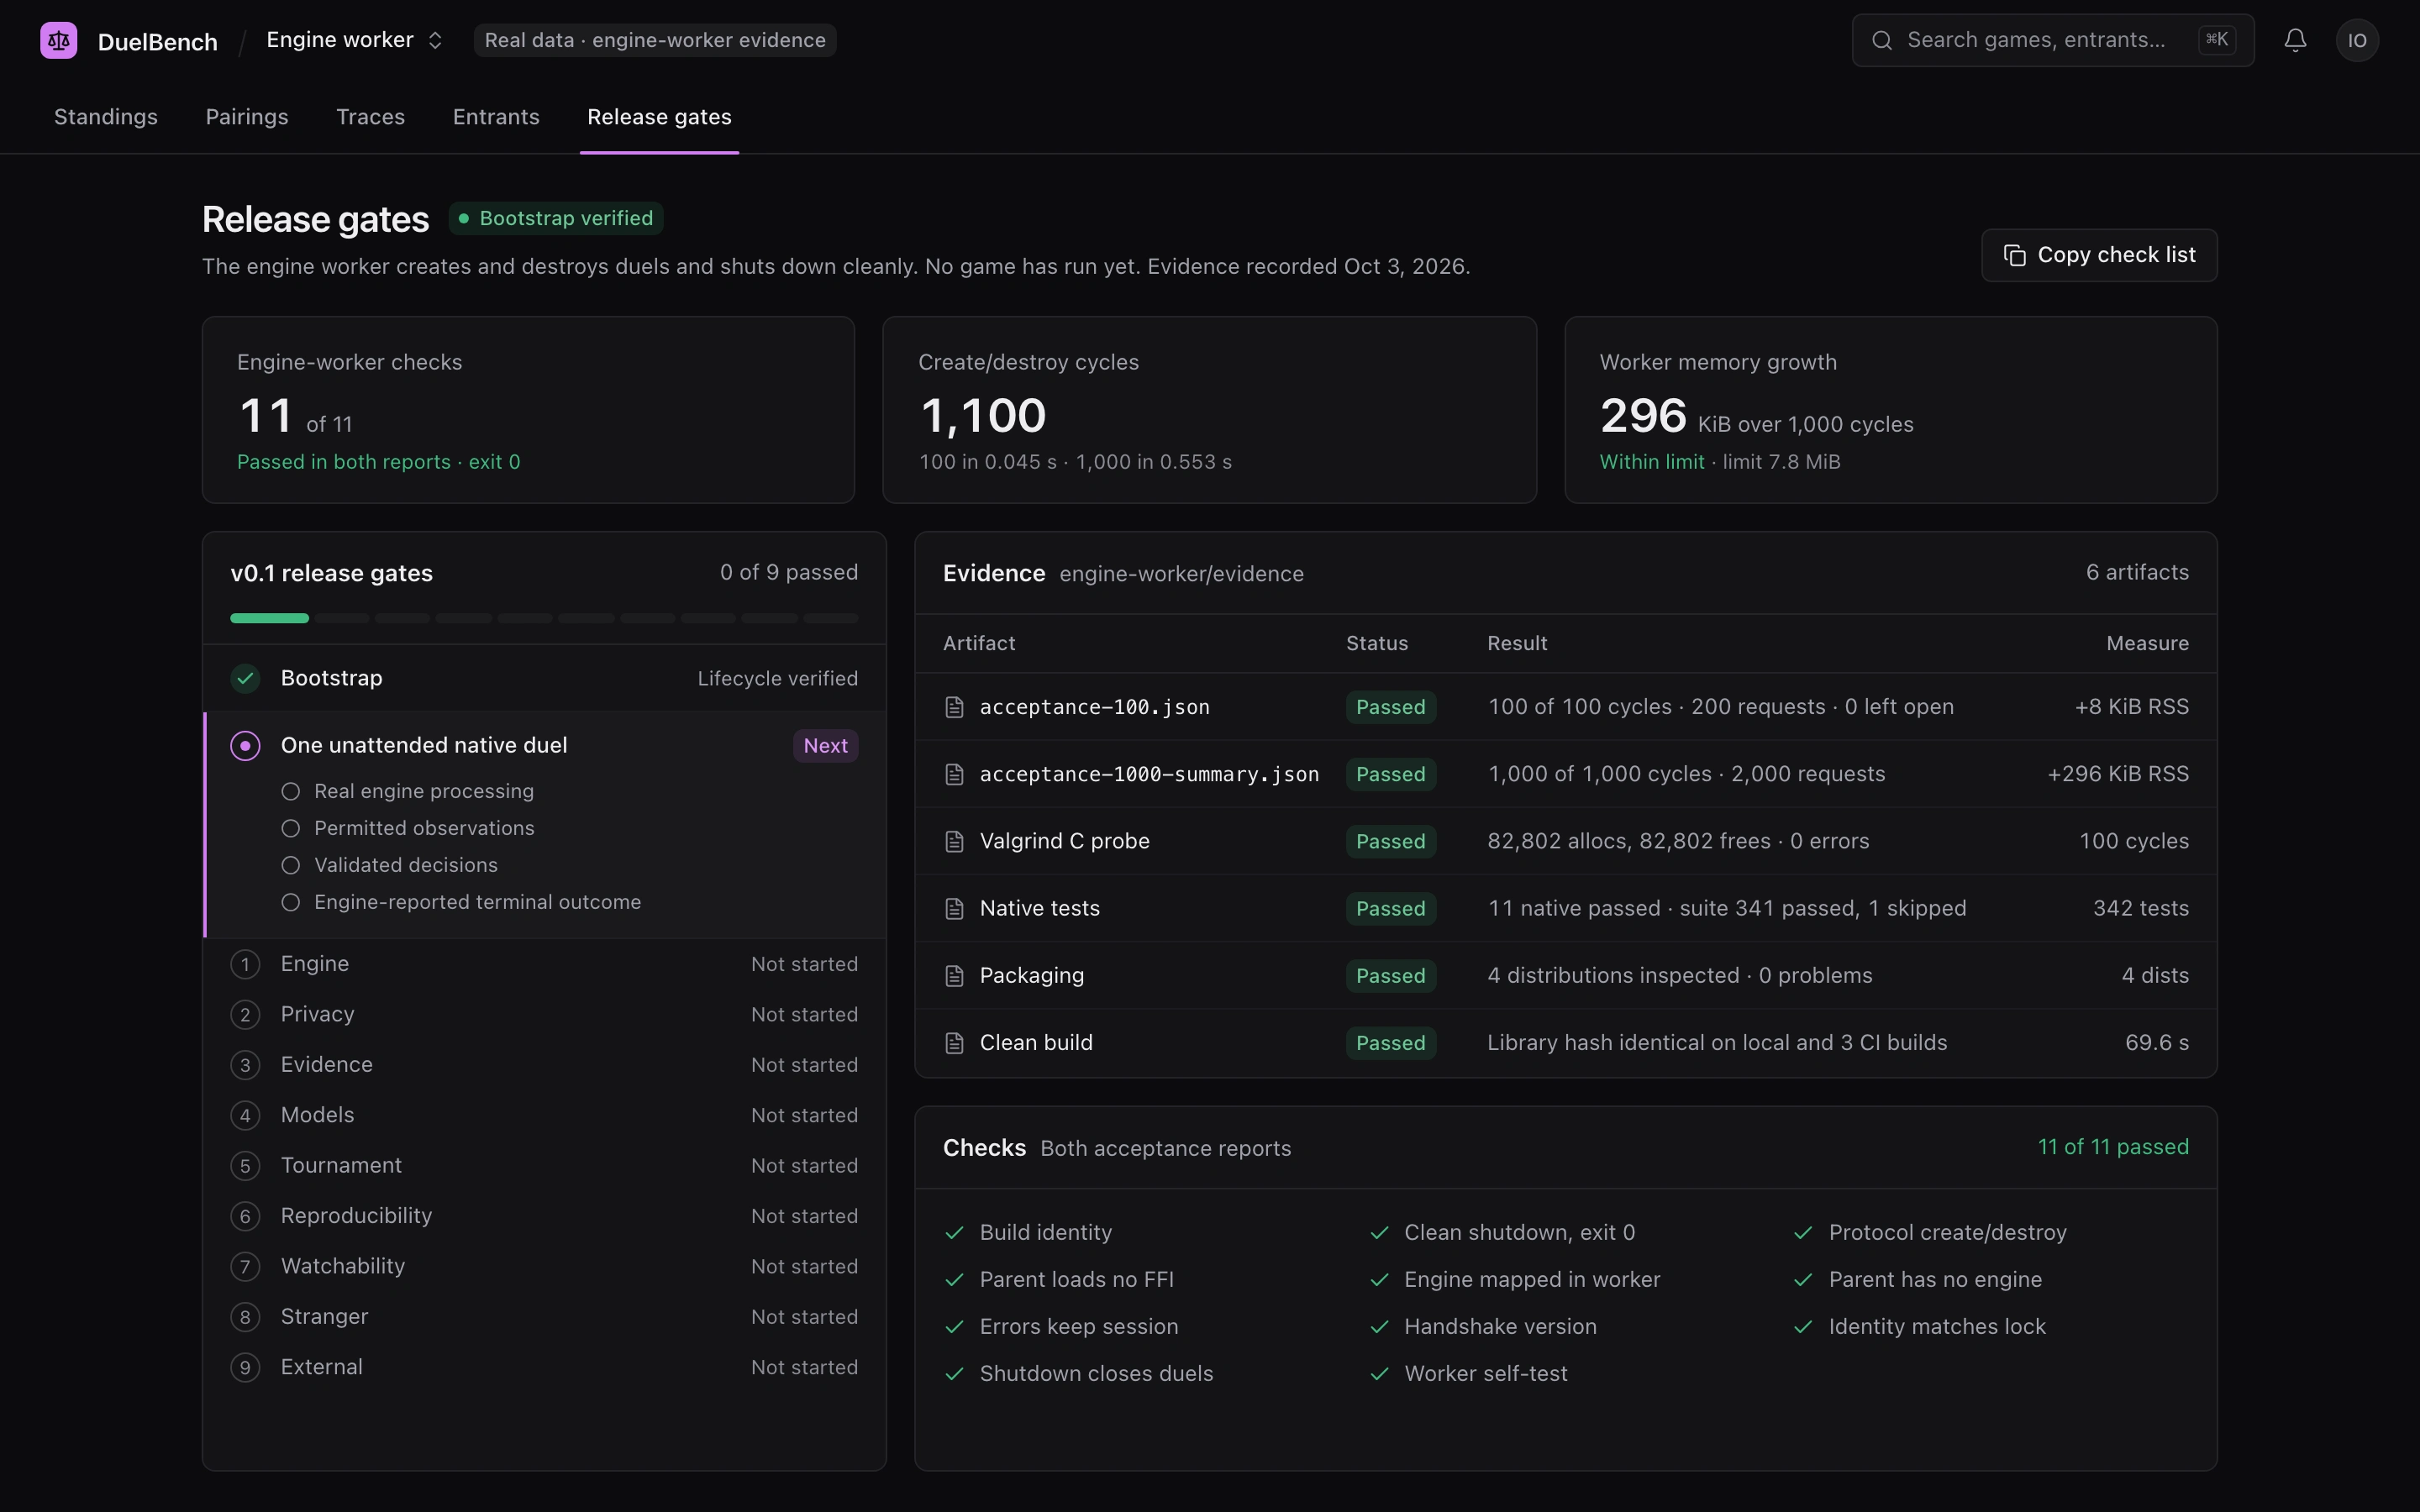
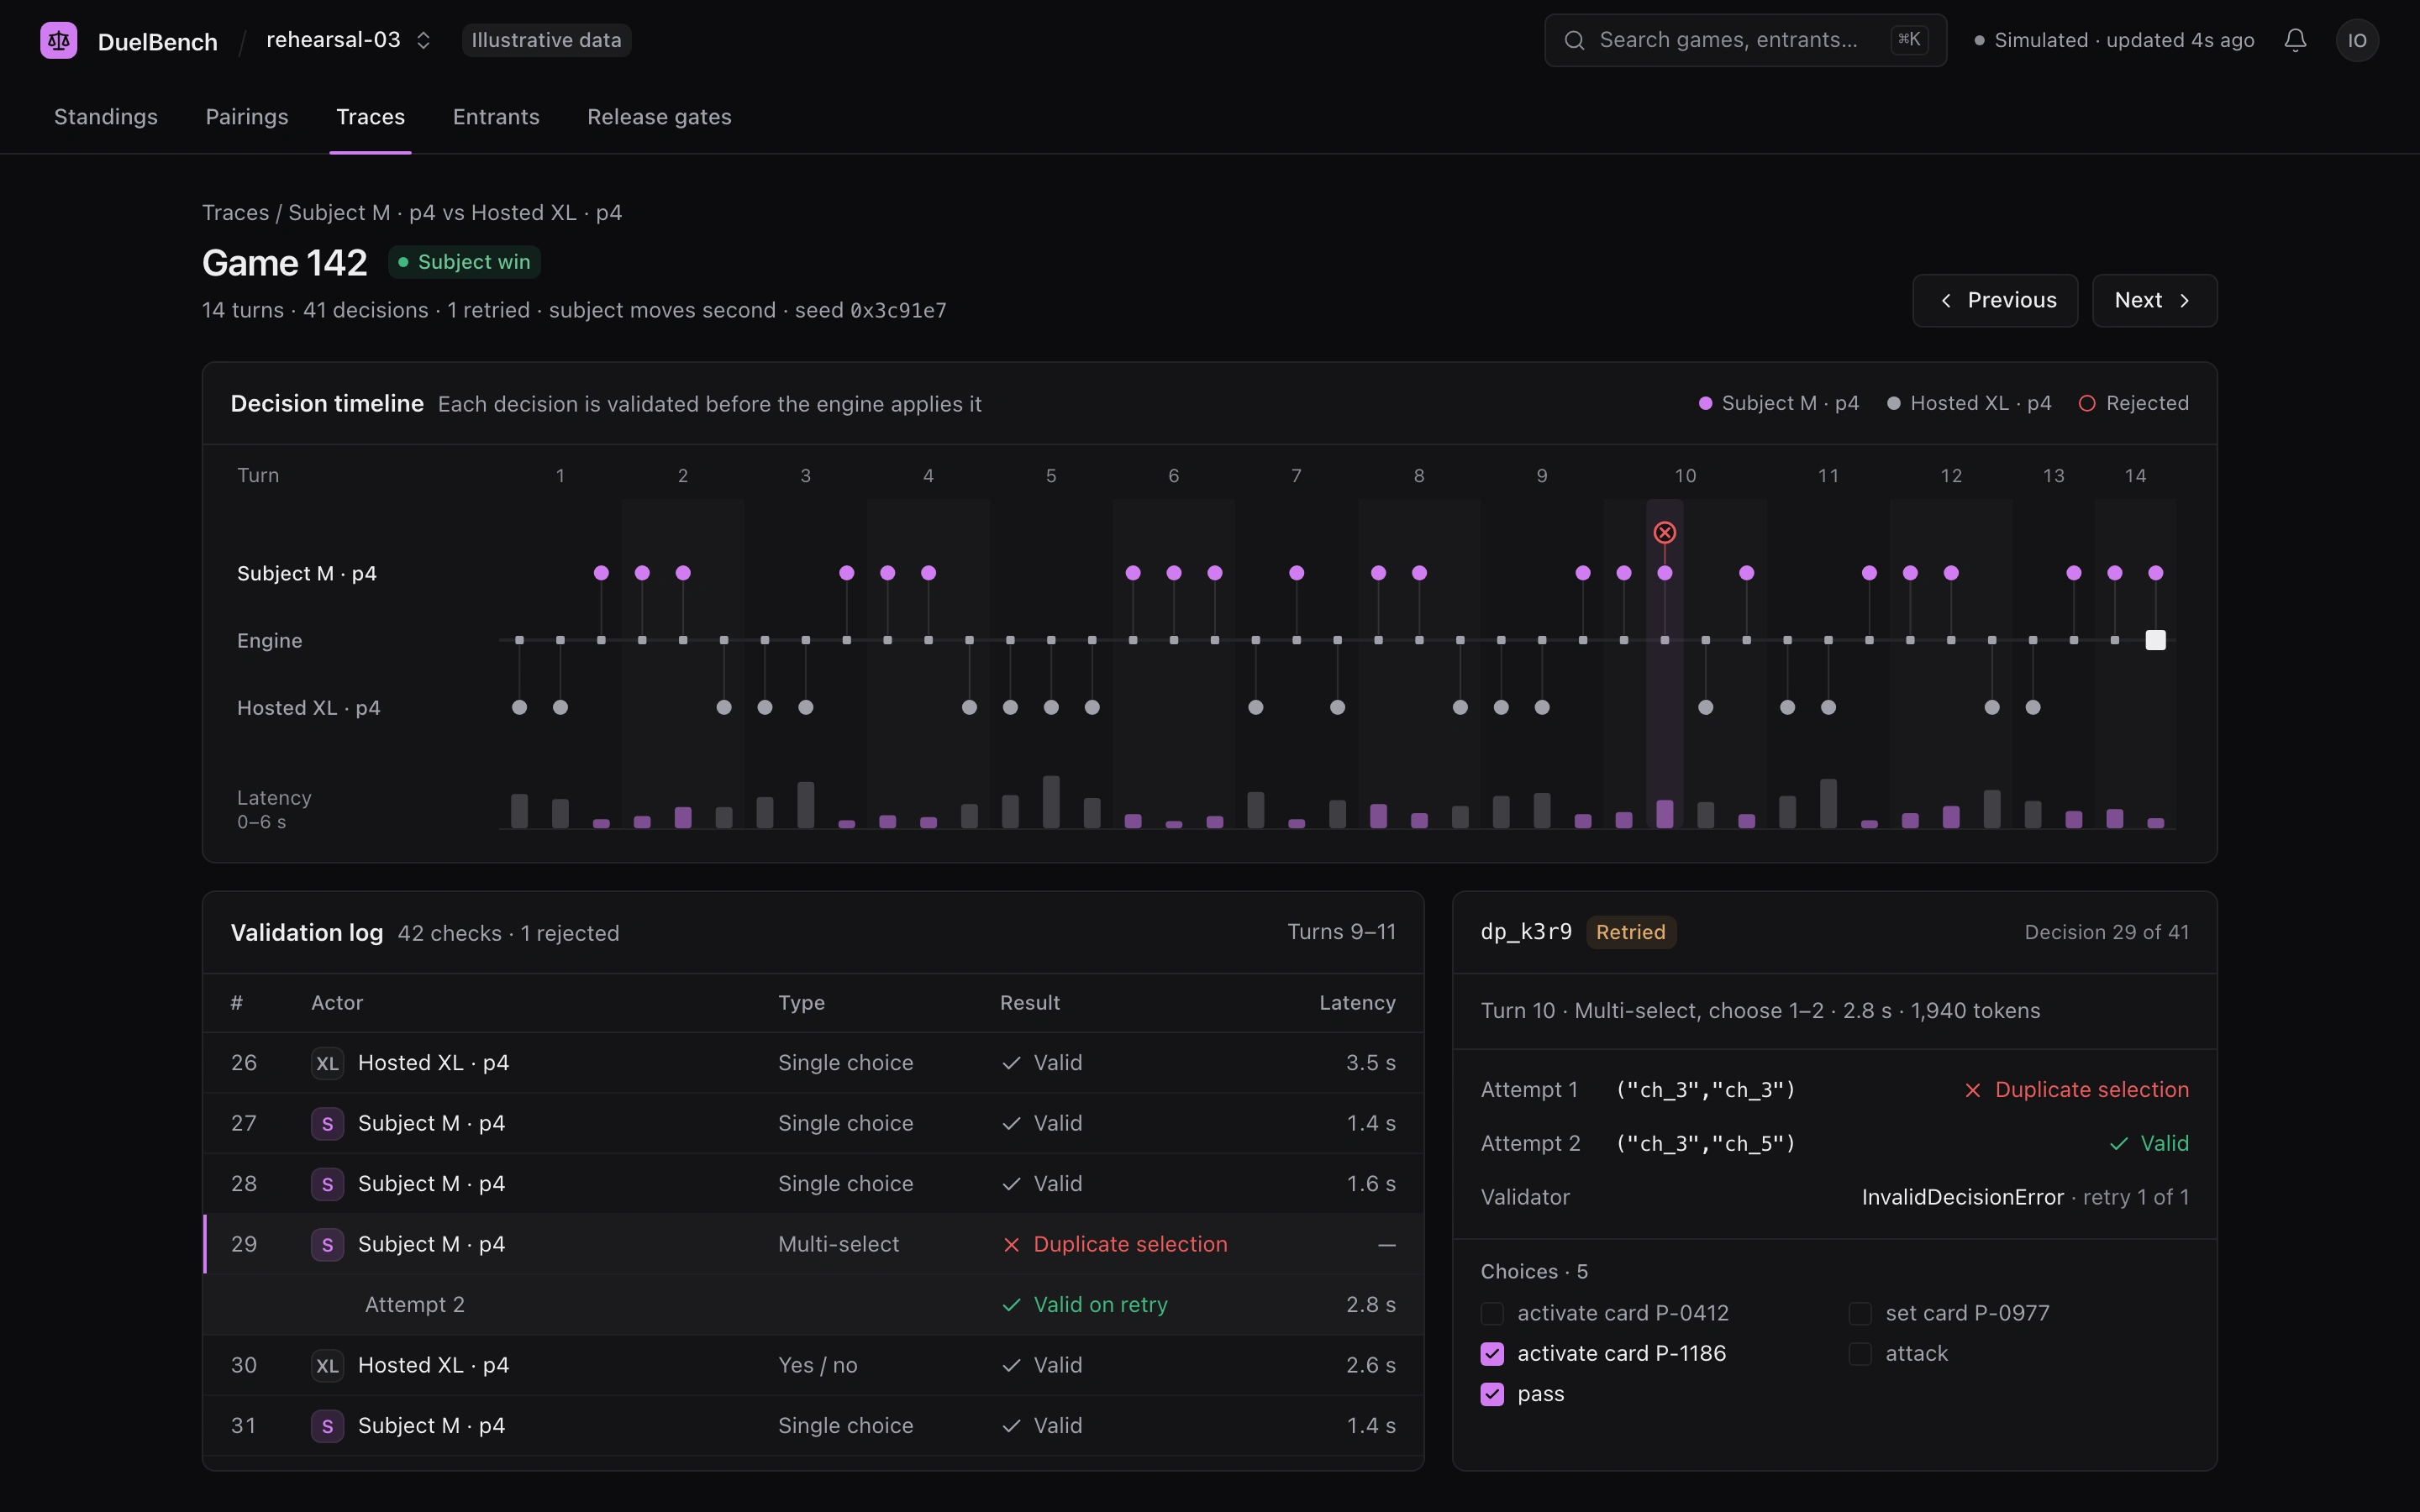
My private DuelBench repo has a decision protocol with a validator that rejects unknown, duplicate and out-of-range choices, a seeded random baseline, and a separate engine worker. The worker's bootstrap passed 100 and 1,000 create/destroy cycles with all 11 checks true. No game has run on it.
The screens are my design for the planned v0.1 views, using only observable metrics. Full games, model adapters and the tournament runner aren't built, and none of the 9 release gates has passed.
What I can build for you
AI Agents & Workflow Automation, from $750: an agent in your tools, tested on your real cases. An agent system with its own evaluation set starts at $2,500.
Captions
Gates & evidence: real engine-worker evidence, with 11 of 11 checks true and 0 of 9 gates passed.
Match trace, game 142: one game, decision by decision; a duplicate choice is rejected, then retried.
Standings: six synthetic entrants by win share, with 95% intervals that overlap at the top.
Entrants: the same model with two prompts makes two entrants with separate records.
Like this project
Posted Oct 19, 2026
Evaluation views for an agent harness where an engine, not a judge model, decides outcomes. Engine-worker checks are real (11 of 11); standings illustrative.
Likes
0
Views
0