Development of CGAF-Tune Framework

Lakshmi Anne


Anne07-Ai/cgaf-tune — A research-focused framework for developing and evaluating novel adaptive fine-tuning methods for large language models, featuring reproducible experiments, baseline comparisons, ablation studies, and clear architecture diagrams. · Other · 5 stars · 0 forks · 0 watching
🌌 CGAF-Tune
Conflict-Gated Adaptive Fine-Tuning for capability-preserving LLM adaptation
CGAF-Tune tests whether parameter-efficient fine-tuning can learn a narrow domain while preserving a base model's general capabilities. It targets Qwen3-0.6B/1.7B on one 16–24 GB GPU with LoRA or 4-bit QLoRA.
Important Research status: early prototype. CGAF is a falsifiable hypothesis, not a claimed state-of-the-art result.\n>\n> Phase 6 finding: CGAF achieved the highest mean domain F1 but did not improve balanced harmonic F1 over LoRA or rehearsal across three seeds.
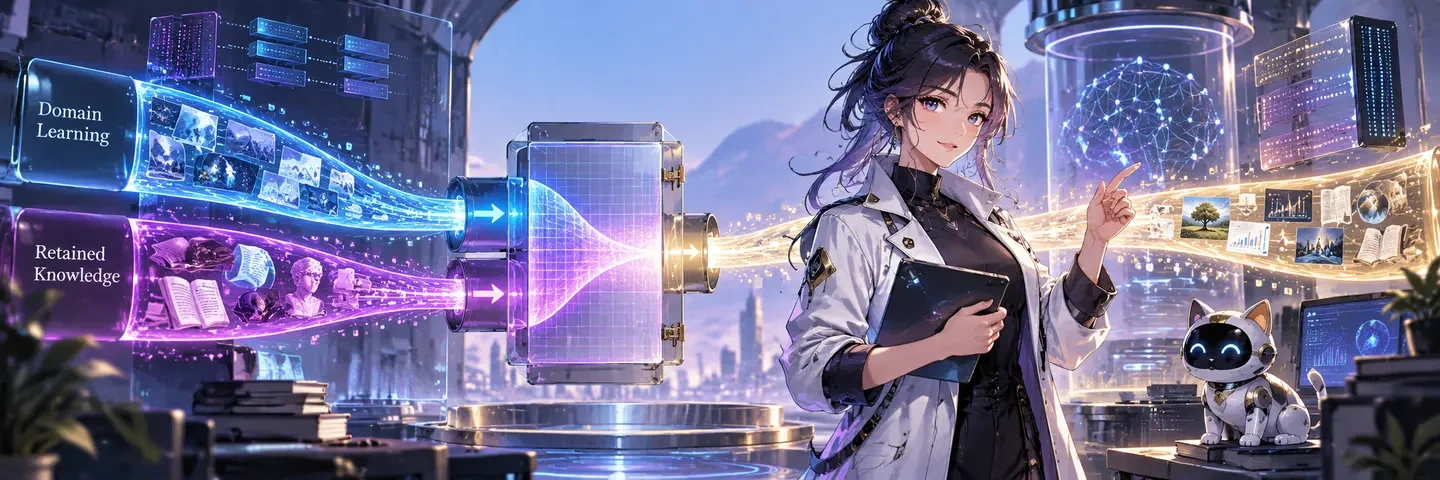
🔵 Learn 🟣 Protect ✨ BalanceAdapt to specialised domain data Preserve general reasoning and instruction following Intervene only when gradients conflict
🎯 Research question
Can layer-local gradient-conflict gates preserve general instruction following and reasoning better than ordinary LoRA, rehearsal, and ungated gradient projection at the same trainable-parameter and data budgets?
🧠 How CGAF works
Each step computes adapter gradients from a domain batch and a small capability-retention anchor batch. For adapter group (l), CGAF measures cosine conflict and smoothly removes only the harmful component:
$$ g'_l = g^D_l - \gamma_l \frac{\min(0,\langle g^D_l,g^A_l\rangle)} {\lVert g^A_l\rVert^2+\epsilon}g^A_l, \qquad \gamma_l=\sigma(-c_l/T) $$
Positive alignment is untouched. The hypothesis is that soft, local intervention yields a better adaptation–retention trade-off than globally mixing rehearsal loss or always projecting gradients.
⚔️ Method comparison
Method Adaptive signal Intervention Retention targetLoRA None Low-rank update No AdaLoRA Parameter importance Rank allocation No Rehearsal LoRA Mixed examples Joint loss Yes PCGrad-style LoRA Gradient conflict Hard projection Yes CGAF Per-group conflict Smooth gated projection Yes
🚀 Quick start
The smoke test executes the complete Phase 1 two-pass gradient engine without downloading a model. For a real Qwen3 QLoRA run, provide domain and capability-retention JSONL files:
Run matched baselines by changing only the method:
Each JSONL row may contain
text, prompt plus response, or a messages list. Training writes step-level conflict diagnostics to metrics.jsonl and saves the final PEFT adapter separately from the frozen base model.🗂️ Repository structure
src/cgaf_tune/ — conflict measurement and gated projectionsrc/cgaf_tune/training.py — domain/anchor backward passes and optimizer-step enginesrc/cgaf_tune/gradients.py — deterministic LoRA parameter grouping and gradient transfersrc/cgaf_tune/data.py — validated JSONL ingestion and causal-LM collationsrc/cgaf_tune/hf.py — Qwen3, 4-bit NF4, and PEFT LoRA constructionsrc/cgaf_tune/runner.py — real training loop, metrics, and adapter checkpointssrc/cgaf_tune/evaluation.py — adaptation, retention, forgetting, and seed summariesscripts/train.py — validated experiment entry pointconfigs/ — reproducible single-GPU configurationstests/ — numerical unit testsdocs/research-proposal.md — hypothesis, related work, and experimental designdocs/architecture.md — system, training sequence, and experiment diagramsdocs/evaluation.md — metrics, baselines, ablations, and reporting rules🧪 Planned baselines and ablations
plain LoRA; rehearsal LoRA; hard PCGrad-style LoRA; AdaLoRA
global versus layer-wise versus module-wise gates
gate temperature, anchor size, projection frequency, and anchor-domain composition
at least three seeds, equal data and update budgets
📊 Primary metrics
Domain score, retained capability score, forgetting, harmonic adaptation–retention score, peak GPU memory, wall-clock overhead, gate activity, and conflict by layer.
✅ Implementation status
Numerically stable per-group smooth projection
PEFT-compatible parameter grouping
Domain and anchor gradient capture
Projected-gradient restoration and optimizer step
Structured per-step diagnostics and offline smoke test
Hugging Face tokenizer/model and local JSONL dataset wiring
QLoRA configuration, training loop, metrics, and adapter saving
GPU pilot execution and matched baseline smoke runs (results)
100-step controlled-conflict effectiveness run, seed 42 (results)
Natural-data 3-seed matched experiment (results)
Temperature × grouping generation screening (results)
Three-seed temperature confirmation (results)
Minimum-conflict threshold screening (results)
Three-seed threshold confirmation (results)
500-step, three-seed long-adaptation experiment (results)\n- [x] Phase 6 validation-controlled scaling and three-seed generation confirmation (results)\n- [x] Phase 7 statistical analysis, Pareto frontier, and seed-sensitivity visuals (results)\n- [x] Phase 8 research manuscript, research card, citation, and reproducibility release (paper, release)\n- [x] Persistent Hugging Face adapter publication (public model, results)
Plain LoRA, rehearsal, and hard-projection baseline engines
Offline multi-seed adaptation–retention evaluation CLI
📈 Evaluation
After recording before/after scores using the schema in
examples/evaluation_scores.json, build a machine-readable comparison report:🔁 Reproducible experiment matrix
Preview the fixed method-by-seed matrix without loading a model:
Remove
--dry-run on a CUDA machine to execute all four methods across seeds 42, 123, and 456. The runner checkpoints experiment-manifest.json after every state transition, allowing failed runs to be identified without losing completed-run metadata.Phase 4 analysis adds deterministic percentile-bootstrap confidence intervals, seed-matched differences against LoRA, automatic Pareto-front membership, and a dependency-free SVG scatter chart with forgetting on the x-axis and domain gain on the y-axis.
🔍 Per-example evaluation and leakage audit
Evaluation JSONL rows require
id, prompt, reference, and category. Run the frozen base model and each trained adapter separately so every prediction remains auditable:The output includes every prediction, normalized exact match, token F1, category aggregates, and example-level bootstrap 95% confidence intervals.
Audit overlap before running final experiments:
Generate a publication-ready Markdown table from evaluation outputs:
📝 Research release
The repository research package and public Hugging Face adapter publication are complete. The model card, PEFT adapter, tokenizer files, and evaluation results are openly available for reproducibility.
📚 References
Hu et al., LoRA, 2021.
Zhang et al., AdaLoRA, 2023.
Farajtabar et al., Orthogonal Gradient Descent, 2019.
Wright et al., SketchOGD, 2023.
Luo et al., Catastrophic Forgetting in LLMs, 2023.
Yang et al., Qwen3 Technical Report, 2025.
Meng et al., PiSSA, 2024.
📜 License
Apache-2.0. Model and dataset licenses remain governed by their providers.
Built for reproducible, honest, capability-preserving AI research.
Learn what matters. Protect what the model already knows. Measure everything.
Like this project
Posted Oct 21, 2026
Developed CGAF-Tune framework for adaptive fine-tuning of large language models.
Likes
0
Views
0