
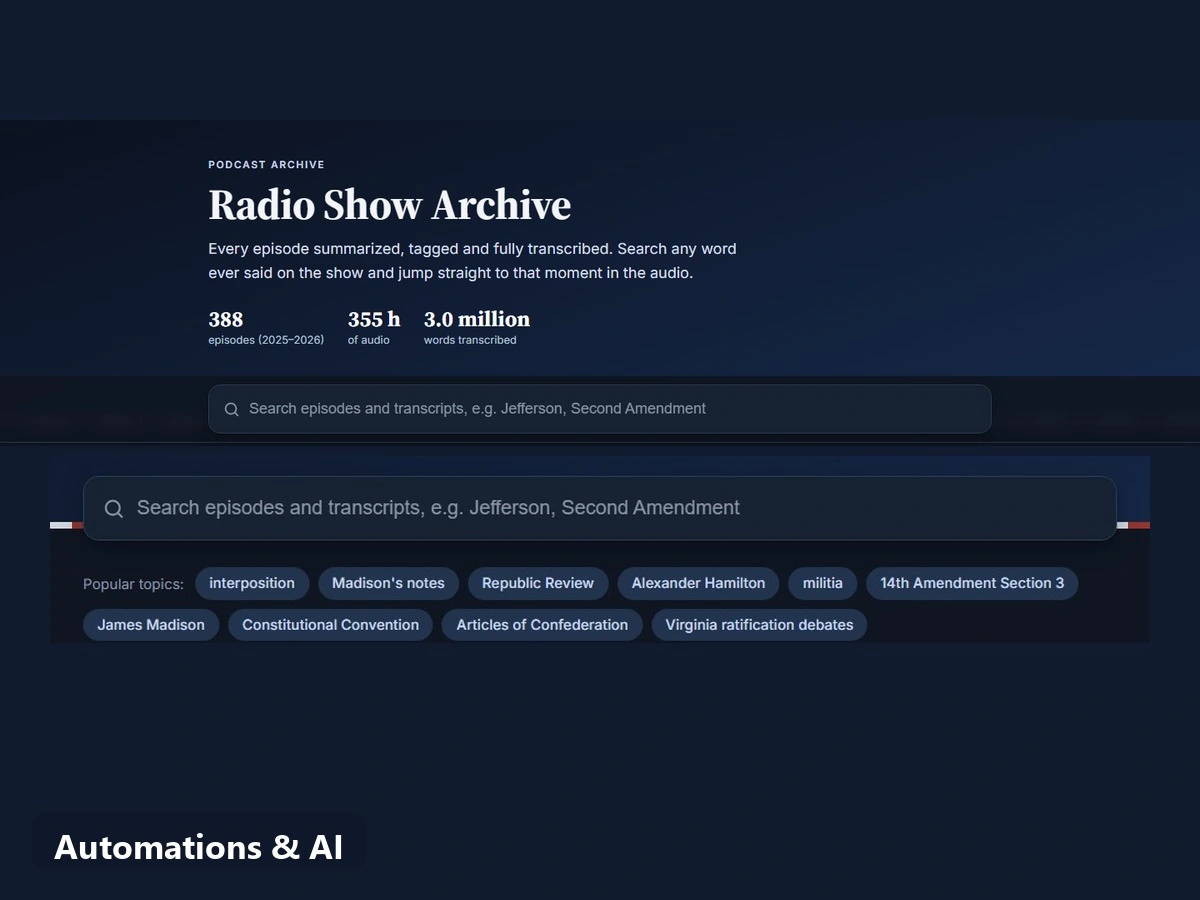
A client in the US wanted every episode of a radio show from 2025 and 2026 to be searchable by any word, independent of the broadcaster's website.
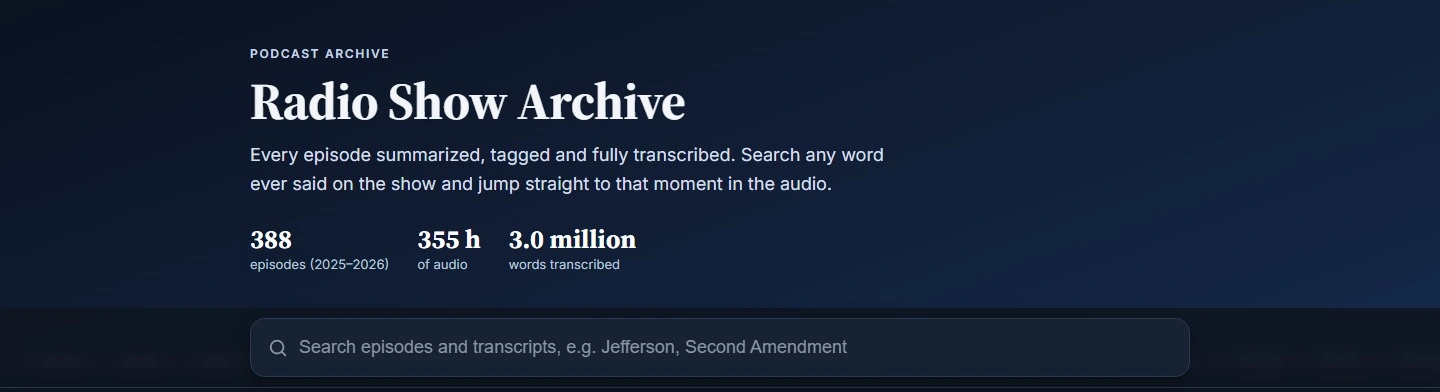
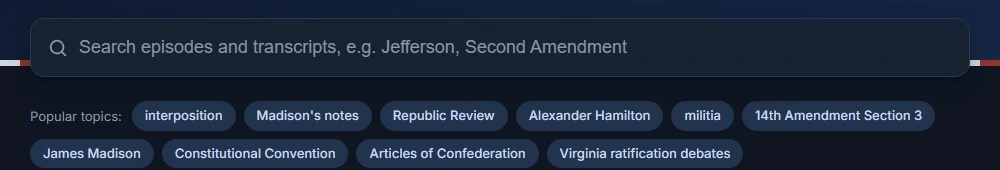
What I built: a Python transcription pipeline (Whisper large-v3, faster-whisper, FFmpeg) that ran in parallel and saved progress after every recording, a second pass that filled gaps and removed invented sentences, and a static site that searches about 3 million words and plays the audio from the exact moment a word was said.
Result: 388 episodes and 355 hours of audio summarised, tagged and searchable, delivered with TXT, SRT and JSON transcripts and an episode database ready to import into WordPress.
My role: the full pipeline and the website, from audio processing to the search interface.
0 likes · 0 views · Nov 19, 2026
Python and Whisper pipeline plus a search site for a US client: 388 radio episodes, 355 hours of audio, about 3 million searchable words.
