
SLM vs LLM for startups
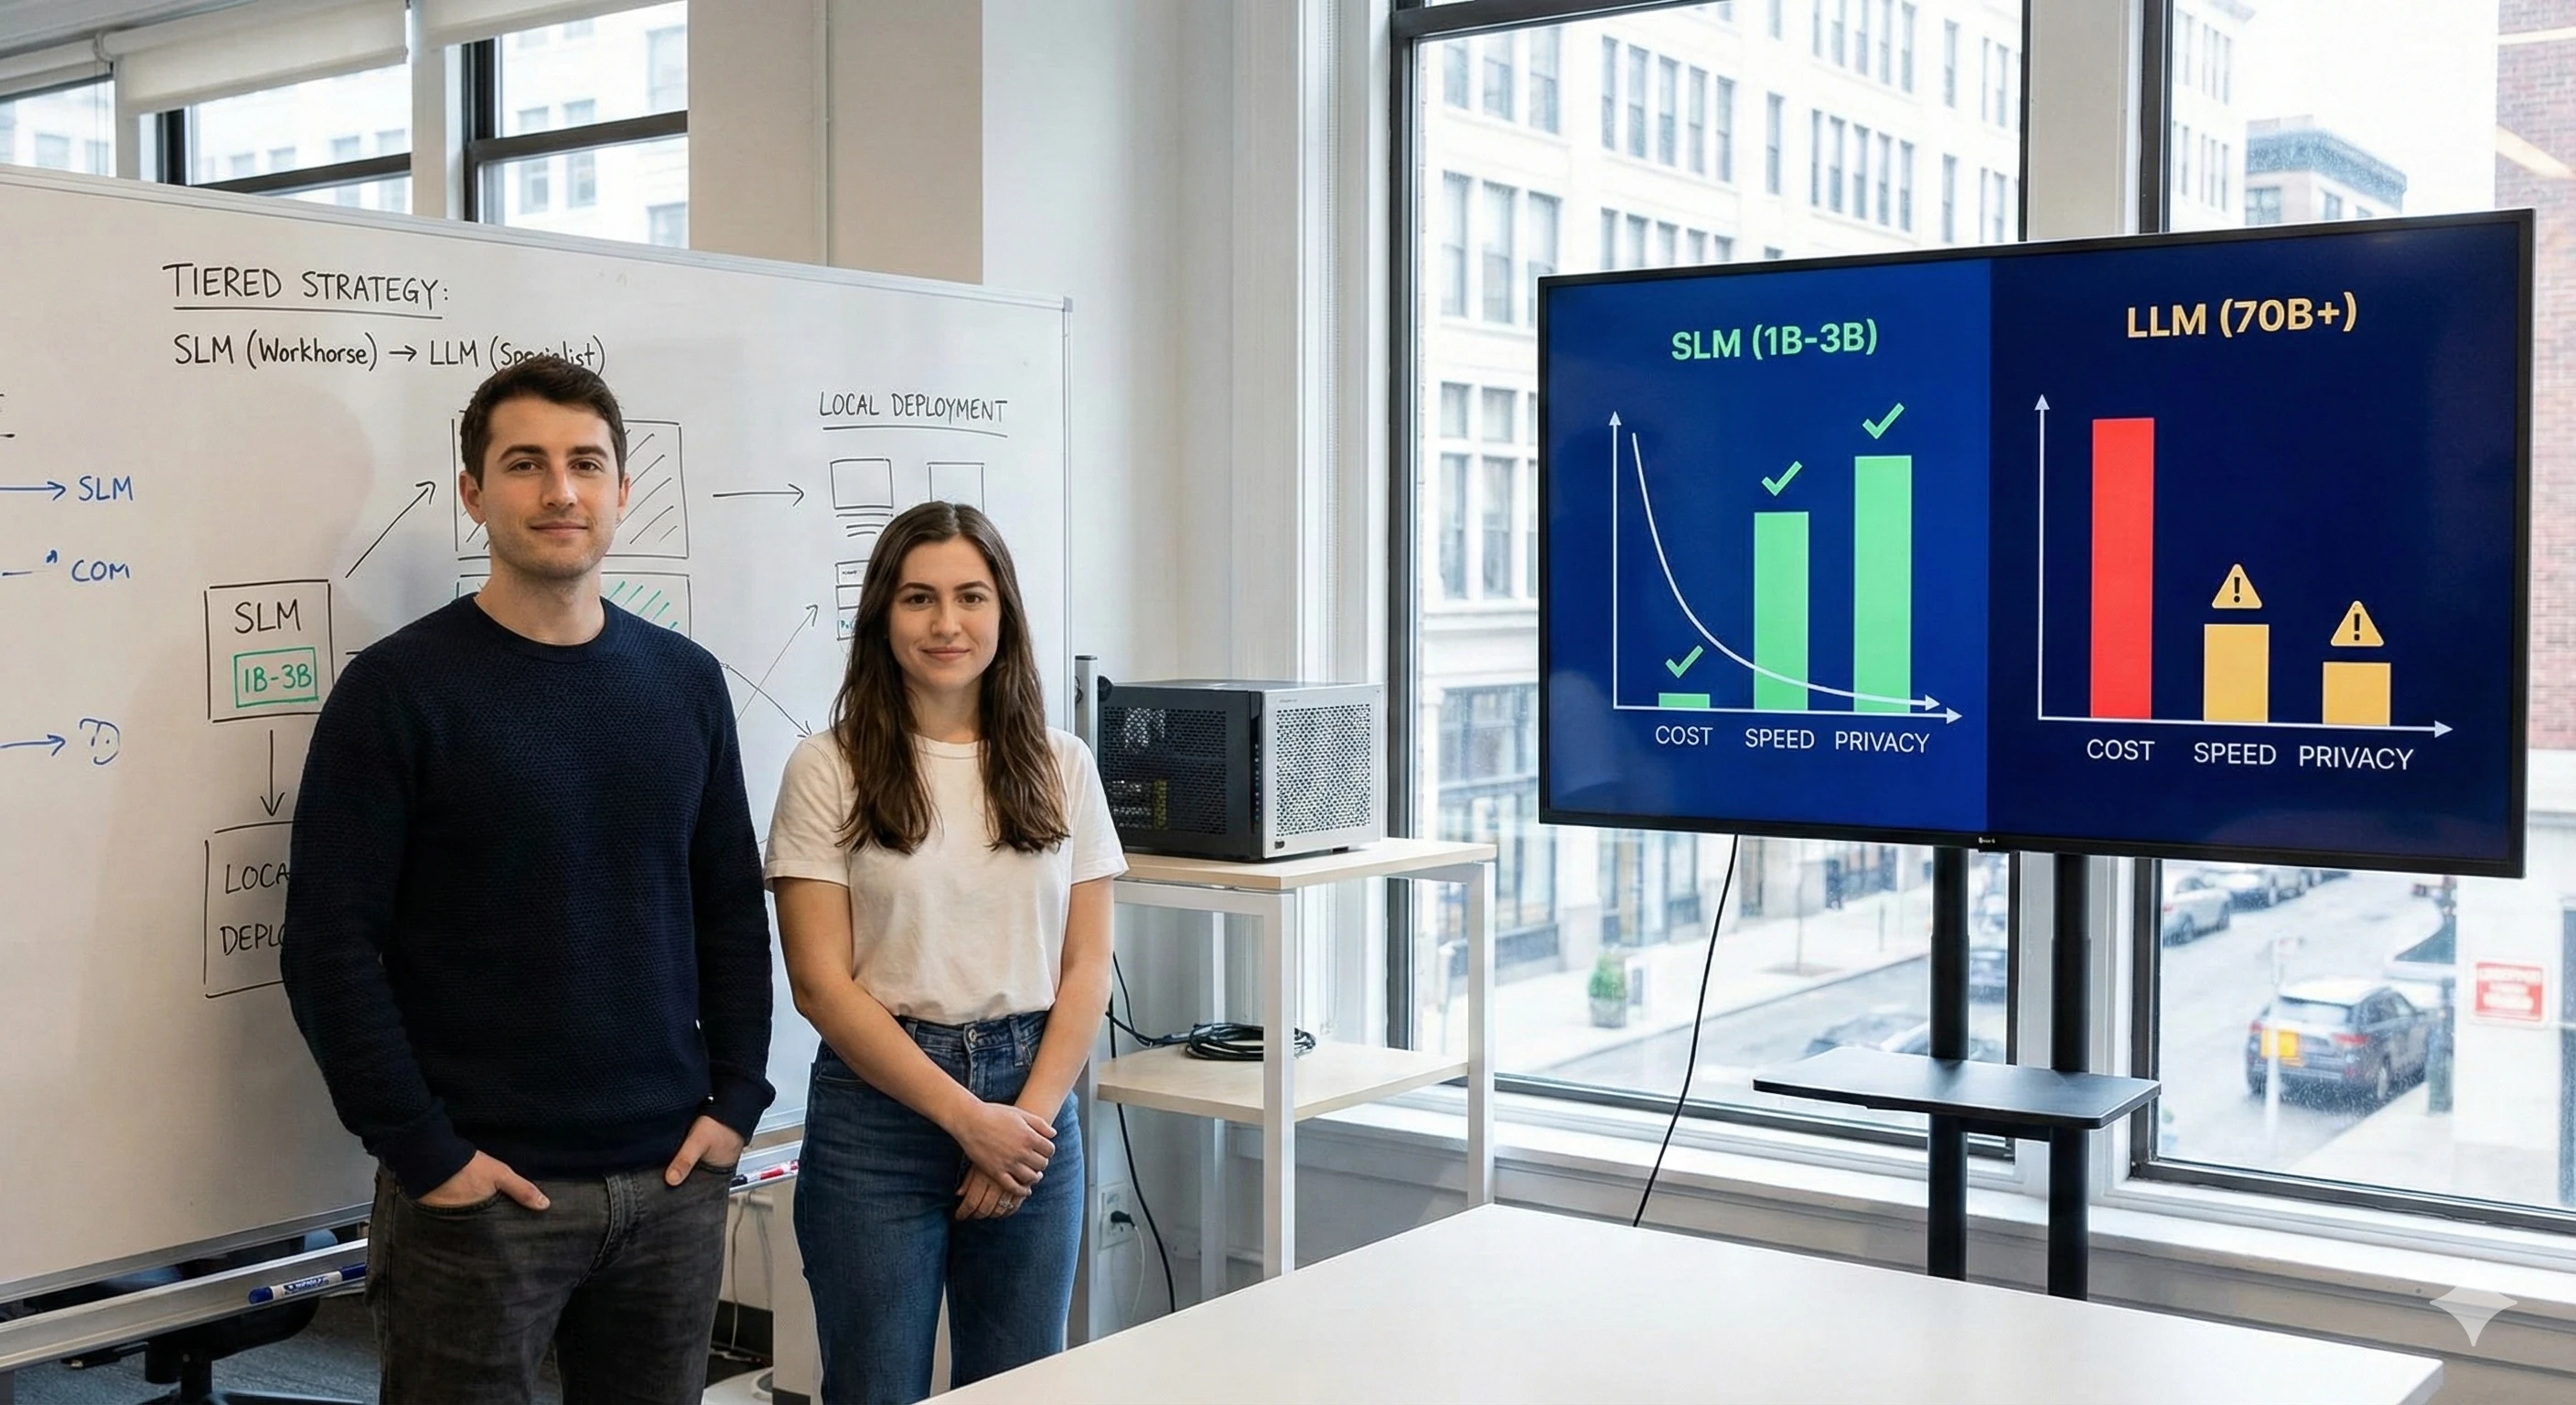
SLMs (1B–3B parameters) are becoming a kind of cheat code for startups: they can be run with a single GPU or even a powerful CPU, data can remain on your own infrastructure, and you still get almost LLM quality for very targeted tasks like support bots, internal search, or document workflows. In numerous benchmarks, contemporary SLMs are only a few F1 points behind bigger models while being up to 10–300x cheaper per request to serve.
Huge language models (between 50 billion and 70 billion+ parameters) are still the preferred option when we talk about complex multi-step reasoning, long contexts, and highly open-ended generation. Nevertheless, the vast majority of startup scenarios do not need such models for every single request.
0 likes · 0 views · Dec 12, 2025
SLM vs LLM for startups SLMs (1B–3B parameters) are becoming a kind of cheat code for startups: they can be run with a singl...
