Enterprise Document Intelligence: RAG over Thousands of Files

Muzakir uddin Hashmi


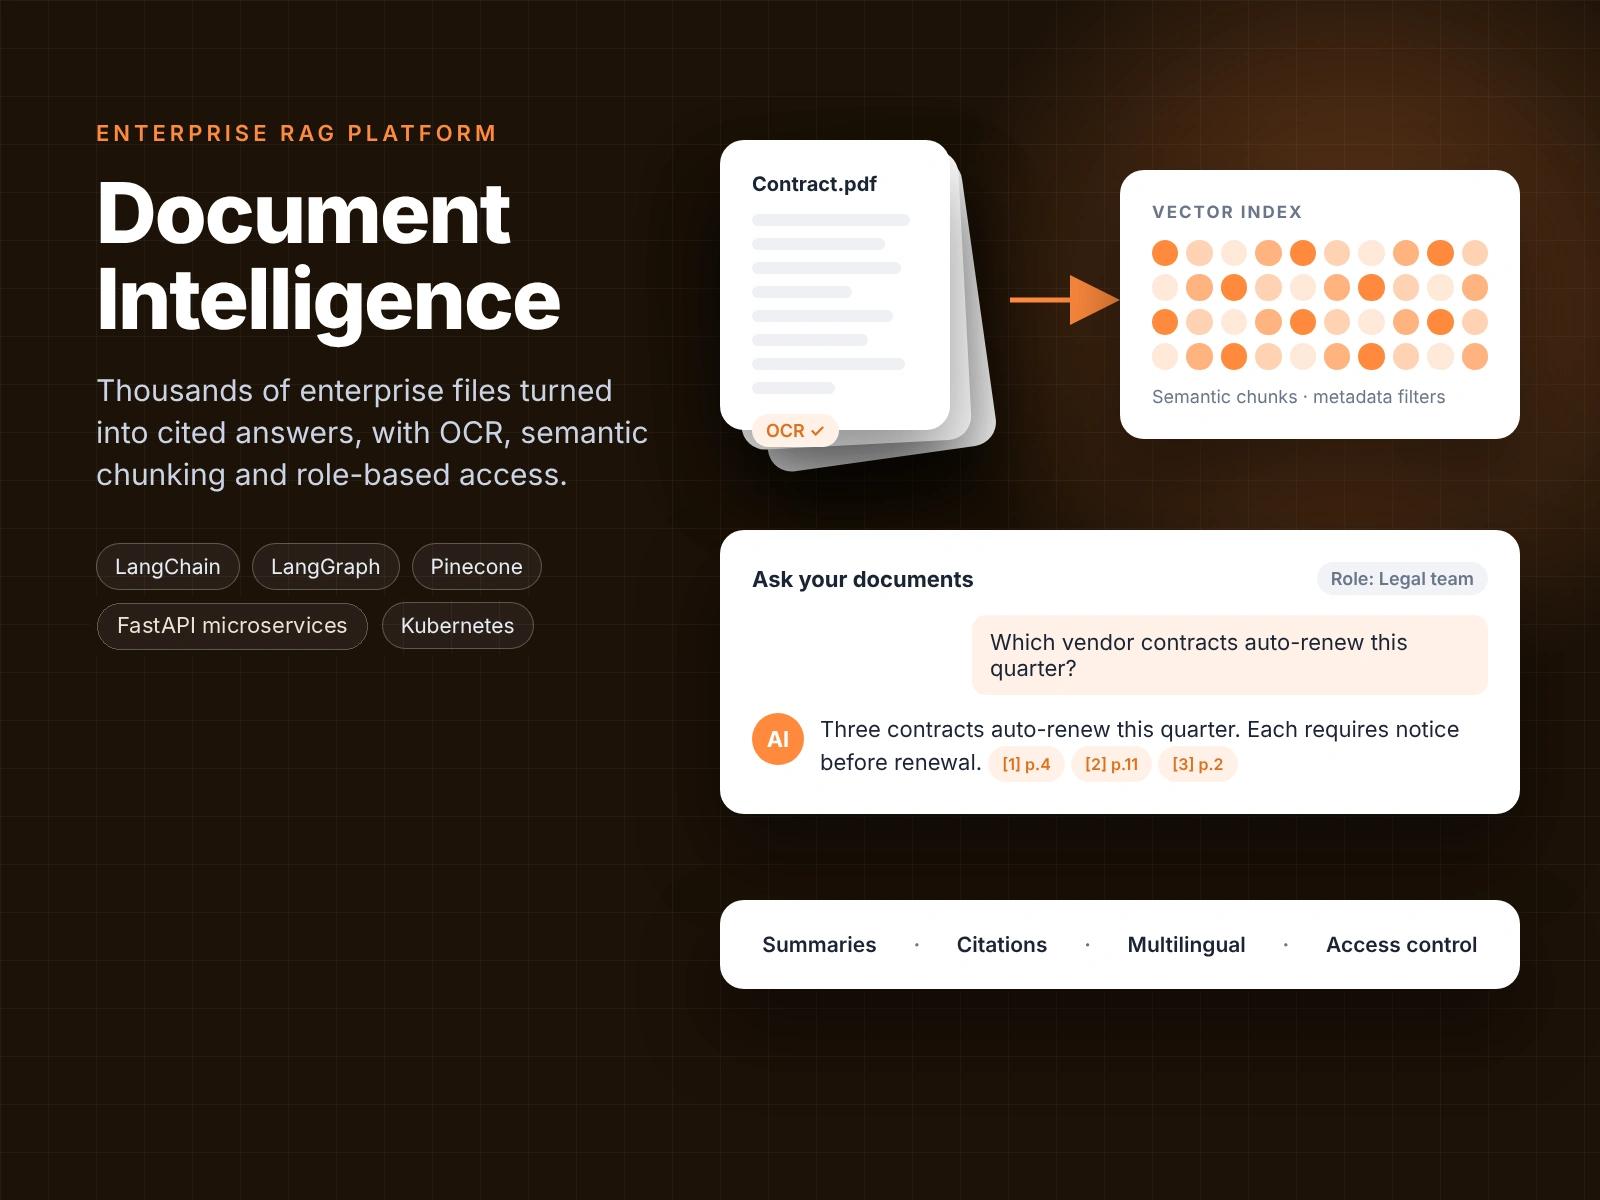
This project involved building an enterprise document intelligence platform for teams that lost hours searching large document sets.
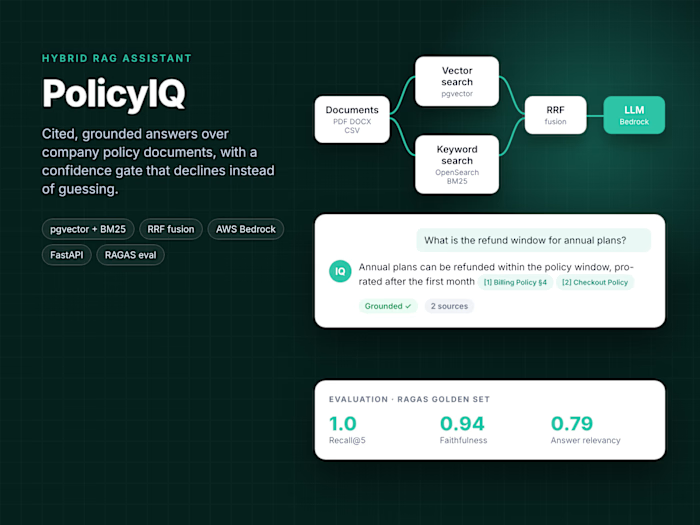
The platform answers user questions with cited, context-aware responses, powered by a Retrieval Augmented Generation (RAG) pipeline.
The pipeline includes PDF ingestion with OCR, semantic chunking, embeddings and Pinecone vector search, orchestrated with LangChain and LangGraph.
The backend runs as FastAPI microservices with Redis queues for background processing, deployed on AWS with Docker and Kubernetes for scalability and reliable deployments.
The React chat interface adds role-based access, metadata filtering, summarization and multilingual answers.
The final platform ingests thousands of files in production, giving teams fast, trustworthy answers from their own documents.
Like this project
Posted Oct 26, 2026