
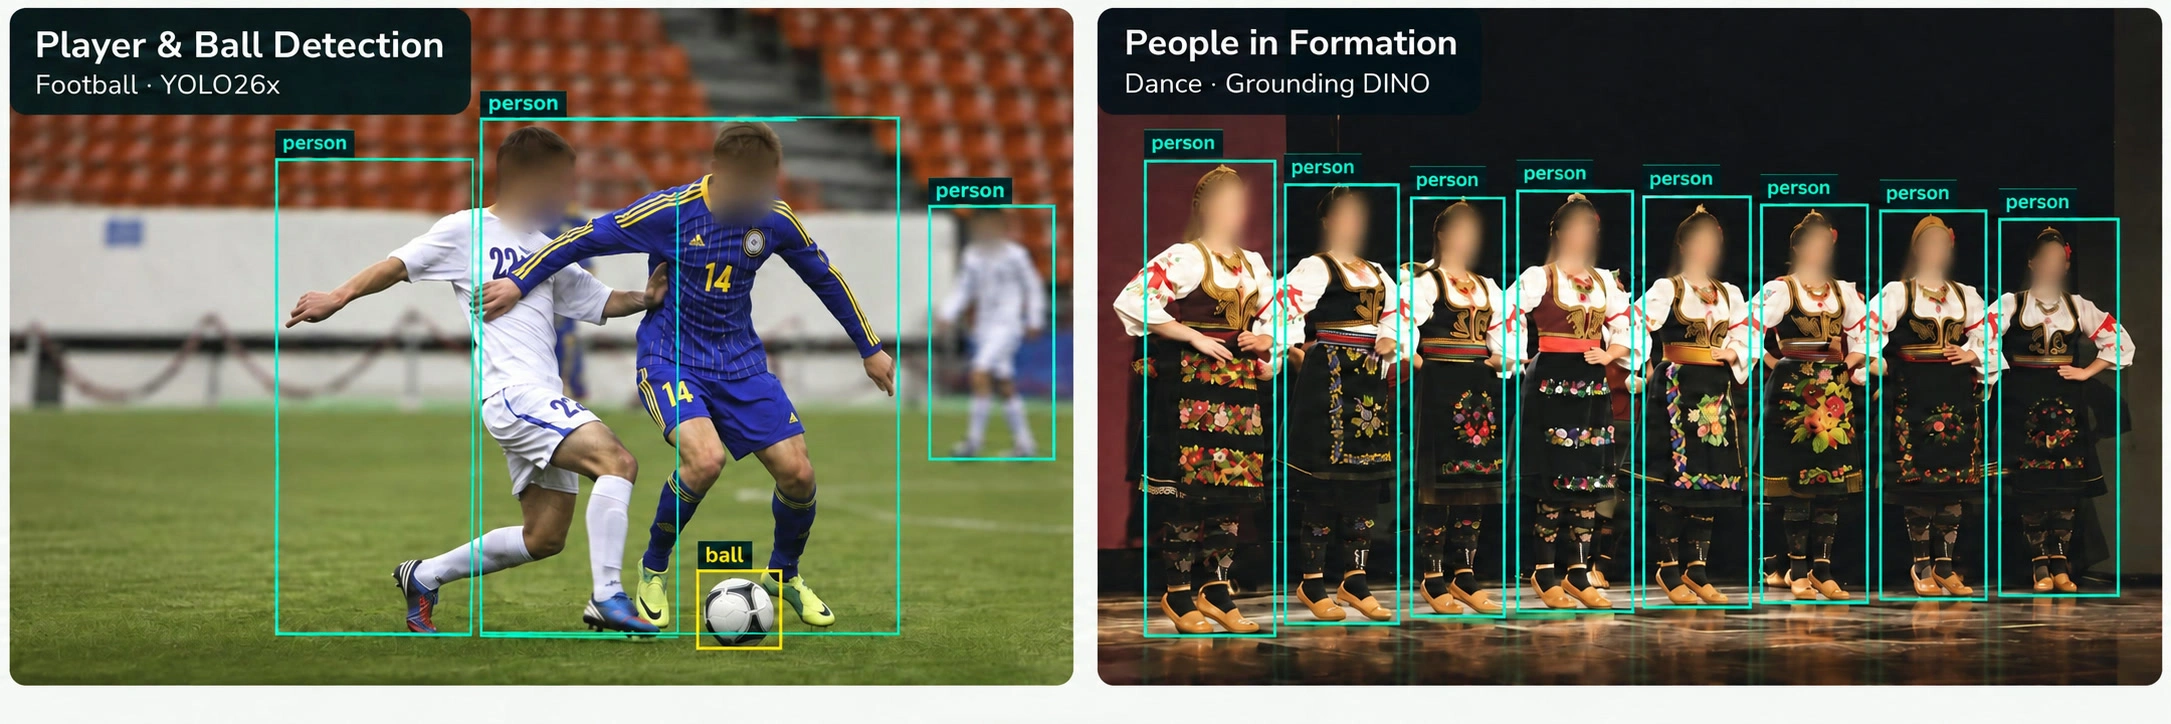
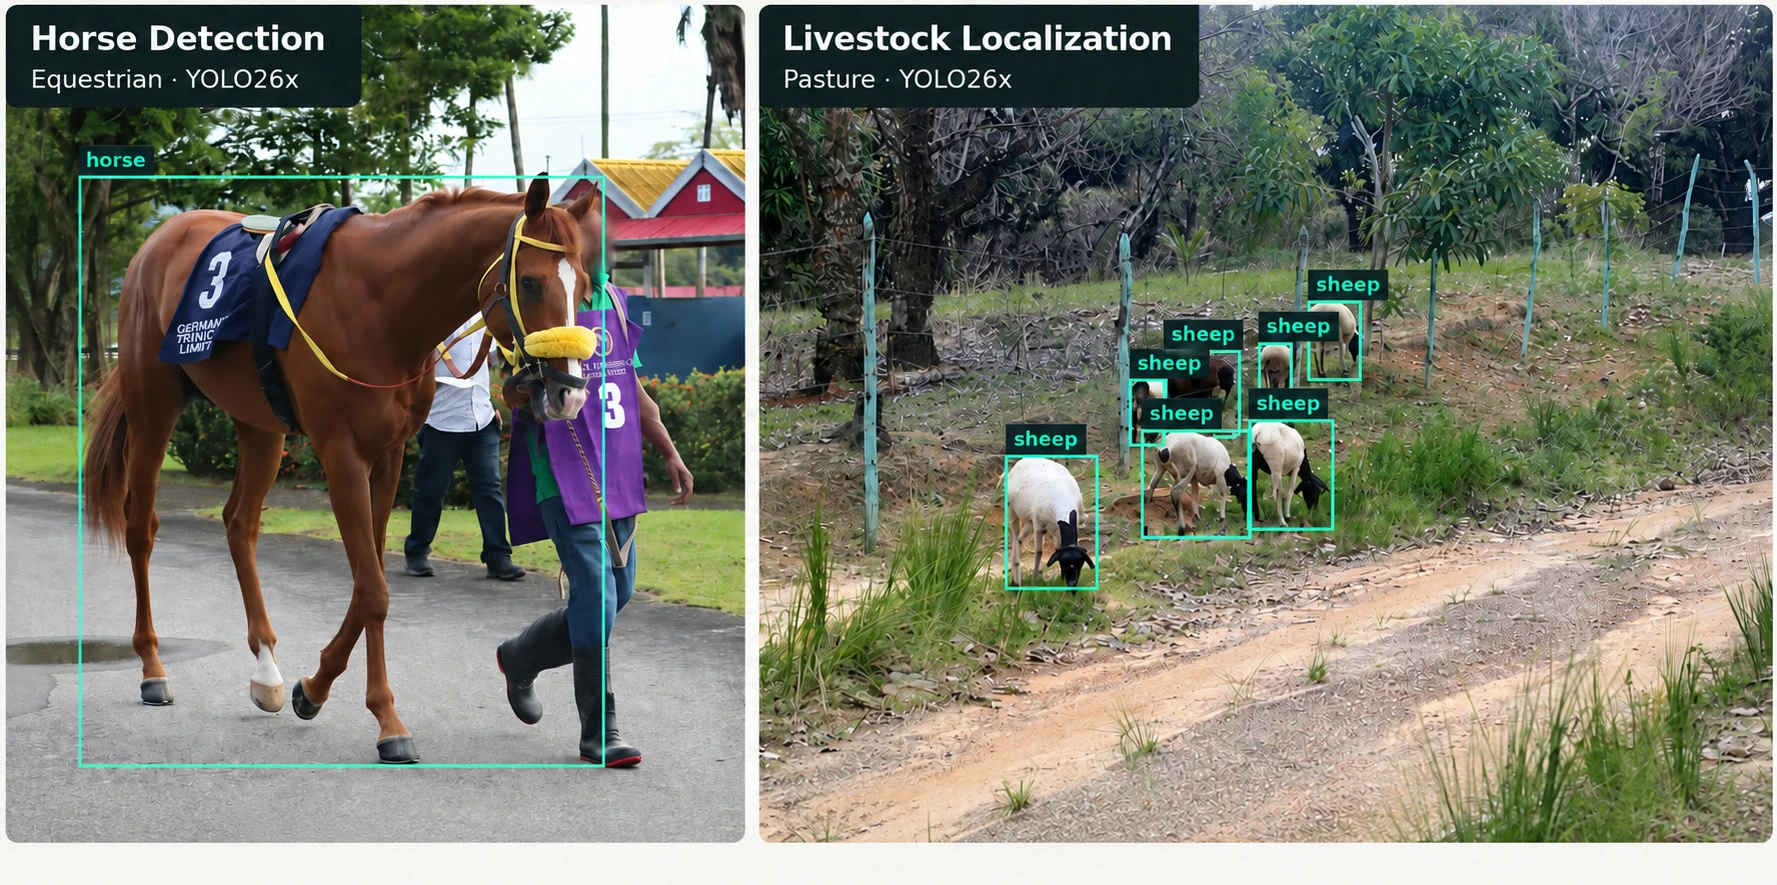
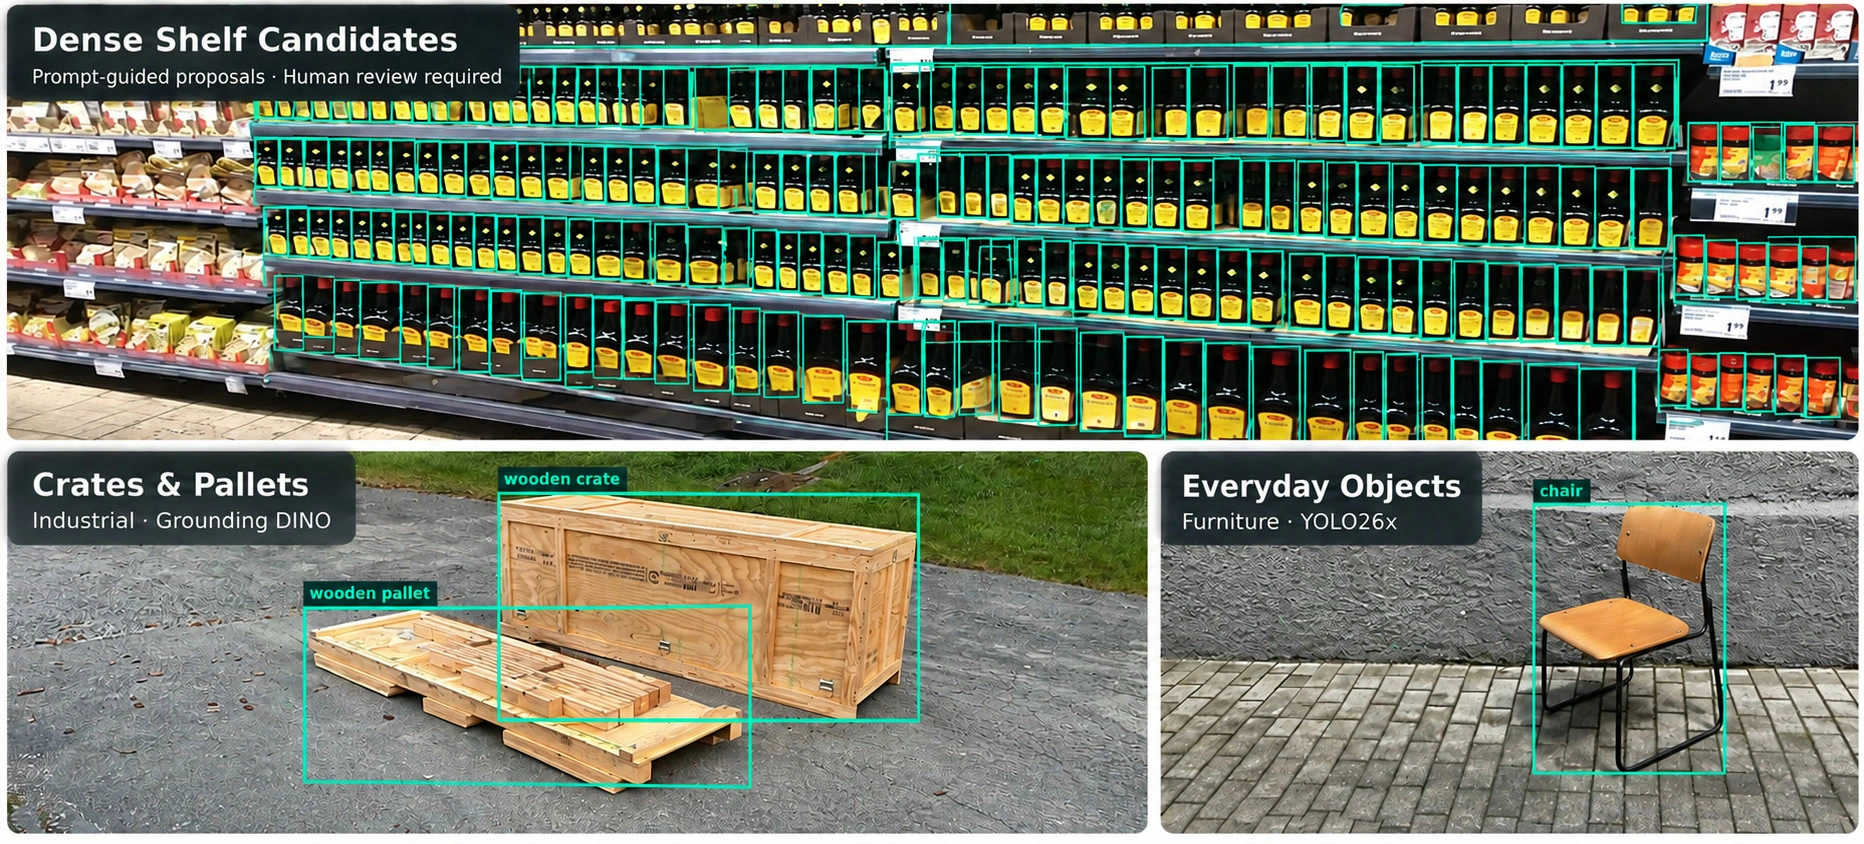
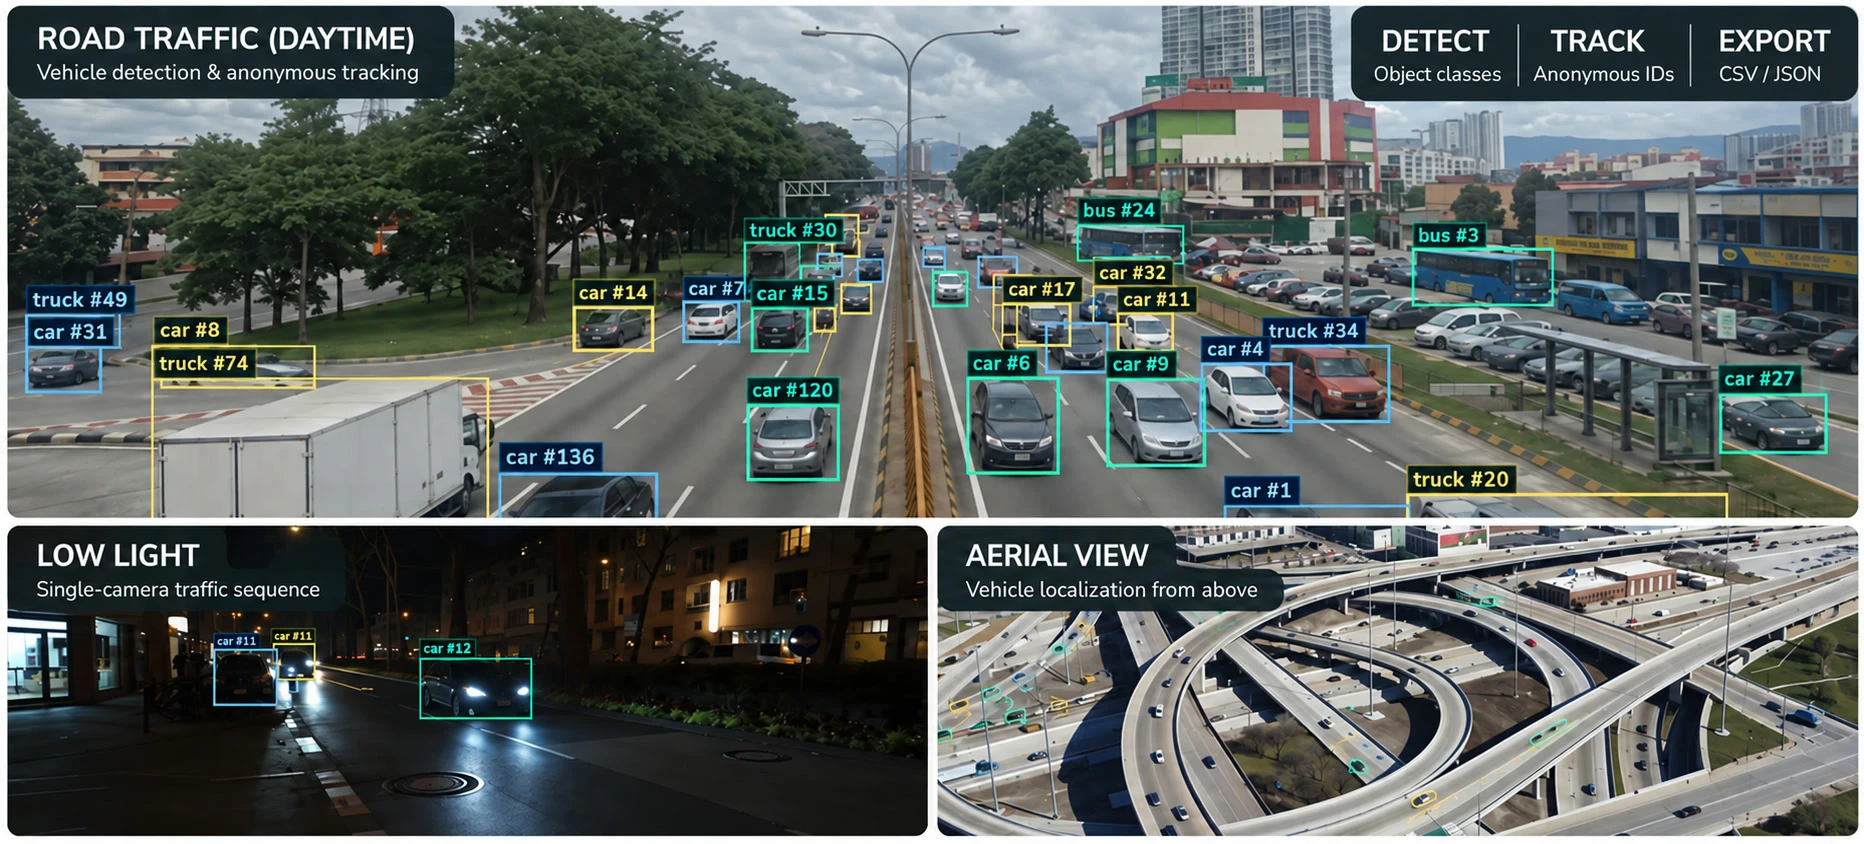
Motivation & Challenge: Turn varied images and videos into usable object and motion data. Detection runs on YOLO across 10 representative scene categories, with BoT-SORT tracking keeping IDs stable through occlusions; open-vocabulary detectors cover object types outside the fixed label set, and prompts and outputs were adapted to each use case.
Results & Deliverables: Robustly annotated 2,078 traffic videos across 10 scene categories with anonymous IDs, domain-specific detection examples, and timestamped CSV/JSON exports.
1 like · 2 views · Sep 16, 2026
Motivation & Challenge: Turn varied images and videos into usable object and motion data.

