F1 RAG Chatbot: Formula 1 answers from race data, shipped to AWS

Aswin Shine


A Formula 1 chatbot that answers from race data back to 1950 and searches the web when it runs thin. RAG on Pinecone, GPT-4.1-mini, Docker and EC2.
A race-engineer chatbot, from the data to the server.
F1 RAG Chatbot answers Formula 1 questions in the voice of a race engineer. It retrieves from nine files of race data covering 1950 to 2025, falls back to a web search when retrieval comes back thin, and writes the answer with GPT-4.1-mini. I built the app, the retrieval pipeline, the Docker image and the pipeline that deploys it to AWS EC2.
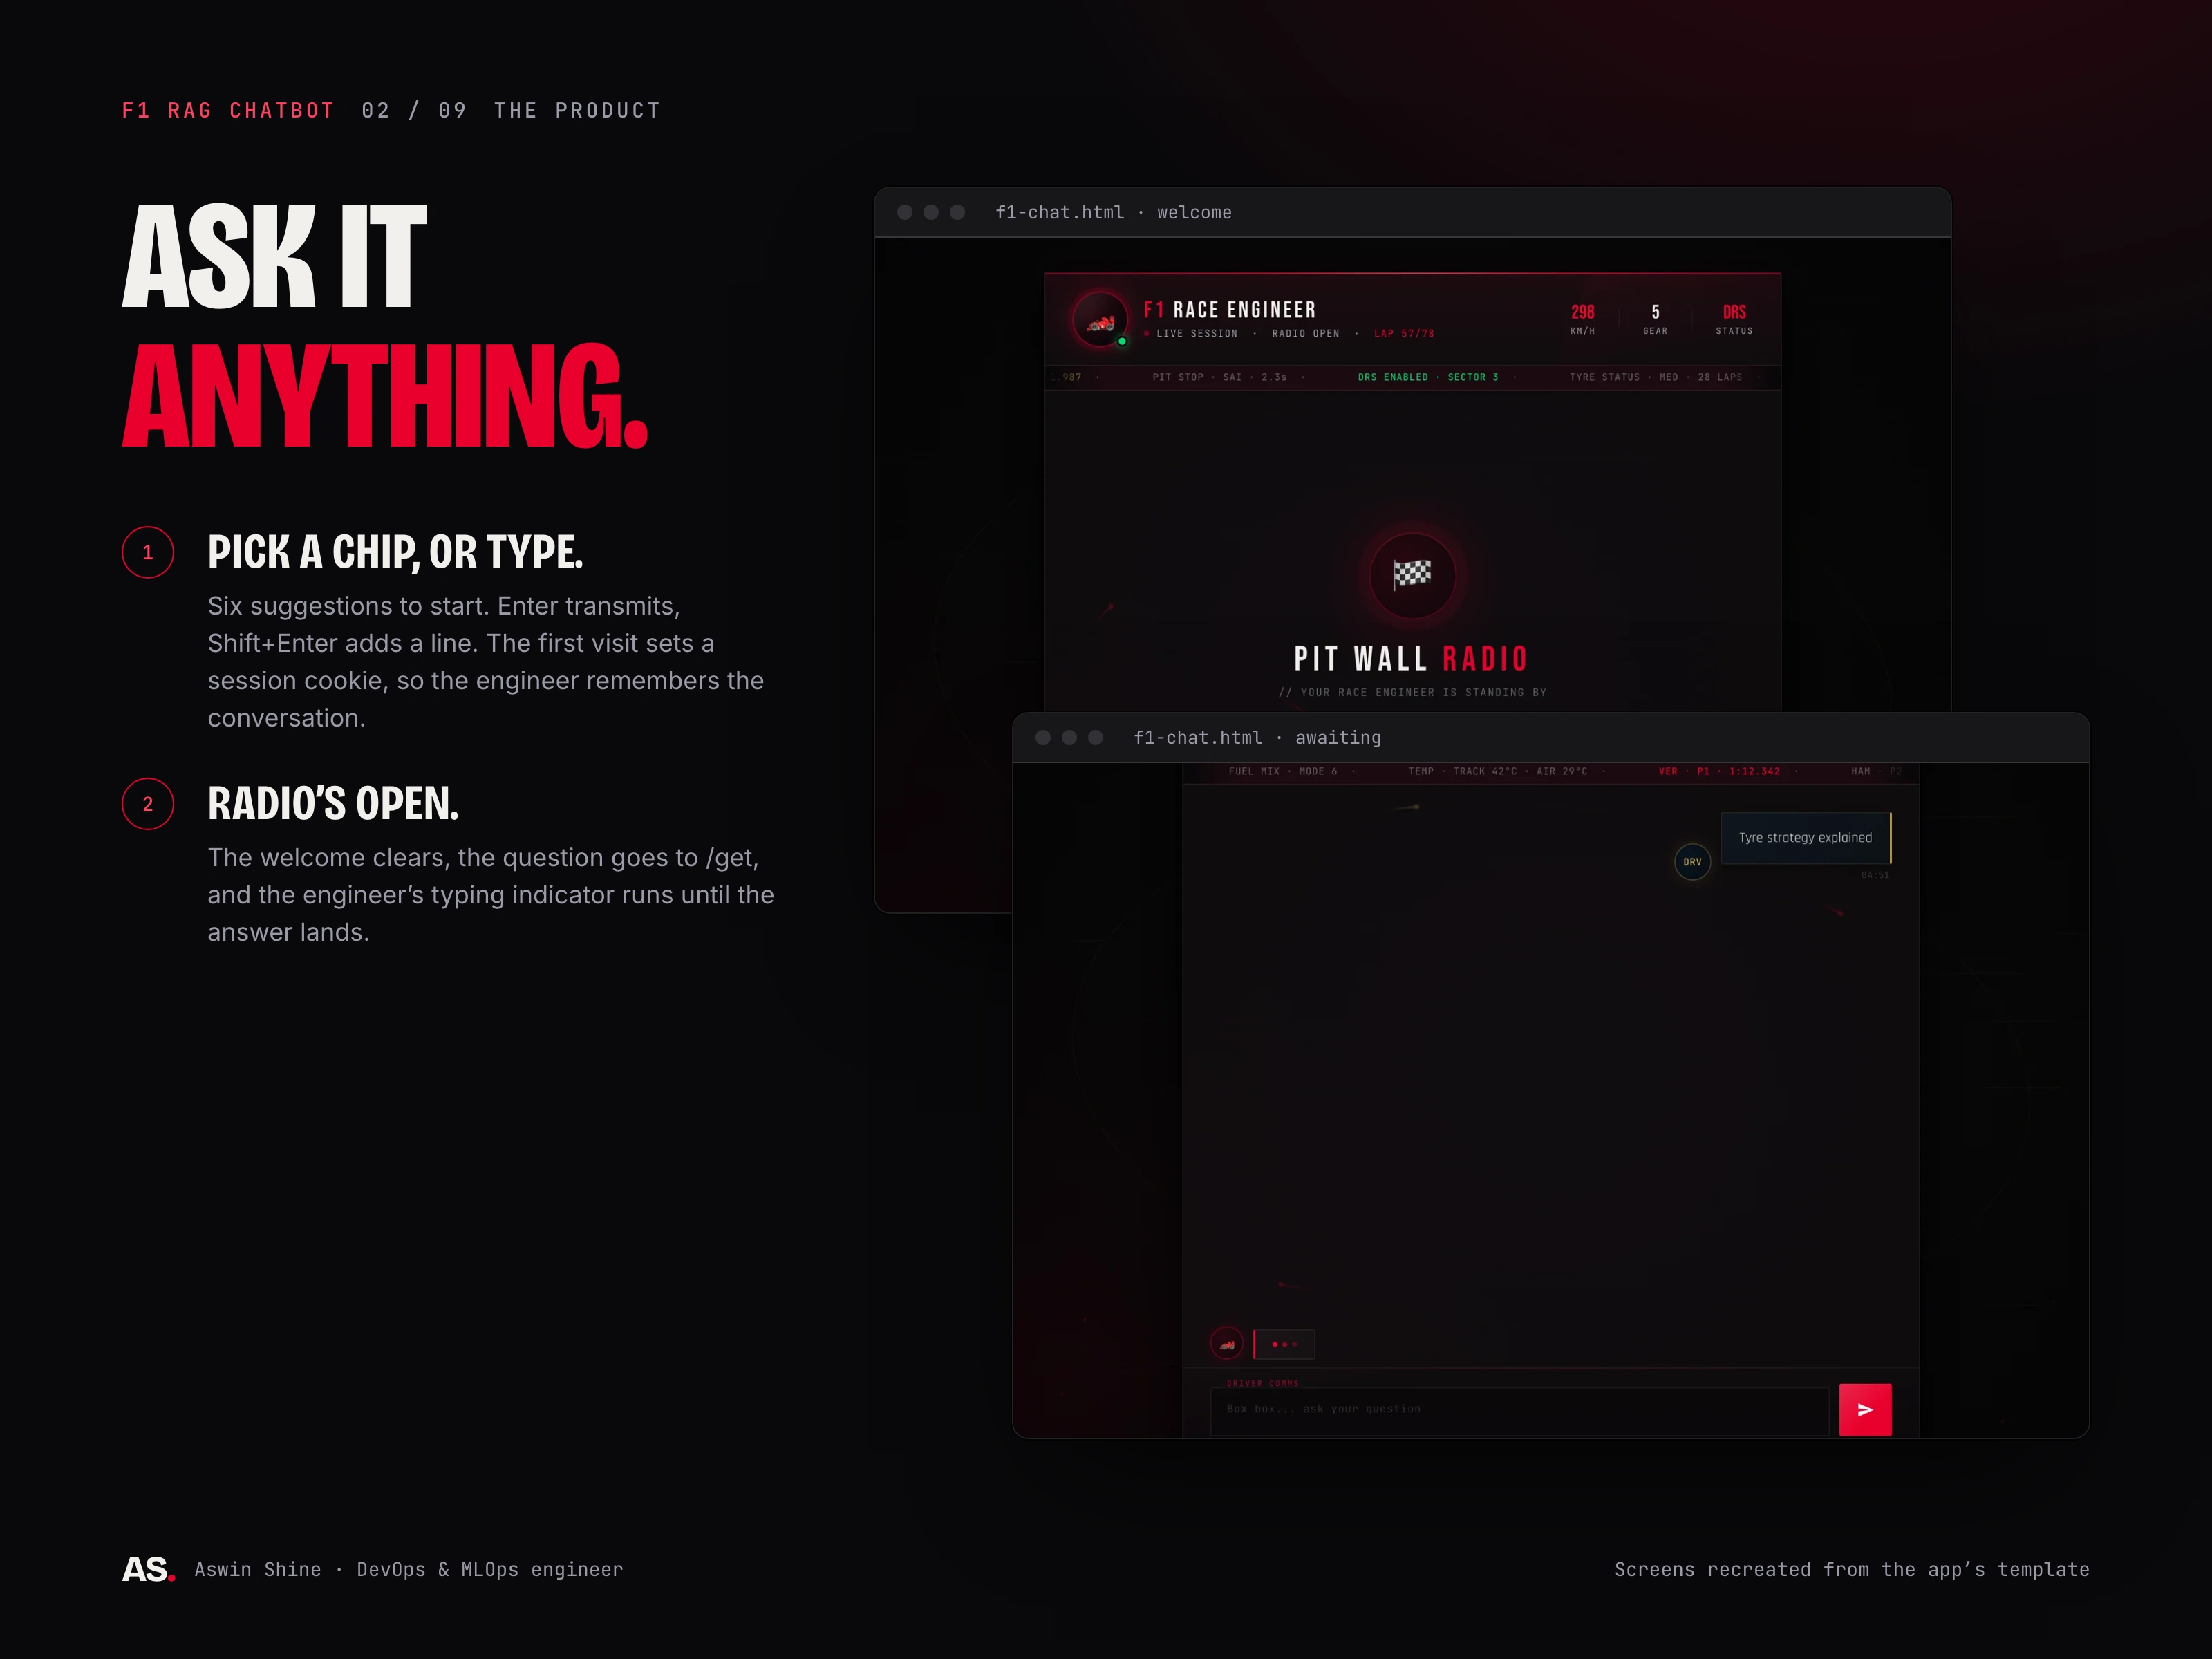
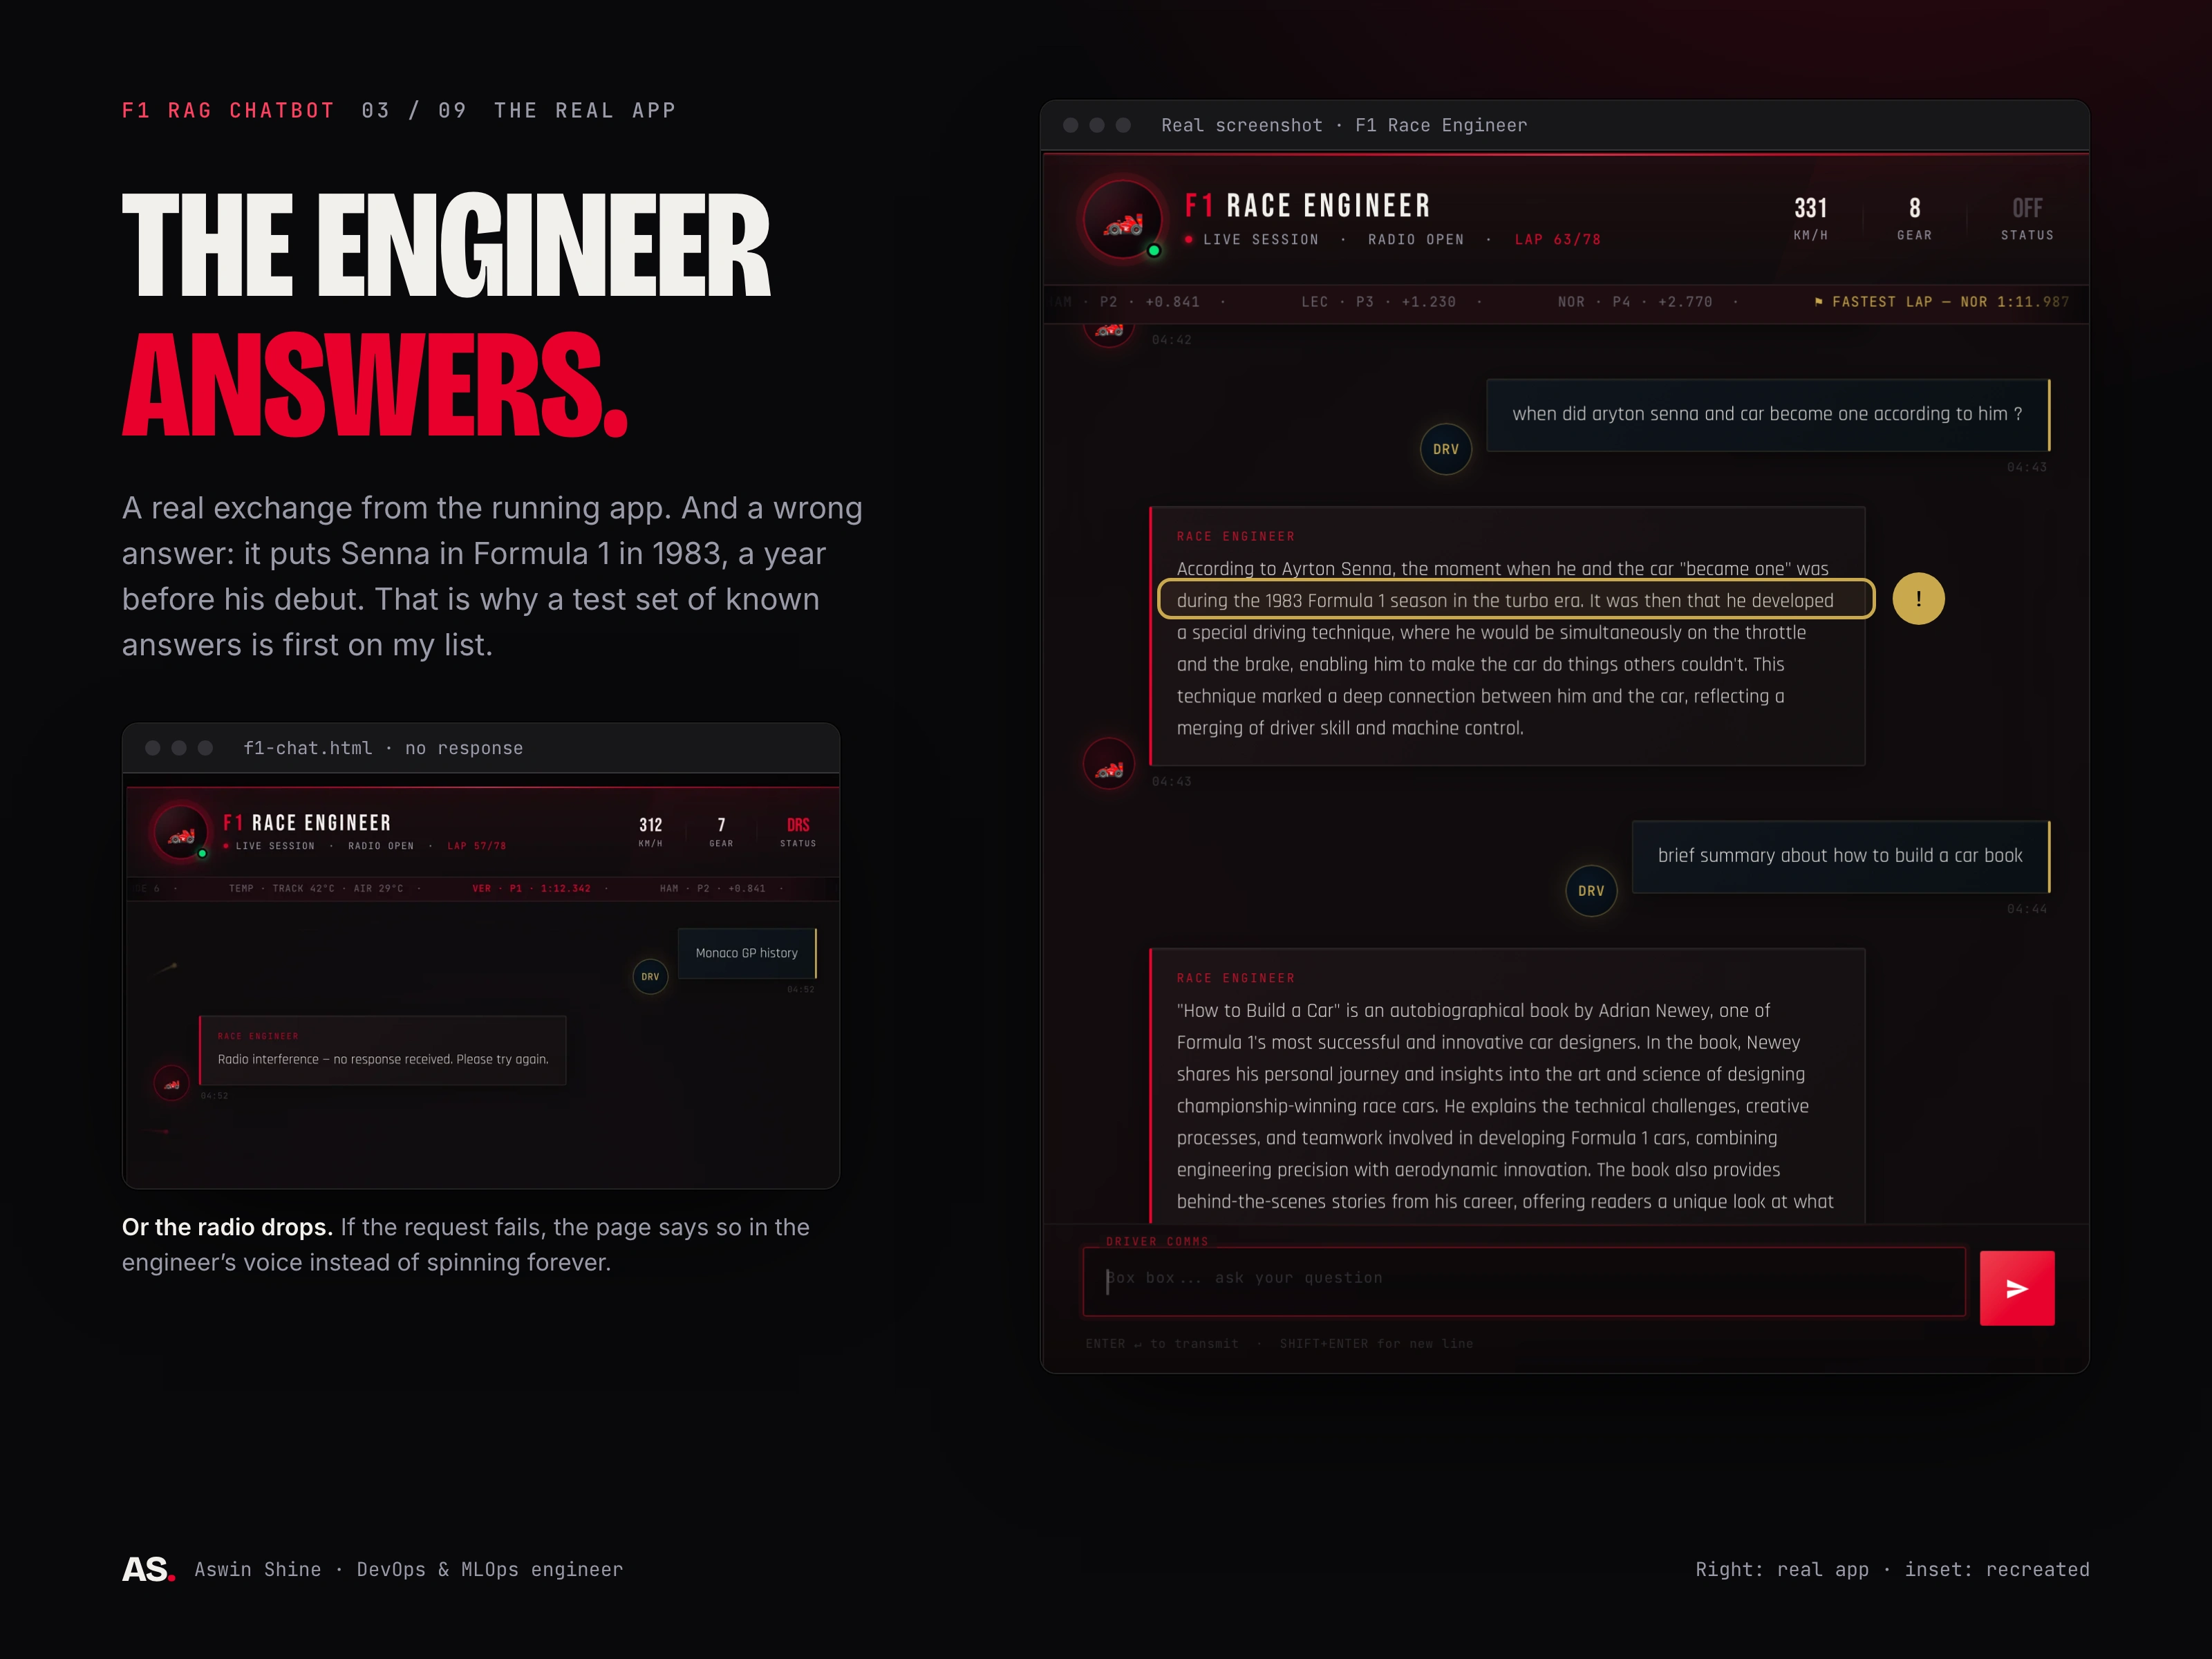
The product.
Pick one of six suggestion chips or type a question. The first visit sets a session cookie, so the engineer remembers the conversation. If a request fails, the page says so in the engineer's voice instead of spinning forever. One real answer is wrong (it puts Senna in Formula 1 in 1983, a year before his debut), and I show it on purpose: it is why a test set of known answers is first on my list.
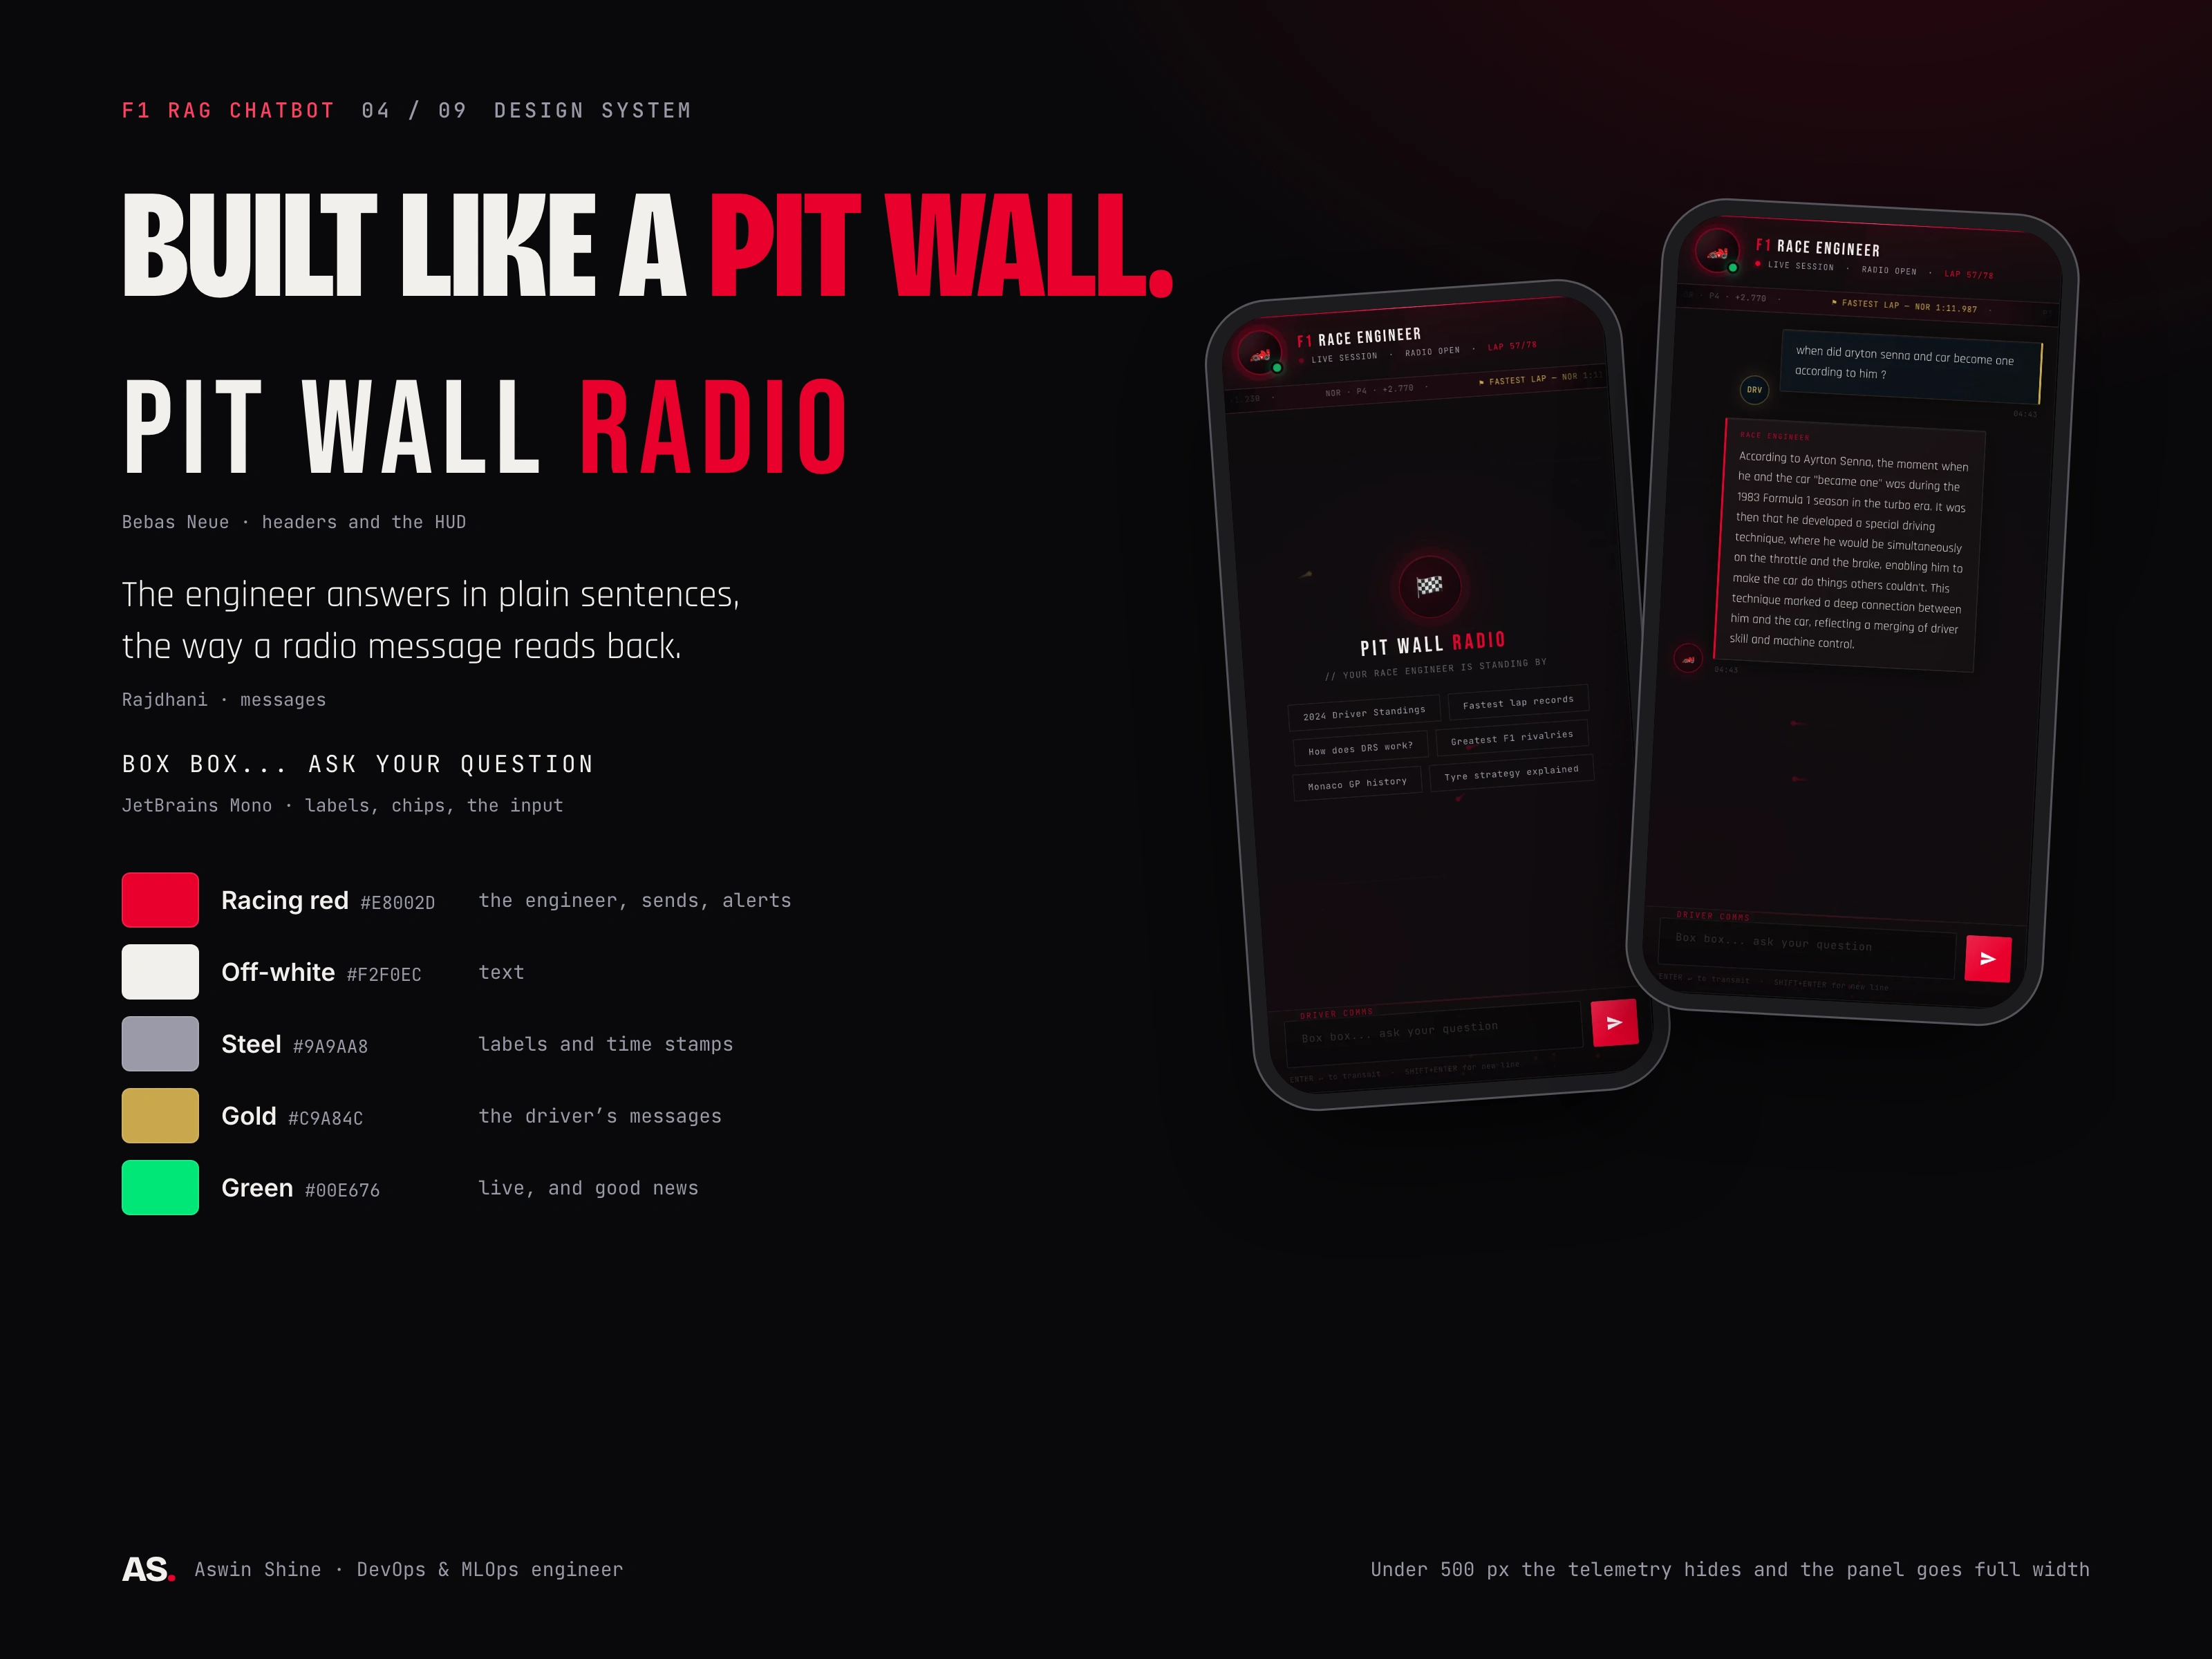
Built like a pit wall.
Bebas Neue for the HUD, Rajdhani for messages, JetBrains Mono for labels, five colours. Under 500 pixels the telemetry hides and the panel goes full width.
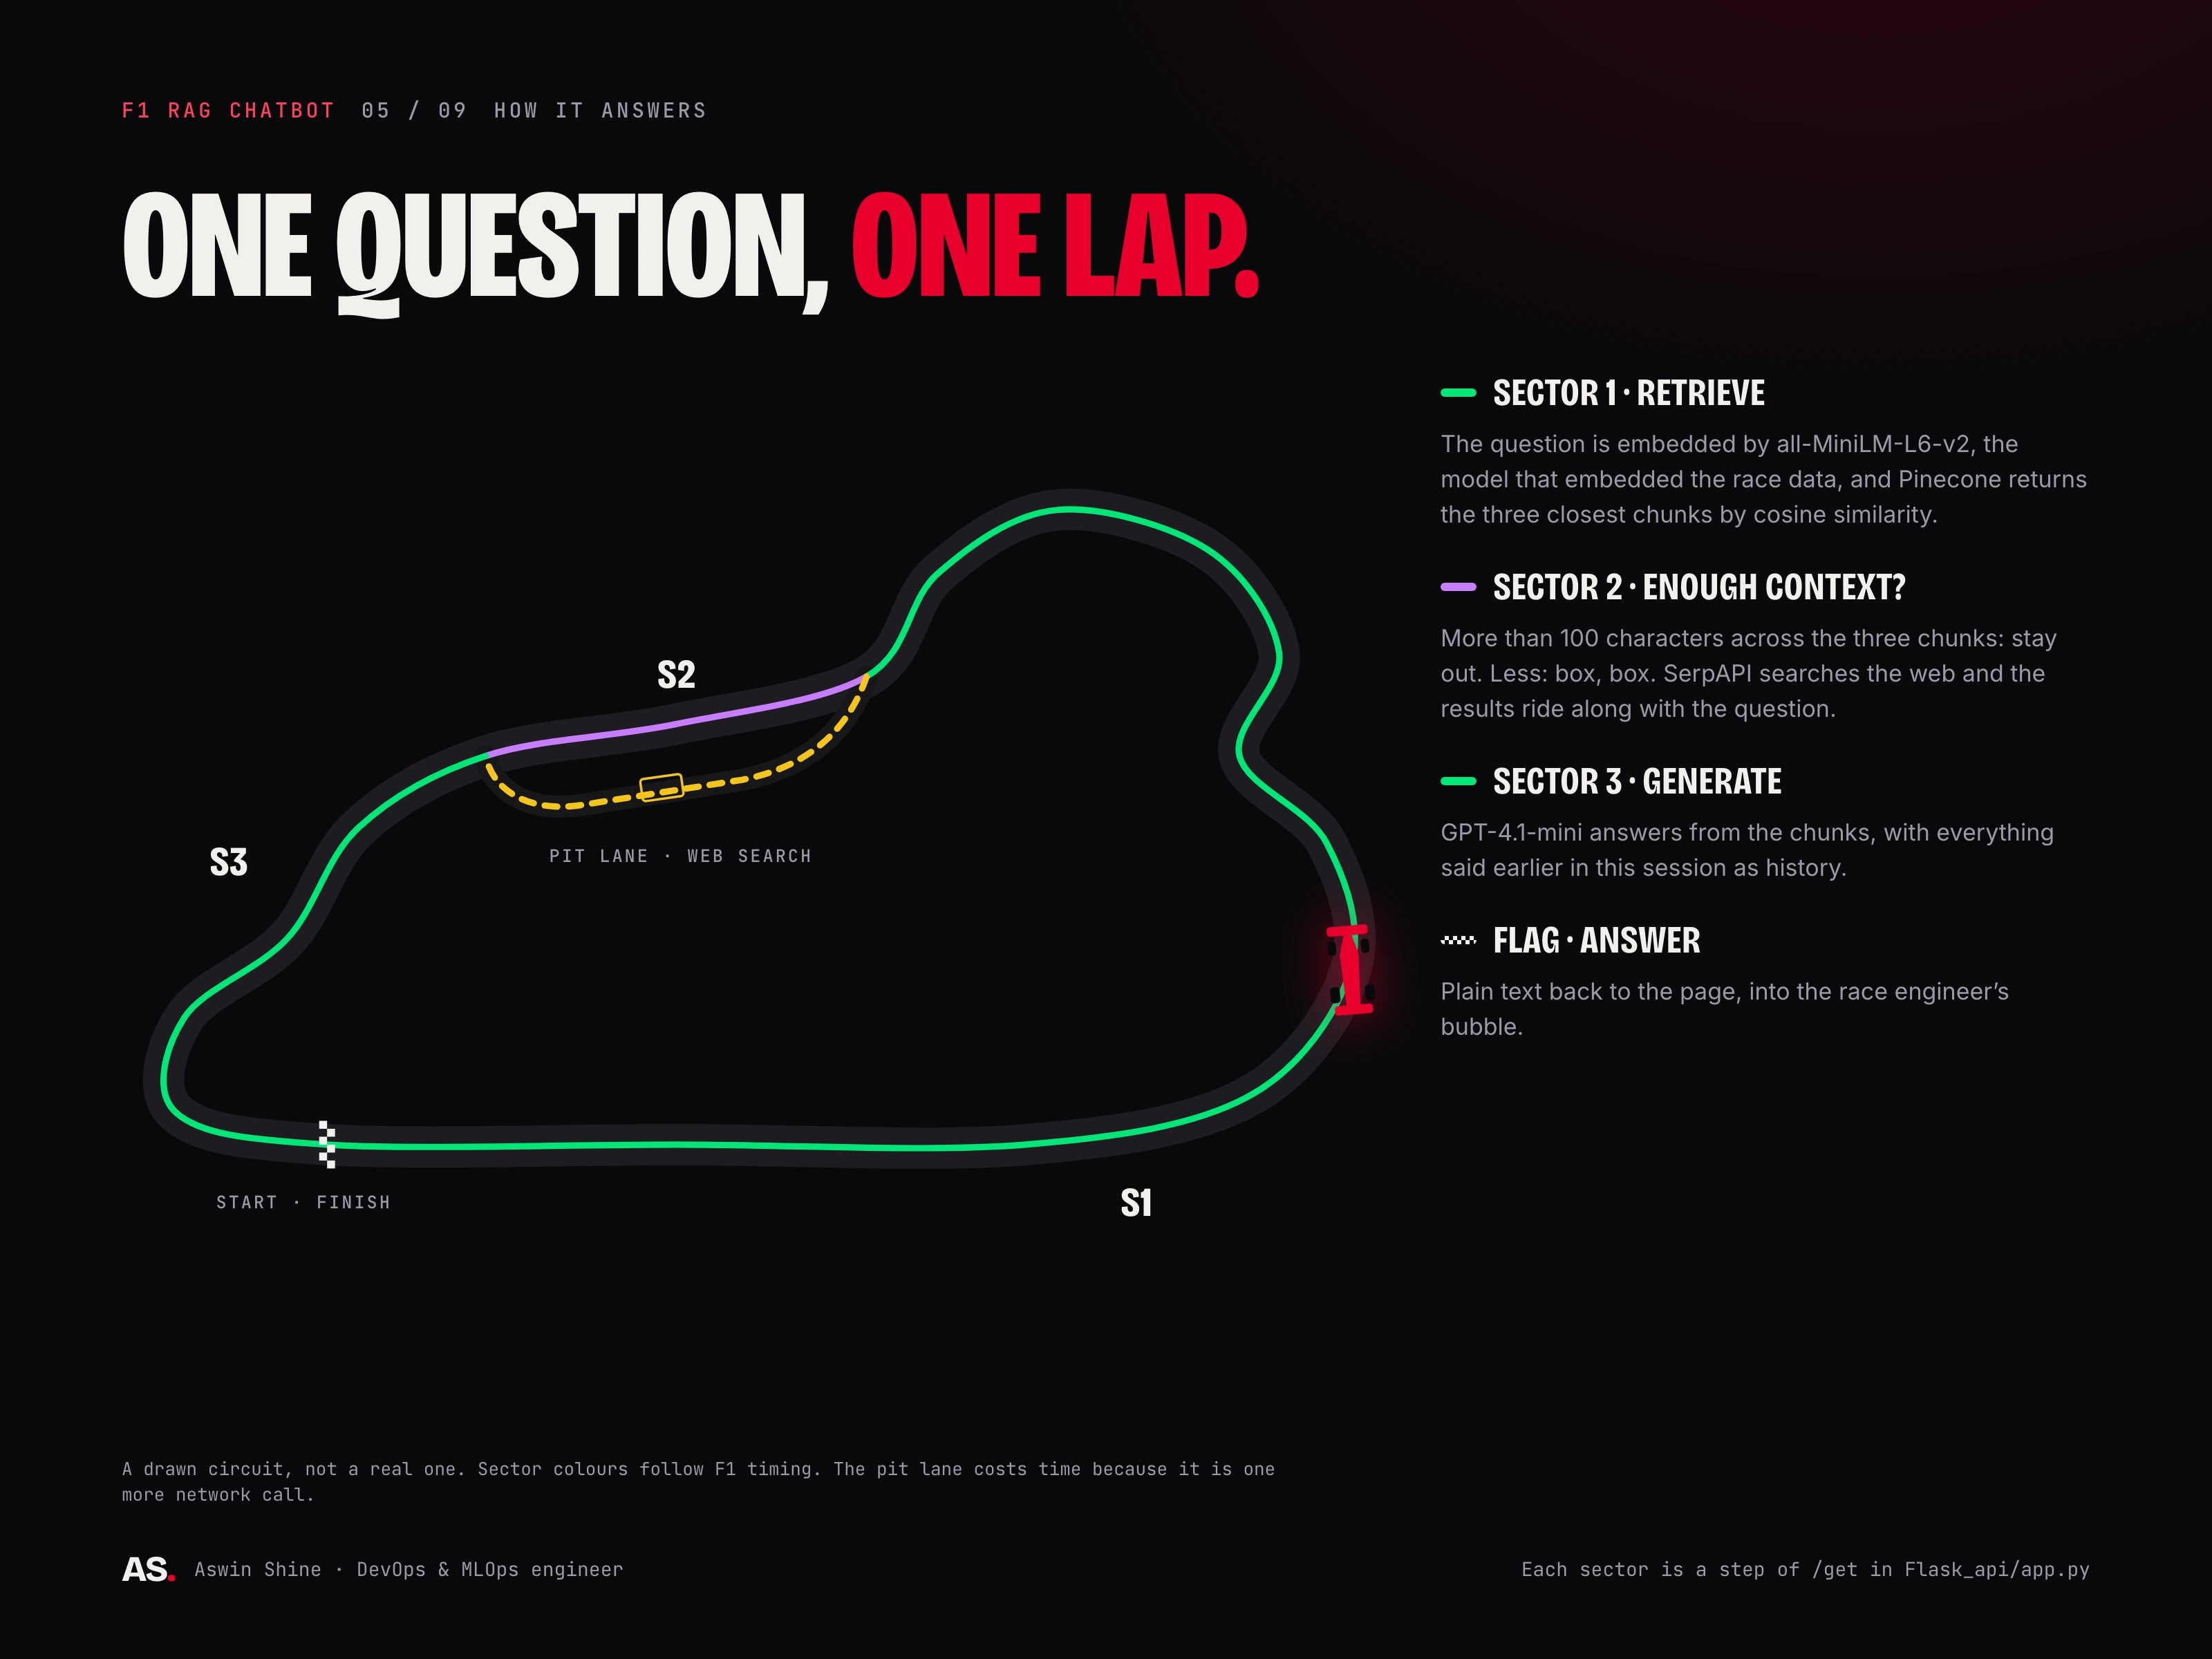
One question, one lap.
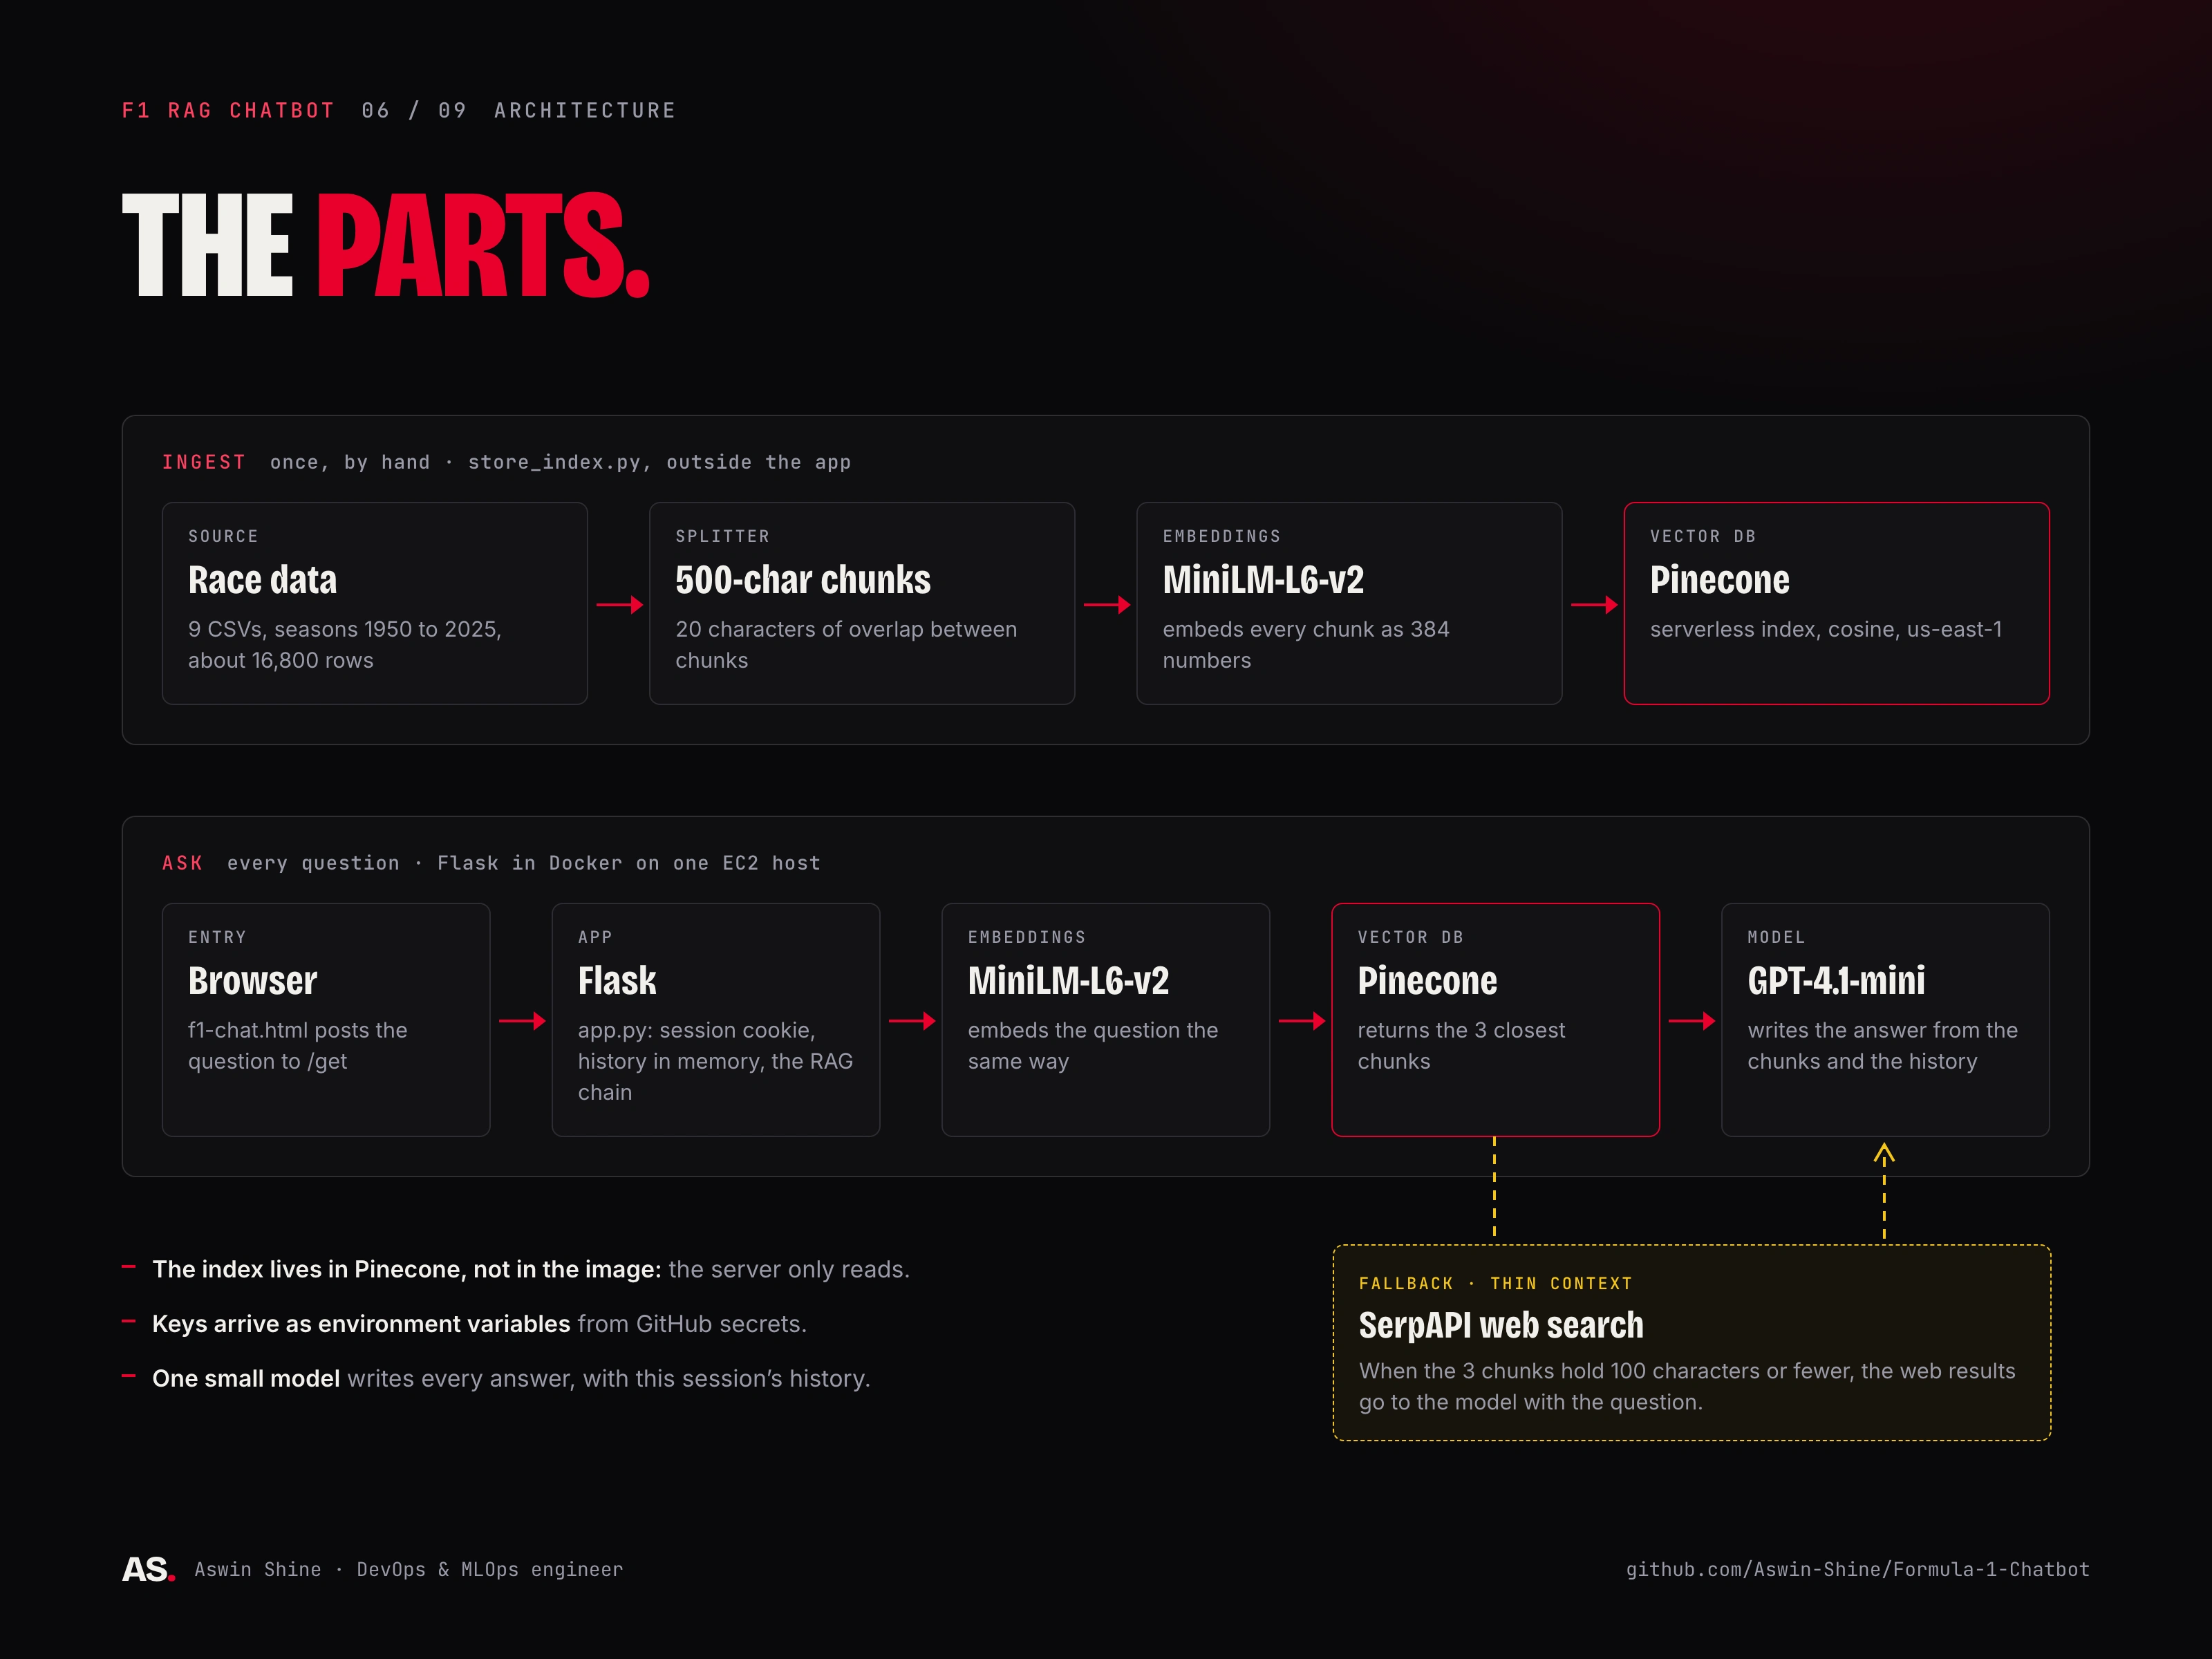
Sector 1 embeds the question with all-MiniLM-L6-v2 and pulls the three closest chunks from Pinecone. Sector 2 checks the context: more than 100 characters stays out, less boxes for a SerpAPI web search. Sector 3 hands the chunks and the session's history to GPT-4.1-mini.
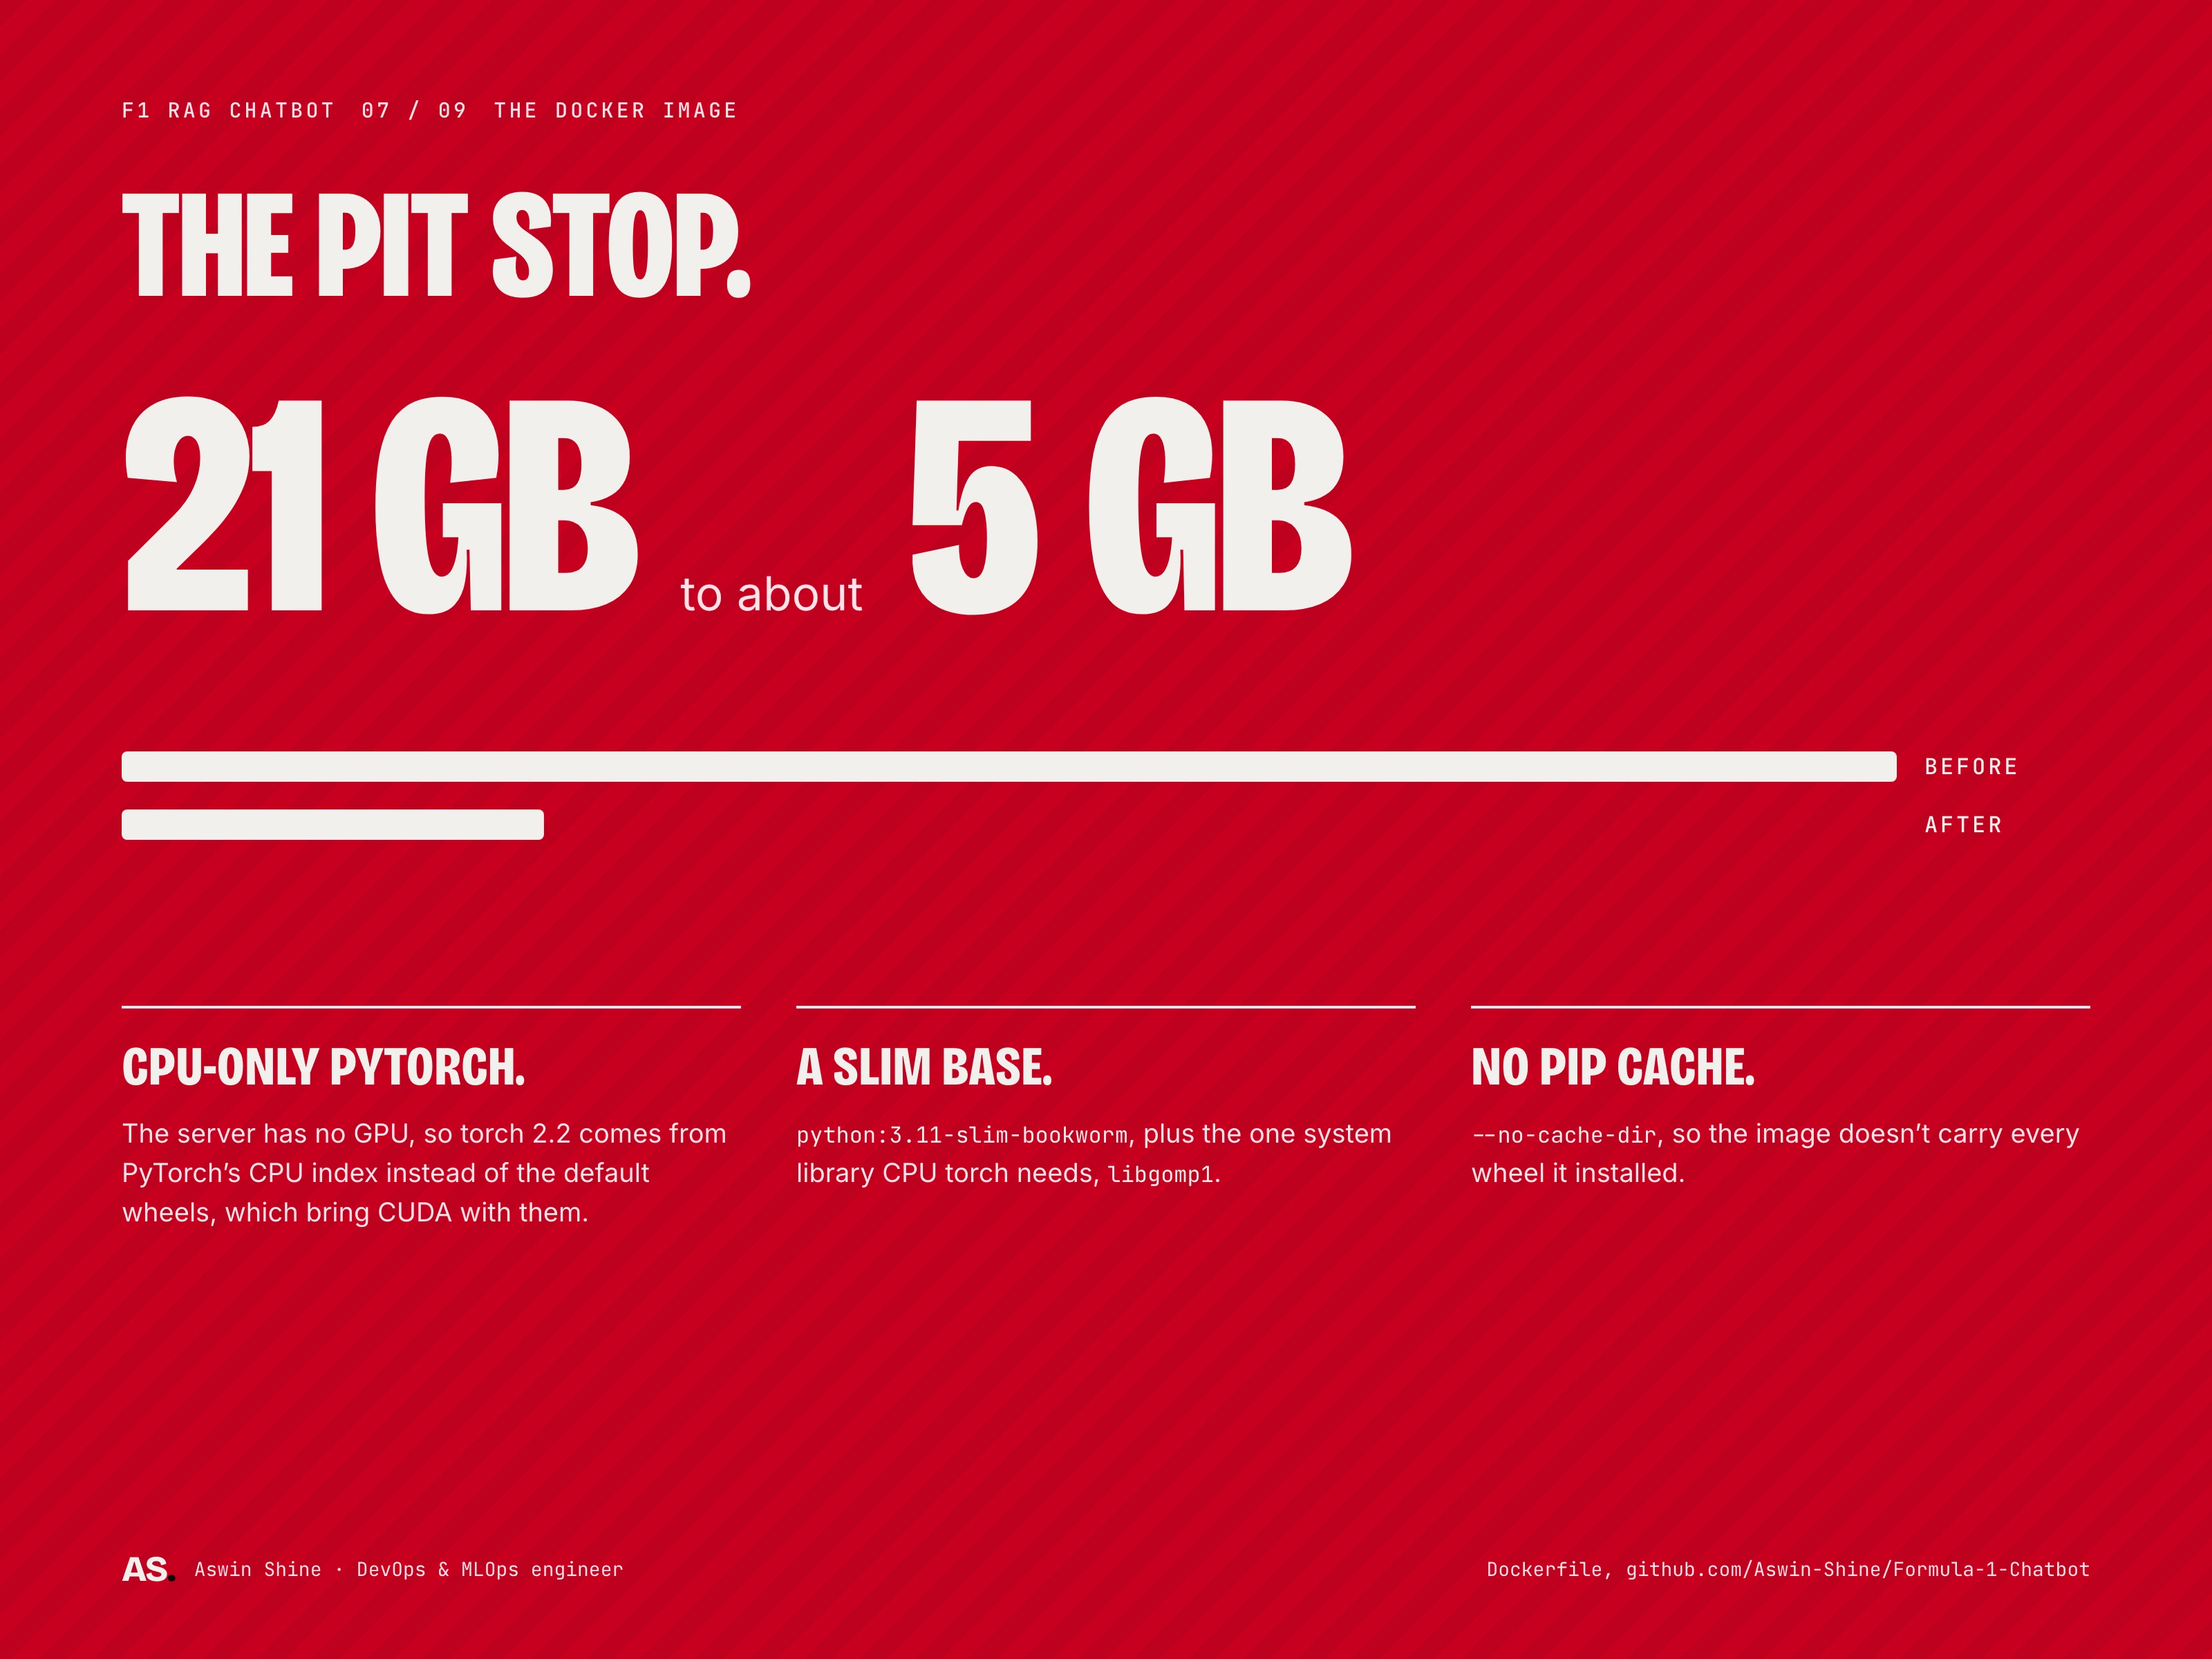
The pit stop: 21 GB to about 5 GB.
The first image was 21 GB. CPU-only PyTorch (the server has no GPU), a slim Python 3.11 base and no pip cache brought it to about 5 GB with the same features.
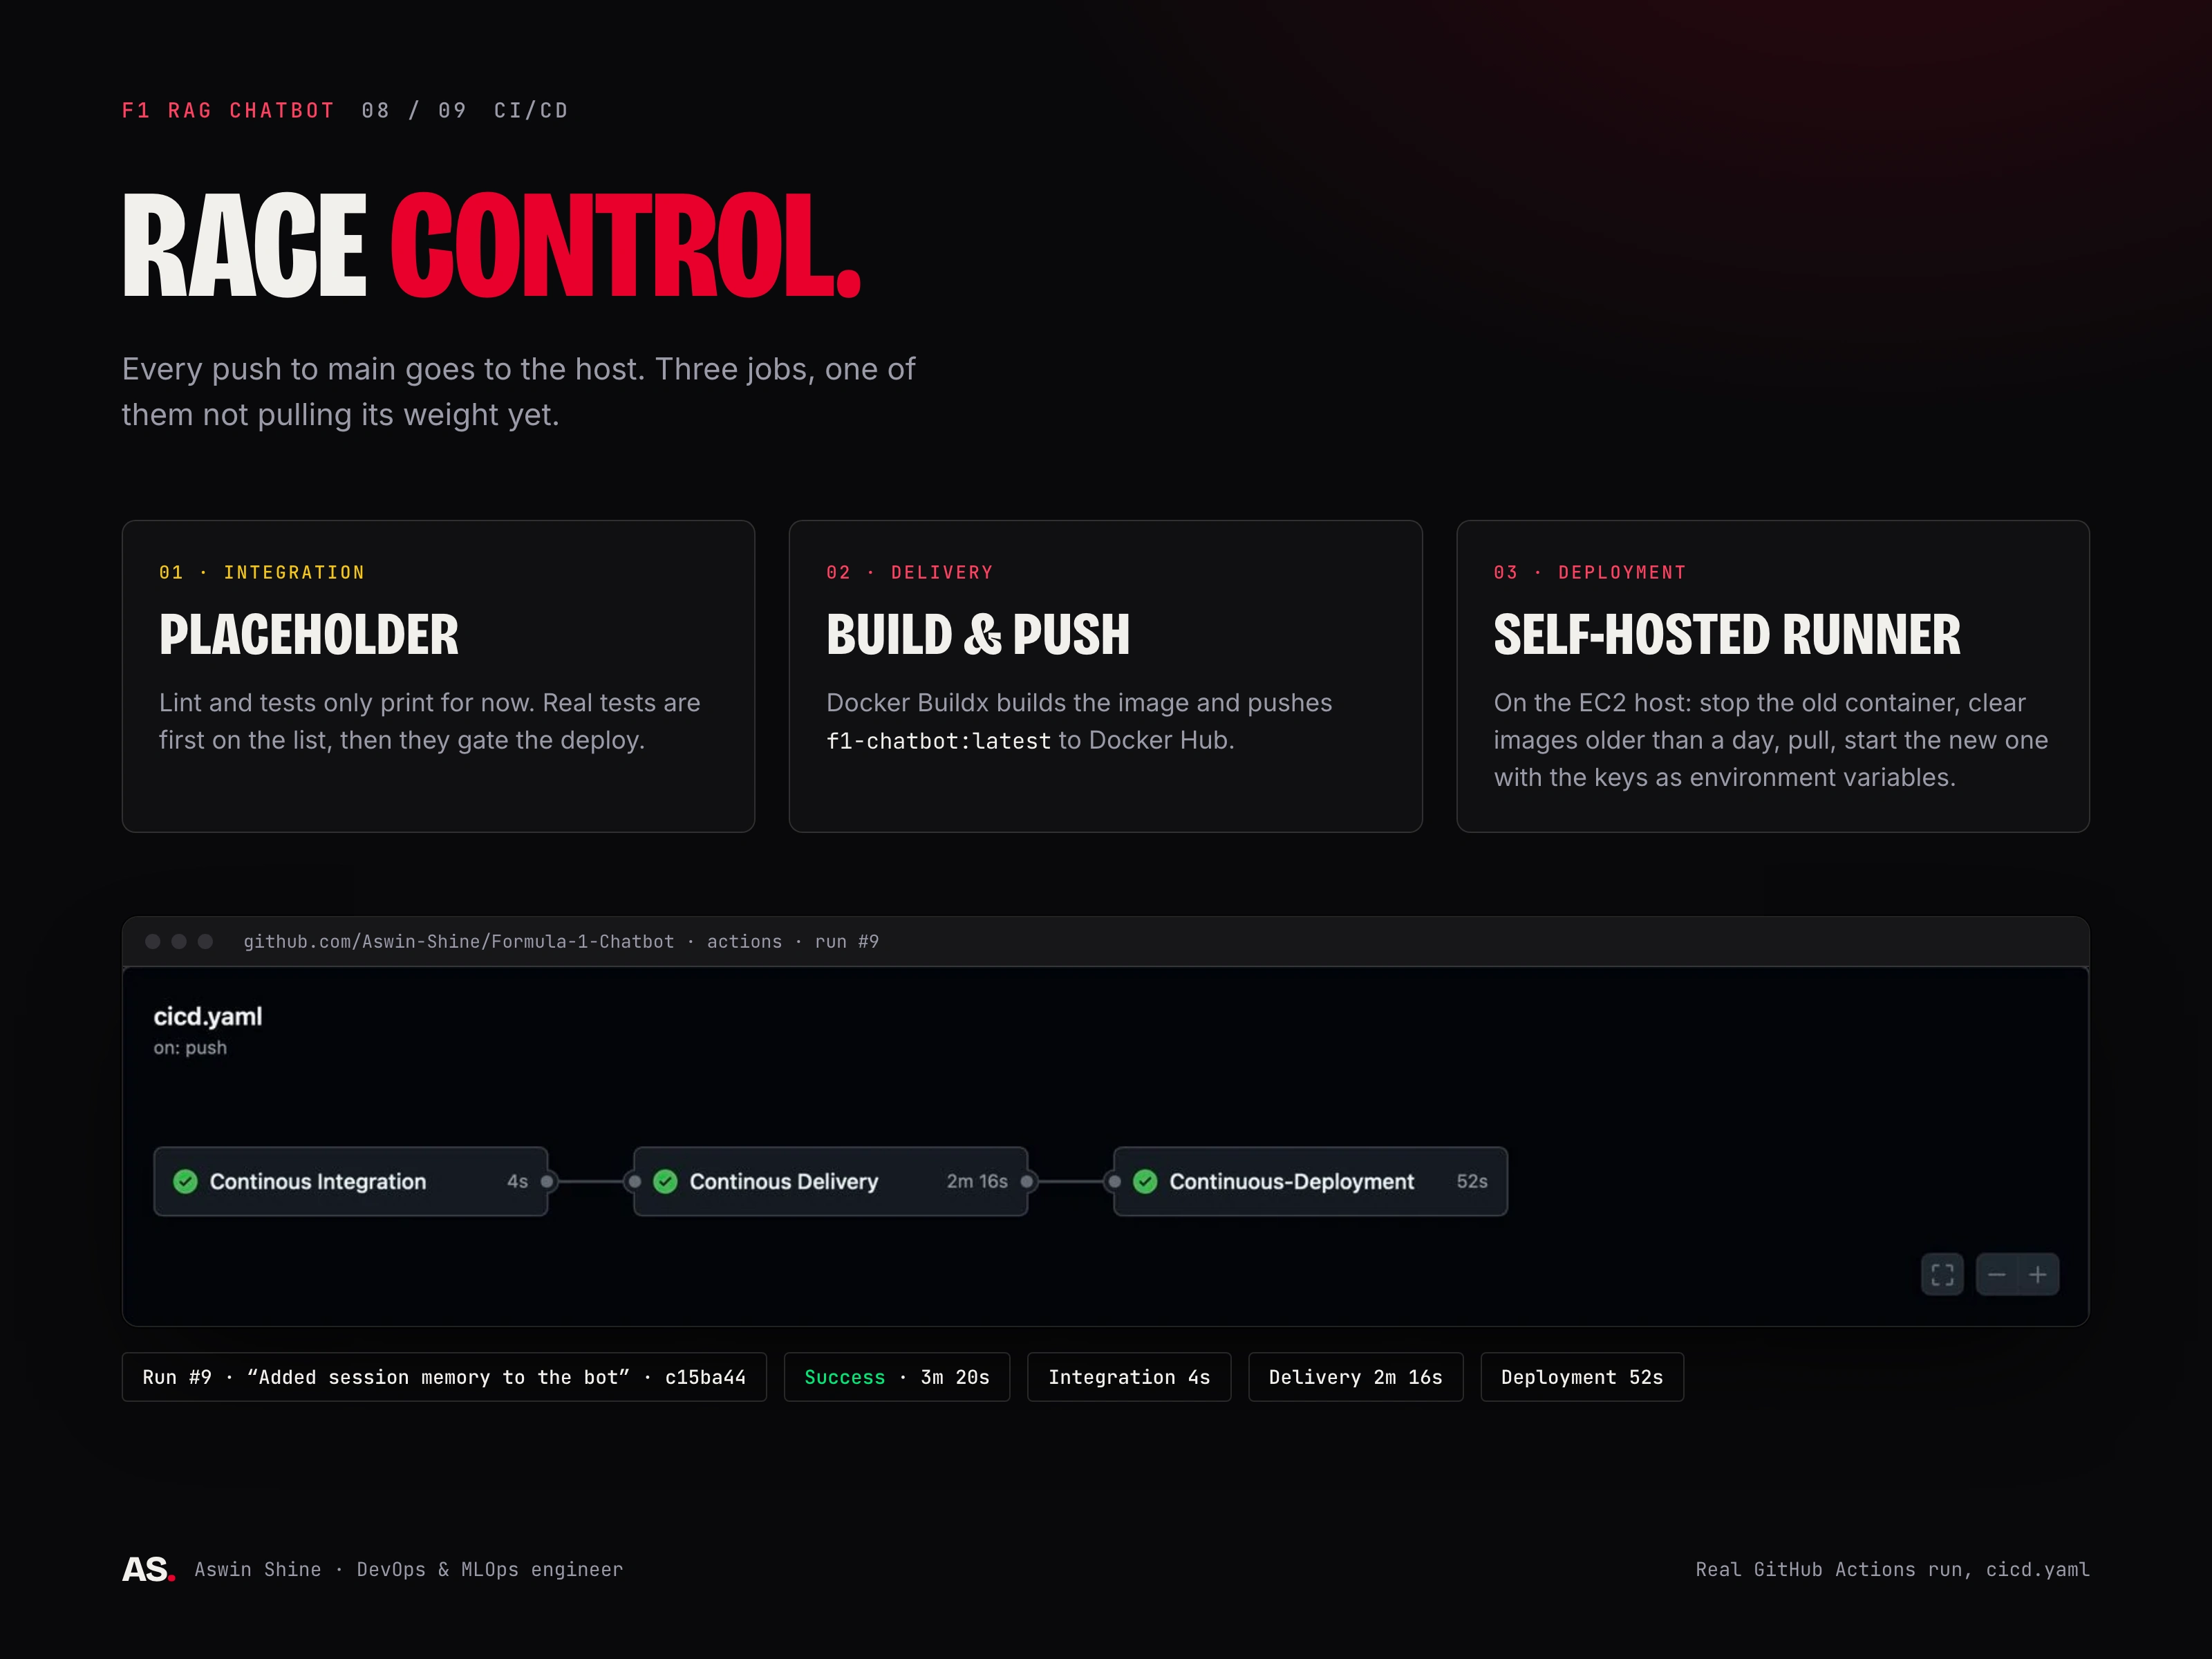
Race control.
Every push to main runs three GitHub Actions jobs: Integration (a placeholder for now), Delivery (Buildx builds and pushes to Docker Hub) and Deployment (a self-hosted runner on the EC2 host pulls and restarts the container, with keys from GitHub secrets). The real run in the image took 3m 20s.
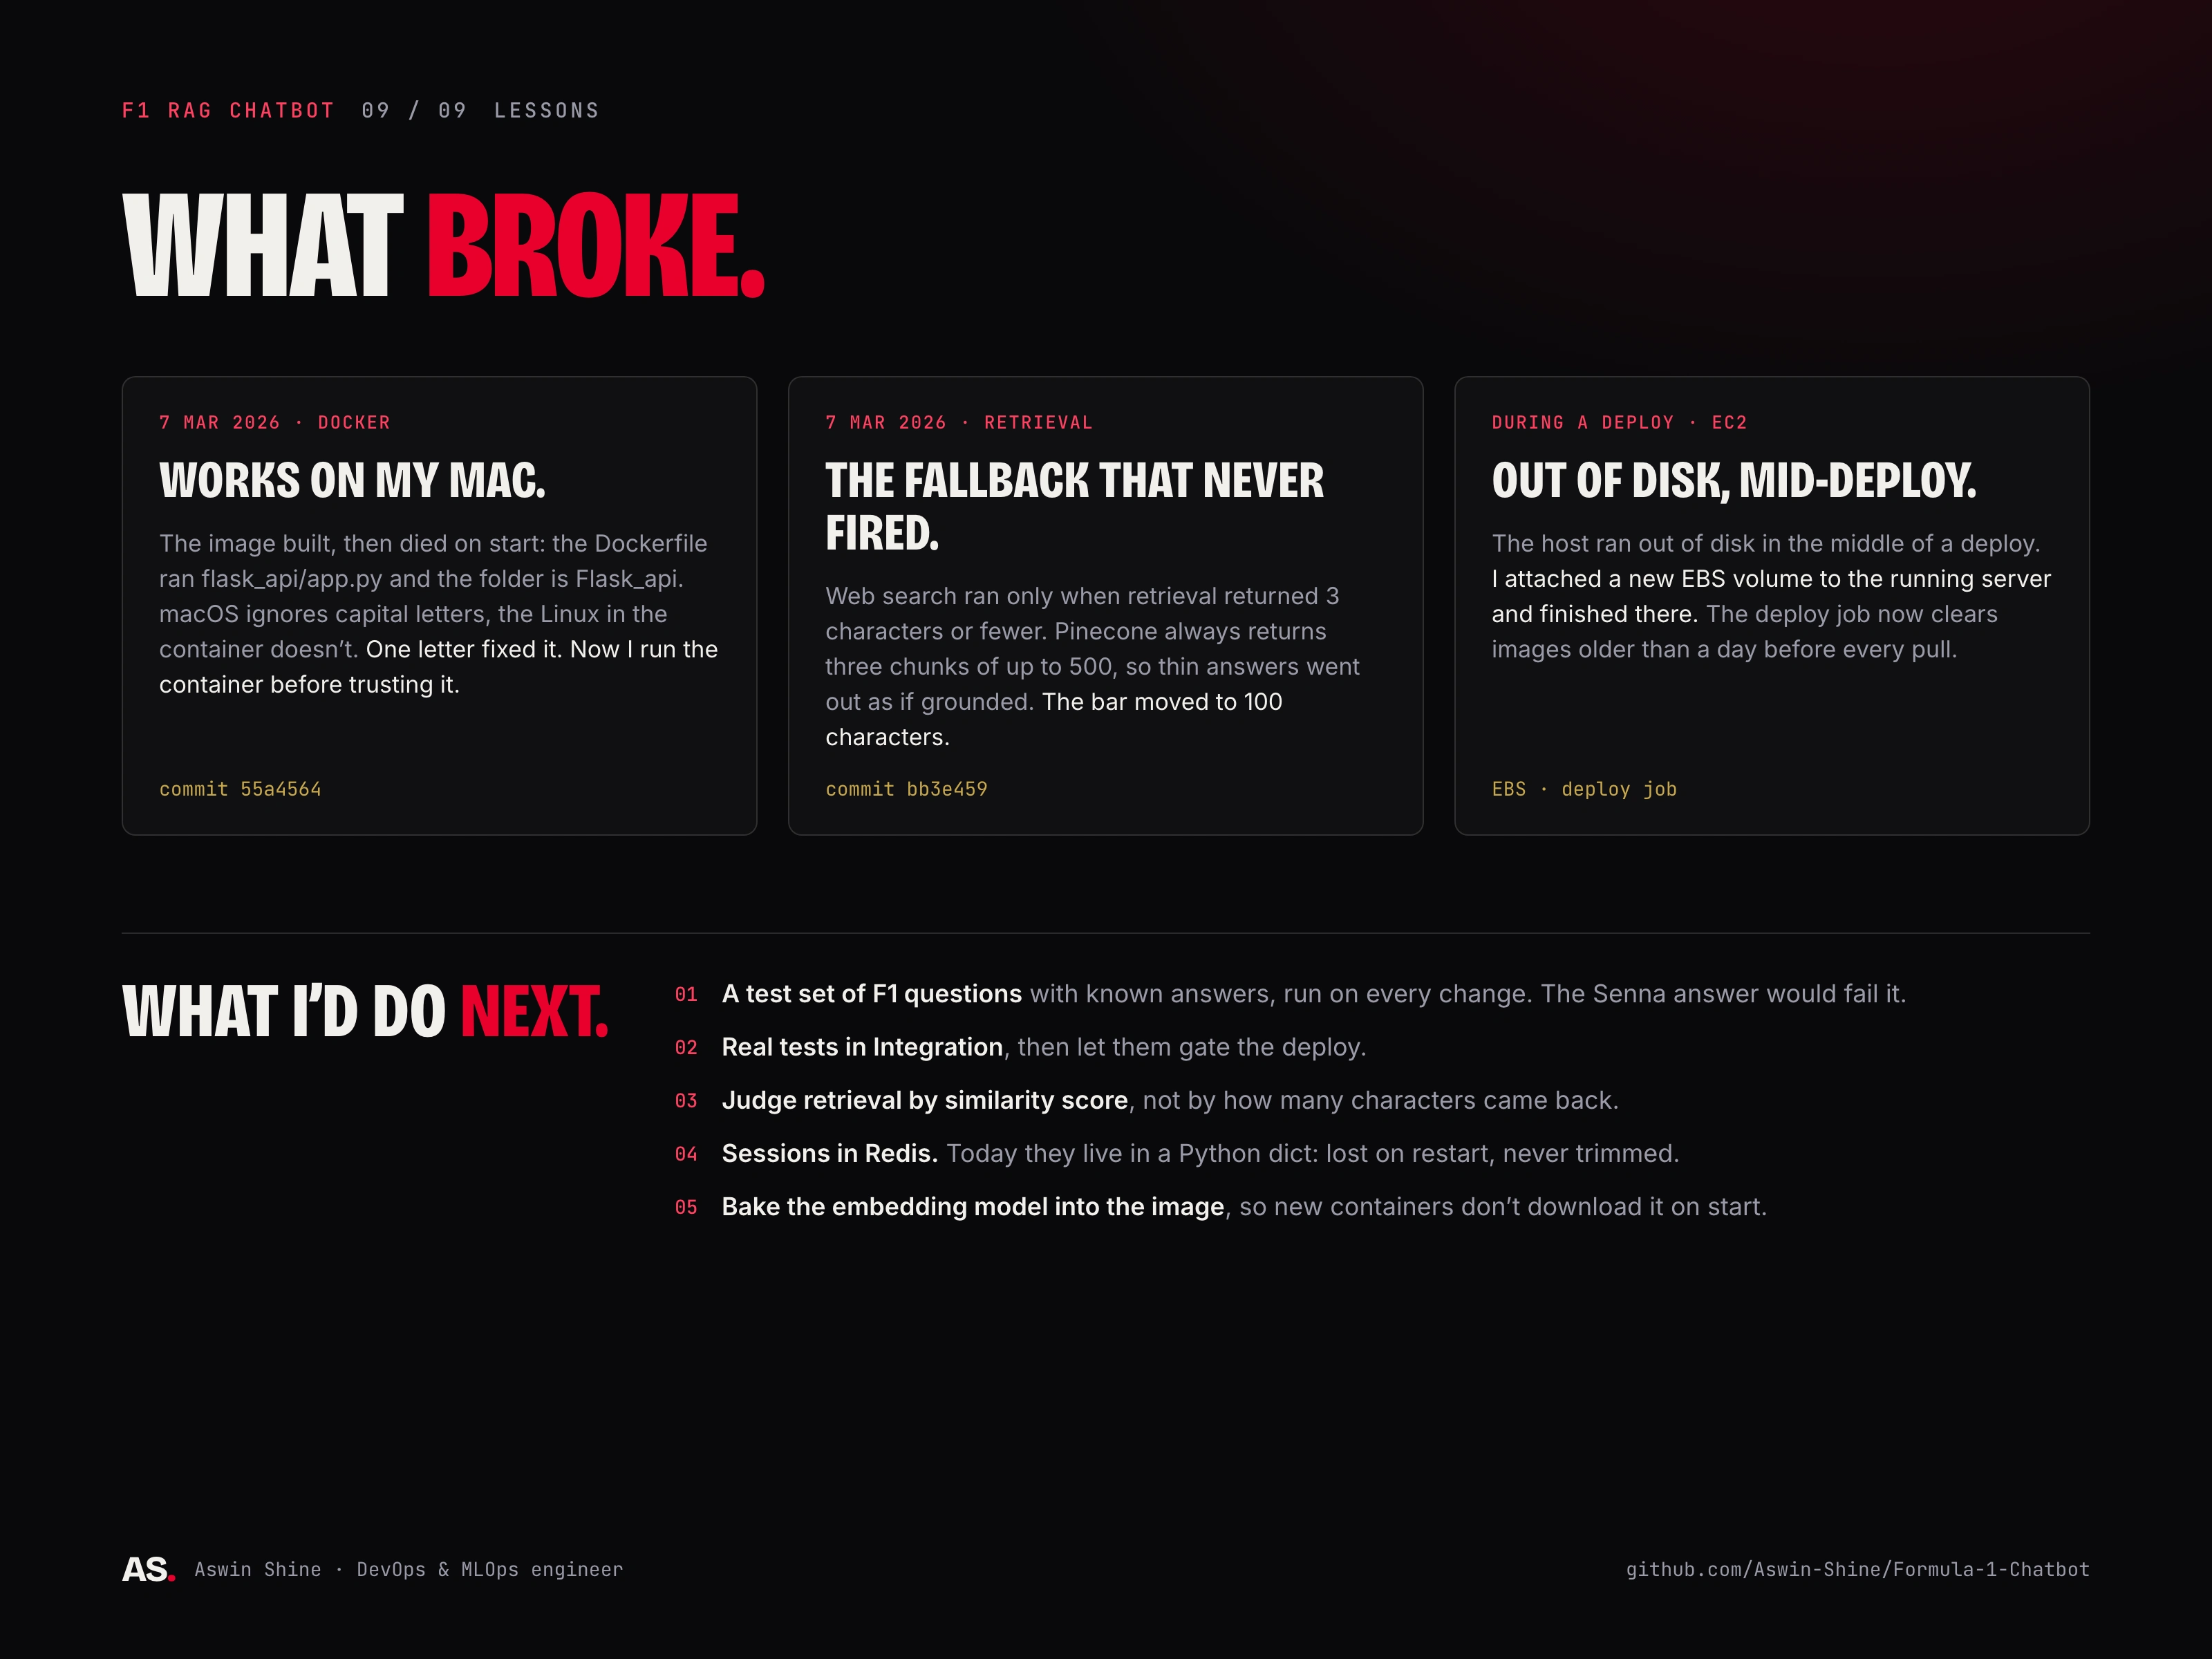
What broke, and what's next.
A capital letter that macOS ignored and Linux didn't, a web-search fallback that never fired, and a server that ran out of disk mid-deploy. Next: a test set of known answers, real tests that gate the deploy, retrieval judged by similarity score, and sessions in Redis.
Like this project
Posted Oct 15, 2026
A Formula 1 chatbot that answers from race data back to 1950 and searches the web when it runs thin. RAG on Pinecone, GPT-4.1-mini, Docker and EC2.
Likes
0
Views
0
Timeline
Feb 5, 2026 - Mar 25, 2026