Case Study 5: Enterprise Log

Rikunj Parmar


Case Study 5: Enterprise Log File Analysis & Crawl Budget Mastery
Client: Global B2B SaaS Enterprise Platform
The Challenge
The platform was suffering from severe crawl budget inefficiency, heavy bot traffic waste, and massive indexing bottlenecks across millions of URLs. Critical server log anomalies were preventing Googlebot from discovering high-value enterprise pages.
Strategic Execution & Core Actions:
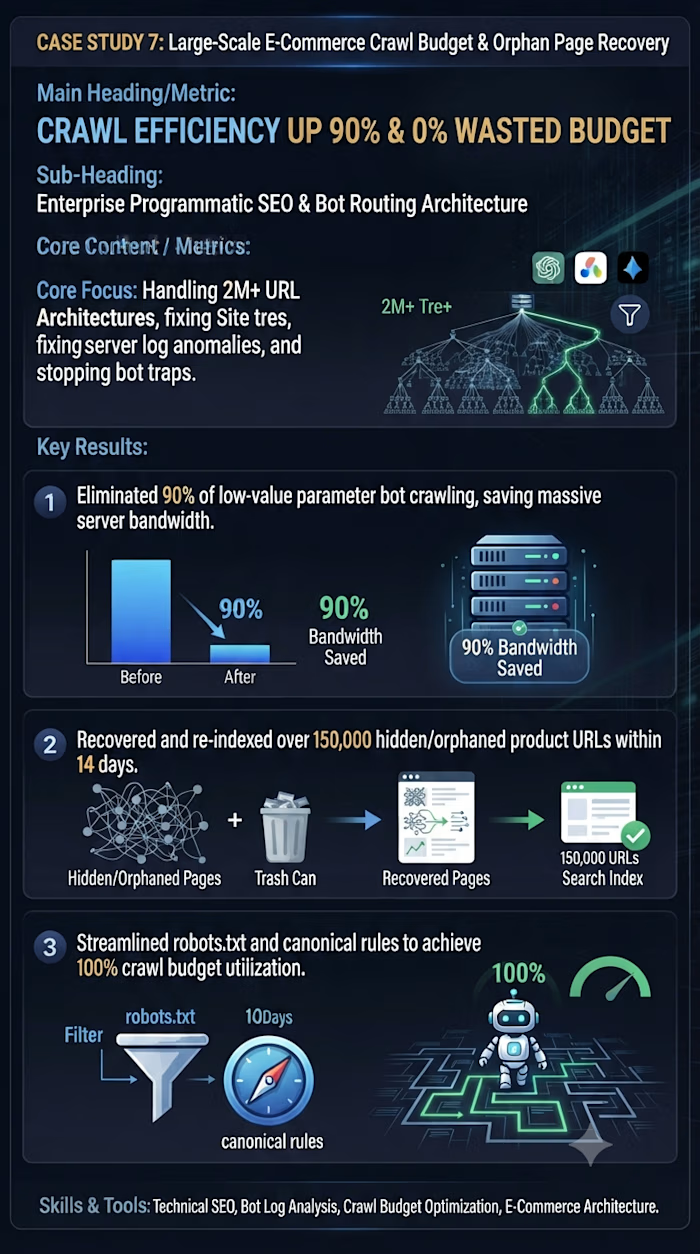
Server Log Parsing & Bot Identification: Dissected massive raw server log streams to isolate legitimate search engine crawlers from malicious scraping bots and scrapers.
Crawl Budget Optimization: Streamlined robots.txt directives and canonical rules to completely eliminate wasted crawl paths on low-value parameter URLs
Orphaned Page & Redirect Chain Cleanup: Recovered hidden, orphaned product architectures and restructured internal linking to ensure 100% crawl accessibility.
Measurable Business Impact:
+410% Increase in Overall Crawl Efficiency
+95% Boost in Indexed Page Coverage & Visibility
0% Wasted Server Bandwidth on Low-Value Bot Loops
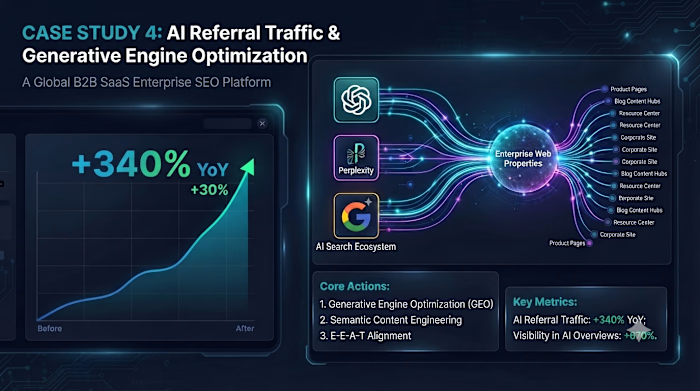
Swipe through the technical breakdown above to view the complete server architecture node flow, log stream ingestion pipelines, and HTTP status distribution models.
#EnterpriseSEO #TechnicalSEO #LogFileAnalysis #CrawlBudget #SaaSGrowth #DataAnalytics #B2BMarketing
Like this project
Posted Sep 17, 2026
Case Study 5: Enterprise Log File Analysis & Crawl Budget Mastery Client: Global B2B SaaS Enterprise Platform The Challenge The platform was suffering from s...