Why am I building a quantitative trading system?
Because I don't want trading to depend on spending hours staring at charts, making repetitive decisions manually, missing opportunities, or letting emotions and inconsistency affect execution.
For retail and independent traders, the difficult part isn't just finding a strategy.
It's knowing whether the strategy actually works, why it works, and why it fails.
That's what I'm trying to solve with my Quantitative Systems Platform.
Recently, I found a major bottleneck in my research.
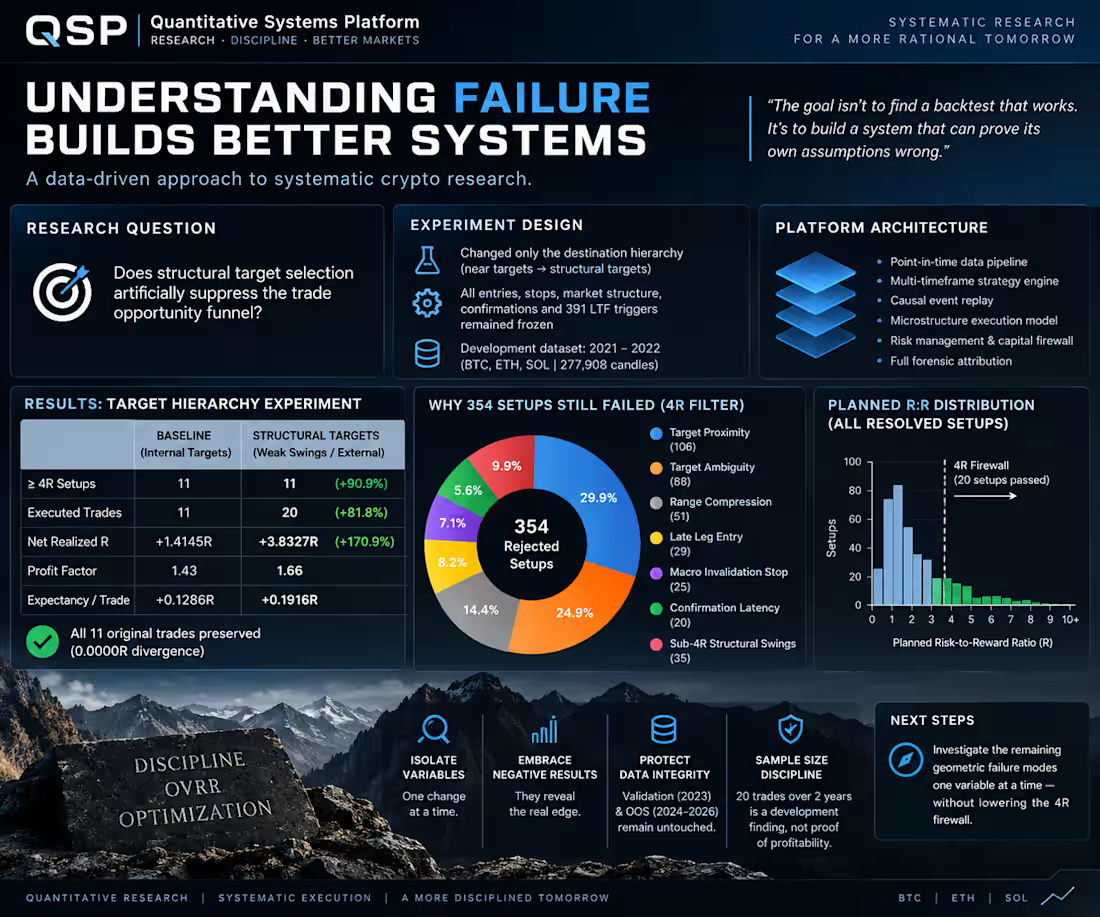
Out of 387 target-resolved setups, only 11 met my ≥4R requirement.
Instead of lowering the requirement to create more trades, I asked:
Was the system choosing the wrong structural target?
I ran a controlled experiment where I changed only the target-selection hierarchy. Entries, stops, market structure, confirmations and the 391 LTF-confirmed triggers stayed frozen.
On the 2021–2022 development dataset:
≥4R setups: 11 → 21
Executed trades: 11 → 20
Net realized: +1.4145R → +3.8327R
Profit Factor: 1.43 → 1.66
All 11 original trades were preserved with 0.0000R divergence.
But the most important part wasn't the improvement.
I investigated the 354 setups that still failed the 4R firewall.
They revealed multiple failure modes:
target proximity, compressed ranges, late entries, wide structural stops, confirmation latency, target ambiguity — and 35 structurally healthy-looking setups that still fell between 1.5R and 3.9R.
So the answer isn't simply:
“Lower 4R.”
The real research problem is understanding the interaction between entry geometry, available expansion, structural risk, confirmation timing and destination selection.
That's why I'm building this platform.
Not to create another black-box trading bot.
I want a system that can tell me:
Why did this trade qualify?
Why did another fail?
Which assumption caused it?
Can I isolate that assumption?
Can I reproduce the result?
Does it survive unseen data?
The long-term objective is straightforward:
Less manual trading. Less inconsistency. More systematic research. More reproducible execution. And eventually, if the evidence earns it, automation.
This experiment is still a development finding, not proof of profitability or production readiness. Validation and out-of-sample data remain protected.
The next step is to investigate the remaining failure modes one variable at a time.
I'm not trying to build a system that only proves itself right.
I'm building one capable of proving itself wrong.
🔗 Project: Quantitative Systems Platform — GitHub (https://github.com/Quantitative-Systems/crypto-platform?utm_source=chatgpt.com)
#QuantitativeFinance #QuantitativeResearch #SystematicTrading #AlgorithmicTrading #TradingSystems #Python #FinTech #RiskManagement #Crypto
1
176
I just published something I’ve been thinking about for a long time.
I’ve spent the last several months learning, building, breaking, and rebuilding with AI.
What started as curiosity about AI and software turned into something much bigger: learning how to actually engineer systems with AI — and eventually combining that with my interest in trading and finance.
I’m now moving toward quantitative systems engineering, building research infrastructure, trading systems, financial software, and experimenting with how far I can push AI-assisted engineering.
I wrote about the journey — the mistakes, failures, lessons, AI experiments, projects, and why I decided to build instead of waiting for someone to give me “real experience.”
From using AI → engineering with AI → building quantitative systems.
If you're interested in AI, software, trading, or building things from scratch, I’d love for you to read it. 🚀
👇 The full story is here:
https://www.linkedin.com/pulse/from-learning-ai-building-quantitative-systems-bukya-naresh-nqh1f
This is the beginning of a much bigger experiment.
Learning. Building. Testing. Breaking. Rebuilding.
And seeing how far I can actually take it.
🚀
#ArtificialIntelligence (https://www.linkedin.com/search/results/all/?keywords=%23artificialintelligence&origin=HASH_TAG_FROM_FEED) #AI (https://www.linkedin.com/search/results/all/?keywords=%23ai&origin=HASH_TAG_FROM_FEED) #SoftwareEngineering (https://www.linkedin.com/search/results/all/?keywords=%23softwareengineering&origin=HASH_TAG_FROM_FEED) #QuantitativeFinance (https://www.linkedin.com/search/results/all/?keywords=%23quantitativefinance&origin=HASH_TAG_FROM_FEED) #AlgorithmicTrading (https://www.linkedin.com/search/results/all/?keywords=%23algorithmictrading&origin=HASH_TAG_FROM_FEED) #QuantEngineering (https://www.linkedin.com/search/results/all/?keywords=%23quantengineering&origin=HASH_TAG_FROM_FEED) #FinTech (https://www.linkedin.com/search/results/all/?keywords=%23fintech&origin=HASH_TAG_FROM_FEED) #TradingSystems (https://www.linkedin.com/search/results/all/?keywords=%23tradingsystems&origin=HASH_TAG_FROM_FEED) #SystemDesign (https://www.linkedin.com/search/results/all/?keywords=%23systemdesign&origin=HASH_TAG_FROM_FEED) #BuildInPublic (https://www.linkedin.com/search/results/all/?keywords=%23buildinpublic&origin=HASH_TAG_FROM_FEED) #QuantitativeResearch (https://www.linkedin.com/search/results/all/?keywords=%23quantitativeresearch&origin=HASH_TAG_FROM_FEED)
0
60
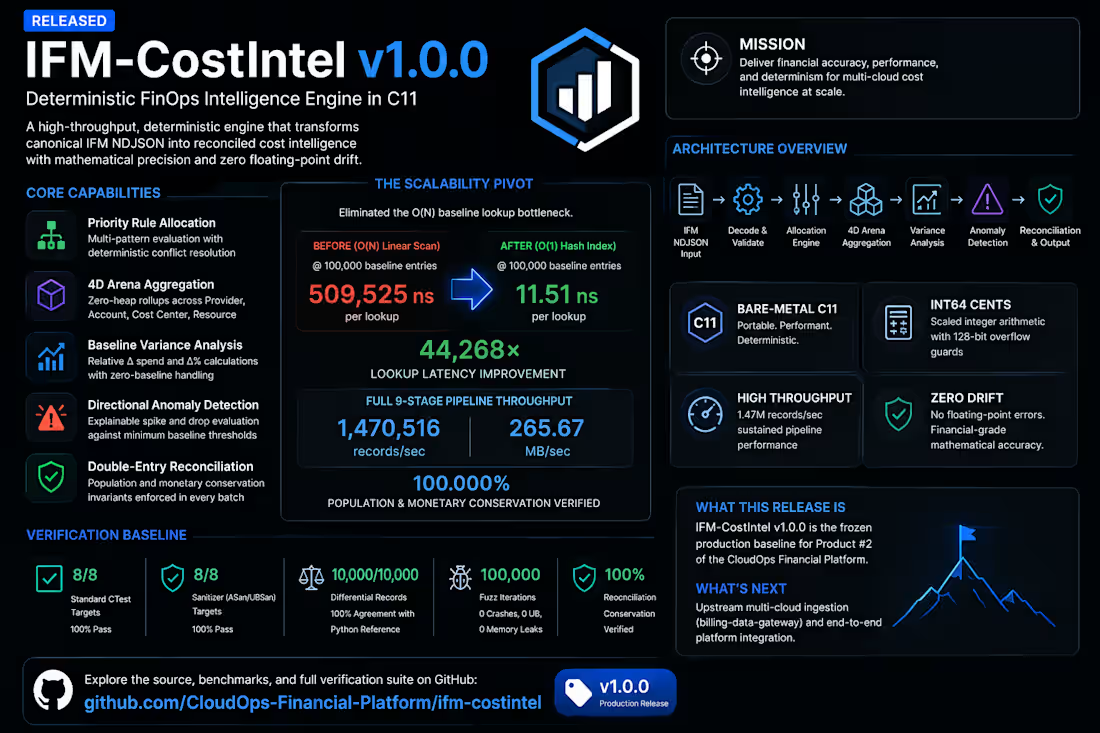
⚡ IFM-CostIntel — Deterministic FinOps & Cloud Cost Intelligence Engine
I’ve built and released IFM-CostIntel v1.0.0, a production-grade C11 financial intelligence engine designed to process normalized cloud billing data and transform it into deterministic, reconciled cost intelligence.
What it does
IFM-CostIntel provides:
Cost allocation with deterministic rule resolution
4D cost aggregation across provider, account, cost center, and resource
Baseline variance analysis
Directional anomaly detection
Financial reconciliation and conservation checks
Structured NDJSON output and audit telemetry
High-throughput processing designed for large billing workloads
Why it matters
Financial pipelines cannot afford silent rounding errors, inconsistent allocation, or unexplained reconciliation differences.
The engine therefore uses fixed-point integer financial arithmetic rather than floating-point calculations and enforces mathematical conservation throughout processing.
During scalability engineering, I also replaced an O(N) baseline lookup with an O(1) FNV-1a open-addressing hash index.
The measured improvement at 100,000 baseline entries:
509,525 ns → 11.51 ns per lookup
≈ 44,268× lower lookup latency
The complete pipeline benchmark reached:
1.47M records/sec
265.67 MB/sec
Verification
The v1.0.0 release has been validated through:
✅ 8/8 standard tests passing
✅ 8/8 ASan/UBSan tests passing
✅ 10,000/10,000 differential records matching the reference oracle
✅ 100,000 adversarial fuzz iterations
✅ 100% financial reconciliation conservation
What I can build with this capability
I can apply this systems-engineering stack to projects involving:
Cloud FinOps • Billing Infrastructure • Financial Data Pipelines • C/C++ Performance Engineering • Data Normalization • Cost Allocation • Reconciliation Systems • High-throughput Processing
The engine is available as an open-source reference implementation, and I’m interested in applying the same engineering principles to custom financial-data and cloud-cost infrastructure projects.
🔗 GitHub:
IFM-CostIntel Repository (https://github.com/CloudOps-Financial-Platform/ifm-costintel?utm_source=chatgpt.com)
🔖 v1.0.0 Release:
IFM-CostIntel v1.0.0 (https://github.com/CloudOps-Financial-Platform/ifm-costintel/releases/tag/v1.0.0?utm_source=chatgpt.com)
Need a high-performance financial or cloud-cost data pipeline? Let's talk.
1
2
208
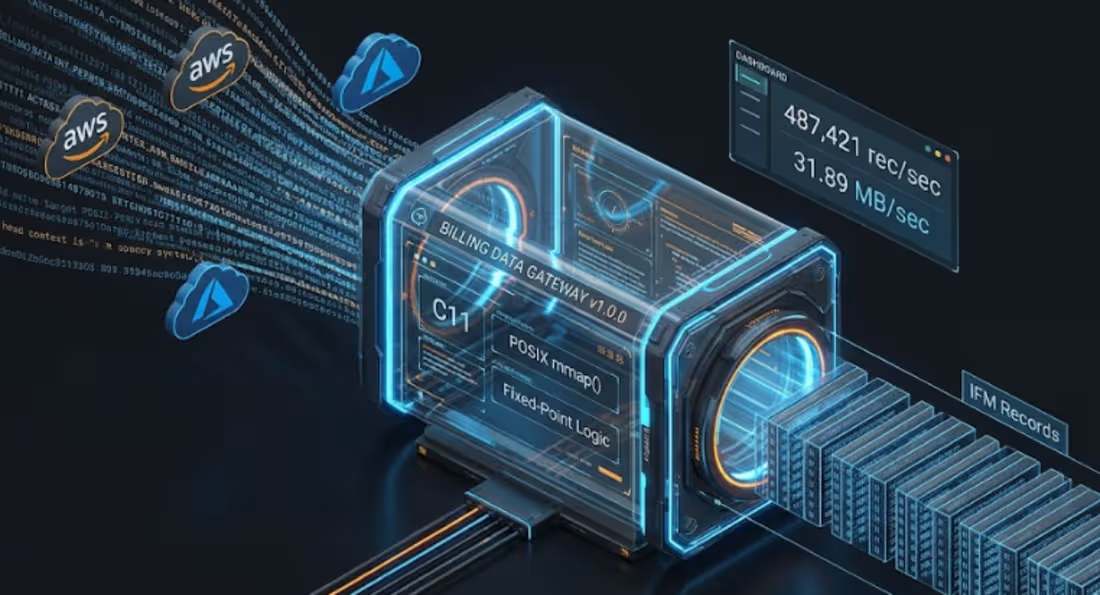
Billing Data Gateway v1.0.0 — Zero-Copy C11 Cloud Billing Engine
1
4