Kevin Williams
Data Scientist & Python Developer | Turning Complex Data Int
New to Contra
Kevin is building their profile!
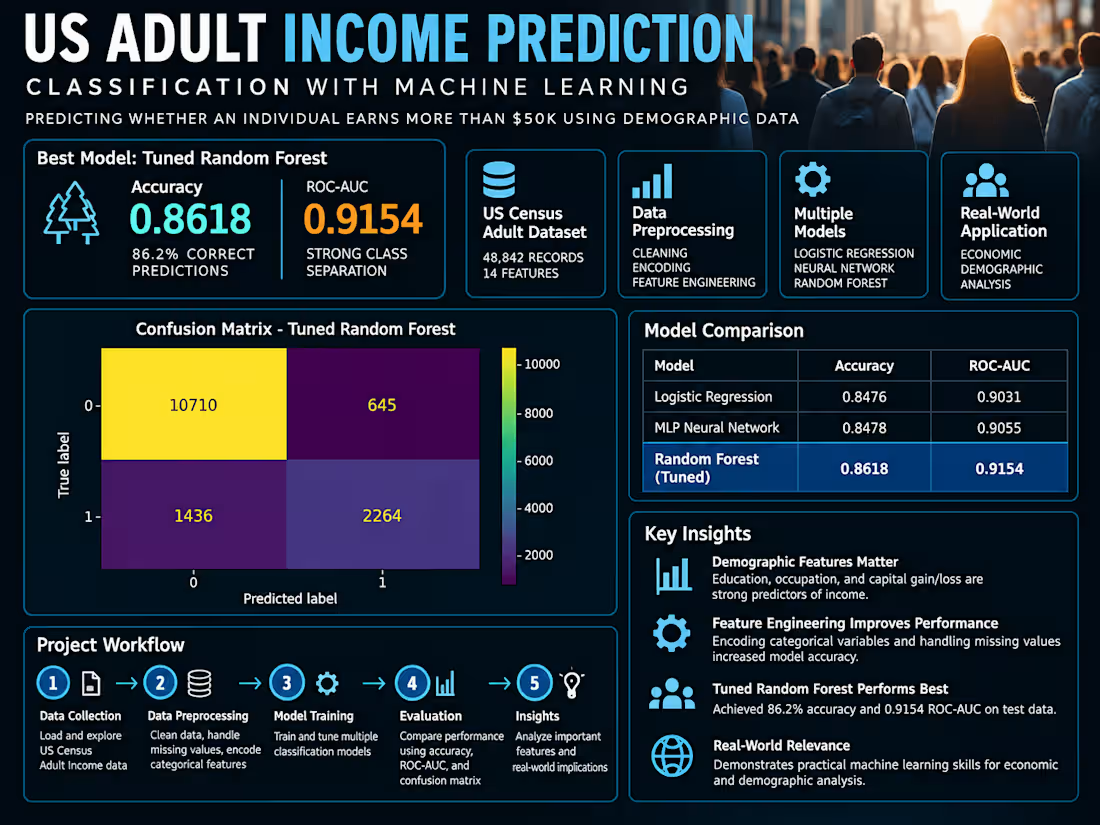
Developed a machine learning classification pipeline to predict whether an individual earns more than $50K using demographic and employment data. The project included data cleaning, categorical encoding, feature engineering, model training, hyperparameter tuning, and performance evaluation.
Compared Logistic Regression, an MLP Neural Network, and Random Forest, with the tuned Random Forest achieving the strongest performance at 86.18% accuracy and 0.9154 ROC-AUC.
The project demonstrates an end-to-end classification workflow, including preprocessing mixed numerical and categorical data, comparing multiple modeling approaches, tuning model performance, and evaluating results using accuracy, ROC-AUC, and confusion-matrix analysis.
0
4
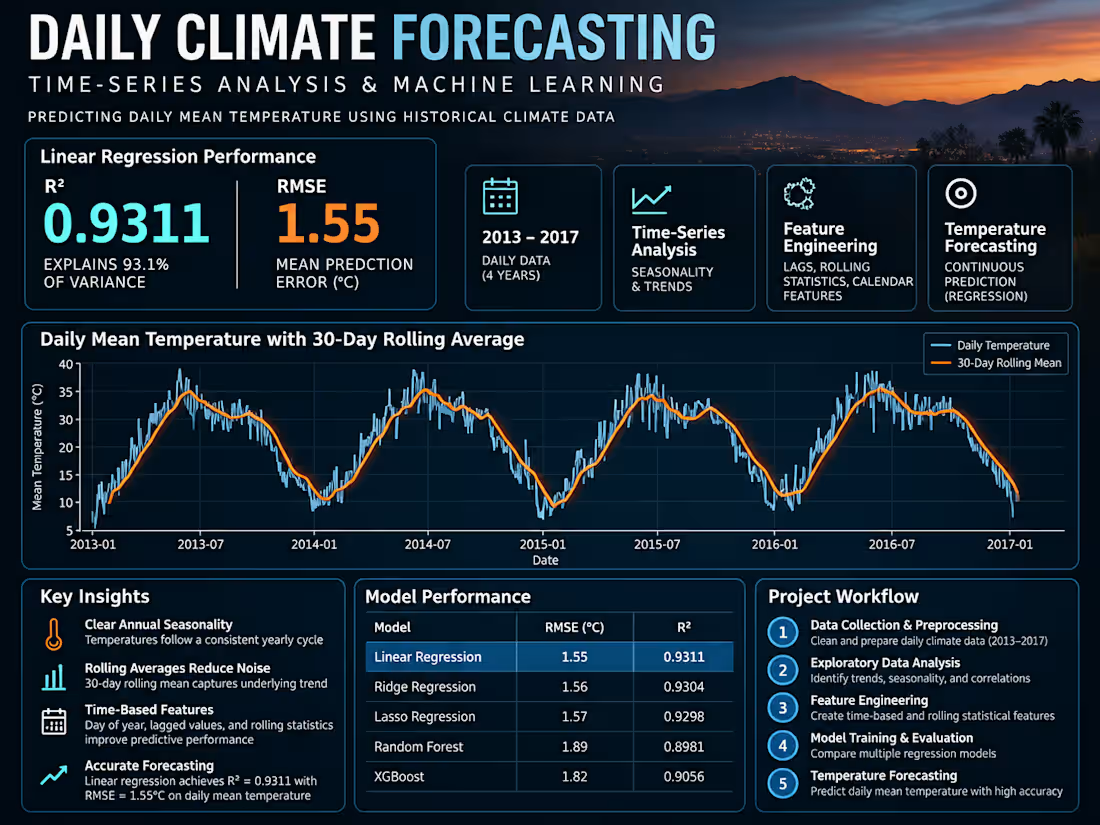
Developed a time-series machine learning workflow to analyze historical climate data and predict daily mean temperature. The project included exploratory analysis, seasonality detection, rolling statistics, time-based feature engineering, and regression model evaluation.
The Linear Regression model achieved an R² of 0.9311 and RMSE of 1.55, demonstrating strong predictive performance on the test data. Analysis of the historical series also revealed clear annual seasonal patterns and showed how rolling averages can help isolate underlying climate trends from daily variation.
The project demonstrates an end-to-end forecasting workflow using Python, from temporal data exploration and feature engineering through model training and performance evaluation.
0
9
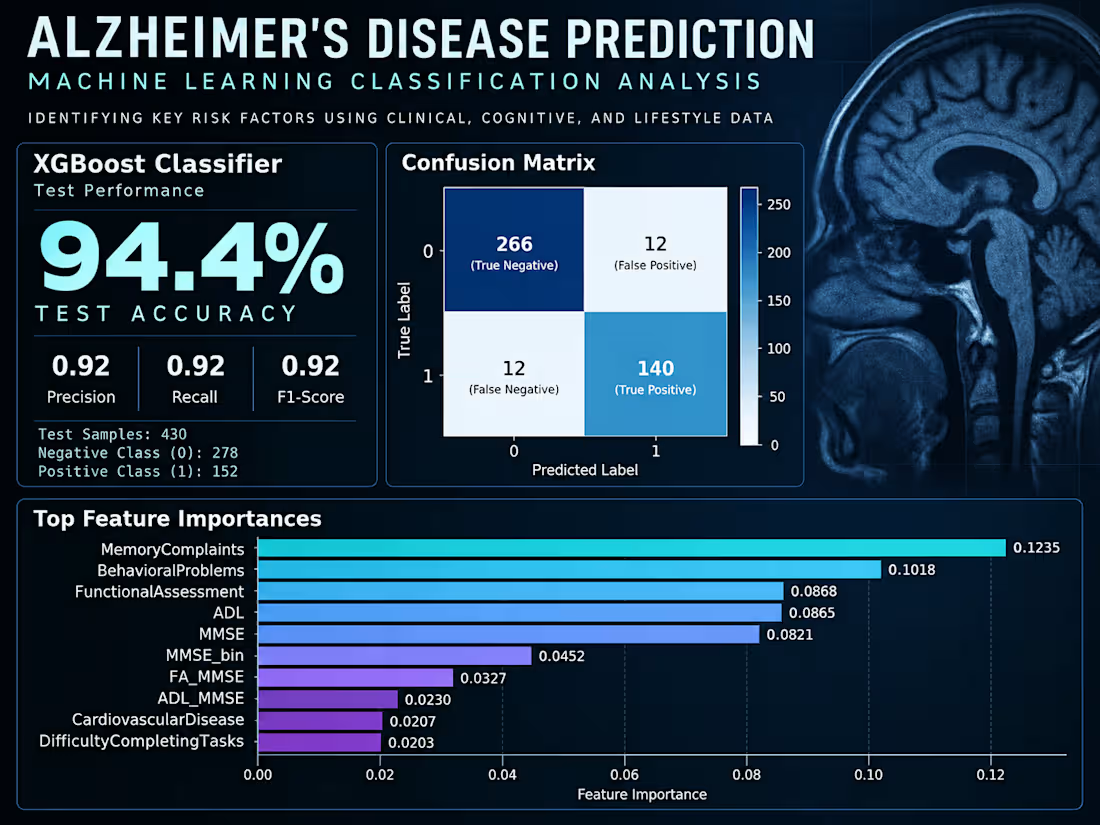
Developed a machine learning classification model to predict Alzheimer’s disease diagnosis using clinical, cognitive, behavioral, and lifestyle data. The project included exploratory data analysis, feature engineering, class-imbalance handling, model training, and performance evaluation.
The final XGBoost model achieved 94.4% test accuracy, with 0.92 precision, recall, and F1-score for the positive diagnosis class. Feature-importance analysis identified memory complaints, behavioral problems, functional assessment, activities of daily living (ADL), and MMSE scores among the strongest predictive features.
The project demonstrates an end-to-end machine learning workflow—from understanding relationships within the data to evaluating and interpreting a predictive model.
0
11
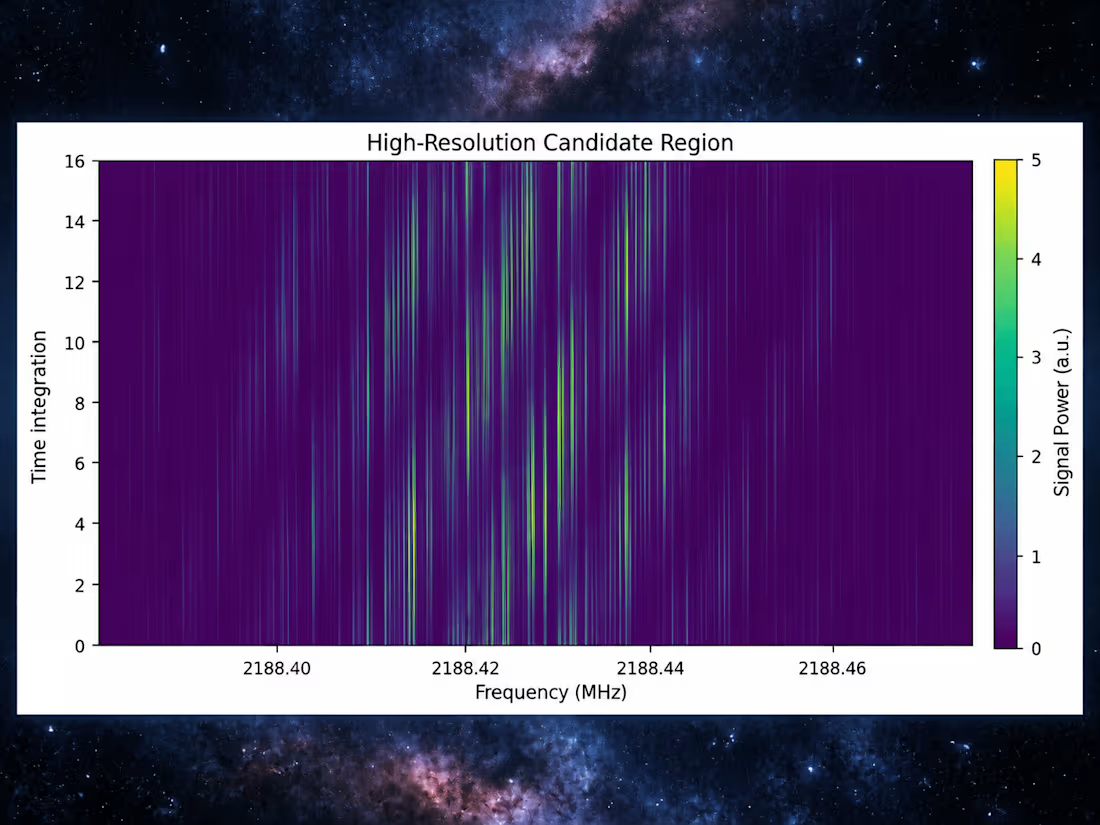
Developed a Python-based scientific analysis pipeline for exploring radio astronomy data and identifying potentially interesting signal structures. The project processes high-resolution spectrogram data, measures signals relative to local noise, and evaluates candidates using characteristics such as persistence, intermittency, bandwidth, and frequency drift.
0
17