Results that are similar to your search
Similar results
Expert in reliable web scraping and data extraction for dynamic websites, eCommerce, directories, marketplaces, and business platforms. Experienced with Python, Playwright, Selenium, Scrapy, BeautifulSoup, Requests, APIs, proxies, browser automation, and data pipelines to collect, clean, validate, and export structured data into CSV, Excel, JSON, databases, or APIs with robust error handling and scalable workflows.
0
196
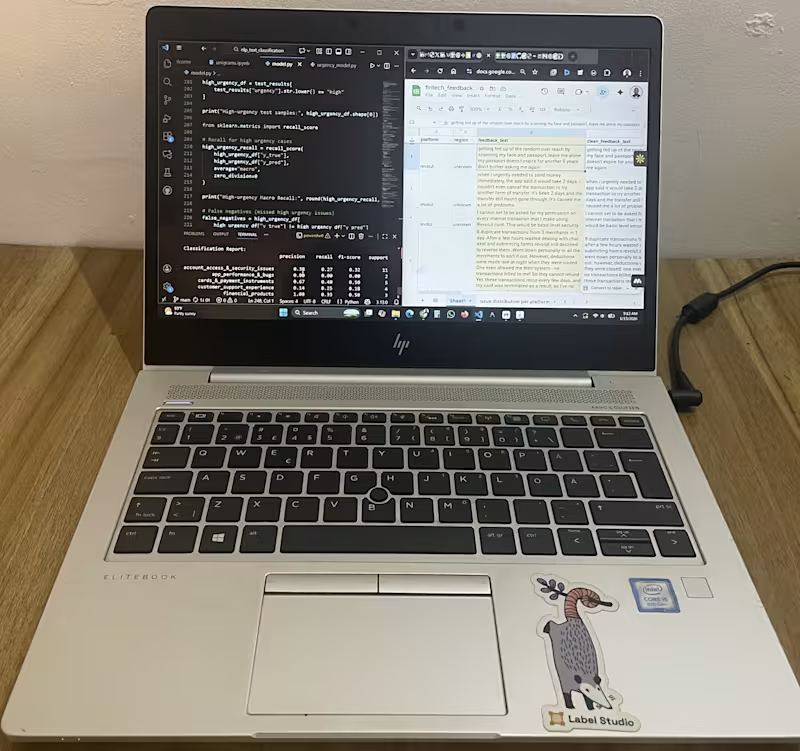
Context-Aware Fintech User Feedback Classification & Urgency Detection
Most feedback tools stop at sentiment; positive or negative. This project goes further by building a decision-driven NLP system that classifies fintech user feedback by issue type and detects operational urgency, enabling smarter triage and escalation.
What was built:
Two machine learning models trained on manually collected and annotated app store reviews from real fintech platforms like Revolut, Wise, and Monzo:
Issue Classifier: categorizes feedback into 9 classes including transaction issues, account security, KYC, refunds, app performance, and fraud
Urgency Detector: binary classifier that flags high-risk feedback requiring immediate attention, optimized for recall to minimize missed critical cases
1
197
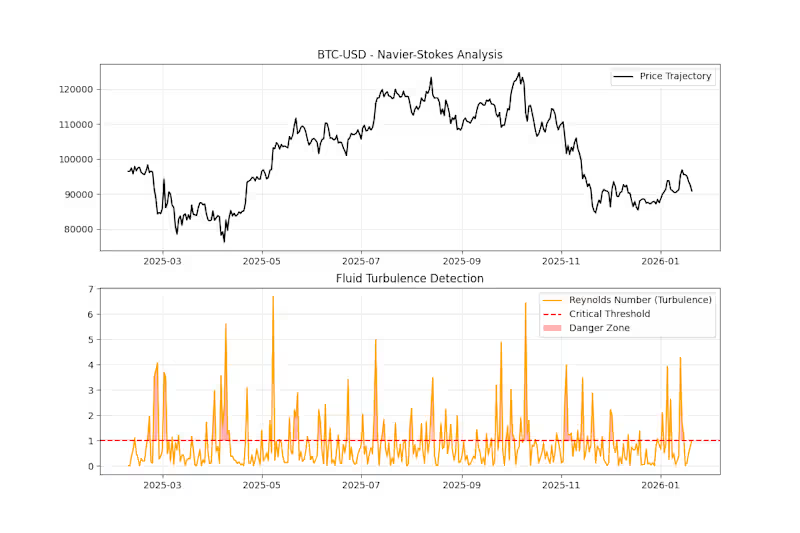
This isn't Finance. It's Physics.
Markets are fluids. Price is velocity. Crash is turbulence.
While you stare at RSI, I am calculating the Laminar Flow.
My S.C.A. Protocol applies Navier-Stokes equations to capital.
If you understand this graph, you know why we need to talk.
The Second Quantum Revolution is here.
0
86
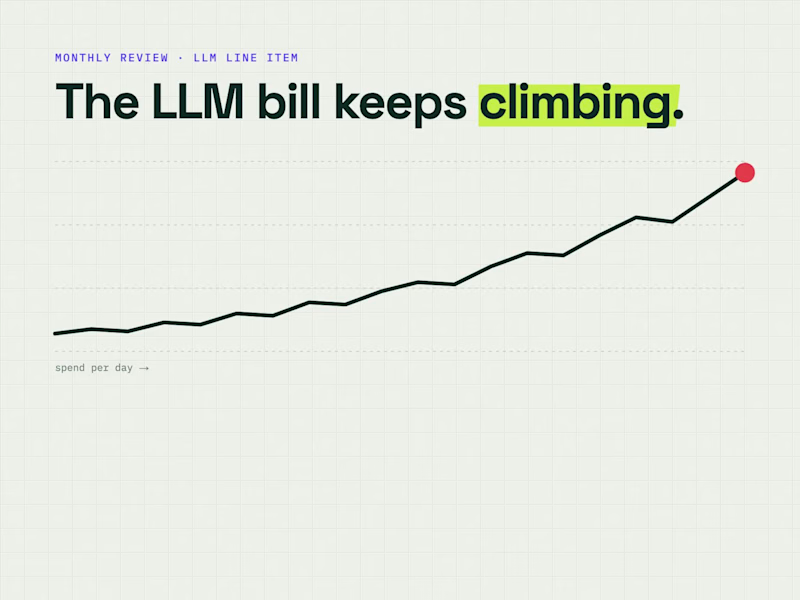
Teams running LLM features in production watch the bill climb and can't say why. Which feature is driving it? Which model? How much goes to retries? Most optimisation advice is a percentage nobody actually measured.
llm-audit is a command-line toolkit I built to answer those questions with evidence.
HOW IT WORKS
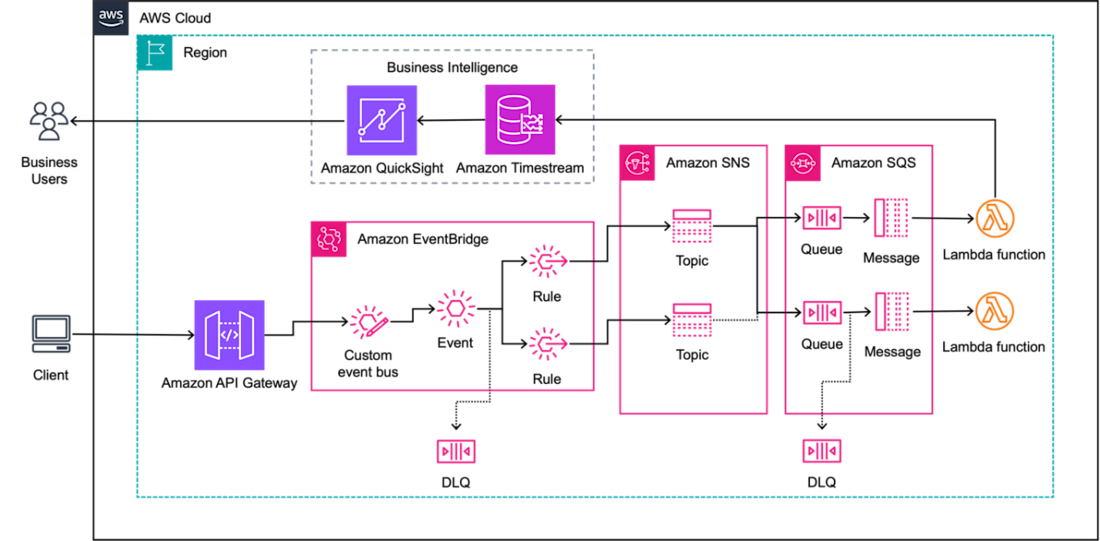
→ Ingest: OpenTelemetry GenAI traces, Langfuse data, or usage exports from OpenAI and Anthropic, loaded into one DuckDB table.
→ Analyze: 16 deterministic checks, 8 for cost (unused prompt cache, model overkill, duplicate calls, context bloat, retry waste, off-peak eligible work and more) and 8 for reliability (error rates, latency, rate limiting, single-provider risk and more).
→ Backtest: replays the workload with each fix switched on alone, then compares predicted and measured savings.
→ Report: one HTML file with ranked findings. Each finding has its evidence query, a fix and a confidence level.
WHAT MAKES IT DIFFERENT
• Content-free. It works from prompt hashes and token counts only, so prompt text never has to leave the client.
• No unmeasured claims. A saving is either measured by the backtest or labelled as an estimate. A fix that lowers quality is marked rejected, even when it saves money.
• Honest gaps. Checks that can't run on the data are listed with the reason, not quietly dropped.
THE PART I'M PROUDEST OF
My first paid backtest failed its own checks: 75% recall and 103% savings error. Instead of tuning the numbers, I debugged the harness. The test runs were sharing the provider's prompt cache, so they weren't independent. A fresh marker per run fixed it, and the re-run confirmed the isolation (0.0 cache hits where there had been up to 1.0).
FIELD-TESTED ON MY OWN APP
I audited AI Lab, my public Q&A app over the EU AI Act and GDPR. Finding zero: the app kept no per-call record at all. My merged PR added a content-free, per-attempt trace. The audit then showed that the evaluation judges took about two thirds of the spend, so scoring answers cost twice as much as producing them.
BUILT LIKE THE AUDIT IT SELLS
915 tests passing · dependencies pinned with hashes · $0.97 total LLM spend for the whole build, under a $15 cap enforced in code.
The demo workload is synthetic and the field run covers one app, so no percentage here applies to your bill. An audit of your own data is the only way to find out. A good starting point is a Bill Snapshot: send your usage exports and get ranked findings back in 48 hours.
#LLMOps #FinOps #AIEngineering #GenAI #LLM #AICostOptimization #Observability #OpenTelemetry #Python #DuckDB #AIAudit #PrivacyByDesign
0
133
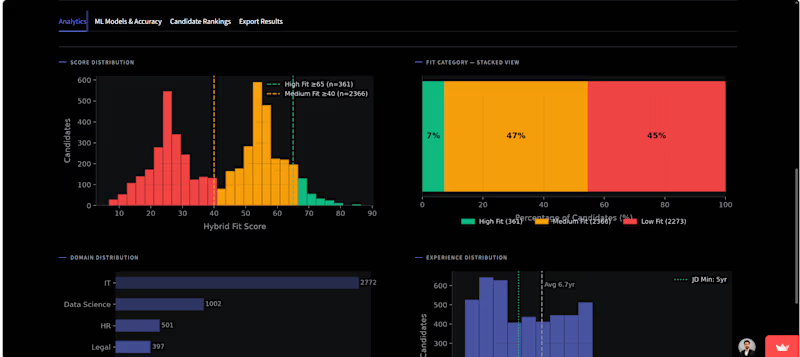
Hybrid NLP AI Resume Screener
Developed a production-grade AI automation pipeline to replace subjective resume screening. Engineered an explainable AI architecture merging Rule-Based linguistic heuristics (60% weight) with TF-IDF cosine similarity (40% weight). Capable of processing and ranking over 5,000 records in seconds.
1
1
238
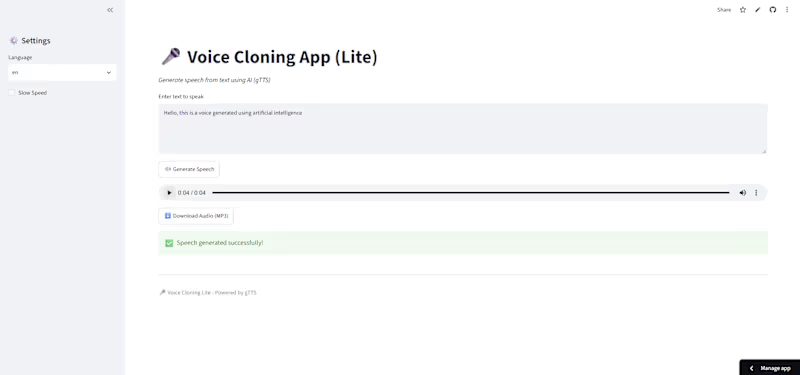
Voice Cloning Lite: Lightweight Text-to-Speech Web App
Built a lightweight, zero-cost text-to-speech application that converts text into downloadable audio across 60+ languages. Designed as a practical, free alternative to premium voice synthesis APIs—prioritizing accessibility and zero cloud costs over premium voice realism.
Engineering Decisions & Trade-offs:
Free-Tier Architecture: Integrated Google Text-to-Speech (gTTS) to eliminate API costs and ensure the app remains permanently free to use. This comes with a trade-off: voice output is functional and clear, but slightly robotic compared to premium paid alternatives (e.g., ElevenLabs, Coqui XTTS).
Multi-Language Support: Enabled text-to-speech across 60+ languages with adjustable speed control.
Audio Export: Implemented MP3 generation and download functionality, allowing users to save synthesized audio directly from the browser.
Production Deployment: Deployed on Streamlit Cloud with graceful error handling for text length limits and network issues.
Tech Stack: Python, Streamlit, gTTS, HTML/CSS.
0
39