Projects using Grafana in PakistanProjects using Grafana in Pakistan🚀 Introducing GraphBridge – Turn JSON into Grafana Dashboards
One thing I've noticed while working on different projects is that applications already have valuable metrics, but getting those metrics into Grafana often requires exporters, custom integrations, or additional setup.
I wanted something much simpler.
So I built GraphBridge.
The idea is straightforward:
Your Application
↓
Send JSON
↓
GraphBridge
↓
Prometheus
↓
Grafana
Instead of writing custom exporters, your application simply sends JSON metrics to GraphBridge.
For example:
{
"active_users": 85,
"orders_today": 42,
"revenue_today": 9840,
"failed_jobs": 3,
"latency_ms": 210
}
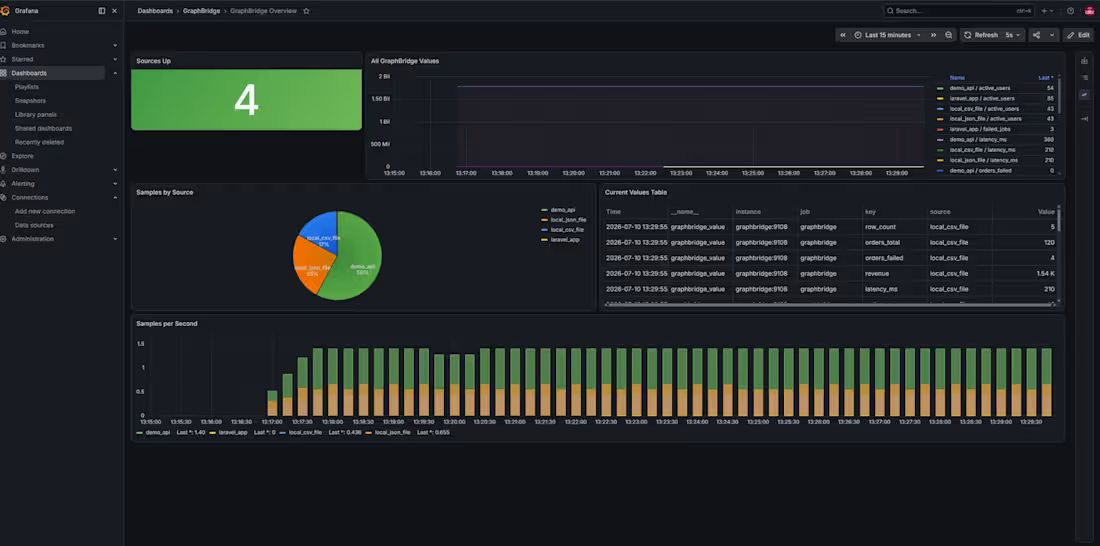
GraphBridge automatically converts the data into Prometheus metrics, making it immediately available for Grafana dashboards.
Current features
✅ JSON Webhook API
✅ REST API polling
✅ JSON & CSV data sources
✅ Prometheus /metrics endpoint
✅ Docker Compose deployment
✅ Auto-configured Grafana dashboard
✅ Example integrations for Laravel, FastAPI, Node.js, and custom applications
Possible use cases
• Application monitoring
• Queue & background job metrics
• Business dashboards
• API performance monitoring
• FFmpeg streaming statistics
• IoT sensor metrics
• Internal analytics
• Custom operational dashboards
The goal is simple:
Send JSON. Visualize everything.
This is the first public MVP, and I'm planning to continue improving it with additional integrations and monitoring templates.
I'd love your feedback and suggestions!
⭐ GitHub:
https://lnkd.in/dAYdNJxg 🚀 Completed a Kubernetes Monitoring Project with Prometheus & Grafana
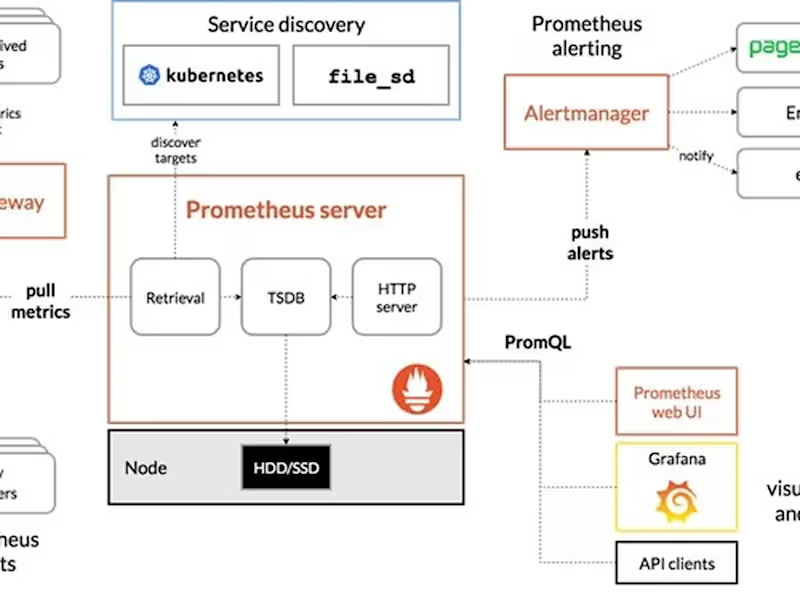
As part of my DevOps learning journey, I completed a hands-on Kubernetes monitoring project where I deployed and monitored a Kubernetes environment using Helm, Prometheus, and Grafana.
🔧 Technologies Used:
• Kubernetes & Minikube
• Helm
• Prometheus
• Grafana
• Node Exporter
• Kube State Metrics
📌 What I implemented:
• Deployed Prometheus and Grafana using Helm
• Monitored Kubernetes pods and services
• Collected node and cluster metrics
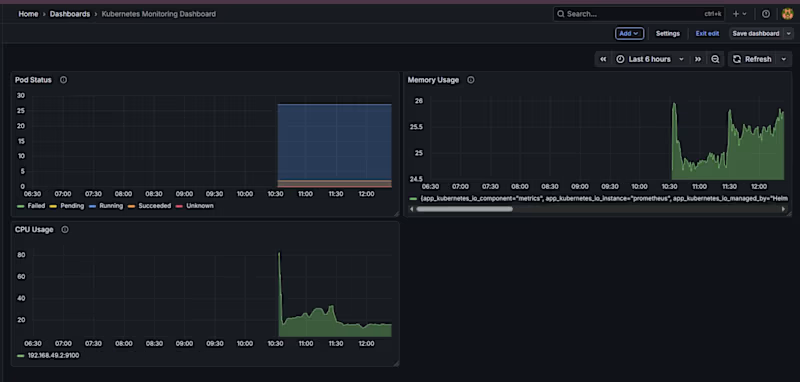
• Created a Grafana monitoring dashboard
• Monitored CPU, memory, and pod status
• Created PromQL queries for monitoring
• Configured a High CPU Usage alert (CPU > 80%)
• Verified deployments using kubectl get pods, kubectl get svc, and helm list
📸 Screenshots below show the actual implementation, including Kubernetes resources, Helm releases, Grafana dashboard, and alert configuration.
This project helped me strengthen my understanding of Kubernetes monitoring, observability, Prometheus, Grafana, Helm, and alerting
Currently continuing my journey toward becoming a Junior DevOps Engineer, focusing on Kubernetes, CI/CD, cloud technologies, monitoring, and automation.
hashtag#DevOps (https://www.linkedin.com/search/results/all/?keywords=%23devops&origin=HASH_TAG_FROM_FEED) hashtag#Kubernetes (https://www.linkedin.com/search/results/all/?keywords=%23kubernetes&origin=HASH_TAG_FROM_FEED) hashtag#Prometheus (https://www.linkedin.com/search/results/all/?keywords=%23prometheus&origin=HASH_TAG_FROM_FEED) hashtag#Grafana (https://www.linkedin.com/search/results/all/?keywords=%23grafana&origin=HASH_TAG_FROM_FEED) hashtag#Helm (https://www.linkedin.com/search/results/all/?keywords=%23helm&origin=HASH_TAG_FROM_FEED) hashtag#Monitoring (https://www.linkedin.com/search/results/all/?keywords=%23monitoring&origin=HASH_TAG_FROM_FEED) hashtag#Minikube (https://www.linkedin.com/search/results/all/?keywords=%23minikube&origin=HASH_TAG_FROM_FEED) hashtag#CloudComputing (https://www.linkedin.com/search/results/all/?keywords=%23cloudcomputing&origin=HASH_TAG_FROM_FEED) hashtag#DevOpsJourney (https://www.linkedin.com/search/results/all/?keywords=%23devopsjourney&origin=HASH_TAG_FROM_FEED)