The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

Verdict QA is an AI quality assurance and evaluation tool focused on LLM evaluation, AI response assessment, data annotation, quality control, rubric design, instruction following, factual accuracy, relevance, and content review. It explores structured scoring and feedback to support AI model testing, benchmarking, response ranking, and continuous improvement across AI systems.


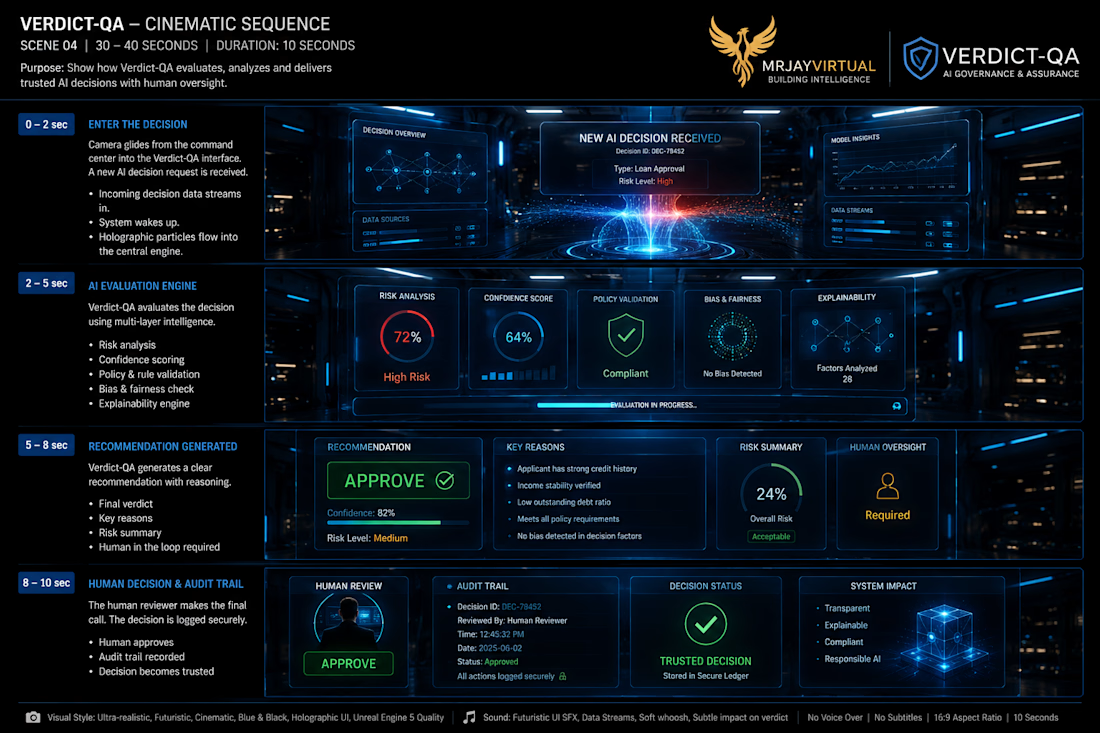

For response ranking, I'd keep factual accuracy separate from style so a polished but incorrect answer can't win on the overall score. Can Verdict QA mark a factual error as a hard failure even when the other rubric scores are high?
The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started







Related posts

Interactive AI Analytics Dashboard | SaaS Product Design
A modern, animated AI-powered eCommerce analytics dashboard designed to help businesses track sales performance, monitor revenue, understand customer behavior, and make data-driven decisions.
The design combines a clean SaaS interface, intuitive data visualization, interactive dashboard elements, and smooth animations to create a more engaging user experience. Every section is designed to make complex analytics easier to understand while maintaining a professional, scalable, and user-friendly layout.


Super clean work!

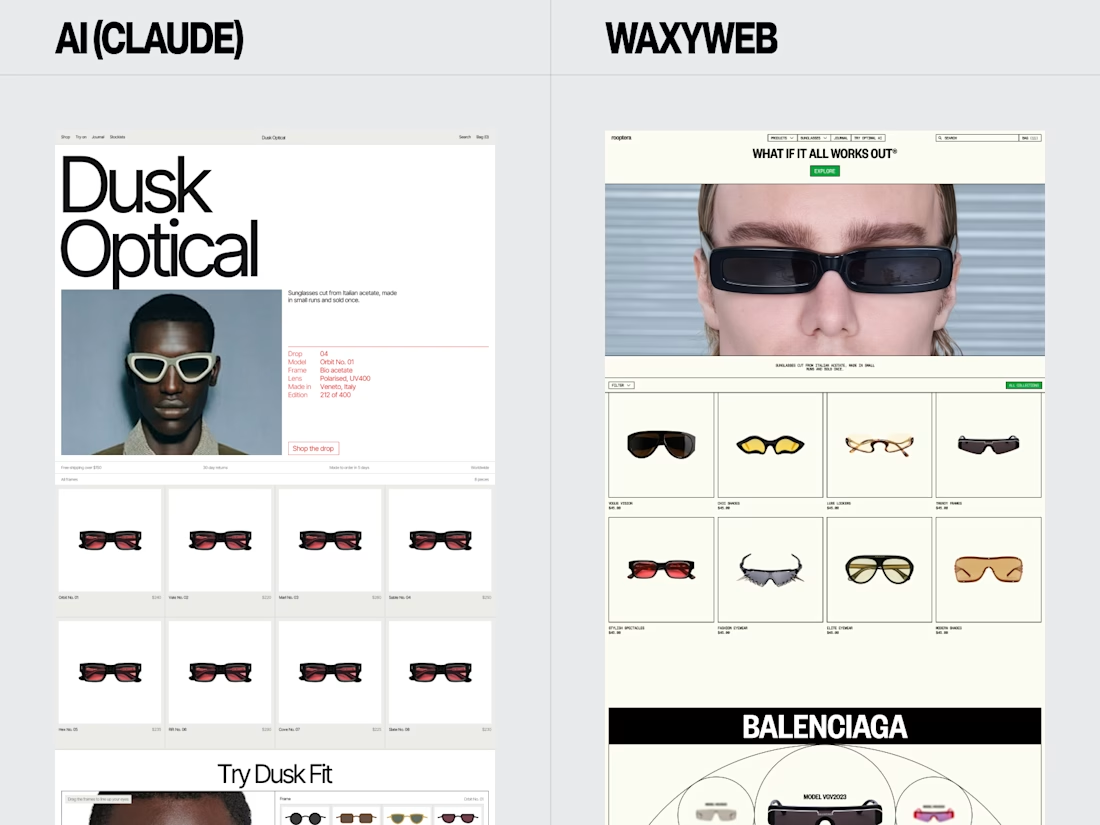
Eyewear Ecommerce Website Redesign — AI vs. WaxyWeb
A side-by-side design comparison exploring two approaches to an online eyewear store.
The WaxyWeb redesign focuses on the relationship between product presentation, collection browsing, editorial imagery, and the store’s visual identity.
Design considerations:
Eyewear product presentation
Ecommerce layout and hierarchy
Collection and product discovery
Fashion-focused visual direction
Consistent online shopping experience
For fashion, eyewear, and lifestyle brands, the goal is to create a store that presents products clearly while giving the brand a recognisable visual presence.
Website design and development: www.waxyweb.com

WaxyWeb

Colours that refuse to mix, combed on water in a stone trough. The Mordant Vault guards colours that refuse to blend. Float them on water. Comb them. Never, under any circumstance, stir.
I built this project to test Colours that refuse to mix, combed on water in a stone trough. The Mordant Vault guards colours that refuse to blend. Float them on water. Comb them. Never, under any circumstance, stir. The core engineering challenge was sustaining uncompromised 60 FPS rendering using WebGL / GLSL Shaders while handling continuous user interaction without framework overhead.
WHAT I WAS TESTING:
I focused on two core engineering benchmarks:
Precision implementation of shader marbling under continuous interactive user input
Sustained 60 FPS render performance and zero-dependency browser execution
THE TECHNICAL SIDE:
Engineered directly in the browser with WebGL / GLSL Shaders, Canvas2D, Shader marbling. The application runs without third-party frameworks or build-step dependencies, using hardware-accelerated rendering and custom event loops to achieve zero-latency response.
Everything executes in the browser using WebGL / GLSL Shaders, Canvas2D, Shader marbling. No third-party frameworks, no heavy runtime bundles, and zero external tracking.
WHAT I LEARNED:
Balancing the mathematical rigors of shader marbling with tactile browser interaction required tuning event throttling and memory allocation to eliminate all garbage collection stutters.
Finding the sweet spot between mathematical precision and frame budget took careful profiling, but the result runs at a steady 60 FPS even on modest hardware.
TRY IT YOURSELF:
The live build is deployed on Netlify. Open it in your browser, test the controls, and observe the render response times.
If you are building high-performance 3D, physics, or creative web systems and want to collaborate, reach out here on Contra.


Anyone who wants the source code can check this in my JSFiddle : https://jsfiddle.net/Saminsami/ezy9k74t/4
jsfiddle.net
Mordant - Samin Sami
Mordant - Samin Sami - a HTML example you can edit and run in your browser on JSFiddle.