The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

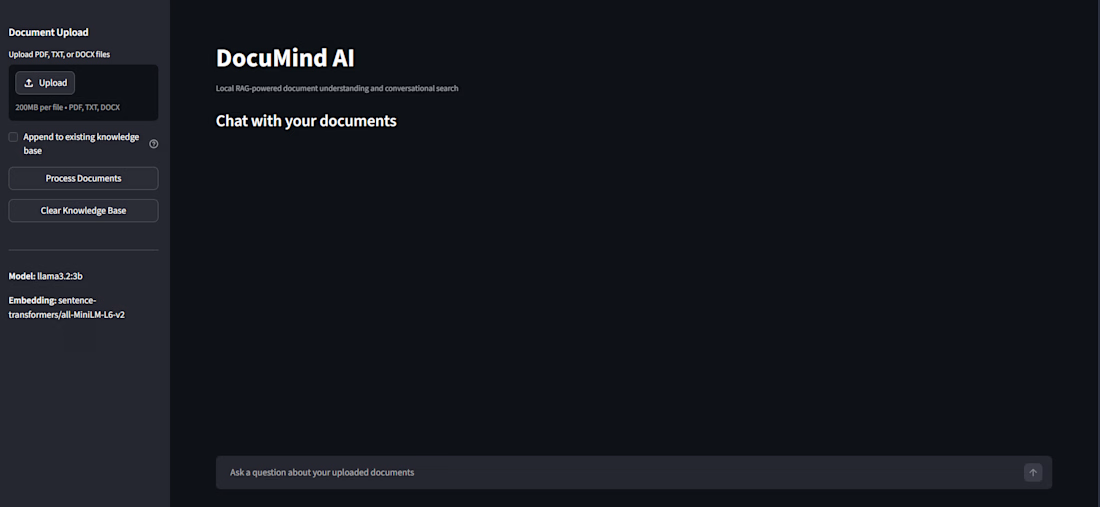
DocuMind AI is a local-first Retrieval-Augmented Generation (RAG) application that lets users upload documents and ask grounded questions about their content.
Built with Python, Streamlit, LangChain, FAISS, SentenceTransformers, and Ollama, the app supports PDF, DOCX, and TXT files. It processes uploaded files into semantic chunks, generates embeddings, stores them in a persistent FAISS vector index, and retrieves the most relevant context for each question before generating a response with a locally hosted LLM.
Key capabilities include document ingestion, vector search, conversational context, source-file references, knowledge-base rebuilding, and Docker-based deployment. The project demonstrates an end-to-end GenAI workflow with a modular architecture designed for local experimentation and privacy-conscious document querying.
Tech stack: Python, Streamlit, LangChain, FAISS, SentenceTransformers, Ollama, Docker.


The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started





Related posts


Messy Data In. Clearer Decisions Out. 📊
Over the past year, I've noticed most businesses don't struggle because they lack data — they struggle because that data never turns into a decision.
That's the gap I work in:
→ Cleaning and analyze data with Python & R
→ Turning findings into investor-ready pitch decks
→ Polishing the final write-up so nothing gets lost in translation
If your team has data sitting in spreadsheets with no story attached, or a pitch deck that needs to actually land — that's exactly where I can help.
Open to projects. Let's talk 👇


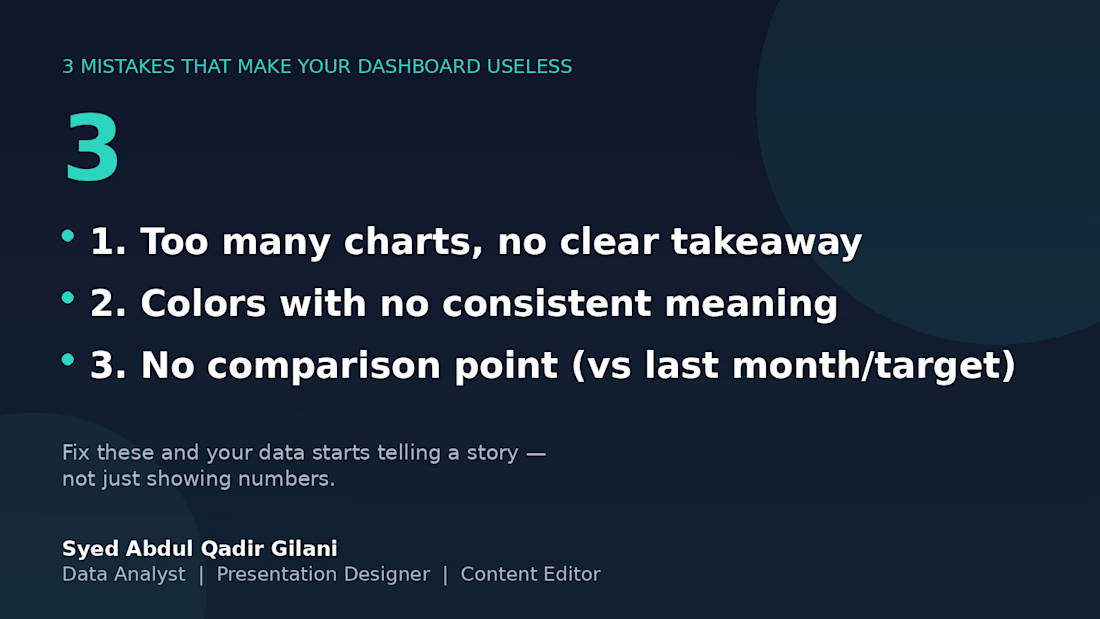
3 mistakes that will eventually make this board useless. 📉
I've reviewed several client dashboards over the years, and the same 3 problems show up over and over:
1️⃣ Too many charts, no clear takeaway — if I can't tell what to do after looking at it, it's decoration, not a dashboard.
2️⃣ Colors with no consistent meaning — red means "unacceptable" on one chart and "category 3" on the next. Pick a system and stick with it.
3️⃣ No comparison point — a number alone means nothing. "Revenue: $12,480" tells you nothing. "Revenue: $12,480 (+18% vs last month)" tells you everything.
Fix these three, and your data stops being numbers on a page — it starts being something people actually use to decide.
What's the most common dashboard mistake you've seen? 👇

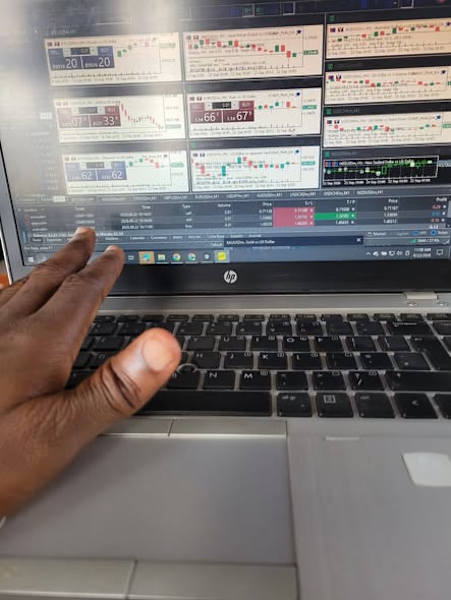
Another late night. Building a quant trading system an agentic model where different AI agents handle research, testing and risk, and none of them is allowed to place a trade on its own.
The hardest part so far? Being honest when the results say "not yet." Most strategies I've tested failed once real costs were included. That's exactly what testing is for.
Keeping The Psychology of Money and The Diary of a CEO close while I figure it out. What are you reading these days?

Curious how you’ve separated the agents from execution. When you say none can place a trade on its own, is that enforced through a separate execution service with fixed risk checks, human approval or both? I’d love to understand where the agent's decision-making ends and the hard rules take over.