The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

AI SDK + RAG chat (Postgres / pgvector)
What is RAG?
RAG stands for retrieval-augmented generation. Instead of hoping the model already "knows" your facts, you retrieve snippets that match the user's question and augment the prompt with that text so generation is grounded in your data.
Why is RAG important?
Large language models only see what they were trained on (plus whatever you put in the context window). That breaks down for private or fresh information: internal docs, product details, notes you typed yesterday, or anything after a model's knowledge cutoff. RAG fixes that by fetching relevant passages at query time and passing them in as context, so answers can stay accurate and attributable to your sources.
A minimal intuition: without extra context, "What's my favorite food?" gets a generic refusal. With retrieved context ("user loves pepperoni + pineapple pizza), the model can answer correctly—because you gave it the fact, not because it remembered you.
Note: Retrieval can be web search, a file store, or anything else. Here I use semantic search over embeddings stored in Postgres. That's one solid pattern, not the only one.


The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Related posts

Hero section for an AI search analytics tool platform.
Animation LIT up the hero section.
Definitely gonna convert "maybe" users to instant "sign-up".
Full landing page WIP, should be finished by tomorrow.


Stunning

Don't just make Ecommerce 2d boring site. Make something that your users remembers😎
built by nextJS, Framer Motion, Lenis, Gsap, TailwimdCSS
Framer Website DesignwebdesignsaaswebsiteNext.jsInteractive DesignWeb DesignFramerVisual Studio Code


AI Textbook with RAG Chatbot
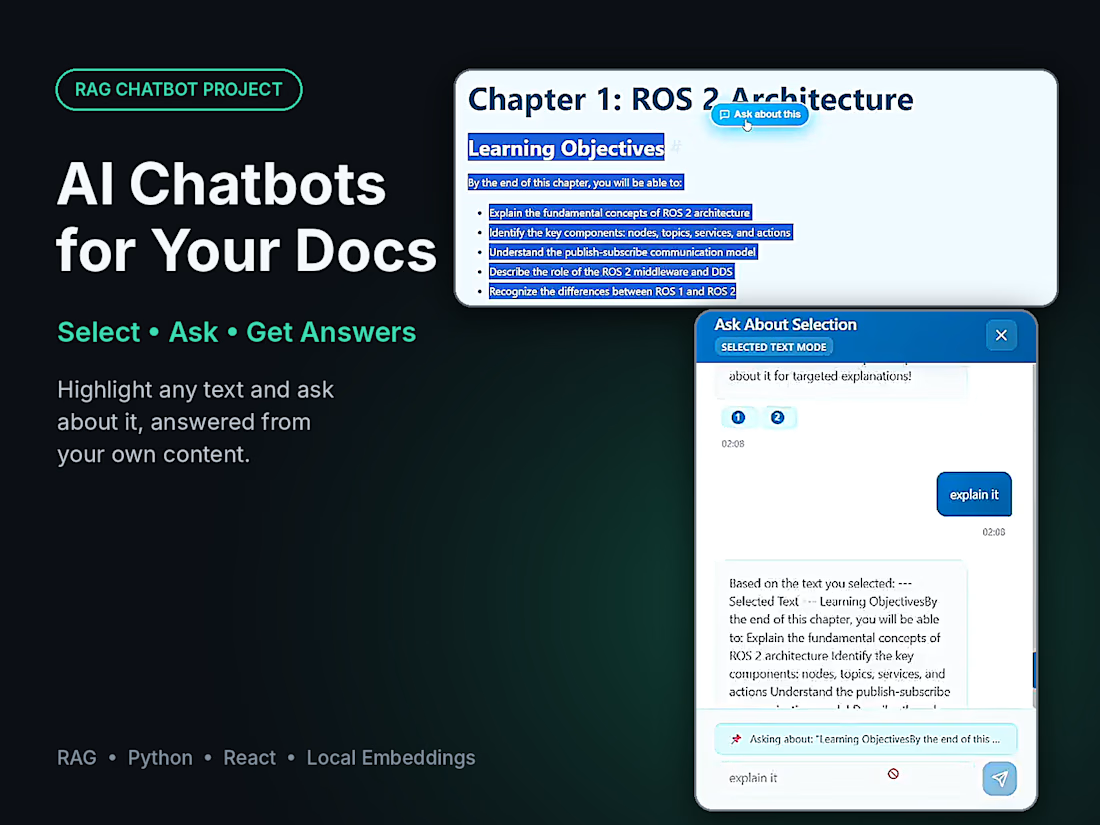
An AI-powered interactive textbook for humanoid robotics, with a built-in RAG chatbot that answers questions from the book’s own content.
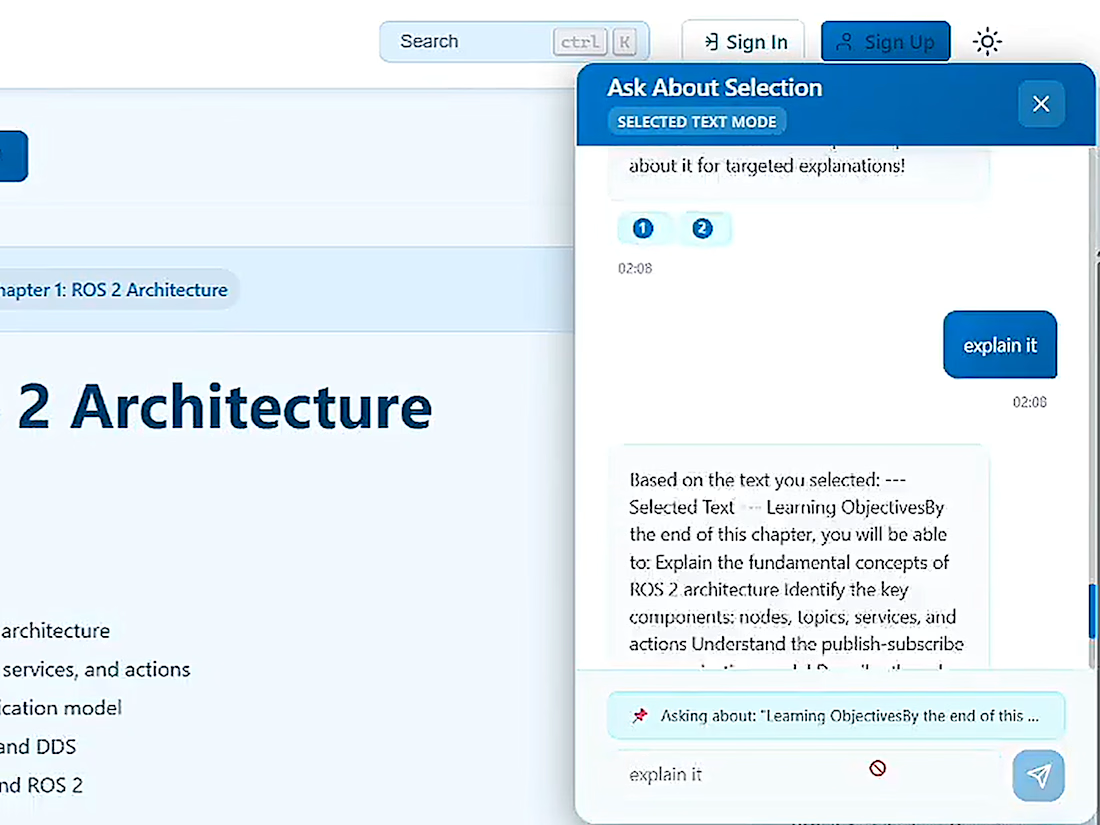
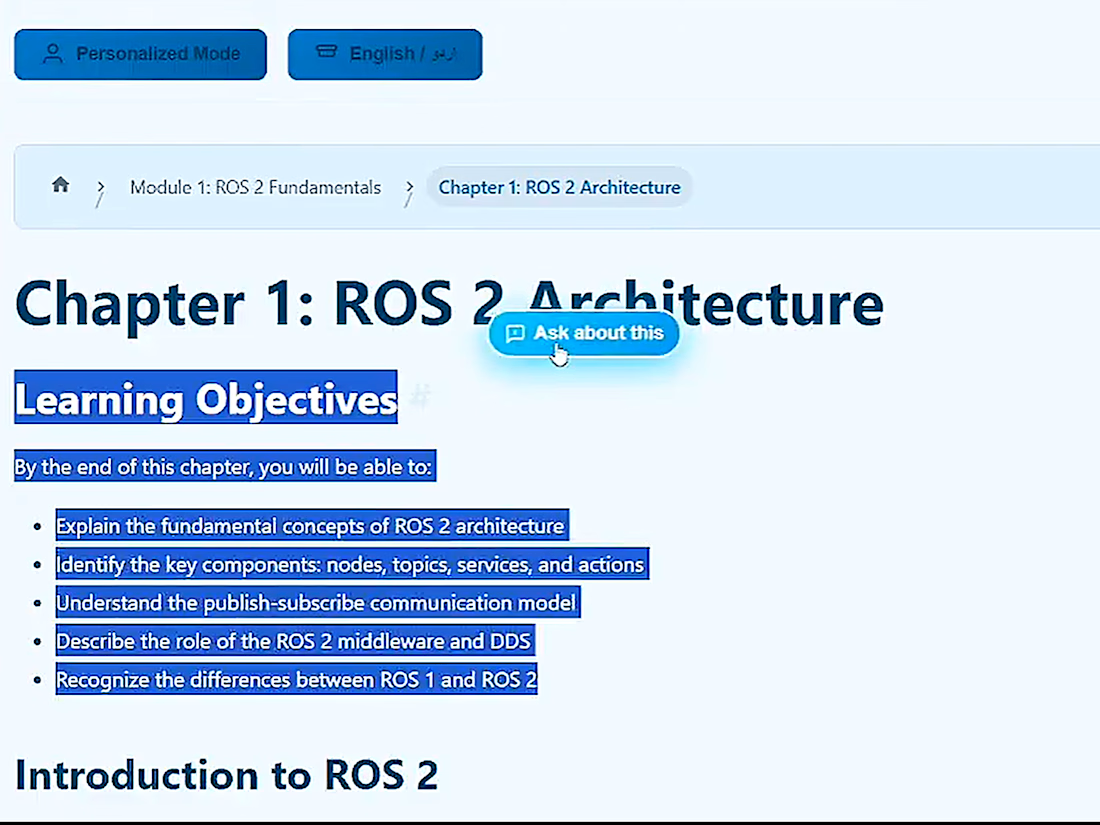
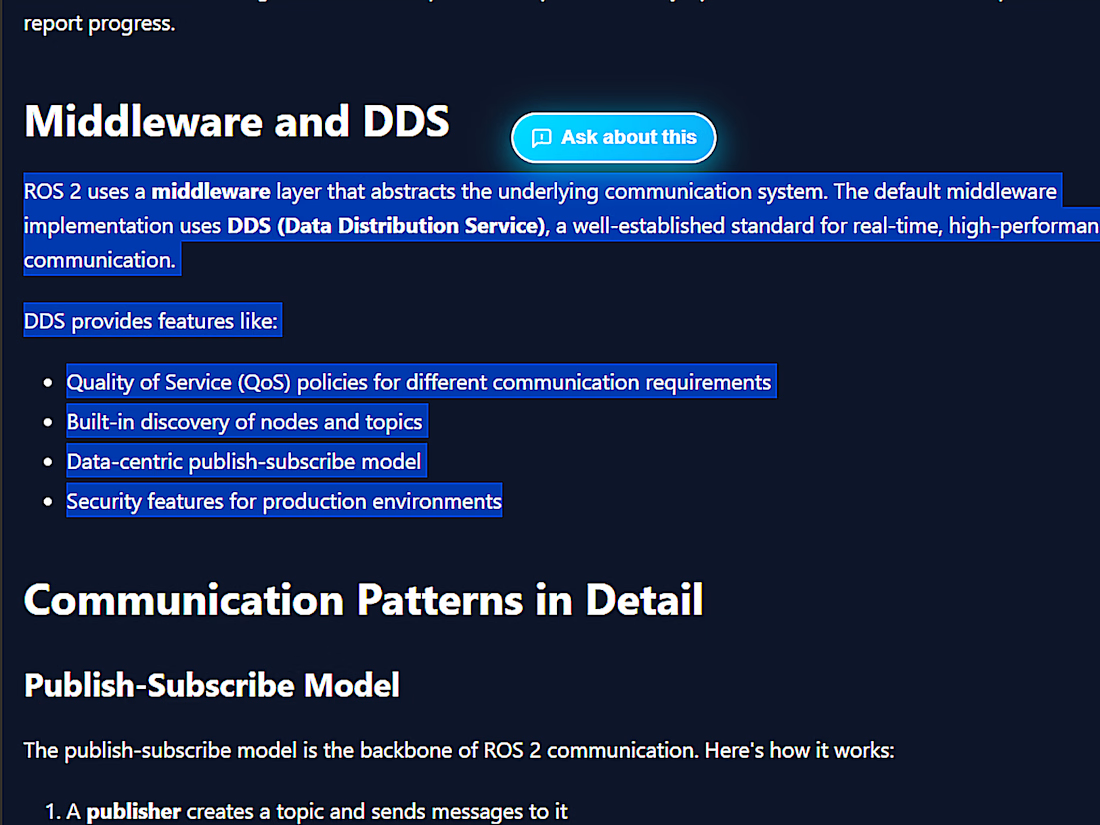
Students can highlight any passage and click “Ask about this” to get an explanation of exactly that section, or open the assistant to ask general questions. Answers stream in real time and include source citations, so readers can check where each answer came from.
Key features:
RAG pipeline grounded in the textbook content
Selected-text mode: ask about any highlighted passage
Streaming answers with source citations
Light and dark mode reading experience
Budget-friendly setup with local embeddings and a free-tier LLM
Built with Python, React and a RAG pipeline with local embeddings.



For selected-text mode, I'd keep the highlighted passage distinct from supporting passages retrieved elsewhere in the book. If a robotics equation uses a symbol defined in an earlier section, can the answer cite that definition as well as the selected equation?