The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

AudioForge — Parameter-Efficient Audio Classification
Built and evaluated an audio-classification pipeline on FSD50K, covering 36K+ training clips across 200 multi-label sound categories.
I compared a CNN trained from scratch against a pretrained Audio Spectrogram Transformer adapted using LoRA.
The LoRA setup trained only 0.52% of the AST’s 86.8M parameters while improving mean Average Precision from 0.302 to 0.557 — an 84% improvement.
Beyond model training, I handled the GPU infrastructure end-to-end: VRAM sizing, AWS EC2 provisioning, quota management, spot-instance fallback, cost-controlled start/stop workflows, and debugging failed training runs with smoke tests before full experiments.
What I worked on
Audio Spectrogram Transformer fine-tuning
LoRA / parameter-efficient training
Multi-label audio classification
PyTorch training and evaluation pipelines
GPU memory and infrastructure optimization
Experiment debugging and validation
Stack: Python · PyTorch · Hugging Face · AWS EC2


The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started





Related posts

Hey Contra!
One more review from my lovely client Sophie 🎉
Happy to work with you!!



Increased revenue opportunities by automating how AI voice-agent calls are captured, analyzed, quality checked, and stored in the CRM.
I built an automated workflow that connects an AI voice agent with Airtable, Google Drive, Gmail, and AI-powered quality analysis.
The workflow receives call data through a webhook, extracts and structures the information, creates a CRM record, retrieves the call recording, uploads the audio for storage and runs an AI quality check on the conversation.
Based on the quality control result, the workflow automatically follows the appropriate path. Qualified conversations can trigger an email notification while the relevant call data and recording are updated in the CRM for future review.


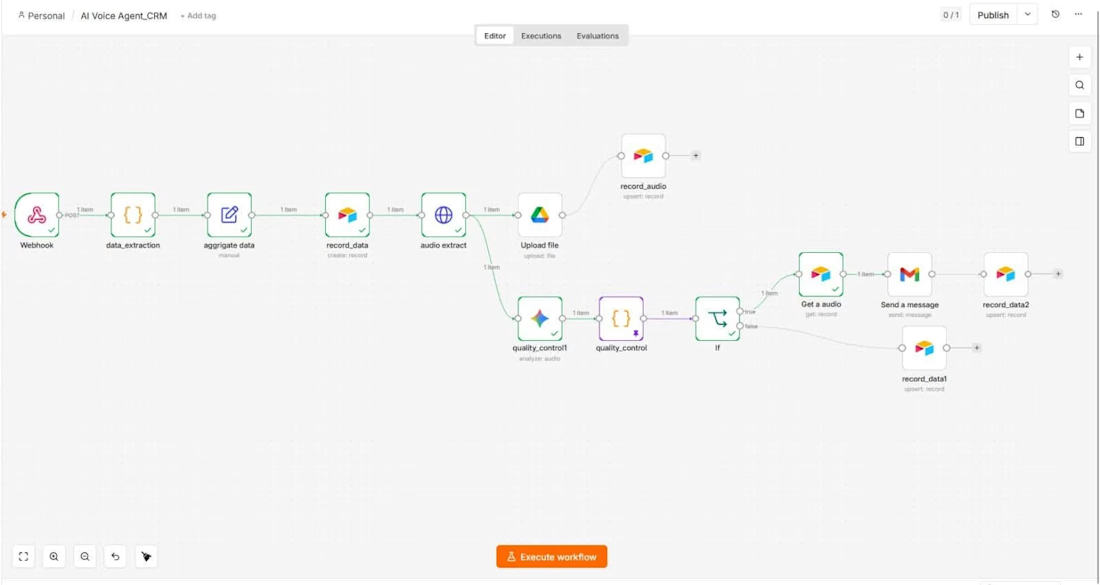

The way the webhook pushes call data straight into Airtable and the CRM removes a lot of manual entry.

Live running HFT Quant Engine with complete automation