The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

I built IAnversic EVAL, a platform focused on evaluating and improving the reliability of AI applications, particularly LLM-powered systems and Retrieval-Augmented Generation (RAG) pipelines.
The project addresses a key challenge in AI engineering: moving beyond subjective assessments of model responses toward systematic, repeatable evaluation. It is designed to help developers assess answer quality, factual grounding, and retrieval performance, identify failure cases, and validate changes before deploying them.
Project outcomes and capabilities:
Designed a dedicated platform for evaluating LLM applications and RAG workflows.
Focused on assessing response quality and the relationship between generated answers and retrieved context.
Established a foundation for repeatable evaluations to compare configurations and identify regressions.
Connected evaluation to practical AI engineering workflows, supporting evidence-based decisions about prompts, retrieval strategies, and model selection.
IAnversic EVAL is part of the broader IAnversic ecosystem, complementing IAnversic RAG with an evaluation-focused approach to building more reliable, measurable, and production-ready AI systems.


The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started


Related posts

Denty — From Consultation to Signed Consent. Built with Base44.
For this #Base44Challenge, I wanted to showcase something beyond a landing page or a beautiful prototype.
A real product. Solving a real problem.
Meet Denty, an AI-powered dental platform designed to simplify clinical documentation and patient consent workflows.
Here's what makes it different.
Instead of manually preparing everything after a consultation, a dentist can upload a transcript and let AI extract the relevant patient information.
The clinician remains in control, reviewing and editing the extracted details before preparing documents.
From there, Denty supports treatment planning, consent form generation, clinical document management, secure signature requests, and downloadable signed PDFs.
It also supports multi-clinic operations, team management, and activity tracking.
Why Base44?
I wanted to move quickly without compromising the product experience.
Base44 helped with application development, data integration, and AI features. But building a usable product required much more than prompts: thoughtful UX, careful design, testing, debugging, and repeated improvements.
Why a 6-minute video instead of 30 seconds?
Because I wanted to demonstrate the product rather than simply show it.
30 seconds can introduce an idea. It cannot meaningfully demonstrate every step of a workflow like this.
In the full recording, you'll see Denty create structured information from a consultation, generate documents, send a signature request, and demonstrate the patient signing process.
This is a functional product, developed for a real-world use case, shared with my client's approval.
We're preparing to launch on Monday.
Full product walkthrough:
https://www.tella.tv/video/startup-design-and-development-project-fo5h9gwr
Built with @Base44.
#Base44Challenge
I'd love feedback from the Contra community, especially on the product experience and clinical workflow.

tella.tv
Startup Design and Development Project 🚀 — Tella
Ans, a designer and developer helping startups build digital products, introduces a very special new project.

Incredible project great job Ans

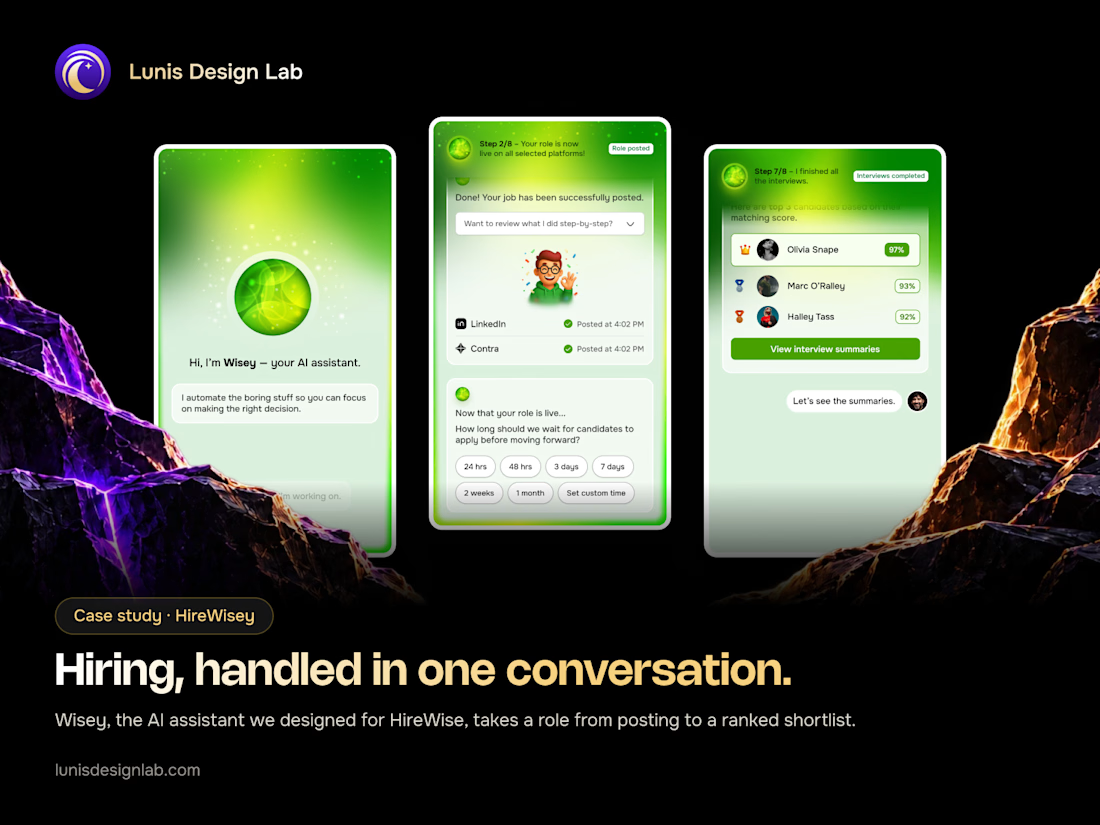
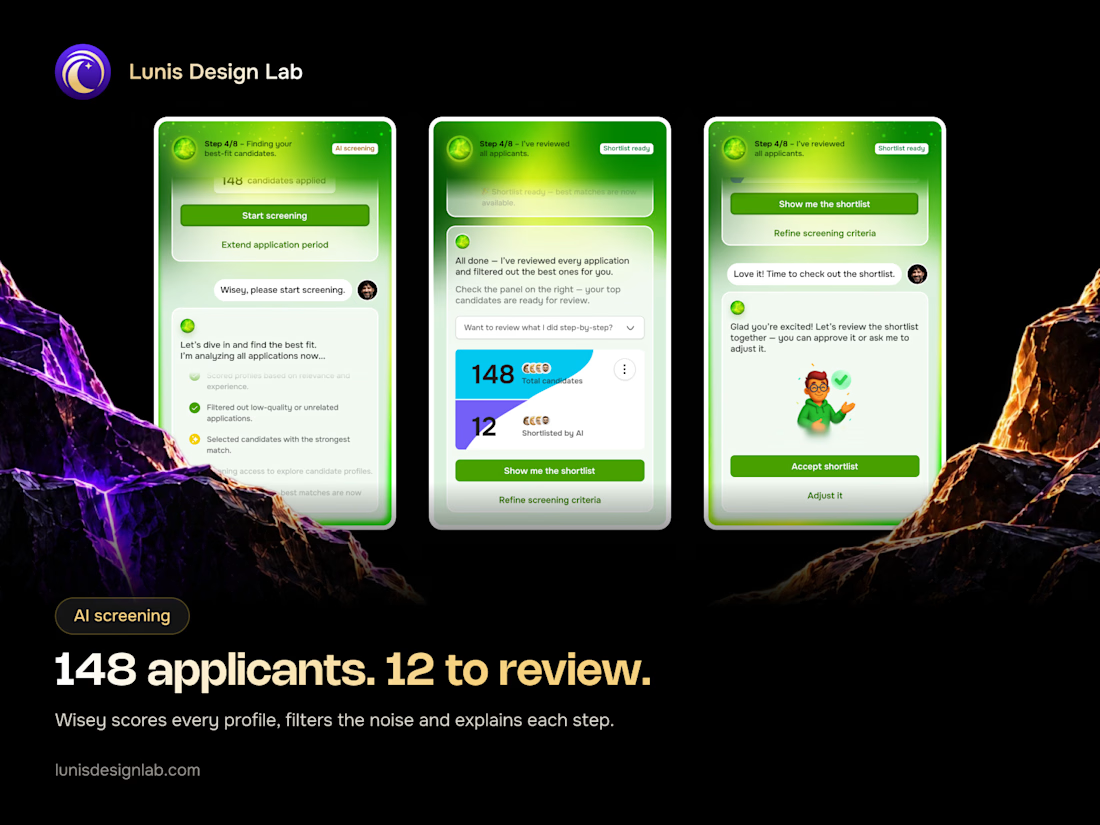
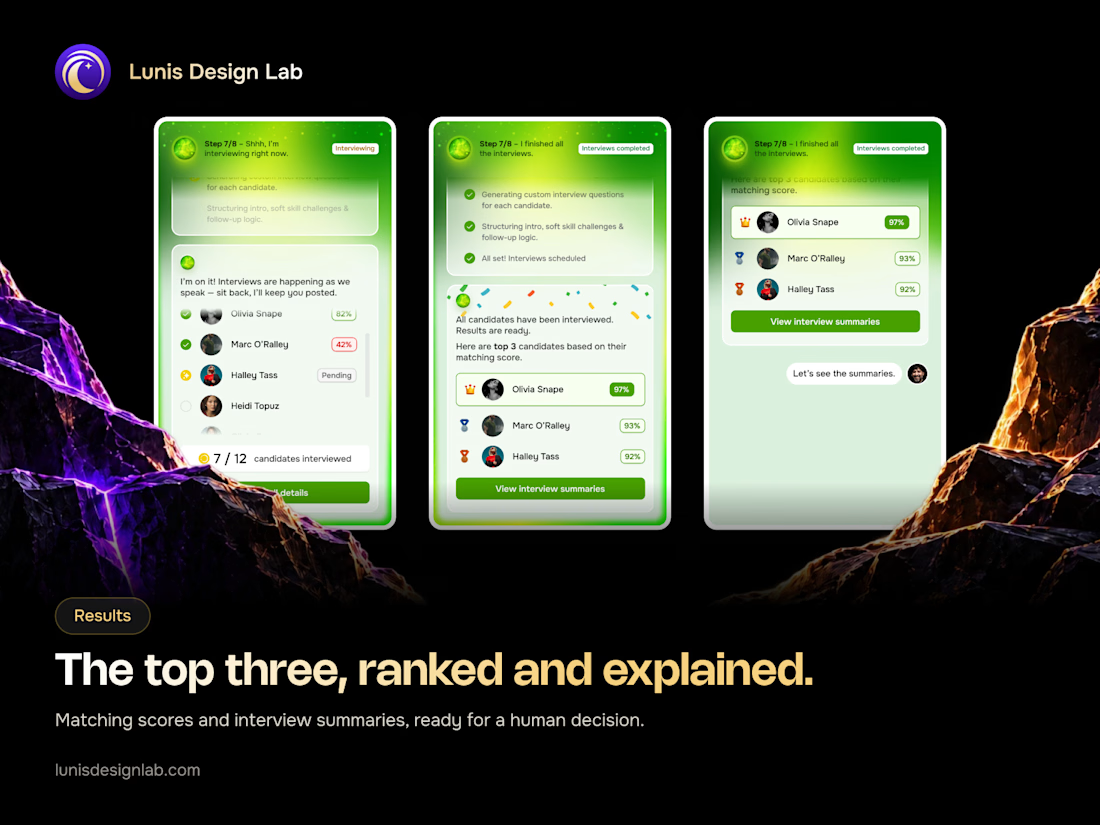
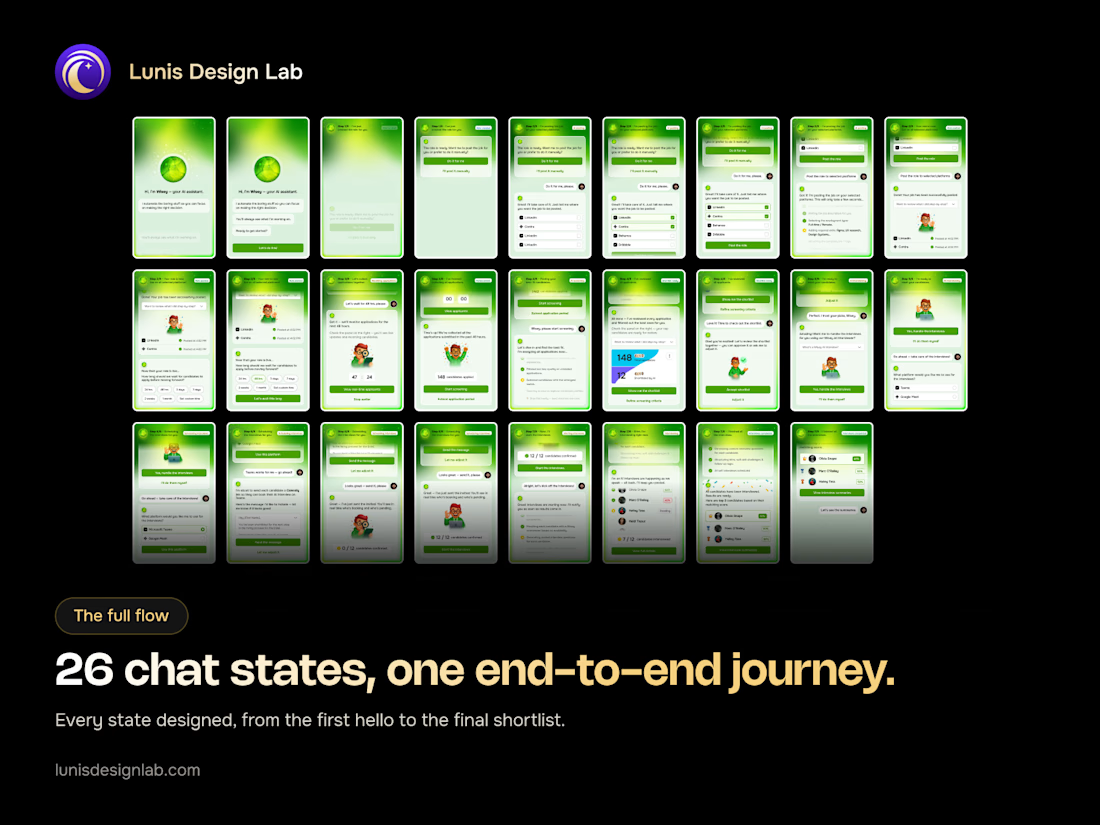
What if AI could handle the entire hiring journey through one conversation?
That’s what we designed with Wisey, the AI assistant behind HireWisey.
26 conversational states, from job posting and candidate screening to AI interviews and the final shortlist.
But the real challenge wasn’t automation. It was trust.
Making every AI decision transparent, understandable, and keeping recruiters in control.
Would you trust AI to handle your hiring process?



Biyiniao (比翼鳥) · SHC-15/36 🦜🦜✨
Which do you prefer — Foil Card 🃏 or 3D Render?

5 voted
83%
1 voted
17%
6 votes
Closed
