The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

Most people don’t actually need more features — they need fewer things breaking at the worst possible moment.
Lately I’ve been focusing on building systems that stay predictable under pressure: clean APIs, stable flows, and logic that doesn’t turn into chaos six months later.
It’s a different kind of work. Less visible at first, but you feel it over time — in speed, in fewer surprises, in things just… working.
That’s usually where the real value hides

This resonates a lot.
The same thing shows up on the operations side—most issues aren’t about needing more tools, but about things quietly breaking under pressure.
When workflows, priorities, and follow-through aren’t structured to hold up over time, everything starts to feel...
The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started





Related posts

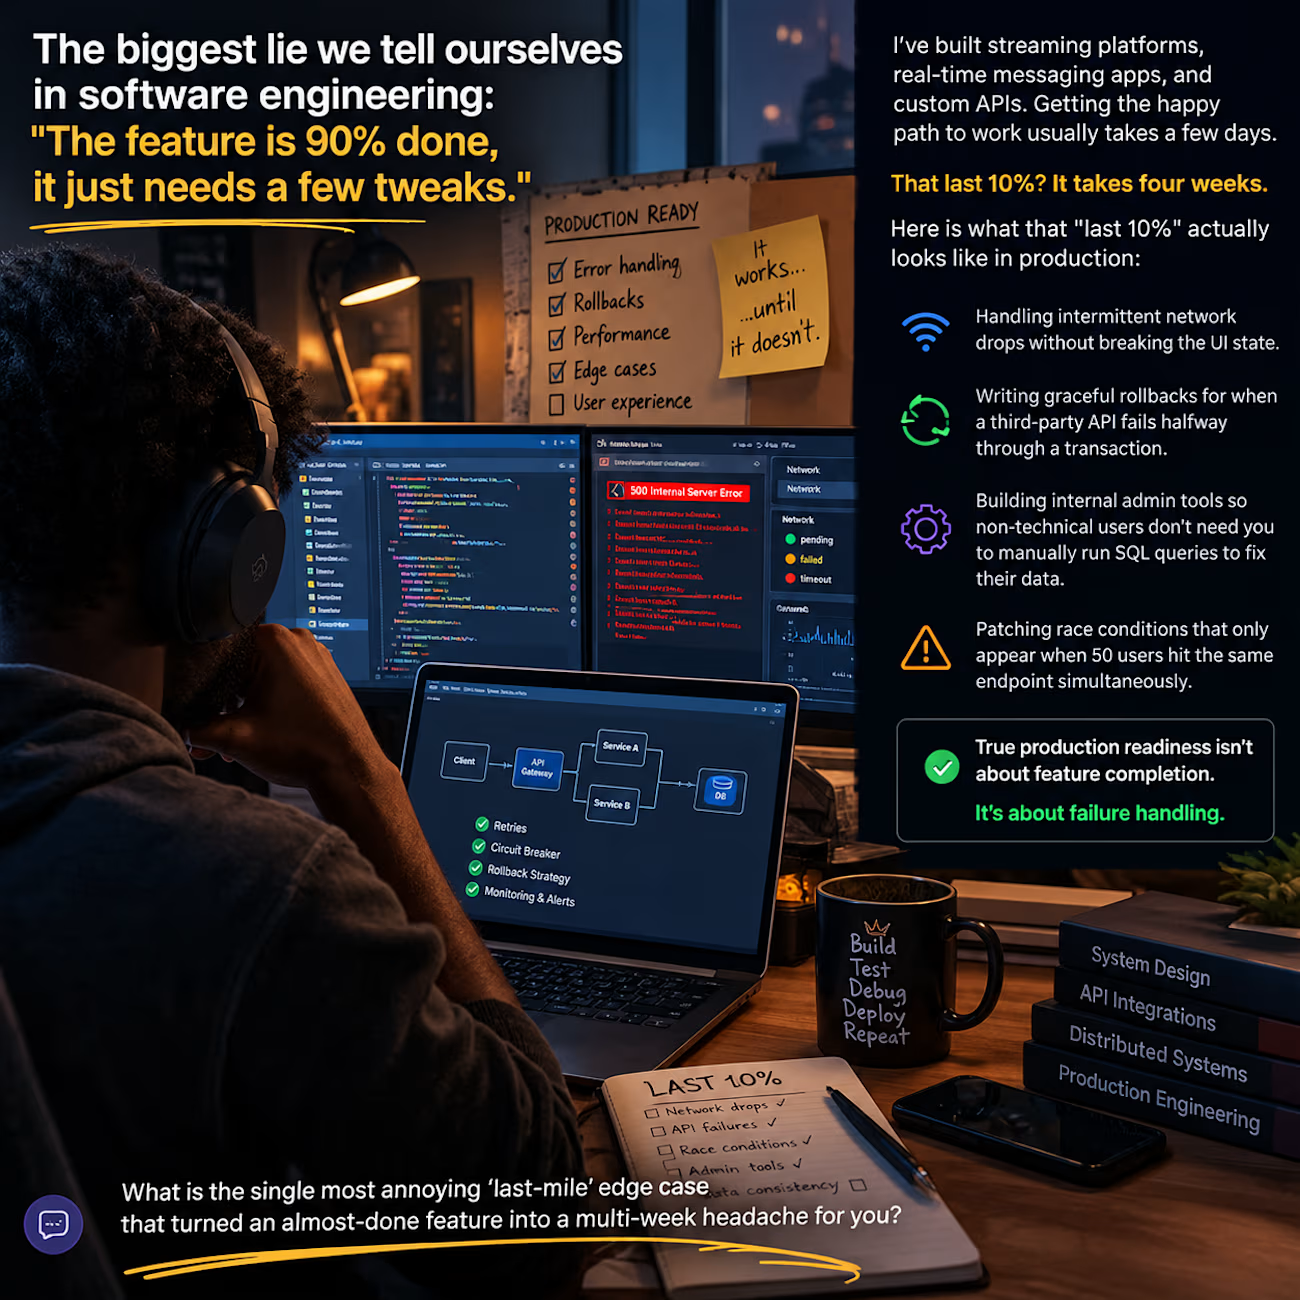
The biggest lie we tell ourselves in software engineering: "The feature is 90% done, it just needs a few tweaks."
I’ve built streaming platforms, real-time messaging apps, and custom APIs. Getting the happy path to work usually takes a few days.
That last 10%? It takes four weeks.
Here is what that "last 10%" actually looks like in production:
• Handling intermittent network drops without breaking the UI state.
• Writing graceful rollbacks for when a third-party API fails halfway through a transaction.
• Building internal admin tools so non-technical users don't need you to manually run SQL queries to fix their data.
• Patching race conditions that only appear when 50 users hit the same endpoint simultaneously.
True production readiness isn't about feature completion. It's about failure handling.
What is the single most annoying 'last-mile' edge case that turned an almost-done feature into a multi-week headache for you?


I haven’t posted much lately because the work got intense.
Two Webflow builds I’ve just finished: MavBio and Jemba9.
One works with biomaterials for medical and research applications. The other builds mission-critical technology for the space industry.
Very different worlds, and genuinely exciting projects to work on.
I’ve also wrapped up a much larger wellness platform that is now being turned into a full case study, while a few new projects are already underway.
A small preview for now. More soon!


wow, the smoothness is mindblowing here

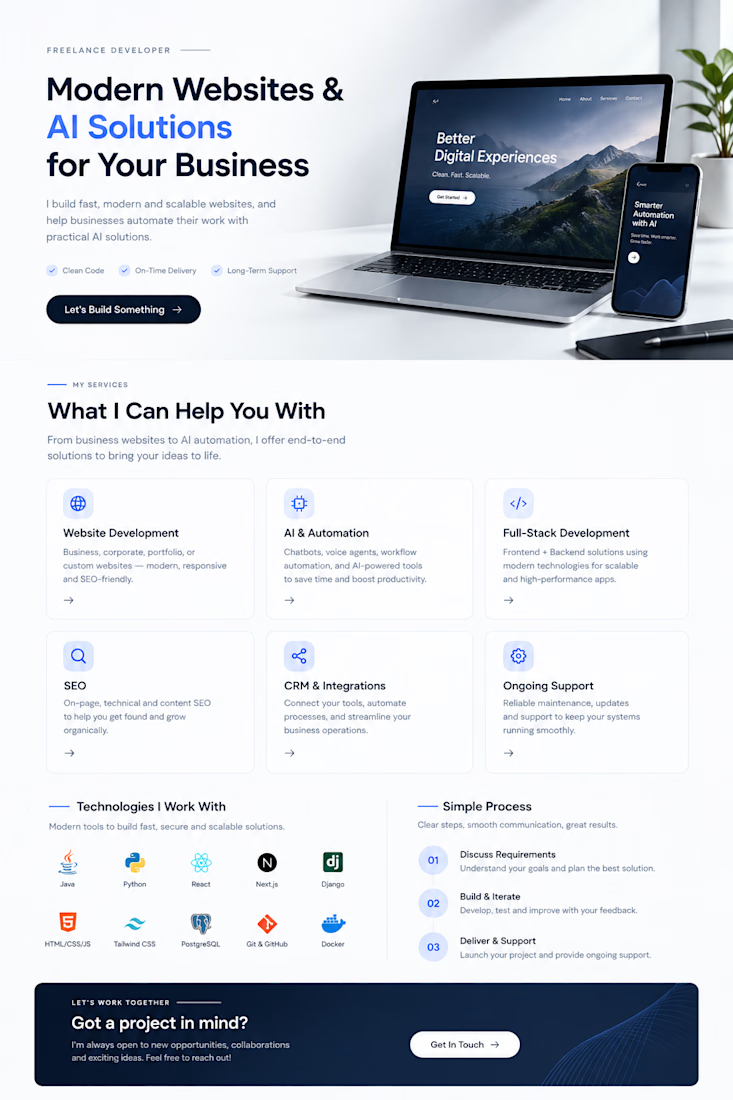
Building more than just websites — creating digital experiences that help businesses grow.
From modern, responsive websites to AI-powered automation, I help turn ideas into practical, scalable solutions.
✨ Web Development
🤖 AI & Workflow Automation
📈 SEO & Digital Growth
Have a project in mind? Let's build something meaningful.