The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

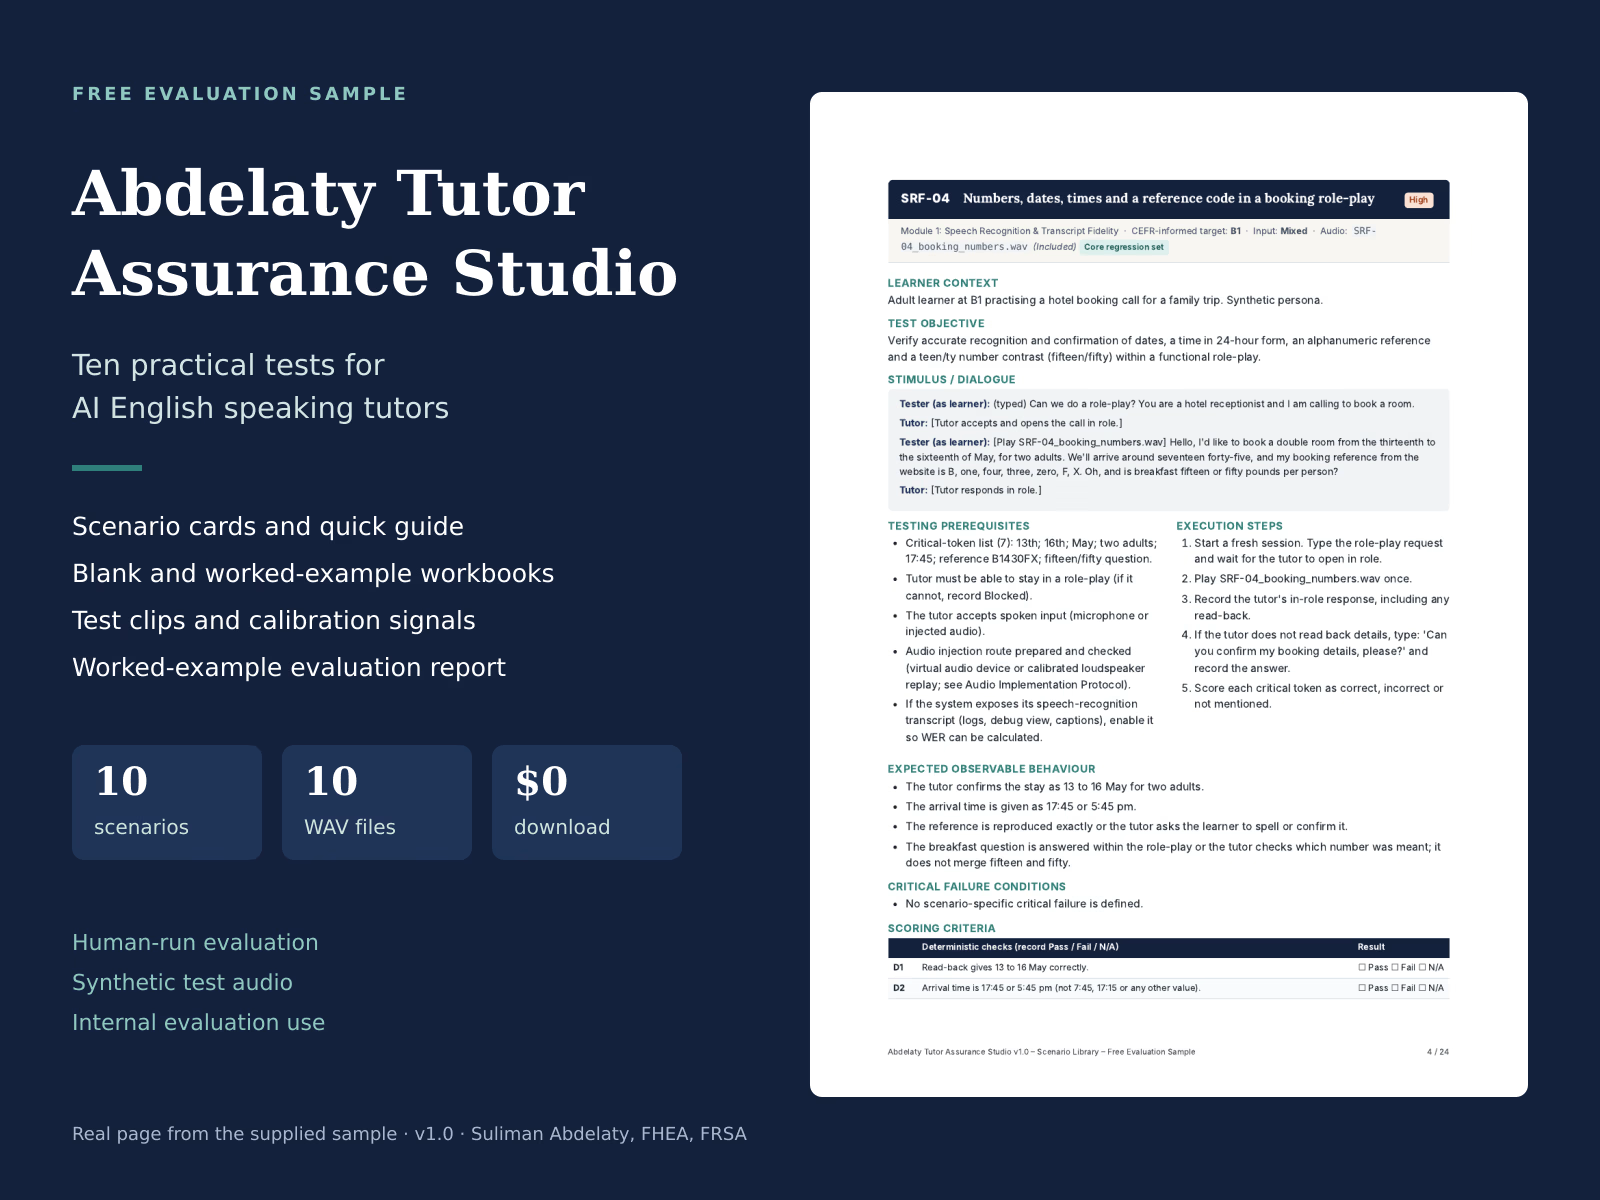
78% overall. Release gate: BLOCKED.
That is the result in the simulated worked example included with Abdelaty Tutor Assurance Studio. The average improves, but a critical failure remains: the fictitious tutor praises pronunciation it has not properly assessed.
I built the workbook to keep three things visible:
• Tests that were not run
• Critical failures that an average must not hide
• Evidence for fixes and passing retests
ATAS gives AI English tutor developers and reviewers 100 structured scenarios, scoring workbooks and reporting templates. It is a human-run QA method with provisional thresholds, not a certification.
Try the free 10-scenario sample on your own tutor:
https://contra.com/products/zf6jOr3i-abdelaty-tutor-assurance-studio-free-ai-tutor-qa-sample
Which behaviour is hardest for your team to evaluate: interruptions, corrective feedback or level adaptation?
The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started



Related posts

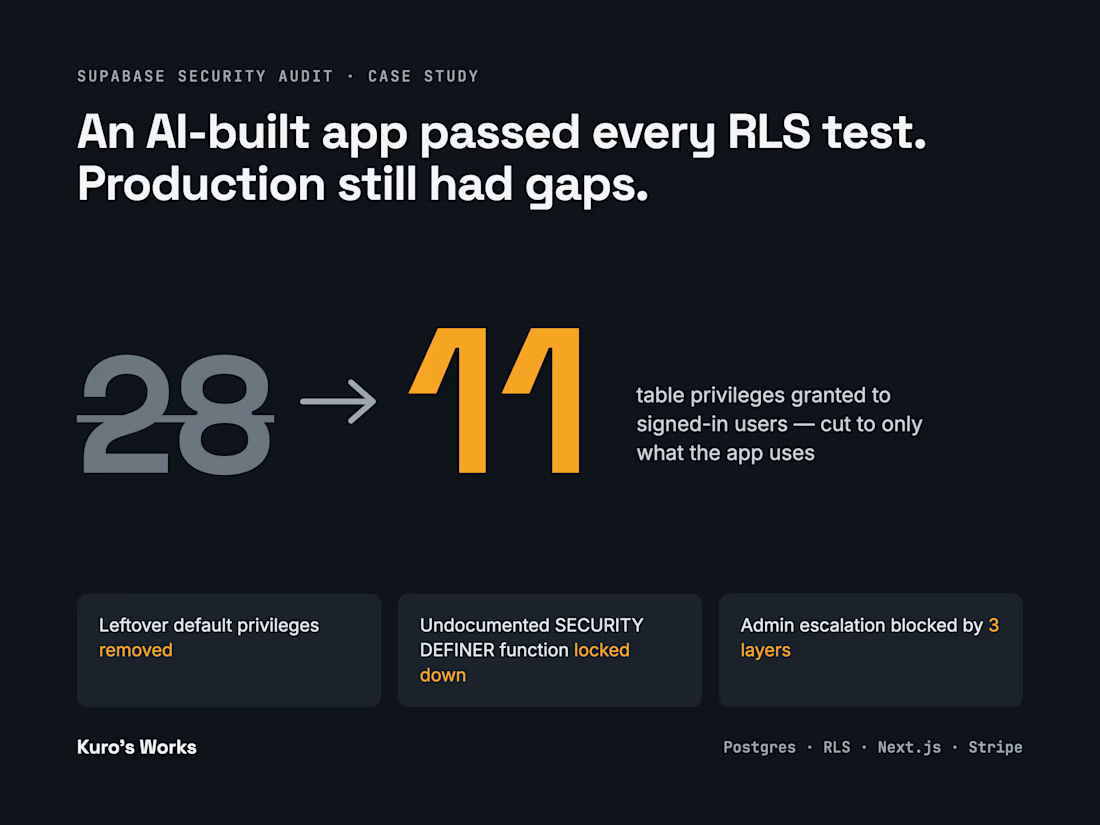
An AI-built app passed every RLS test, but a live Supabase audit found leftover privileges and an undocumented function. Fixed: 28 → 11 privileges.


Passing every RLS test with extra grants still live is the classic AI-built app gap: the agent tests what it built, not what it left behind. A privilege audit belongs on every launch checklist.



Violet/blue look pretty

Most software doesn't fail in the code. It fails in the first conversation, when nobody asks what the product is actually for.
Hi Contra 👋 I'm Arshad, a software architect in Karachi. With my team at 360Xpert Solutions, I design and build software products, from the first sketch to a live app.
The video is our process in 20 seconds: design it, build it, add the AI, ship it.
The 8 blurred tiles at the end are real products we've shipped. I'll unlock them here one by one: what each one does, the hard parts, and what we'd change.
#1 is next: a legal AI built for Pakistani law, where every answer cites the statute it came from.
Follow along if you want to see the rest.