The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

Most LLM outputs fail in production because prompt testing is done by manual eyeballing.
The Universal Prompt Evaluation Workbench - a developer tool that quantitatively benchmarks and scores prompts before deployment.
Core Features:
Multi-Provider Rig: Switch between Google Gemini (gemini-3.8-flash), Groq, and OpenAI with unified dispatch.
Inference Controls: Test Temperature, Top-P, and token limits to eliminate output drift in real time.
Automated 4-Pillar Judge: Instantly grades responses (0–100 & Letter Grade) on Format, Grounding, Completeness, and Latency.
Math Checksums: Deterministic math verification for structured receipt and invoice data.
Watch the 90-second demo to see it catch a failing prompt (Grade F) and validate an optimized, schema-enforced prompt (Grade A — 98/100).
🌐 Live Working Tool: https://lnkd.in/dwwQDk_2
🔗 GitHub Repo: https://lnkd.in/d-tY4ri3
#AI #PromptEngineering #LLMOps #Python #FastAPI #Groq #GoogleGemini


The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started





Related posts


Nothing but high end

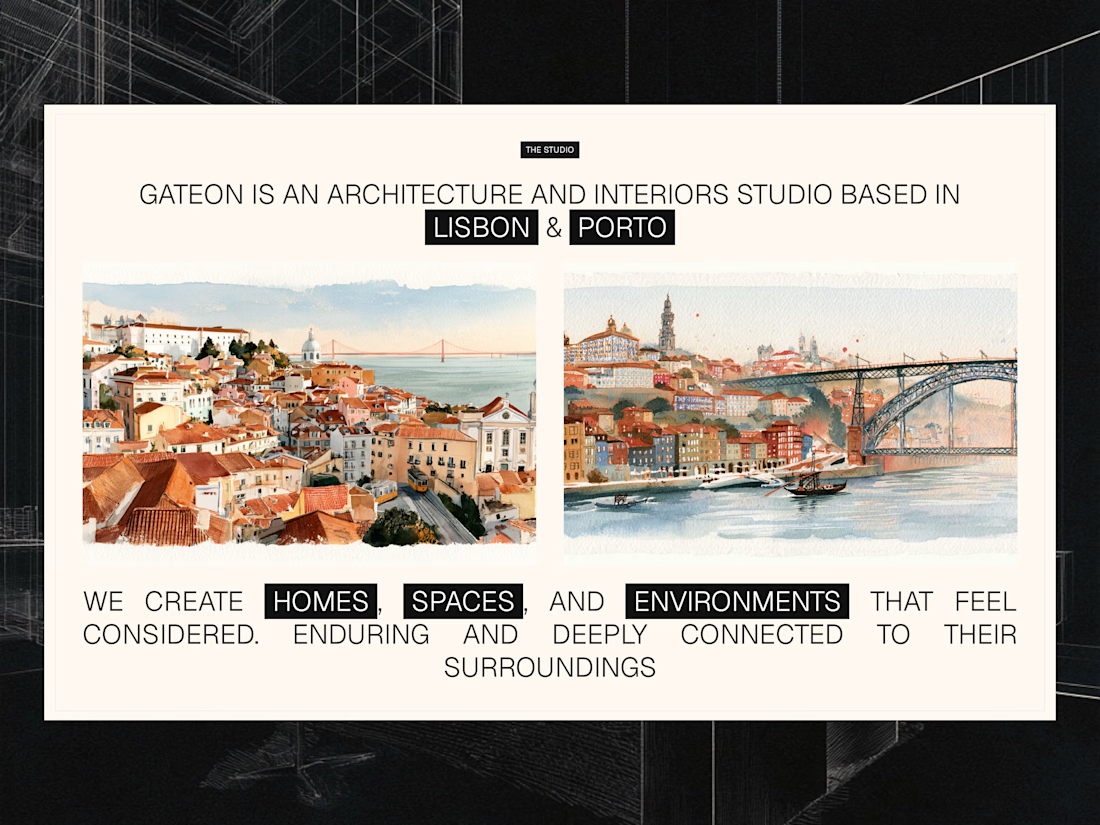
Studio section for Gateon, a interior design and architecture studio with bases in Lisbon and Porto


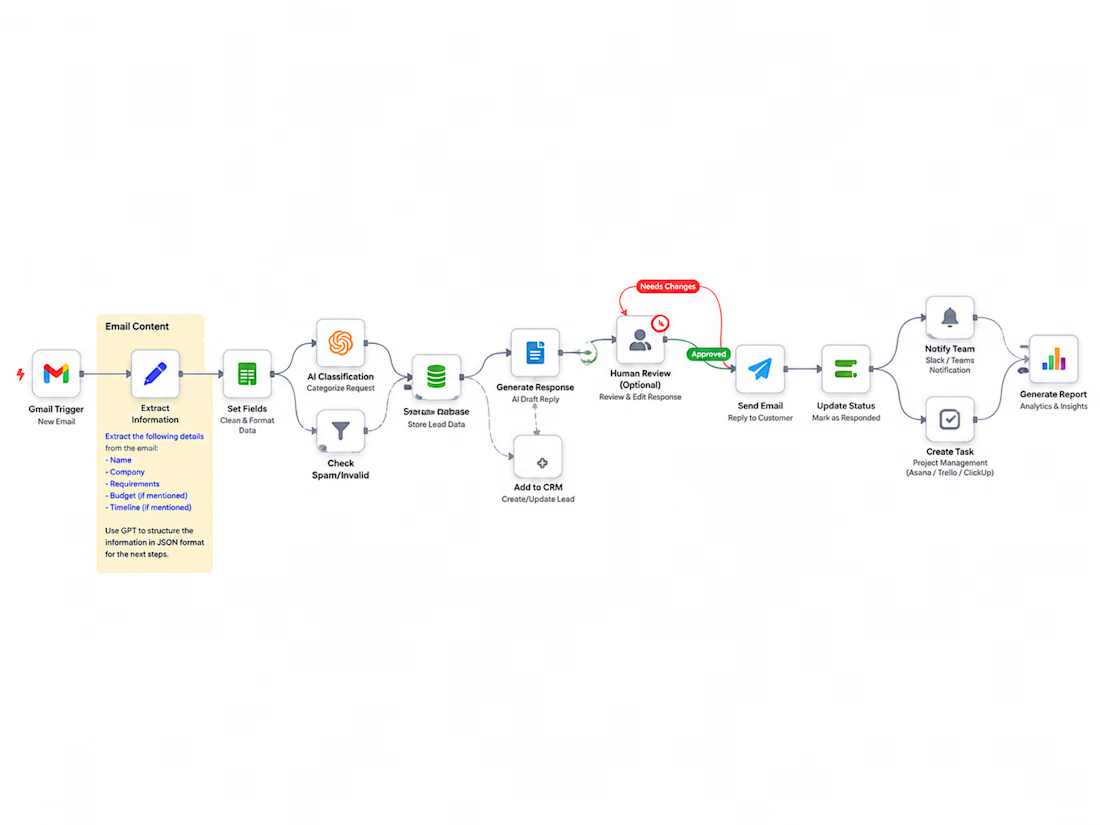
AI Content Automation Pipeline | n8n • ChatGPT • Airtable • Notion
Built an AI-powered content automation system that streamlines content generation, management, and publishing through one connected workflow—reducing repetitive work and improving content production efficiency.
What I Built
AI content generation with ChatGPT / OpenAI API
Automated n8n workflows
Airtable & Google Sheets data automation
Notion draft management and publishing
Custom REST API & webhook integrations
Optimized AI prompt engineering
End-to-end content workflow automation
Tech Stack
n8n • OpenAI API • ChatGPT • Airtable • Notion • Google Sheets • Python • Webhooks • REST APIs
Key Skills
AI Automation • Workflow Automation • Prompt Engineering • API Integration • Content Automation • Database Automation • ChatGPT Integration • n8n Development
SEO Keywords
AI Content Automation • n8n Automation • n8n Developer • ChatGPT Automation • ChatGPT API Integration • OpenAI API Integration • AI Workflow Automation • AI Automation Developer • Content Automation • n8n Workflow Development • OpenAI Automation • Prompt Engineering • API Integration • REST API Integration • Webhook Automation • Airtable Automation • Notion Automation • Google Sheets Automation • Python Automation • Database Automation • Business Process Automation • Marketing Automation • Automated Content Generation • Generative AI • Custom AI Automation • Custom Workflow Development
Result: A scalable AI content pipeline designed to reduce manual work, connect multiple platforms, and make content creation and management faster and easier.
#AIContentAutomation #AIAutomation #n8n #n8nAutomation #ChatGPT #OpenAI #WorkflowAutomation #ContentAutomation #ChatGPTAPI #OpenAIAPI #APIIntegration #PromptEngineering #Airtable #Notion #GoogleSheets #GenerativeAI #BusinessAutomation #AutomationDeveloper #AIDeveloper


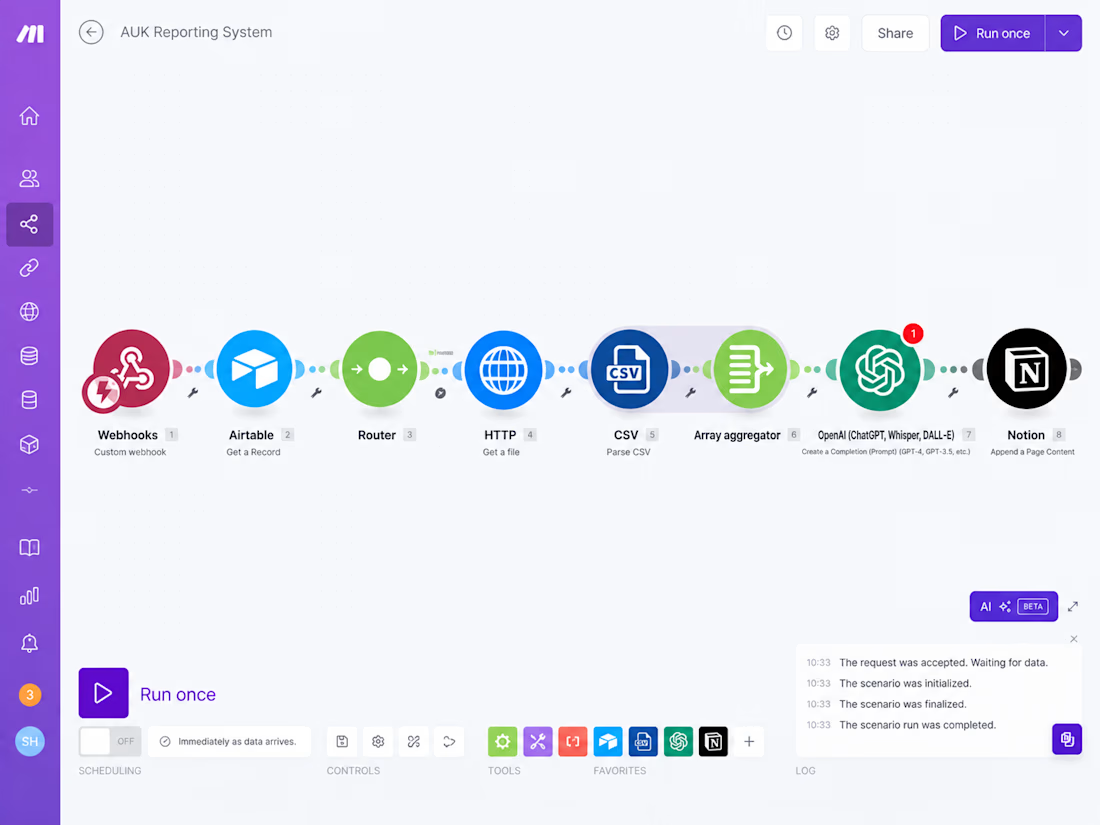

Linking ChatGPT responses to Airtable and Notion in one flow wipes out the manual transfer step. That lets you focus on the creative side instead of data juggling.