The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

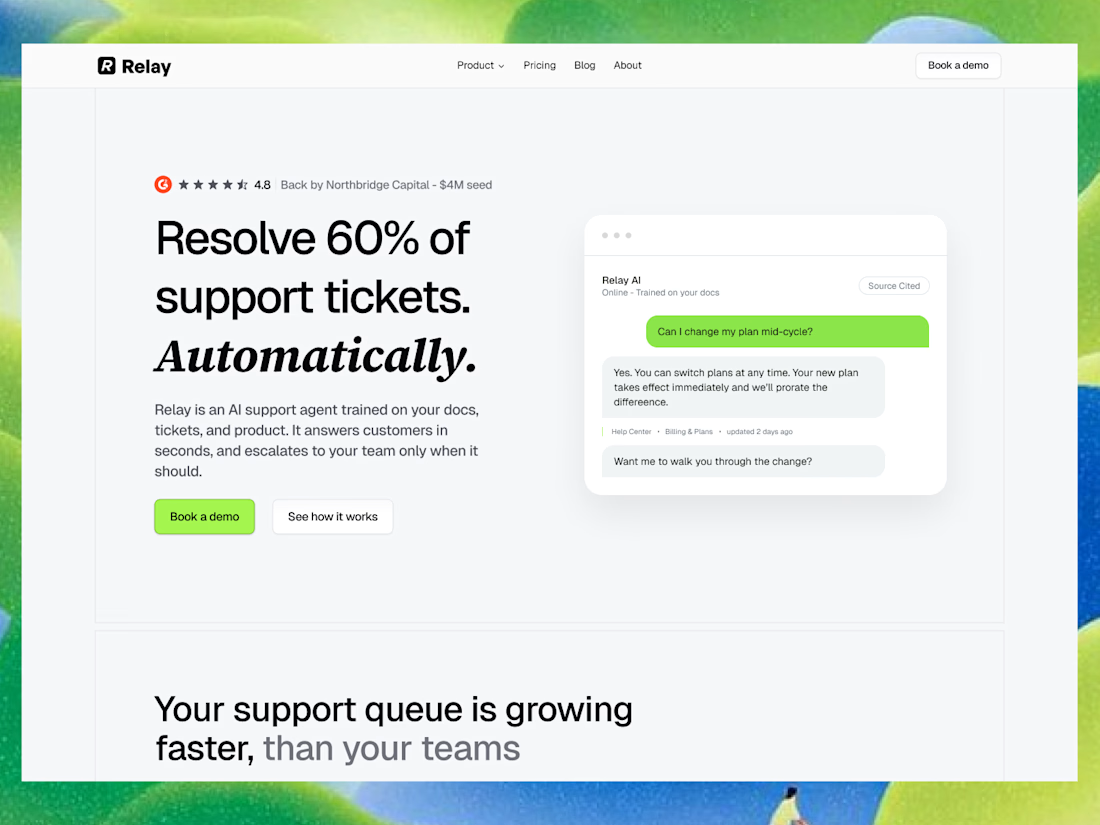
Your support queue is growing faster than your team can handle.
What if you could resolve 60% of support tickets automatically with AI?
I'm building Relay AI, an AI support agent trained on your docs, tickets, and product. It answers customers in seconds, and escalates to your team only when it should.
The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started





Related posts

On DZ Labs we are building a multi-specialist AI assistant, and the hardest part wasn't the AI.
The idea: a company gets a team of expert assistants, each with its own role, and every question is routed to the right one. The specialists in my prototype (psychology, engineering, medicine, history) are placeholders. The architecture is the point: swap them for legal, HR or support and the system stays the same.
What I didn't expect was how much of the work is context management.
A chatbot resends the whole conversation on every message. Cost and latency grow with each turn, and eventually the context window runs out. So I built a token-aware memory layer:
Past a token threshold, older messages are summarized automatically
The model receives the summary plus the recent turns, not the full history
Nothing is deleted: the full conversation stays in PostgreSQL
Conversations survive a restart and resume where they left off
Two lessons I'd pass on:
Test with a fake model first, then the real one. My 56 automated tests passed, and the first real run still failed: the real model returned its answer in a different shape than my fake did. That mismatch became a new test.
Read what your libraries actually do. The summarizer was folding the user's current question into the summary, so the model was answering a recap instead of the question. No error, just worse answers.
Where it stands: no RAG yet. So far it's prompt engineering and context tuning, with no model retraining. Retrieval over company documents is the next step.
Stack: Python, LangGraph, Claude, FastAPI, PostgreSQL, Docker.
#AIEngineering #LangGraph #LLM #Python
github.com
GitHub - sebastian946/Chat_Bot_AI: PRactice LLM create a chat bot to use memory and manage the context
PRactice LLM create a chat bot to use memory and manage the context - sebastian946/Chat_Bot_AI

Built a full digital operation for Wild and Free, a women-led animal rescue in Assam : an editorial website, a live adoption database, an AI agent on web and WhatsApp that screens adopters and books meet-and-greets, and a 60-second rescue intake. Designed and built end to end. Check it Out .


I built an AI pipeline for a tech recruiting agency that finds AI engineers, checks what they’ve built and sorts them into a shortlist to review.