The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

Case study: An AI content pipeline we built for a media client.
The challenge: turn a stream of source documents (including scanned PDFs) into automated daily email digests.
What made it hard:
→ Half the inputs were scanned PDFs of variable quality. Vision models for OCR > legacy OCR engines.
→ Hundreds of inputs/day. Pipeline extracts, groups, dedupes, rewrites, and scores by importance.
→ LLM landscape moves fast — we built a swappable provider layer.
Stack: Next.js + Python + provider-agnostic model layer.
If you're staring at messy inputs and wondering whether an LLM can make sense of them: yes — but the engineering matters more than the model.
The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started





Related posts

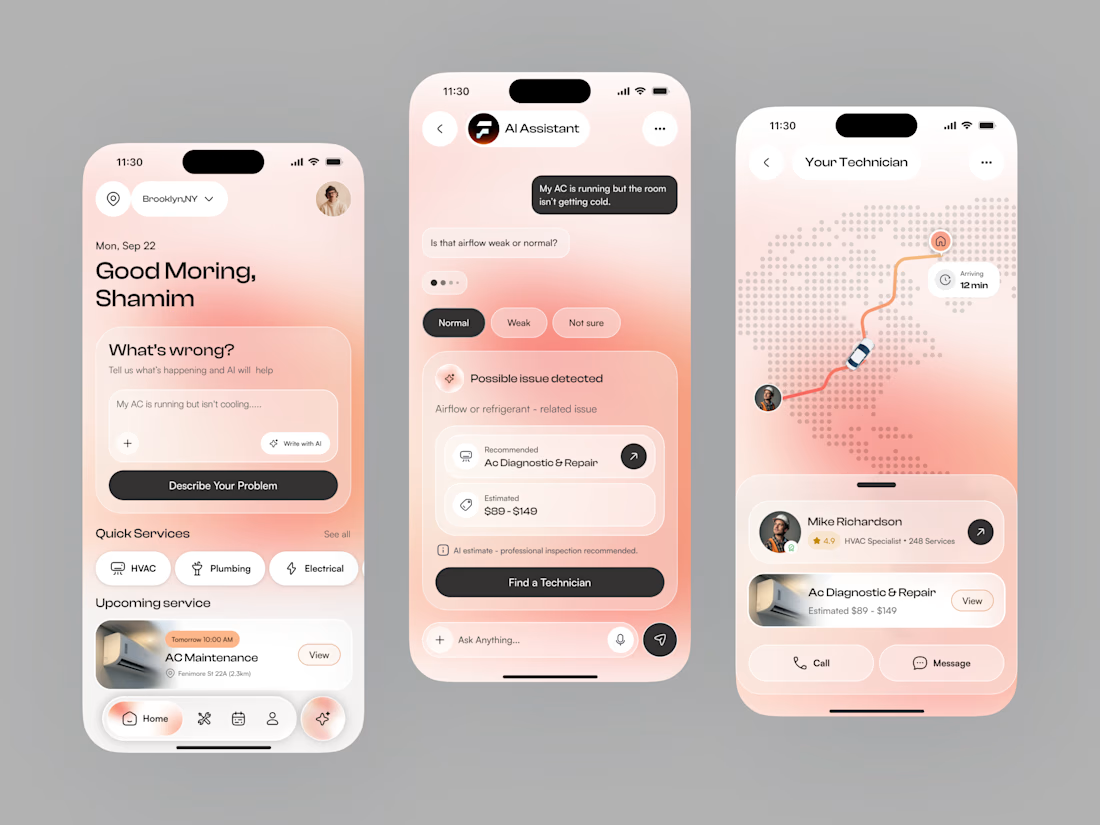
AI Home Services App — Smart Technician Booking & Repair
A premium AI-powered home services app designed to simplify how people diagnose home problems, find the right service, and book qualified technicians.
The product uses AI to turn a simple problem description into a clear service recommendation — helping users move from “What’s wrong?” → “What do I need?” → “Who can fix it?”
Key Experience
→ AI-powered problem diagnosis
→ Text, voice & photo input
→ Smart service recommendations
→ Technician discovery & booking
→ Transparent service information
→ Real-time technician tracking
→ Premium, intuitive mobile experience
The concept is designed for founders building AI home-service platforms, technician marketplaces, repair apps, and SaaS products where reducing friction and improving the booking experience can create a stronger customer journey.
Role: Product Designer
Focus: AI Product Design · UX/UI · Mobile App Design · Service Marketplace




Combining CapCut with AI tools like Claude has completely changed my workflow. I use Claude to draft scripts, structure video content, and generate captions/ideas — then bring it all together visually in CapCut for fast, polished edits.
As a freelance data analyst, developer, and translator, I've started using this combo for client content too — it saves hours on planning and keeps output consistent.
Open to collaborating on video/content projects that mix AI-assisted workflows with CapCut editing. Let me know if you're working on something similar! 🚀




claude for structure then capcut for the edit is a nice split. how much time does it actually save per video?


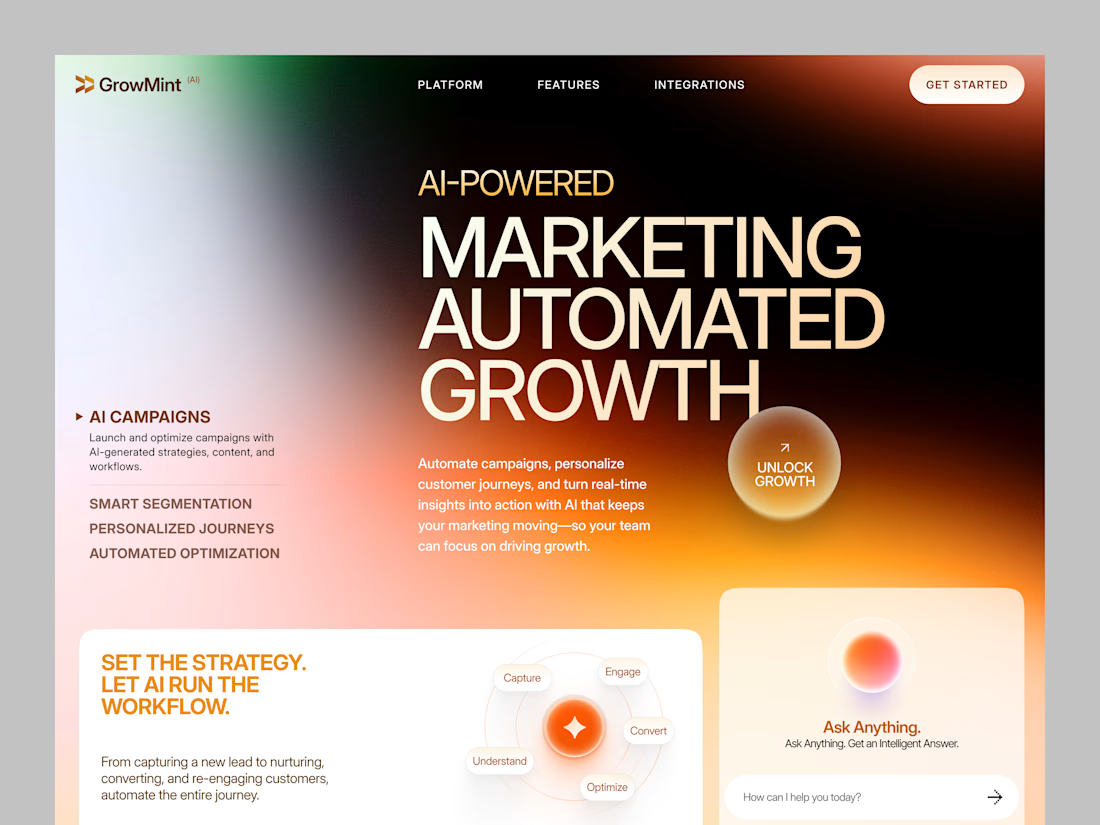
GrowMint AI - AI Marketing Automation Website
An AI marketing automation experience designed around the needs of marketing teams, growth marketers, and digital businesses.
The interface brings campaign management, customer journeys, analytics, and AI-driven optimization into a focused SaaS product experience, making complex automation easier to understand and navigate.

Nice design