The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

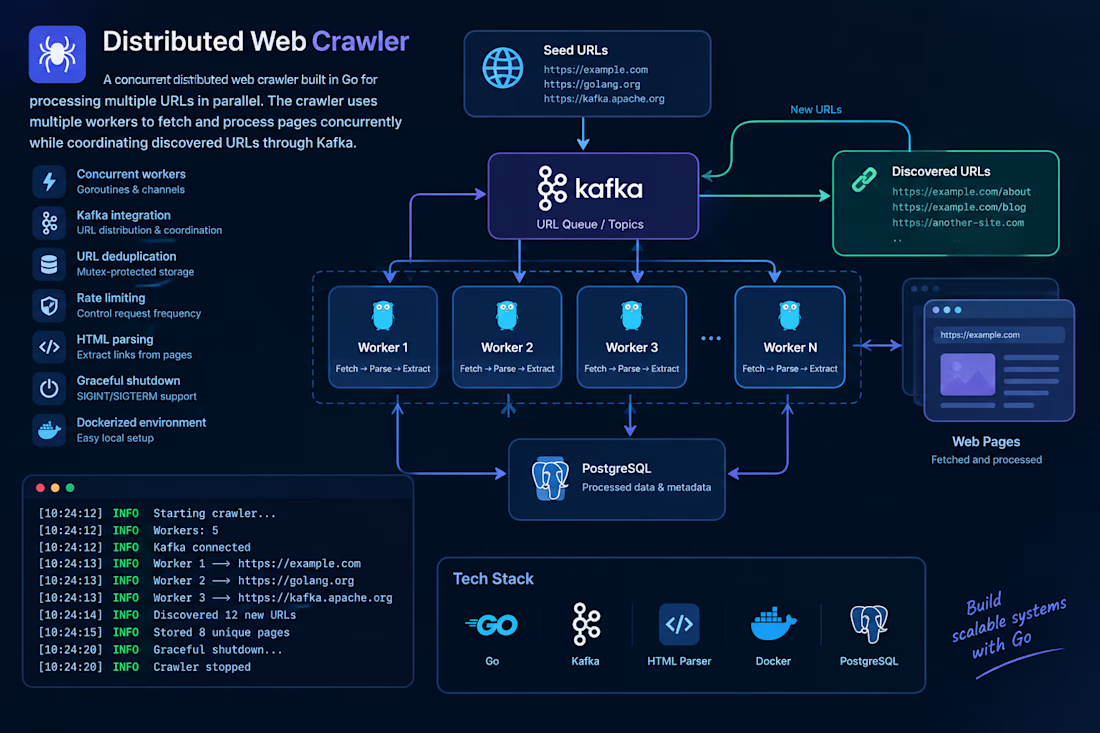
Distributed Web Crawler
A concurrent distributed web crawler built in Go for processing multiple URLs in parallel.
The crawler uses multiple workers to fetch and process pages concurrently while controlling request rates and coordinating discovered URLs through Kafka.
Tech stack: Go, Kafka, goroutines, channels, context, HTML parser, Docker
The project demonstrates practical use of Go concurrency patterns, distributed task processing, synchronization, rate limiting, and graceful application shutdown.


The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started

Challenges
View all


Related posts

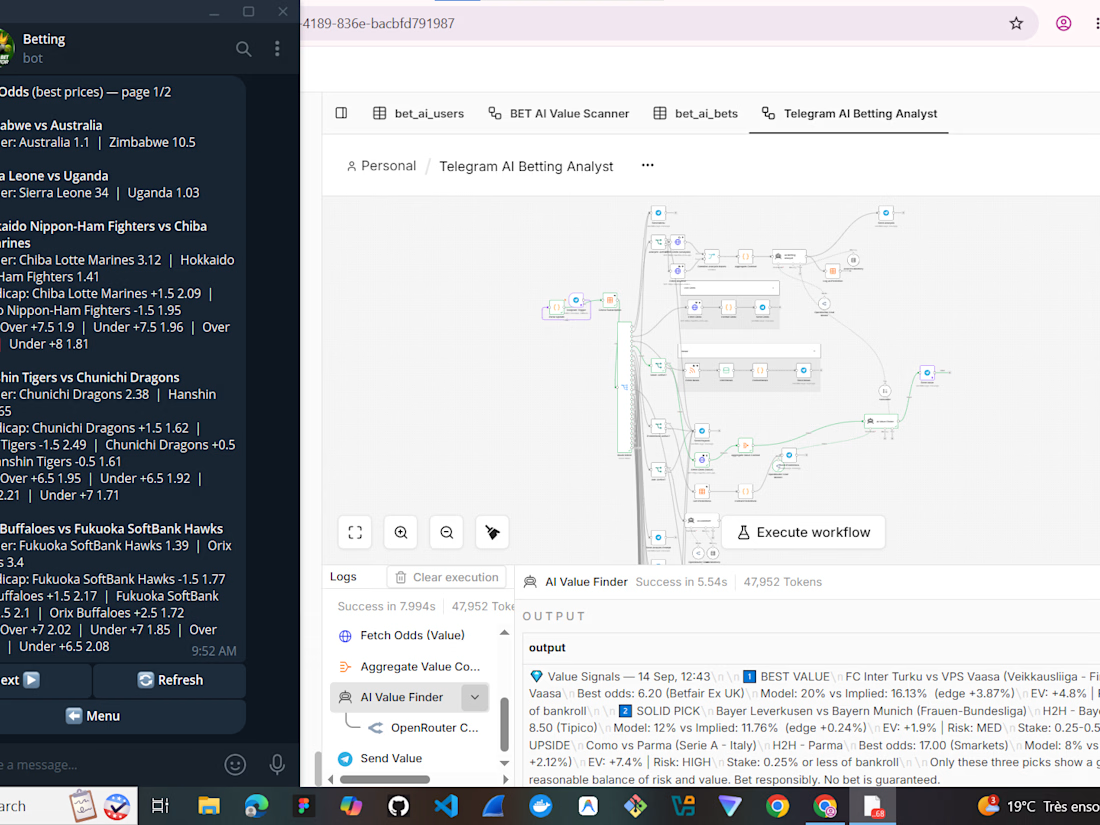
I built a fully automated Telegram AI Betting Analyst to process live sports data and find market edges. ⚡️
Instead of manually checking odds, this system centralizes the whole process:
→ Fetches and aggregates live odds via API
→ Routes data through an AI Value Finder to spot +EV (Expected Value) opportunities
→ Pushes real-time alerts and analysis directly to a Telegram bot UI
I handled the entire architecture in n8n, turning raw market data into an interactive, actionable dashboard right in the user's pocket.
#automatedworkflow #n8n #TelegramBot #AIAutomation #API
AI Agent DesignerAI Agent EngineerBusiness Workflow AutomationDockerN8NautomatedworkflowTelegram API



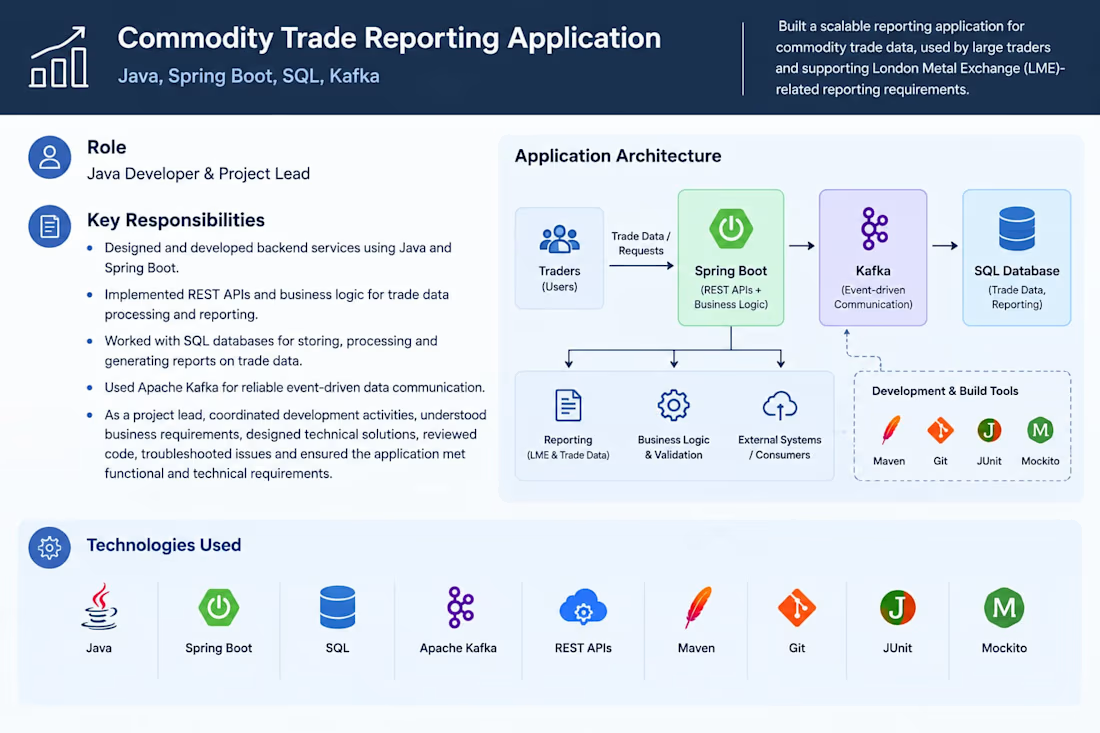
Commodity Trade Reporting Application | Java, Spring Boot, SQL, Kafka
Worked as a Java Developer and Project Lead , leading the development of a reporting application for commodity trade data used by large traders and supporting London Metal Exchange (LME)-related reporting requirements.
Key responsibilities included designing and developing backend services using Java and Spring Boot, implementing REST APIs and business logic, working with SQL databases for trade data processing and reporting, and using Apache Kafka for reliable event-driven data communication.
As a project lead, I was responsible for coordinating development activities, understanding business requirements, designing technical solutions, reviewing code, troubleshooting issues, and ensuring the application met functional and technical requirements.
Technologies: Java, Spring Boot, SQL, Apache Kafka, REST APIs, Maven, Git, JUnit, Mockito.

Been noticing something for a while students and freshers applying to 100+ internships/jobs, tracking everything in messy spreadsheets, and having zero idea why their resume isn't getting past the first screen.
So I'm building ApplyTrack , a simple tracker + resume-JD matcher made for exactly this problem. Log your applications in one place, see your pipeline at a glance, and get an instant match score + suggestions before you even hit submit.
Still early days, building it solo as a MERN project. No fluff, no bloated feature list just the two things that actually move the needle for a job search: staying organized, and applying smarter instead of just applying more.
More updates soon 🚀
Live link : https://apply-track-tau.vercel.app/
Github : https://github.com/CodeSagarrr/ApplyTrack.git
Full Stack DevelopmentmernstackdevelopersaaswebsiteBackend DevelopmentFrontend DevelopmentMongoDBNode.jsReact