The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

A scraper that "works on my machine" but 403s in production? Check your User-Agent before anything else.
Python's default urllib User-Agent gets blocked by a huge number of sites instantly. The fix is one line — send a real browser User-Agent — but the failure looks like a hundred other things (auth, rate-limits, IP bans), so people chase the wrong bug for an hour.
The broader lesson from building scrapers daily: the code is easy, the resilience is the job — pagination, rate-limits, anti-bot headers, retries. That's where the value is.
The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Related posts


dovvstudio.com is officially an Awwwards Nominee. First time I submit something there, no idea what to expect, and it got in.
Link below


Congrats! Getting nominated on your first submission is such a great achievement. Definitely something to be proud of!


AdvantageGEO: a Framer site for an agency that gets brands cited by AI search.
The hero opens with a bold claim, SEO is dying.
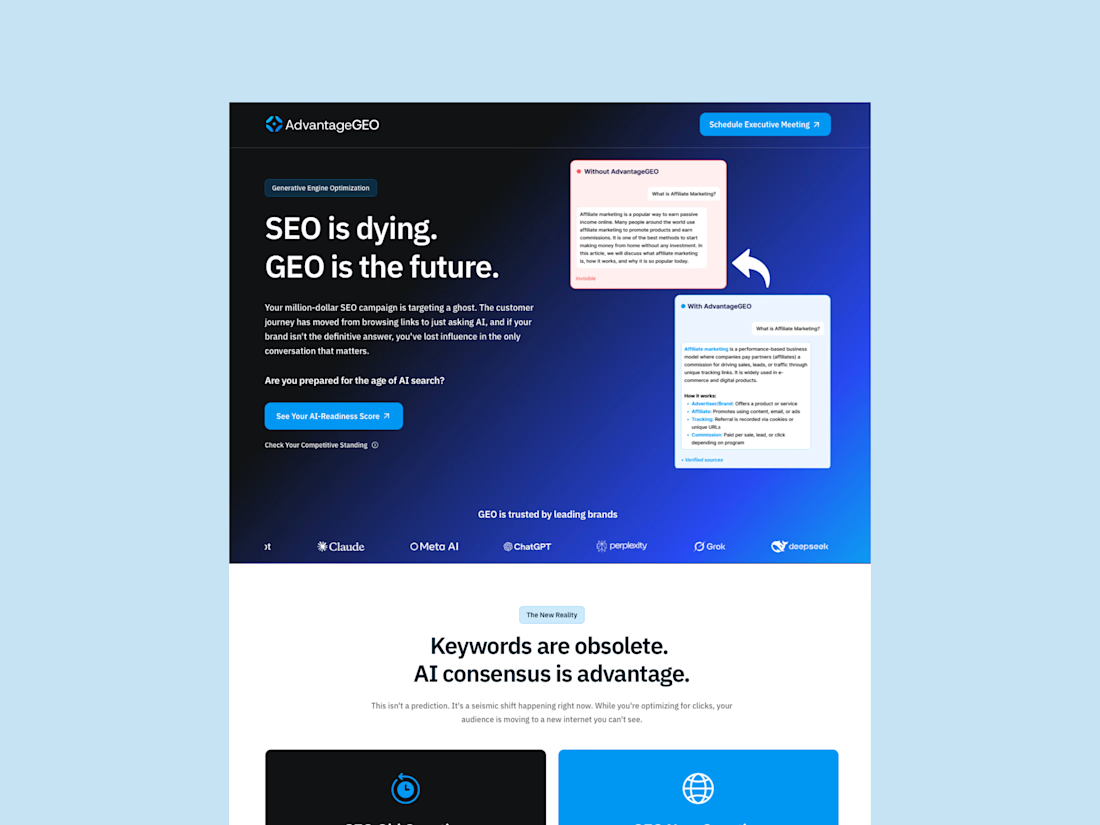

The dark blue hero with the "SEO is dying" headline is a bold opener. The side by side chat cards make the GEO idea easy to get at a glance.

ROOTED - An Interactive Hero Where Clouds Part and Roots Grow
rate this hero section?


Looks amazing!