The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

I'm a UI designer. Spent years hoarding UI screenshots, 3D icons, illustrations. Pinterest, Dribbble, Figma, desktop, random folders.
The constant nightmare: I need a tab bar. Or an empty state with illustration. Right now. I know I saved something like this. Three months ago. Somewhere, lol.
Built a desktop app to kill my own pain. Files on disk, plain folders, sync via Google Drive / Dropbox / iCloud. No cloud lock-ins. That was the easy part.
The hard part - search.
Off-the-shelf vision models are useless for UI. Dropped a Linear screenshot into CLIP - it sees "a computer screen with text". Thanks, super informative, lol.
They were trained on cats and landscapes, not on interfaces.
What ended up working - a combo of four layers. OCR pulls button labels, headings, body copy from every image. On top of that, a vision model with my own prompt dictionary for UI patterns: modal, toast, tabs, empty state, chart, dashboard. Wrote the dictionary myself, from what I actually look for. Plus manual tags users drop in two clicks. And fuzzy search over filenames as a fallback.
Now "settings" pulls up settings screens even when the word isn't on the image. "empty state" pulls illustrations of these screens, not random app shells. Closer to how I actually search. By what's in the image. Not by filename.
Not perfect. Dense dashboards still confuse the model. Auto-tags are rough. But this is the first reference manager I built that I actually use myself.
Curious - what else could I tweak in the search logic to make it work sharper?

The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started

Challenges
View all


Related posts

Designed a dashboard concept for tracking net worth across every asset type — stocks, crypto, property, pensions, funds, cash, and liabilities — all in one place.
Instead of the usual pie chart or bar graph, the centerpiece is a dial: a single, glanceable gauge showing where your wealth actually sits. Behind it, a quiet grid of every asset category fades in and out of visibility, reinforcing that everything's accounted for even when it's not the focus.
Dark UI, a single confident green accent, and a lot of negative space — built to make a genuinely overwhelming task (seeing your entire financial picture at once) feel calm instead of cluttered.


wow the animation feels super smooth, what is this animation for?

Working on the homepage for Still Blooming, a wedding and floral studio, I explored two different layout directions for the hero section. Same brand, same copy, just a different structure and visual rhythm.
Option 1 : Left Aligned. Text sits on the left with supporting content beside it, giving an editorial, asymmetrical feel.
Option 2 : Centered. Everything is stacked and centered, giving a clean, balanced, more classic hero layout.
Would love your honest UX/UI take which direction feels more elegant, functional, and true to a wedding/floral brand, and why?
22 voted
41%
32 voted
59%
54 votes
Closed

Great Design :)


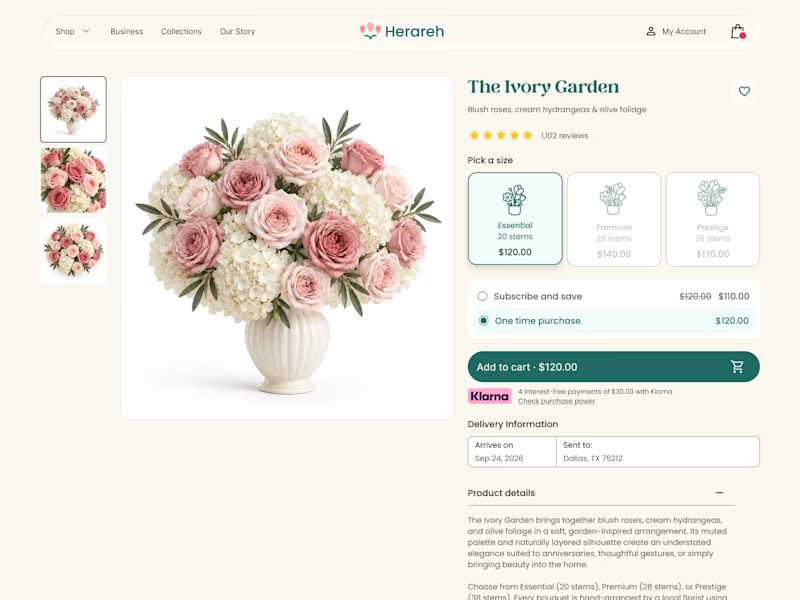
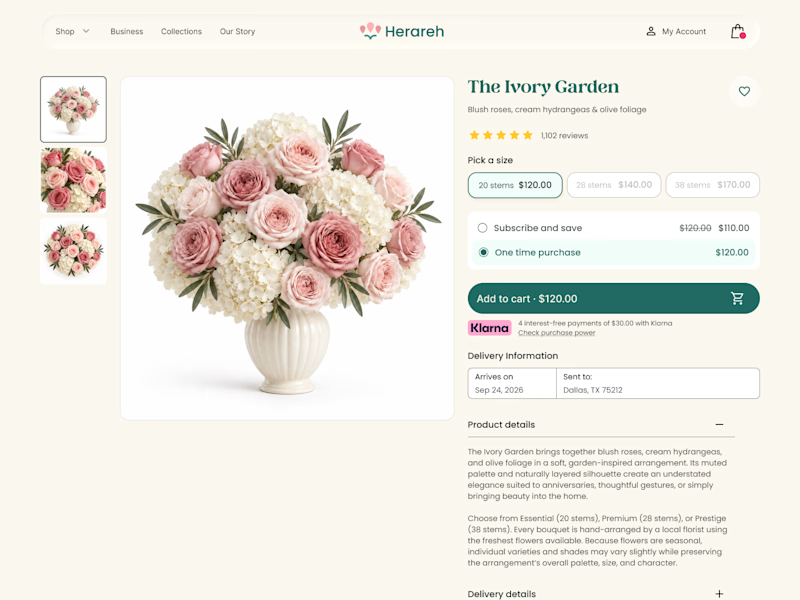

Icon cards for me, bouquets are such a visual purchase that a scannable icon beats reading "small/medium/large" every time. Did the compact chips version convert worse in testing, or are you still gathering data on that?