The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

I got tired of manually scraping platforms for automation gigs. It was taking me 20 hours a week just to find a couple of decent leads.
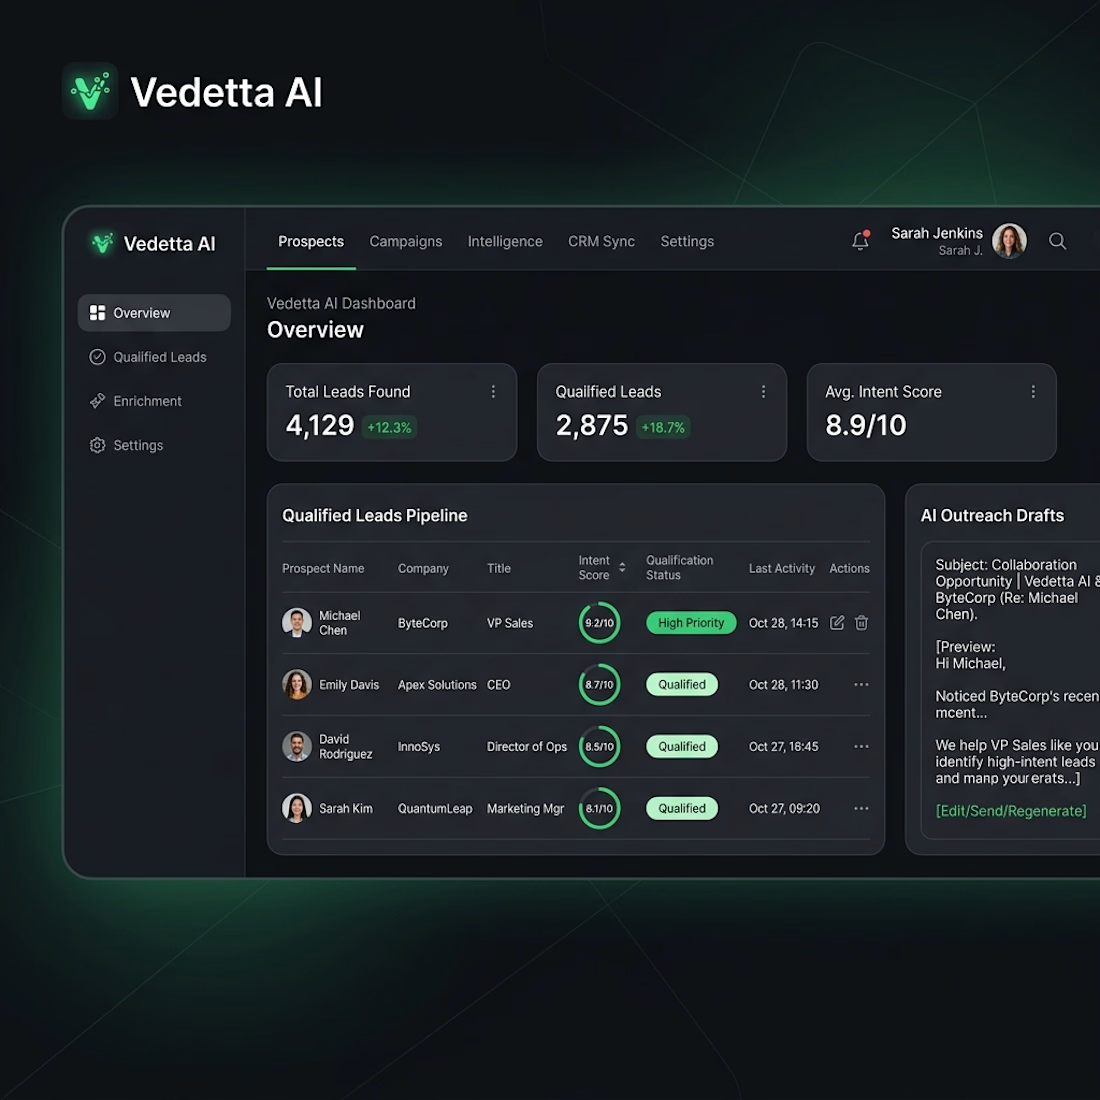
So I built a custom n8n + Claude architecture to do it for me. I call it Vedetta.
Instead of relying on basic keyword filters, I set up a Node.js backend that feeds raw data directly into a custom scoring model. Claude actually reads the job description and assigns an intent score from 1-10 (filtering out the low-budget clients right away).
If a lead scores above a 7, n8n automatically drafts a tailored cold message and pings my Telegram. I get a notification on my phone. If the draft is solid, I hit approve and it gets sent.
Zero hours spent sourcing. I only spend time talking to pre-qualified leads now.
I just uploaded the full breakdown and dashboard UI in my portfolio here on Contra. If anyone's struggling with manual lead gen and wants to see how the n8n logic works under the hood, let me know in the comments.

The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started




Related posts

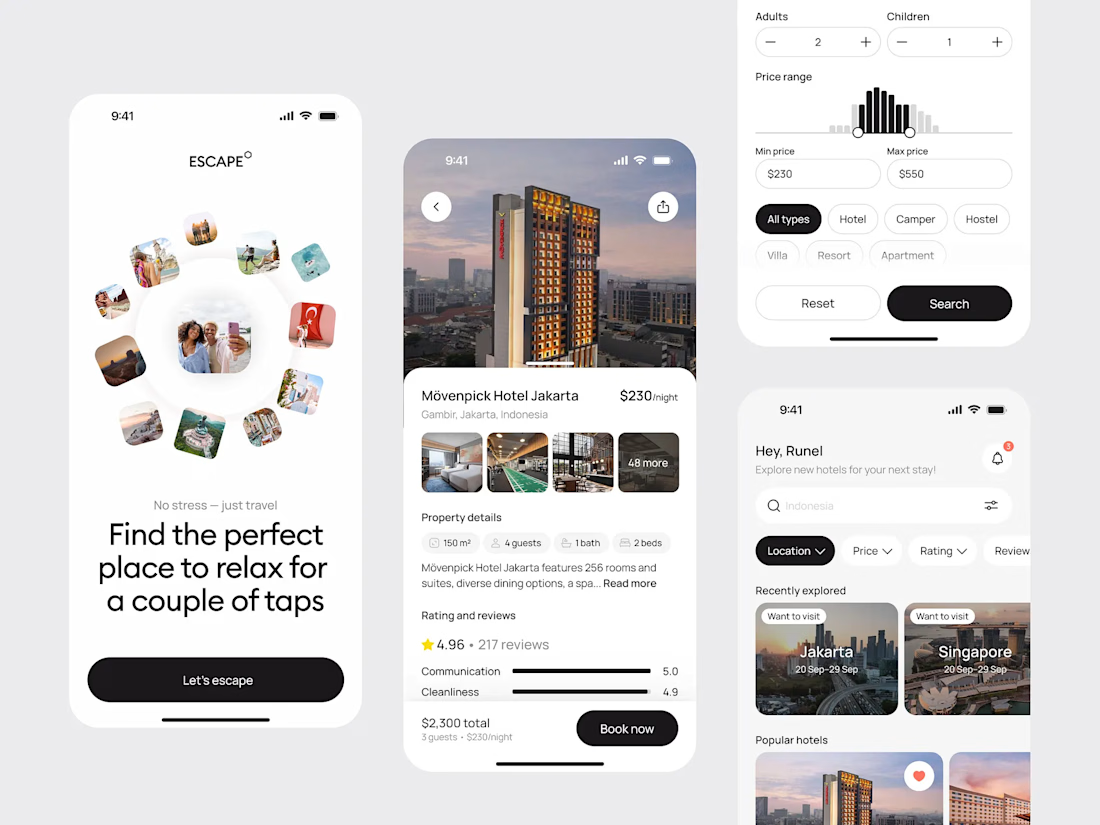
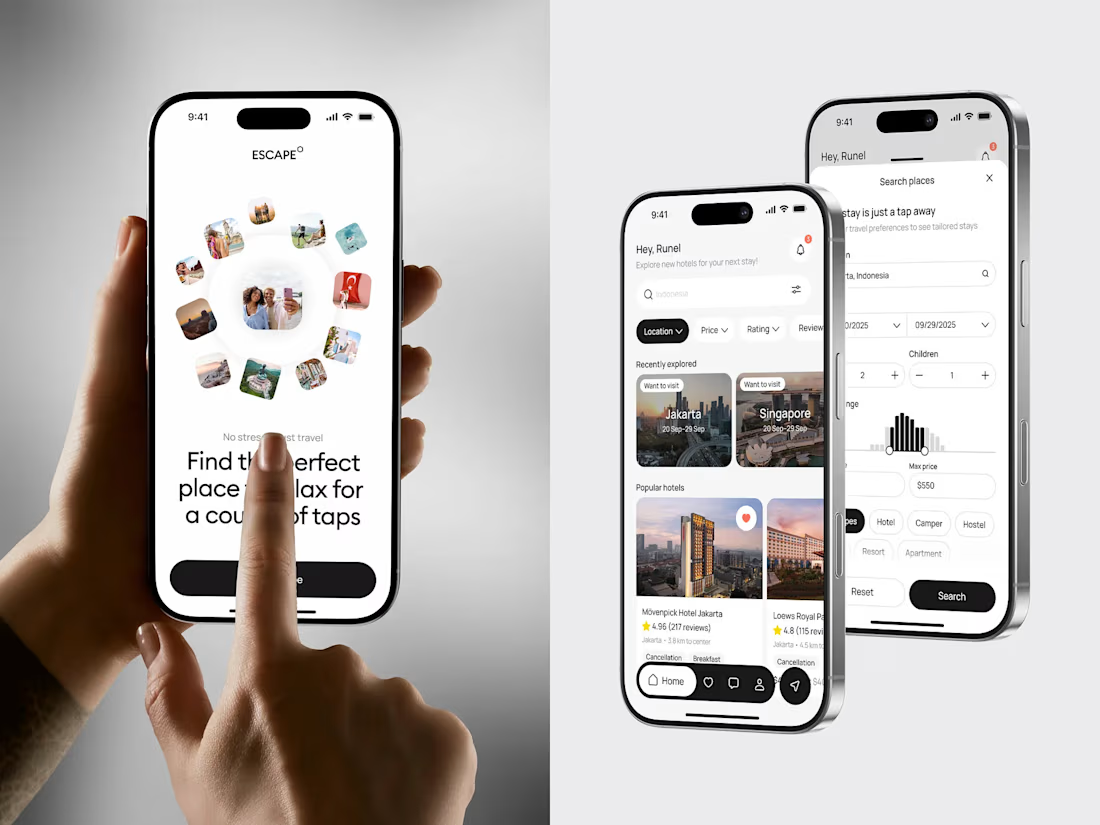
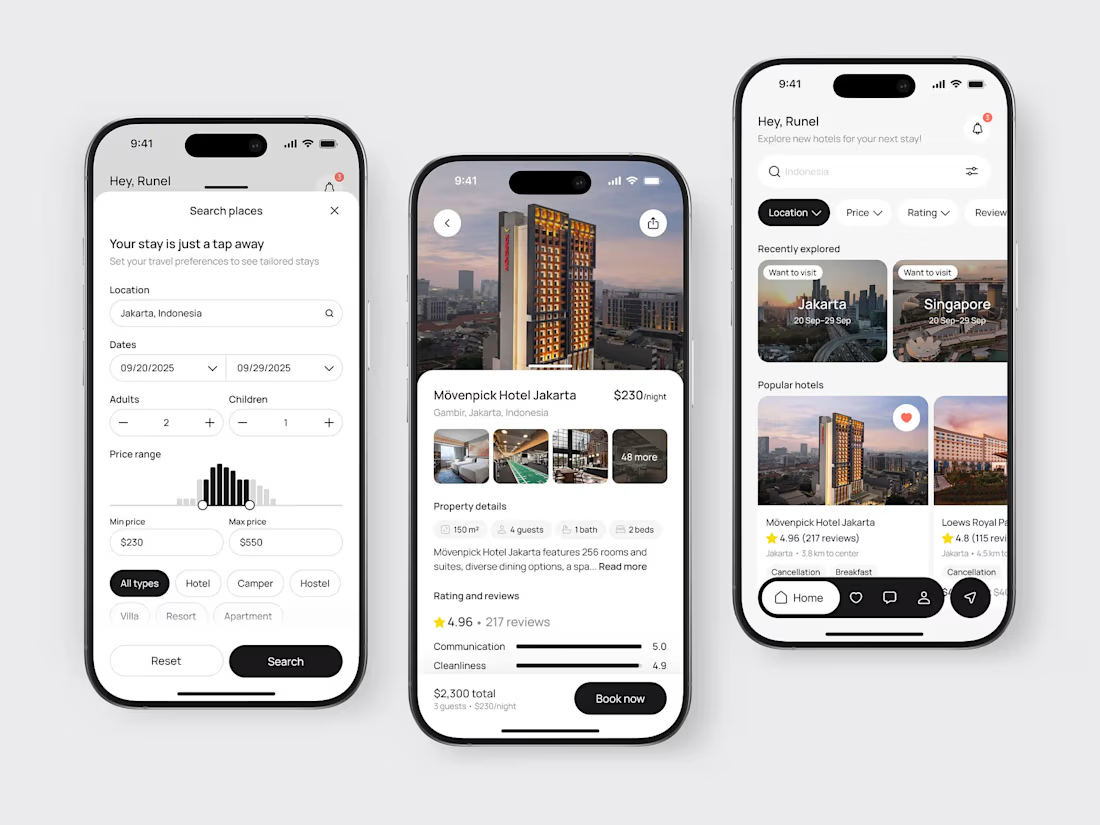
Really clean and polished app design! The booking flow looks intuitive and the overall UI feels modern and easy to use. 👏



good work

AI Assistant Using Your Business Knowledge Base — RAG on Your Documents
THE PROBLEM
Q&A bots break down when knowledge lives in documents: a 100-page manual has no "questions" to match, it can't fit into a prompt, and generic chatbots hallucinate instead of admitting what they don't know.
THE SOLUTION
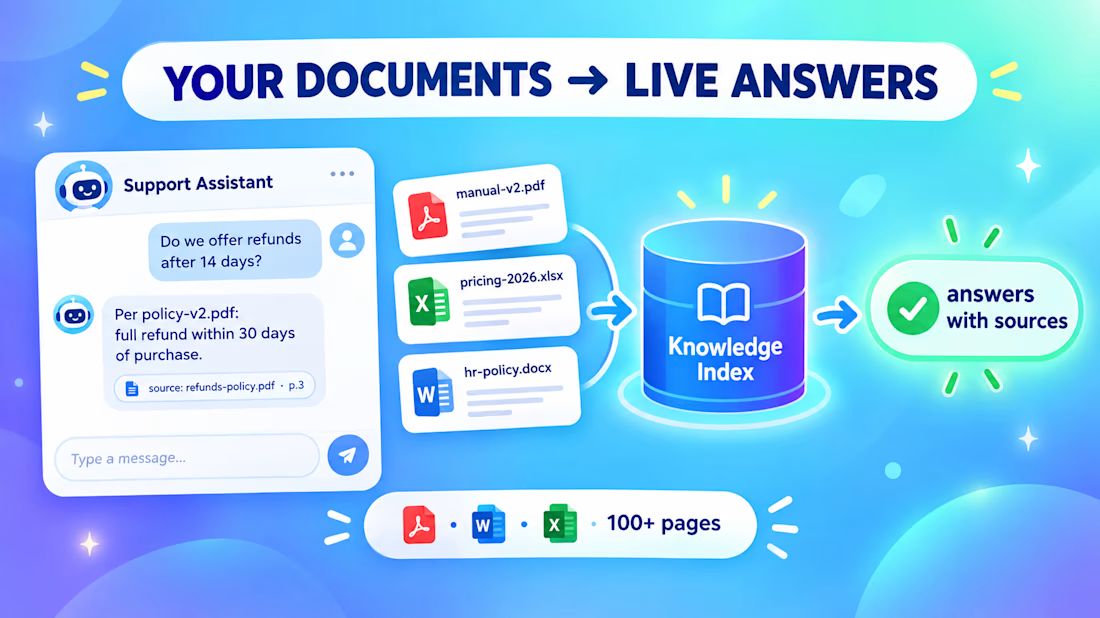
A RAG (Retrieval-Augmented Generation) knowledge base: documents are split into meaningful chunks, embedded into a vector index, and the assistant answers from the right sections — by meaning, not keywords.
Any format as-is: PDF, DOCX, TXT, Markdown — 100+ pages is fine
Answers grounded in YOUR documents — it says "I don't have that information" rather than inventing
Source references — every answer shows which document and section it came from
Runs on your infrastructure — documents never leave your control
One command to re-index after updating documents — documented, no programmer needed
LIVE DEMO
Ask it about my products, pricing, deployment and support — it answers from 6 real documents with sources:
https://kb-assistant-demo.dvc-ai.workers.dev



The 'I don't have that information' line is the part most RAG builds skip, and it's the one that matters. How do you set the cutoff? On mine, a fixed similarity threshold broke once I filtered results by user role. Scores shifted and it refused questions it could answer.

Automated a manual Google Sheets → Slack workflow to eliminate repetitive data entry and give the team instant notifications.
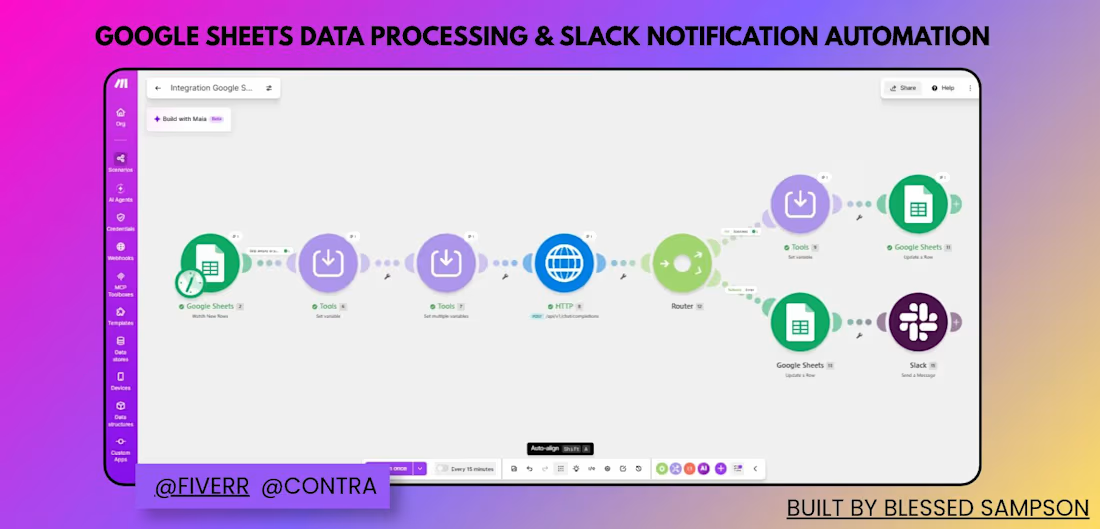
Previously, new data had to be manually checked, processed, and shared across the team — slow and easy to miss. I built a Make.com scenario that:
Watches Google Sheets for new/updated rows
Processes and routes the data through a router based on conditions
Creates corresponding Trello cards for task tracking
Logs processed records back to Google Sheets
Sends real-time Slack notifications so the team is instantly updated
Result: What used to be manual checking and updating is now fully automated — saving hours weekly and removing room for human error.
Tools: Make.com, Google Sheets, Trello, Slack



wow love this