The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

I tried to fix loneliness. I ended up building a Places API 280x cheaper than Google.
A couple of years ago, a friend came up with an idea that I still think is worth pursuing.
Moving to a new city is hard. Not because of logistics — but because of the quiet. You have a great coffee shop downstairs, a pool table two blocks away, and zero people to share it with. Dating apps exist. Friend apps don't, not really.
So the three of us built one. The pitch: open the app, see people nearby in cafes and bars who are openly up for a chat, a language exchange, a game of pool. No awkward matching, no swiping — just proximity and intent. A modern Foursquare, but for human connection instead of check-ins.
We built it. We shipped it. And then we completely failed at marketing. The product worked. The growth didn't. Classic indie story.
The technical leftover
One thing stuck with me from that project: the data layer.
Early on we used OpenStreetMap. It's incredible for what it is — but the POI data is inconsistent, incomplete in non-English speaking regions, and hard to work with at scale. Midway through we switched to Overture Maps — an open dataset backed by Meta, Microsoft, Amazon, and TomTom — and never looked back.
After the startup wound down, I kept thinking about Overture. The dataset had grown to 80+ million places worldwide. The license — CDLA Permissive 2.0 — has zero commercial restrictions. And yet almost nobody was serving it through a clean, affordable API.
The Google Places problem
If you've ever built a location-based feature, you know the pain.
Google Places API charges $17 per 1,000 requests for Place Details. Nearby Search is $32 per 1,000. For a startup running 500,000 requests a month, that's $8,500–$16,000. Monthly. Before you've found product-market fit.
The result? Developers either cripple their apps with aggressive caching, avoid the feature entirely, or burn through their Google credit and get an unexpected invoice.
There had to be a better way.
What I built
I spent a few weeks building a REST API on top of the Overture Places dataset, written in Rust with Axum and PostGIS on the backend.
Two endpoints:
Nearby search — find places within a radius, optionally filtered by category:
Search by name or brand — find all locations of a specific business:
This one searches across both name and brand fields simultaneously, so you don't have to know how Overture classifies a particular chain.
Each response includes coordinates, name, category, address, operating status, phones, websites, social links, and emails.
The numbers
Google Places charges $17 per 1,000 requests for Place Details, and $32 for Nearby Search. Commercial use comes with restrictions, and overage bills are a common surprise.
This API starts at $0.10 per 1,000 requests, Nearby Search is included, the license has zero commercial restrictions, and overages are soft — $0.05 per 1,000 if you exceed your plan.
Plans on RapidAPI:
Basic — free, 5,000 requests/month
Pro — $10/month, 100,000 requests
Ultra — $30/month, 500,000 requests
Mega — $80/month, 2,000,000 requests
The Pro plan at $10/month for 100,000 requests — Google would charge $1,700 for the same volume.
The honest part
The data isn't perfect. Overture is updated monthly, not in real-time. In some regions — especially smaller cities outside Western Europe and North America — coverage is thinner than Google's.
If you need reviews, photos, real-time open/closed status, or Google's autocomplete quality — this isn't a replacement. It's an alternative for the use cases where you just need POI data and coordinates, and you don't want to pay Google's prices to get them.
What's next
The API started as a side project for the social app. But honestly, I'm not done with that original idea either. The loneliness problem is real, and I still think proximity-based social has legs — just needs a different approach to growth than what we tried.
For now, the Places API is live on RapidAPI. Free tier available.
And if you're building something in the location space and want to talk — I'm always up for that conversation.
Built solo, with Rust, PostGIS, and too much coffee.


The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started

Challenges
View all


Related posts


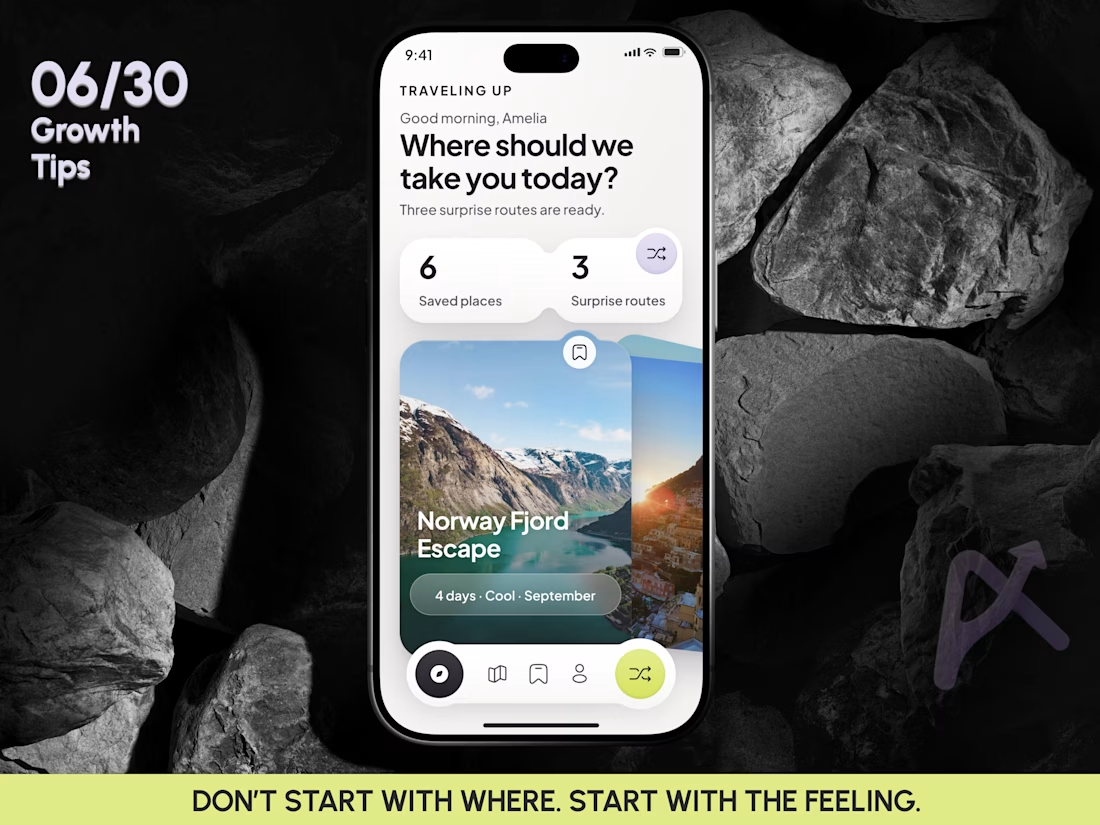
🧠 GROWTH TIP 06/30: DON’T START WITH WHERE. START WITH THE FEELING.
Most travel apps start with one question: “Where do you want to go?”
That works when the user already knows the answer. But a lot of travel discovery starts earlier, with a much less specific thought: I want to go somewhere, I just don’t know where yet.
That idea became Traveling Up, a travel randomizer concept.
Instead of asking users to work through dozens of filters, the product starts with just three signals:
🌍 how much time they have
🎭 how they want the trip to feel
☀️ what kind of climate they prefer
The destination stays a surprise.
Hypothesis: removing destination selection from the first step could move users faster from vague travel intent to genuine interest in one specific trip.
What I would test:
• Destination first search vs Mood first randomizer
• Randomize start rate
• Destination save rate
• Plan this trip CTR
• Time to first interesting destination
💡 Growth insight: in discovery products, uncertainty is not always friction. Sometimes it is exactly what creates curiosity and moves users toward the next action.
This concept came to me after a particularly inspiring trip. And I think it is the first mobile concept I have created purely for myself, rather than for a client project, in roughly three years.
So this one has a little more freedom, art direction, and product experimentation in it.
06/30 complete.
If you enjoy seeing mobile product experiments like this alongside the growth thinking behind them, follow along. And if this direction resonates, a reaction helps me understand which ideas are worth exploring deeper next.
#MobileAppDesign #TravelApp #TravelAppDesign #MobileUX #UXDesign #ProductDesign #GrowthDesign #TravelTech #InteractionDesign #UIDesign #ProductStrategy #MobileProduct #AsolDesign


Perfect

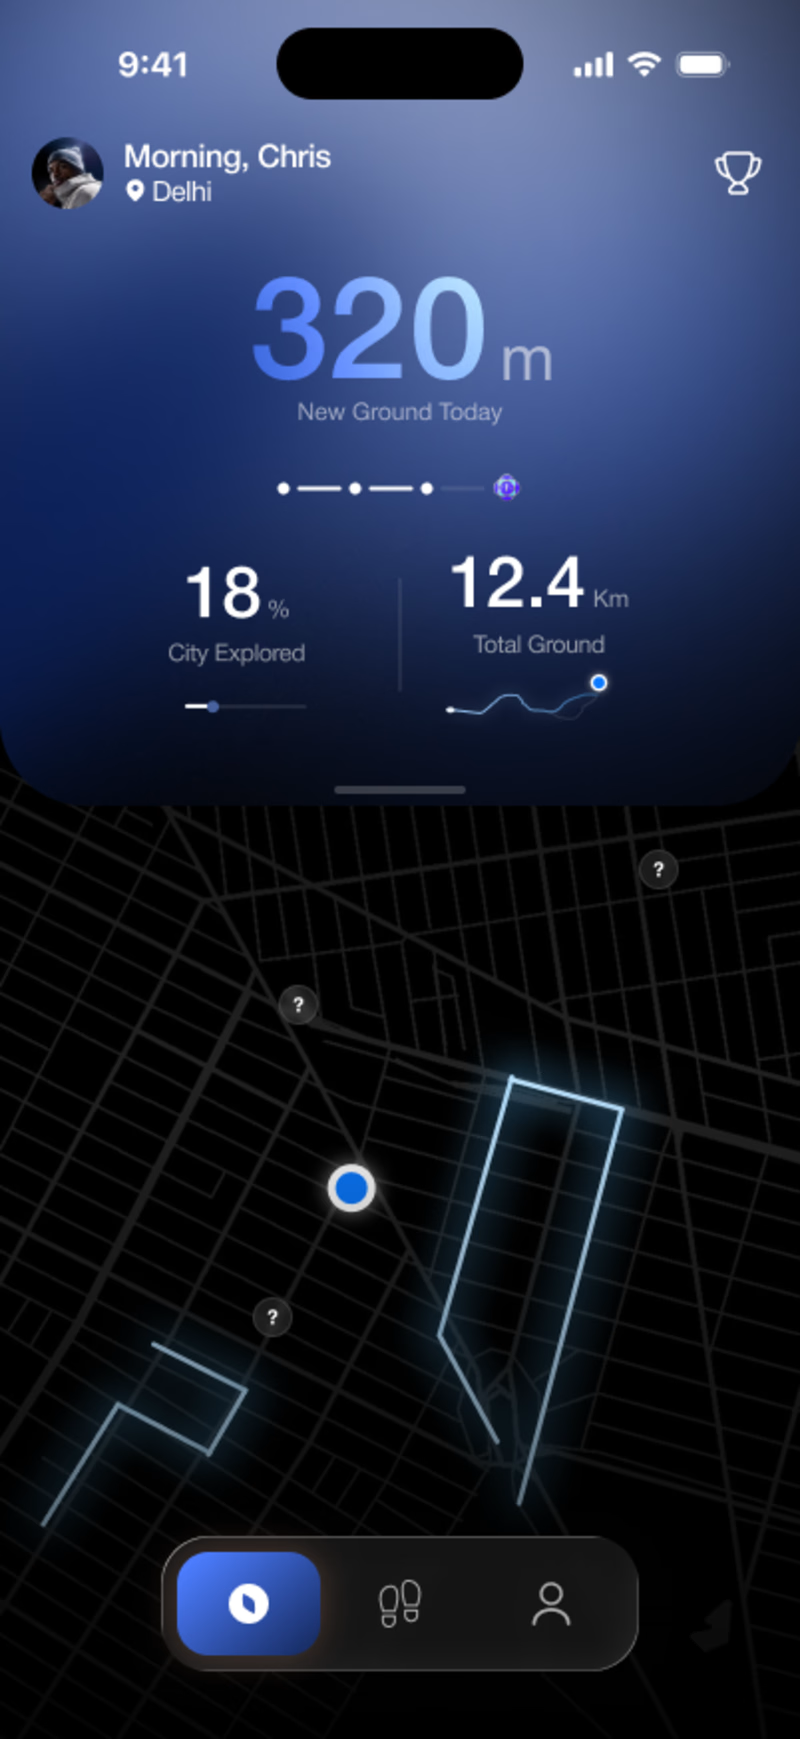
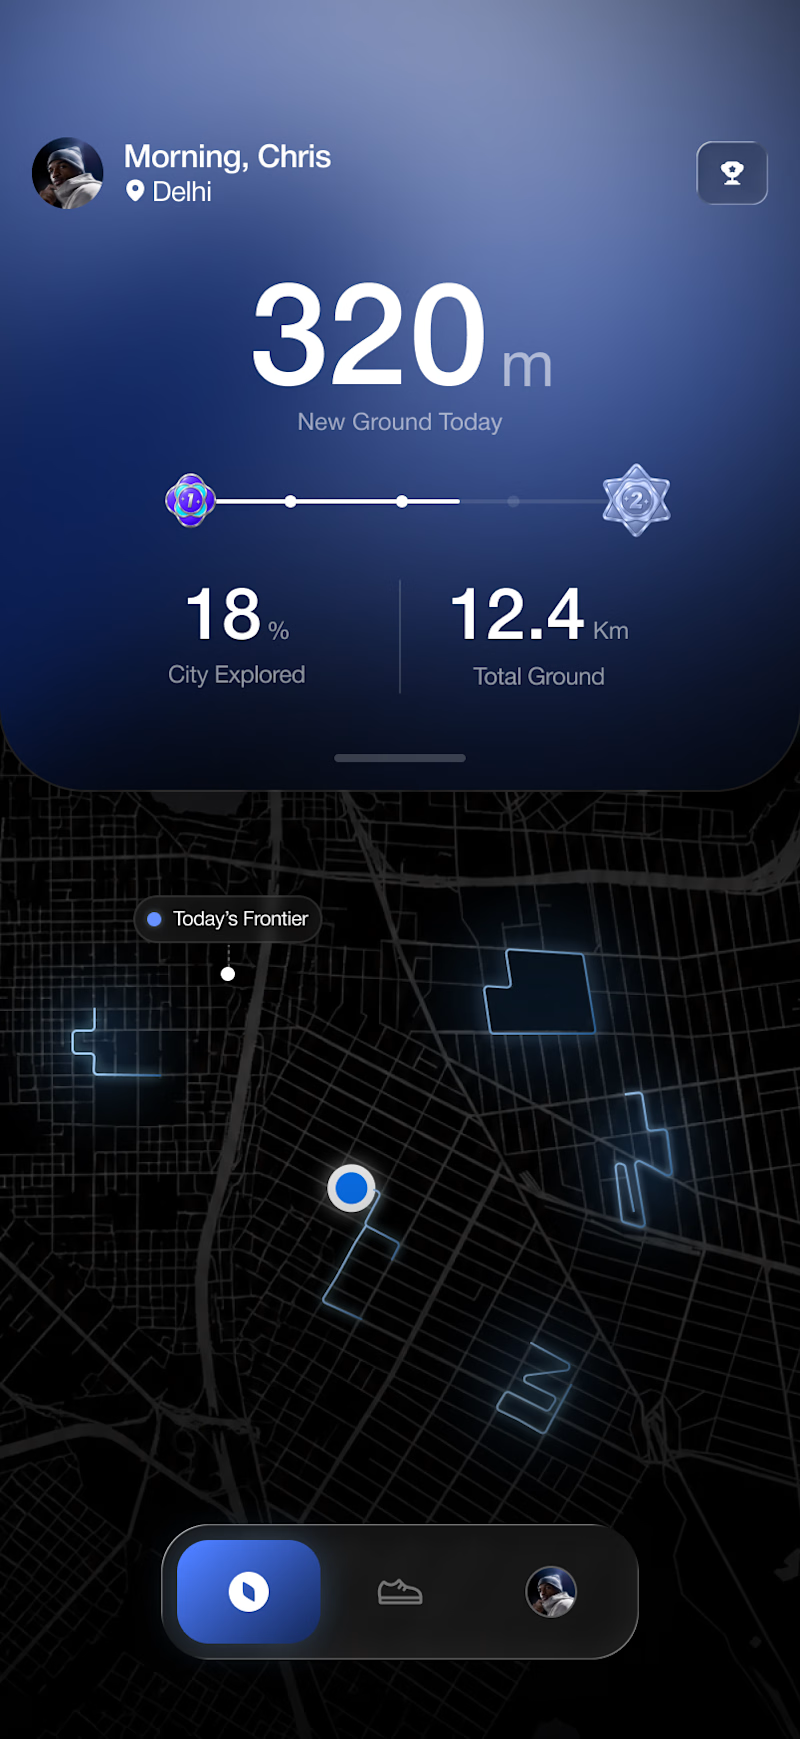
App design for an exploration app. 2 options, because minor decisions make the biggest impact.

7 voted
50%
7 voted
50%
14 votes
Closed


Title: UtilForge — Client-Side Developer Tool Matrix
Summary: A suite of 20+ developer utilities that run entirely in
the browser. No uploads, no server, no data leaving your machine.
What I did: Built the full stack — Next.js frontend, Web Workers
for heavy processing (formatting tens of thousands of lines of JSON,
PDF manipulation, hashing) so the UI never blocks. Every tool works
offline after first load.
Tags: Next.js · React · TypeScript · Web Workers
Link: utilforge.dev


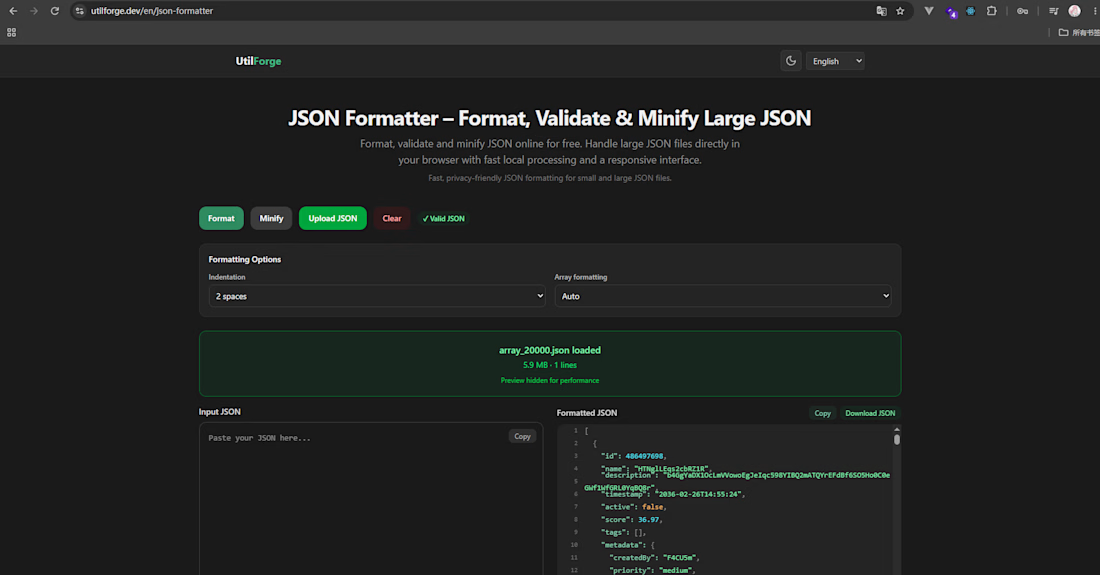

The no-upload promise is the strongest part. I'd make the offline state visible in the UI, so someone working with sensitive JSON or PDFs can see that the file stays on their machine before they drop it in.