The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

AI Model Cultural & Linguistic Alignment
[Visual: network/data-node diagram — "Teaching AI to understand culture accurately"]
The Challenge
Large language models are often trained on data that underrepresents or misrepresents non-Western knowledge systems — including African spiritual philosophy and Yoruba cosmology. This creates models that produce inaccurate, flattened, or culturally tone-deaf responses.
My Approach
I developed structured Q&A datasets to help fine-tune LLMs on the Ifá epistemic corpus and Yoruba linguistics, grounding abstract philosophical concepts in accurate, well-sourced training data. I also audited existing model outputs to catch bias, factual errors, and low-resource language translation issues, then designed corrected examples and precision prompt structures for more reliable outputs.
The Outcome
Models trained on this work represented complex cultural material with greater accuracy and less bias.


The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started







Related posts

Hi! I’m a college student and an aspiring AI/ML engineer who loves building things with technology and turning ideas into real projects.
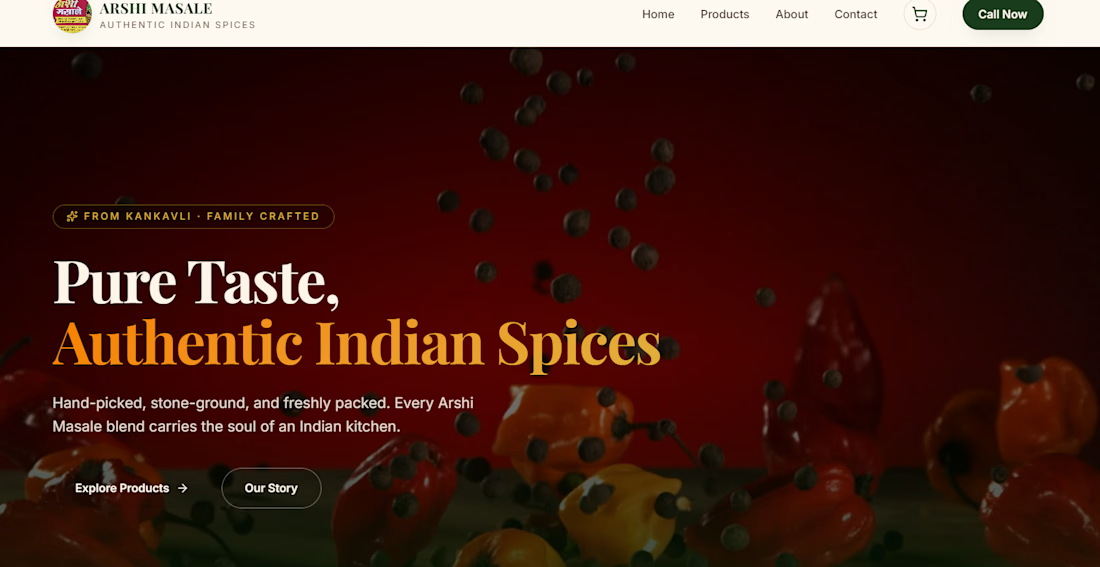
I built the Arshi Masale website for a local spice business from Sindhudurg, Maharashtra. This project was special to me because it showed me that even as a student, I can use what I’m learning to create something useful for a real business.
I focused on making it modern, simple, mobile-friendly, and ready for future e-commerce features. This is one of the projects that motivates me to keep learning, building, and eventually turn my passion for AI and technology into a career.


DO SUPPORT GUYS 😊

I’ve been building HTML and React templates for a while. I have a roadmap of 10+ templates. I might release them in batches or all at once.
The templates will have AGENTS.md and DESIGN.md files for you agent.


You nailed the overall mood here. The details just reinforce it nicely.

So I Recently rebranded my upcoming AI Agent Harness from "Crank" to "Pixie" which is the name of my cat. Do you think it was the right decision?
Which one do you prefer? Crank or Pixie?!
Check it out here: pixie.ecnivs.com
#FreelancerLife #AIHarness #FrontendDesign #AIAgent #ArtificialIntelligence #WebDevelopment #Design #TasteTest
5 voted
71%
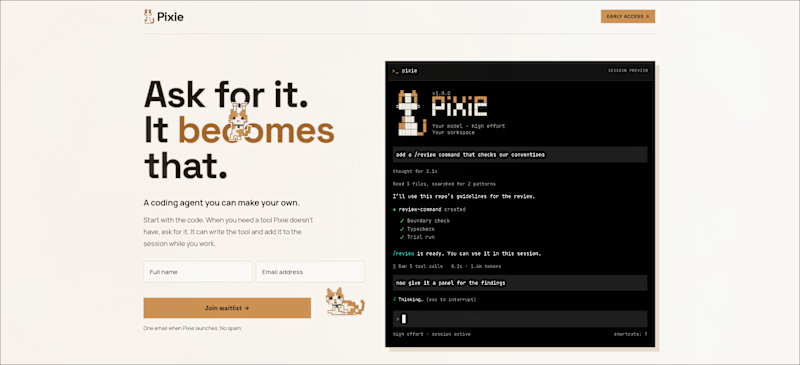
2 voted
29%
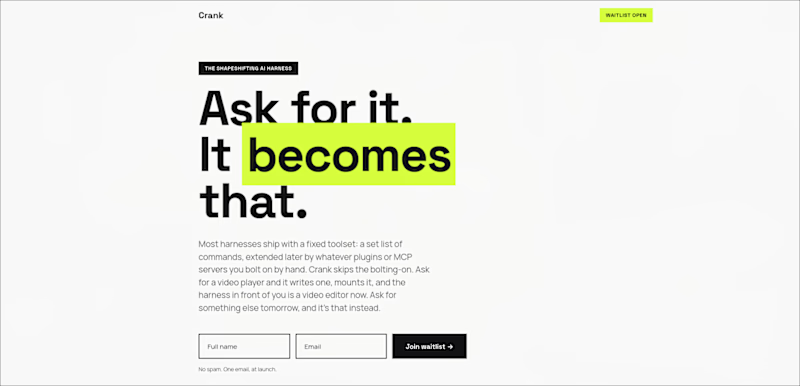
7 votes
Closed

Pixie gets my vote too. Naming it after your cat makes it memorable, and it feels a lot friendlier for a tool people trust with their code. Nice rebrand.