The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

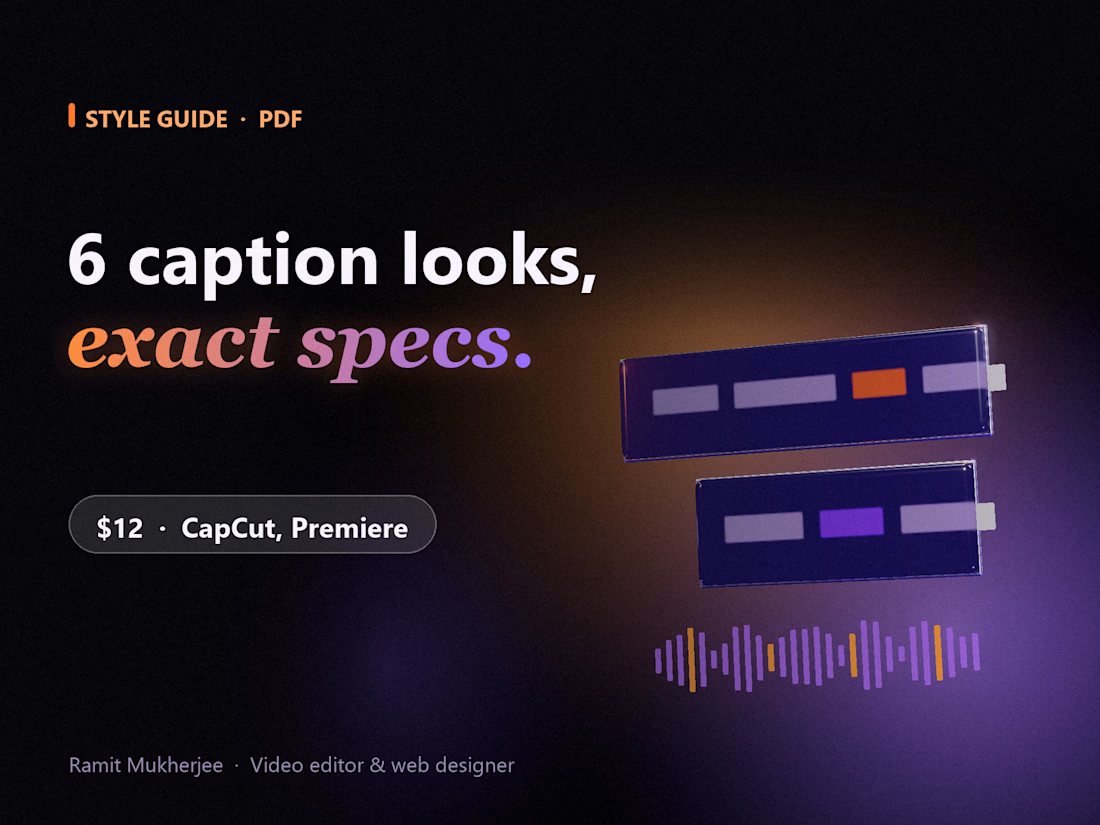
Same sentence, six caption looks. Only one of them keeps people watching.
My caption guide lists six looks for podcast clips, from plain white to a boxed card. The pick depends on the face and the background, not on taste. Busy footage needs a box. A clean close-up can carry a single highlighted word.
My rule: highlight one word per card, never a whole phrase, and never cut a word in half between cards.
This cover is from my caption style guide. Independent concept, not a client project. This is my portfolio website https://gleaming-haupia-a8b3b9.netlify.app/
Which look would you pick for a talking-head clip?
The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started





Related posts

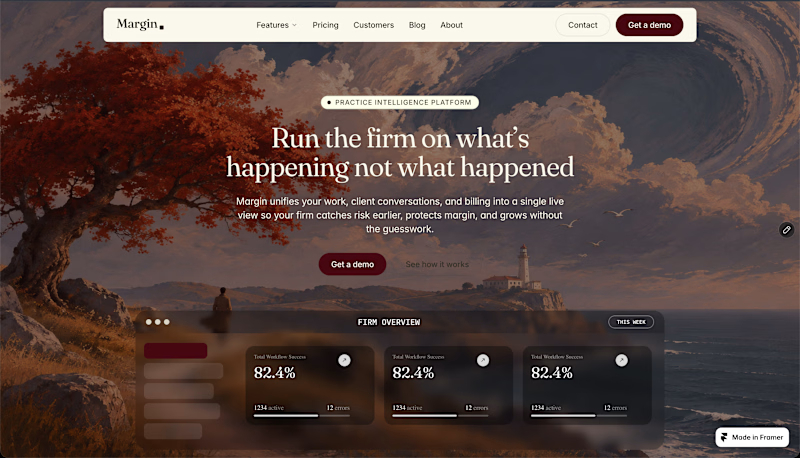
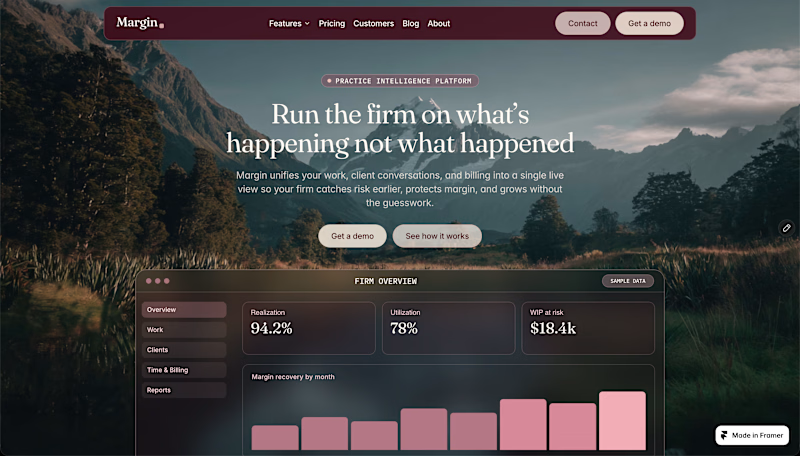
One template. Two completely different personalities. 👀
Experimenting with visual directions for a new Framer template.
🍂 1 — Warm, cinematic & editorial
🏔️ 2 — Dark, moody & premium
Both are still works in progress.
Which one would make you stop scrolling 1 or 2?
2 voted
67%
1 voted
33%
3 votes
Closed

Voted 1. The sunset and lighthouse make the page feel like a real brand. Is the dark one meant for a different audience?

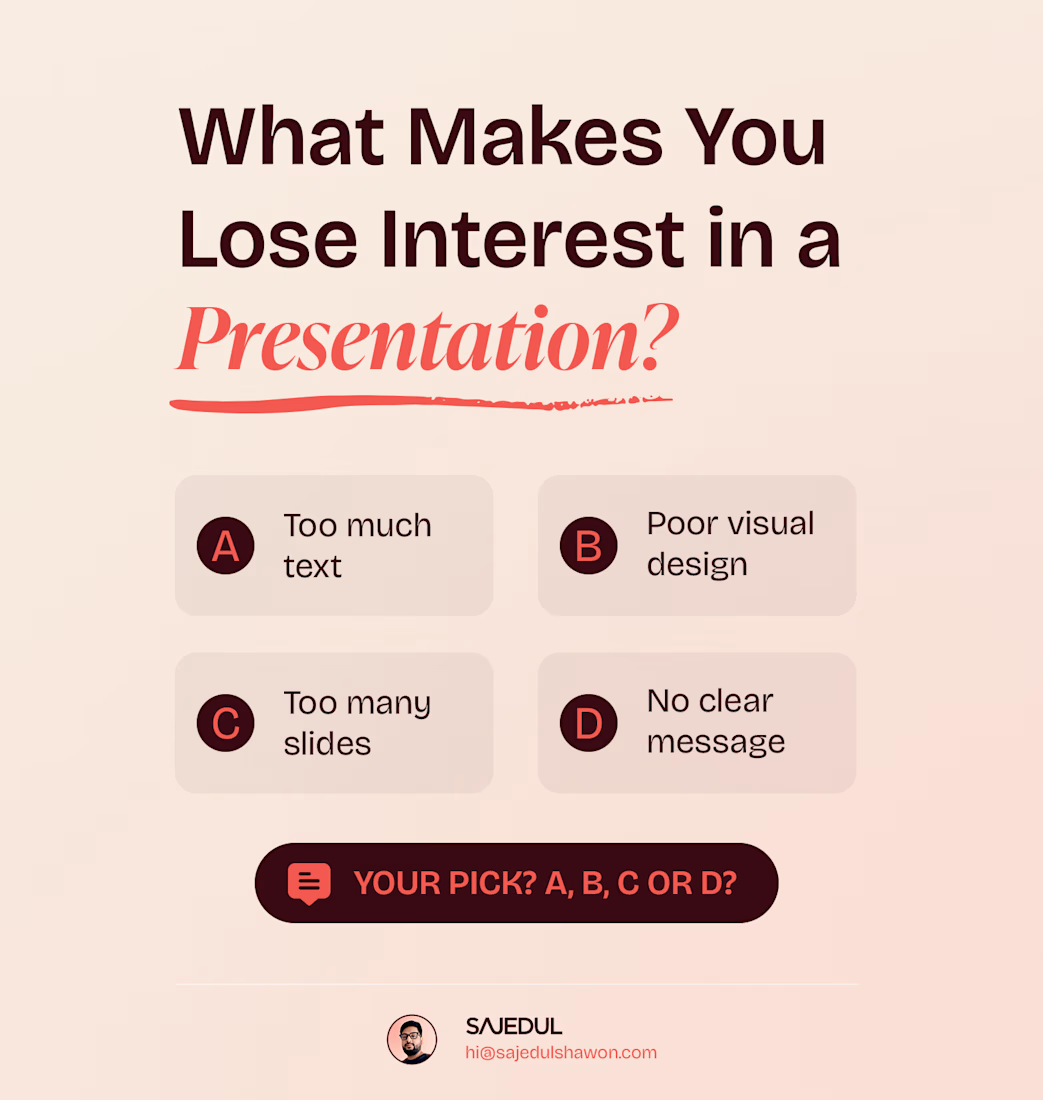
What Makes You Lose Interest in a Presentation?
Good presentation design isn't just about making slides look attractive. It's about keeping the audience engaged and making every message count.
But even a well-designed presentation can lose its audience.
I'm curious what other creatives, founders, and professionals think.
What's your biggest presentation frustration?
A. Too much text
B. Poor visual design
C. Too many slides
D. No clear message
Share your pick in the comments. I'd love to hear different perspectives.
#PresentationDesign #VisualDesign #CreativeCommunity


Too many slides can overwhelm and distract. Less is often more.

GTA6… I got there first 🚨
A 60-second fan short made entirely with AI video, with my own face as the lead. Nine shots, seven characters, built from one selfie and a set of reference images. No cameras were used.
I started from a public prompt guide by kaye_creatives on Higgsfield and treated it like a shooting script: built my own character sheet, cast the missing character, generated each shot separately, then cut, captioned, titled and mixed it myself.
What I'd pass on to anyone trying this:
Give every reference image one job. Face, room, prop or camera angle, never two at once.
Put exact counts in the prompt. Models add people and props unless you tell them how many.
Generate long, cut short. My first assembly was 67 seconds. The final is 60, and the pace is where the quality came from.


Great work as always bro!