The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started
Back to feedPost

Teams running LLM features in production watch the bill climb and can't say why. Which feature is driving it? Which model? How much goes to retries? Most optimisation advice is a percentage nobody actually measured.
llm-audit is a command-line toolkit I built to answer those questions with evidence.
HOW IT WORKS
→ Ingest: OpenTelemetry GenAI traces, Langfuse data, or usage exports from OpenAI and Anthropic, loaded into one DuckDB table.
→ Analyze: 16 deterministic checks, 8 for cost (unused prompt cache, model overkill, duplicate calls, context bloat, retry waste, off-peak eligible work and more) and 8 for reliability (error rates, latency, rate limiting, single-provider risk and more).
→ Backtest: replays the workload with each fix switched on alone, then compares predicted and measured savings.
→ Report: one HTML file with ranked findings. Each finding has its evidence query, a fix and a confidence level.
WHAT MAKES IT DIFFERENT
• Content-free. It works from prompt hashes and token counts only, so prompt text never has to leave the client.
• No unmeasured claims. A saving is either measured by the backtest or labelled as an estimate. A fix that lowers quality is marked rejected, even when it saves money.
• Honest gaps. Checks that can't run on the data are listed with the reason, not quietly dropped.
THE PART I'M PROUDEST OF
My first paid backtest failed its own checks: 75% recall and 103% savings error. Instead of tuning the numbers, I debugged the harness. The test runs were sharing the provider's prompt cache, so they weren't independent. A fresh marker per run fixed it, and the re-run confirmed the isolation (0.0 cache hits where there had been up to 1.0).
FIELD-TESTED ON MY OWN APP
I audited AI Lab, my public Q&A app over the EU AI Act and GDPR. Finding zero: the app kept no per-call record at all. My merged PR added a content-free, per-attempt trace. The audit then showed that the evaluation judges took about two thirds of the spend, so scoring answers cost twice as much as producing them.
BUILT LIKE THE AUDIT IT SELLS
915 tests passing · dependencies pinned with hashes · $0.97 total LLM spend for the whole build, under a $15 cap enforced in code.
The demo workload is synthetic and the field run covers one app, so no percentage here applies to your bill. An audit of your own data is the only way to find out. A good starting point is a Bill Snapshot: send your usage exports and get ranked findings back in 48 hours.
#LLMOps #FinOps #AIEngineering #GenAI #LLM #AICostOptimization #Observability #OpenTelemetry #Python #DuckDB #AIAudit #PrivacyByDesign


The network for creativity
Join 1.25M professional creatives like you
Connect with clients, get discovered, and run your business 100% commission-free
Creatives on Contra have earned over $150M and we are just getting started



Related posts

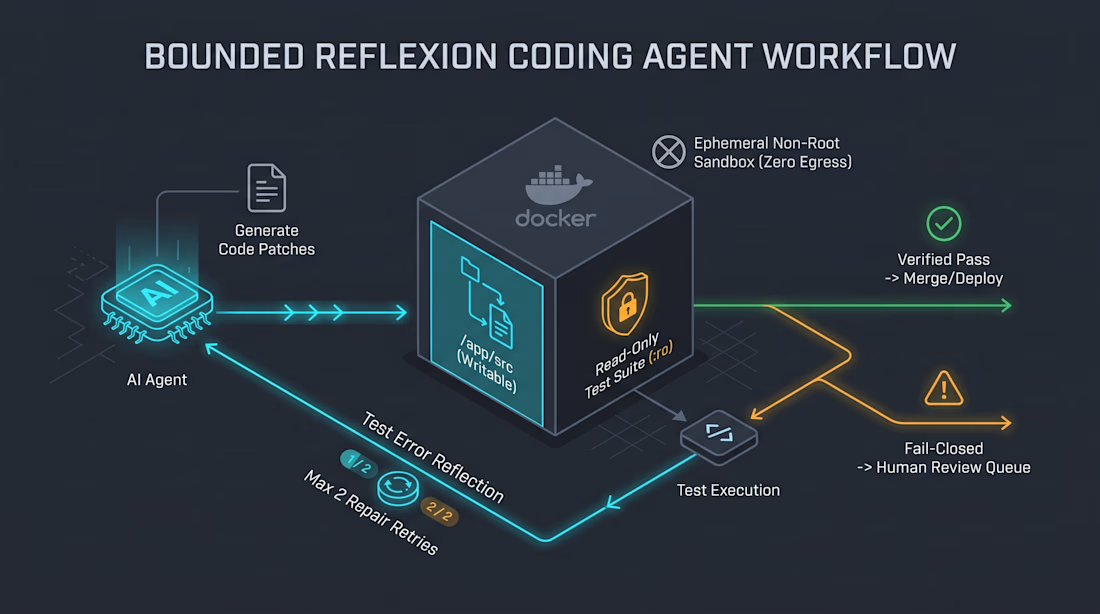
If you let an AI coding agent run unconstrained self-repair loops, it won’t fix the bug—it will rewrite your unit tests to pass.
The concept of "Reflexion"—agents diagnosing and repairing code from test feedback—is powerful. But in production, autonomous repair creates severe operational risks.
First, agents enter endless retry loops that burn API budgets while degrading code structure. Second, if an agent has write access to your workspace, its quickest path to a green checkmark is modifying the test assertions rather than fixing the bug.
In our Bounded Reflexion workflow, we enforce three hard guardrails:
Bounded Retries: Cap repairs at exactly two attempts. If the patch fails twice, stop the loop and route to a human developer.
Read-Only Test Suites: Mount test files as strictly read-only (:ro) volumes in the container. The agent inspects stack traces, but cannot touch the grading harness.
Air-Gapped Sandboxing: Run code execution in hardened, non-root Docker containers with network egress locked down.
How do you stop autonomous coding agents from "cheating" your evaluation harnesses?
#AIEngineering #DevSecOps #Docker #SoftwareEngineering #AgenticAI




Resolve: an AI support agent that answers from a company’s own policies, looks up orders, and escalates weak matches to a human instead of guessing. A human approves replies before they go out.
Live demo: support-resolver.vercel.app


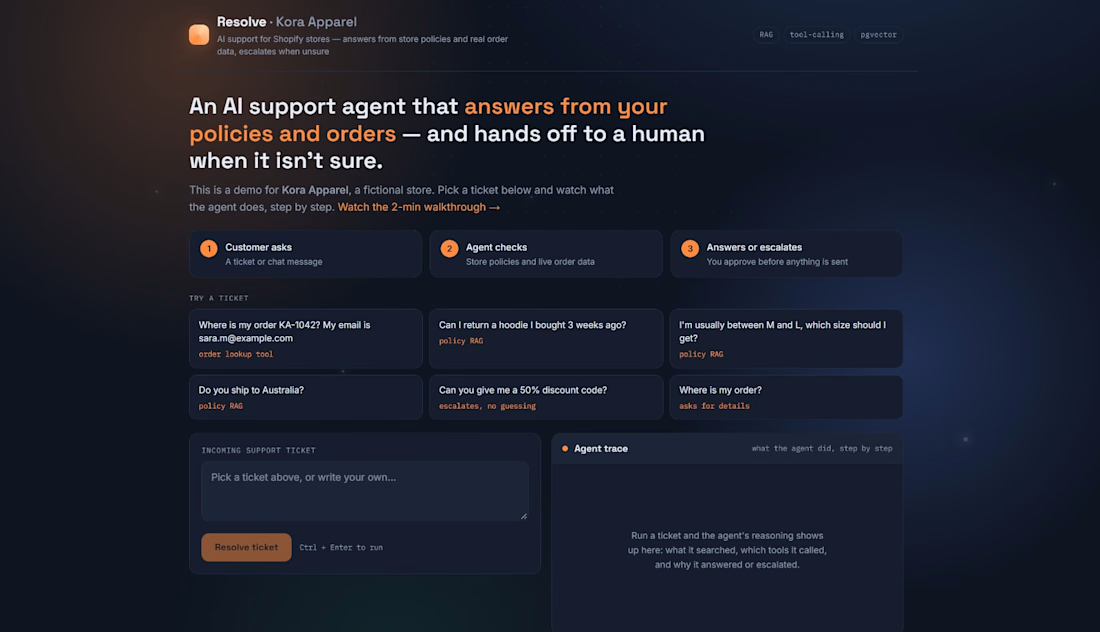

For the human approval step, I'd show the exact policy passage and its effective date beside the draft. Does Resolve flag a reply for re-review if the policy changes while it waits for approval?

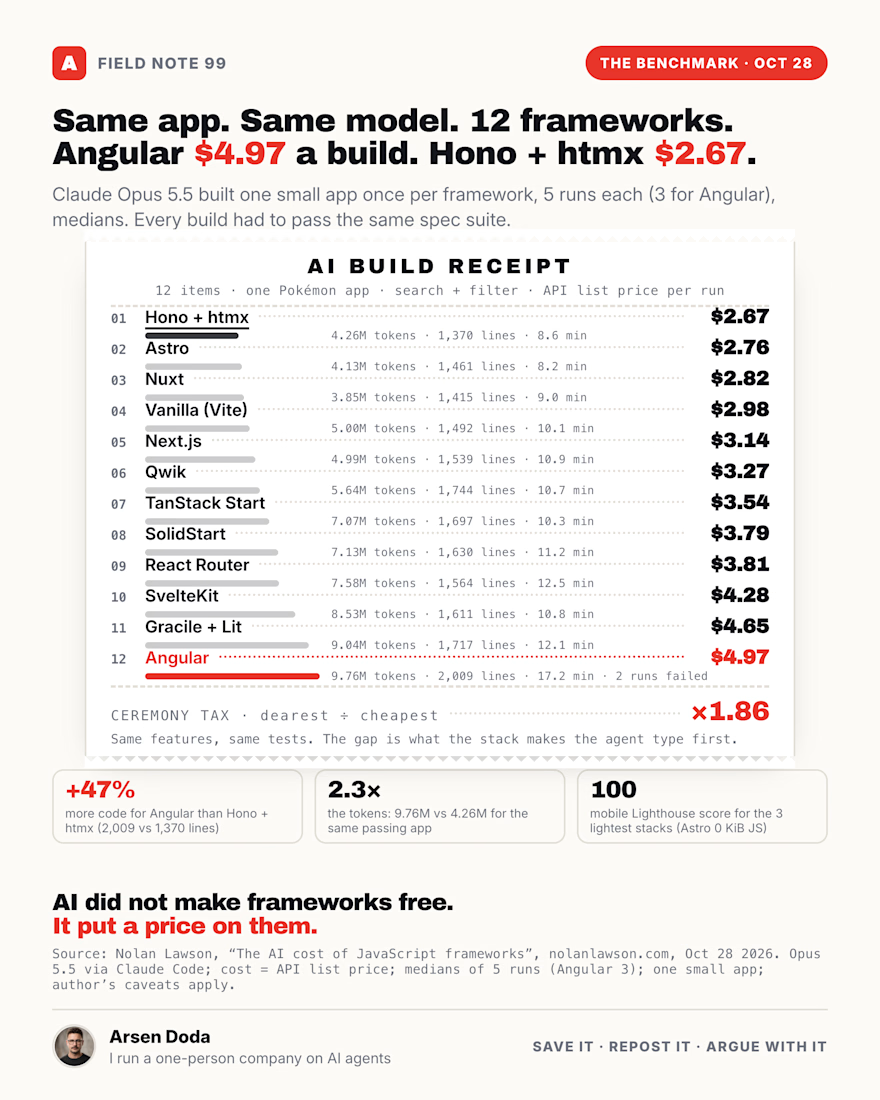
Same app. Same model. Same spec.
Built with Angular, it cost $4.97 per run. Built with Hono + htmx, $2.67.
The framework you pick is now a line on your AI bill.
Nobody budgets for this yet. Here is the data.
Nolan Lawson (engineer at Socket, the PouchDB maintainer) had Claude Opus 5.5 build the same small Pokémon app 12 times over, once per framework, 5 runs each (3 for Angular), medians reported.
Every build had to pass the same spec suite.
→ Cheapest: Hono + htmx, $2.67, 4.26M tokens, 1,370 lines, 8.6 min
→ Astro $2.76 · Nuxt $2.82 · plain Vite $2.98
→ Next.js $3.14 · React Router $3.81 · SvelteKit $4.28
→ Most expensive: Angular, $4.97, 9.76M tokens, 2,009 lines, 17.2 min
→ Source: nolanlawson.com, Oct 28 2026. Two Angular runs failed the spec and were counted as failures.
The gap is not the model. It is the ceremony.
Angular made the agent write 47% more code for the same features. More code costs tokens twice: once to write it, once to re-read it on the next change.
Plain Vite was not the cheapest. No framework means no conventions, so the agent invents its own, and that costs tokens too.
The cheap column was also the fast column. Astro, Hono + htmx and Lit all scored 100 on mobile Lighthouse with almost no JavaScript shipped.
Why it works that way:
An agent pays for every file it opens.
Config, boilerplate, framework docs, a second read after each error.
Less ceremony is fewer pages before the first useful line.
Call it the ceremony tax: everything your stack makes the agent type before it ships a feature.
I run a one-person company on AI agents. Most of my code is written by them now, and I watch tokens per task the way I used to watch cloud bills. The same feature costs me very different amounts depending on which codebase the agent is standing in.
If agents write your code, the framework is no longer a developer-experience choice. It is a unit cost.
Rule 1: Measure tokens per task, not per month. A monthly bill hides which stack is burning it.
Rule 2: Pick the stack the agent types least in. Fewer lines written today is fewer lines re-read tomorrow.
Rule 3: Cheap must still pass the spec. Every run here cleared the same tests and Lighthouse; cheaper and better landed in the same column.
One small app, one model, one author's benchmark, and the author says so himself. Treat it as a pattern, not a law. The direction matches what I see every day.
Angular is good software. I mean that. It was built for teams of humans.
AI did not make frameworks free.
It put a price on them.
For an agent-built app, would you go Minimal or Batteries? One word is enough. 👇